Repository navigation
runtime: long pauses STW (sweep termination) on massive block allocation #31222

Description
Activity
- changed the title
[-]runtime GC: long pauses STW (sweep termination) on massive allocation[/-][+]runtime GC: long pauses STW (sweep termination) on massive block allocation[/+]on Apr 3, 2019 - changed the title
[-]runtime GC: long pauses STW (sweep termination) on massive block allocation[/-][+]runtime: long pauses STW (sweep termination) on massive block allocation[/+]on Apr 3, 2019 To be clear, the reproducer is making a 3.2 GiB allocation which is going to take a while for the OS to fulfill.
However, I dug into this a bit and I'm seeing ~1s pauses, sometimes with only ~50ms pauses.
The 50ms pauses represent a lower bound for how fast the OS can give us back pages. The ~1s pauses actually come from the fact that we're zeroing the entire 3.2 GiB allocation, even though it just came from the OS.
We have an optimization which avoids re-zeroing fresh pages, but unfortunately this optimization is conservative. For example, if a needzero span at the end of the heap is contiguous with the new 3.2 GiB allocation, then those two are going to coalesce, and the 3.2 GiB free space will be marked needzero, when really only the first N KiB of it actually needs to be zeroed.
One way we could fix this is by making needzero a number, and if we can guarantee that only the first N KiB need zeroing, then we only zero that. If it's some weird swiss cheese of non-zeroed memory then we just assume the whole thing needs zeroing, rather than trying to keep track of which parts need zeroing.
I'm not sure if this fix is worth it though, since future allocations would still have to go back and zero this memory anyway, causing the 1s delay to return.
Reacted by Yegor Myskin, Yuanjia Zhang and Weizhen WangFor 1.15, one of my planned follow-up tasks on non-cooperative preemption is to make memclrNoHeapPointers preemptible. For large pointer-free allocations, this should make the long zeroing operation preemptible.
Reacted by Yegor Myskin, Cholerae Hu, Oleku Konko, Foubarre, Rafael Otero Reinert, Mario Ranftl and Jim WeiReacted by Oleg Kovalov, Rafael Otero Reinert and Jim WeiIn case others are wondering if they are running into this:
memclrNoHeapPointersshows up in pprof CPU profiles, so you should be able to find code paths calling it. You can also look for really large allocations in thealloc_spaceprofile. (For the record, we are seeing ~second long GC pauses due to this issue in a production application using Go 1.14; thanks for the excellent reproduction which helped me understand this)I just encountered a >1s GC pause scenario, any suggestions on how to avoid the long pause?
@changkun Is that with Go 1.17? Zeroing some large allocations is now preemptible, if you suspect that's the problem here.
1 second is quite a while. Is this reproducible? Can you get a GC trace where this GC happens? That would help in narrowing down the source of the pause (that is, which part of the cycle it happened). Even if it doesn't show up in the trace (like, this is about trying to stop the world, not actually having the world stopped) that's still useful information.
I am using a tip version
go version devel go1.18-527609d47b Wed Aug 25 17:07:58 2021 +0200 darwin/arm64. The profile is collected from an app running on iOS.The GC pause reported by
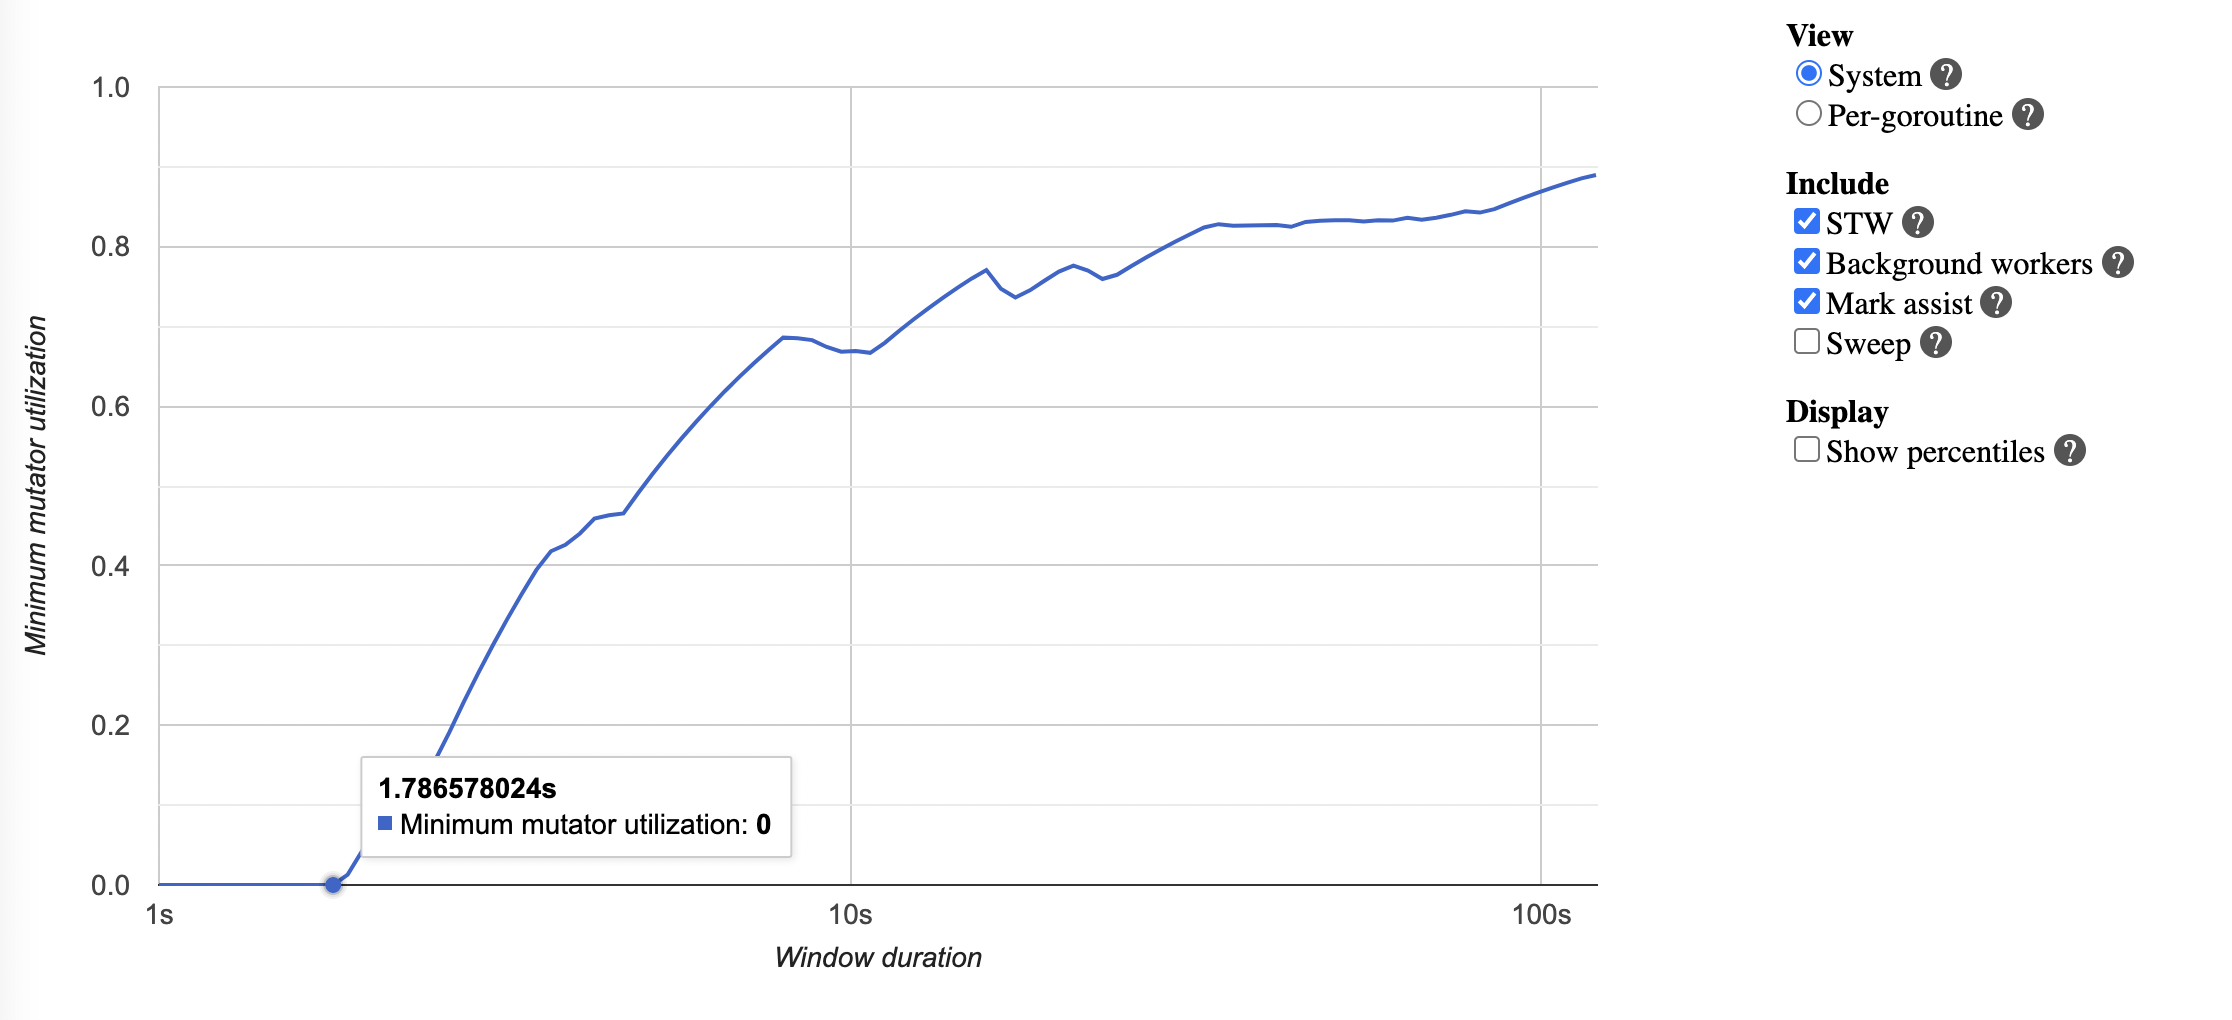
runtime/metricspackage is as follows:1.2032e-05: * 2.2528e-05: * 3.2768e-05: ** 3.3792e-05: *** 3.4816e-05: *** 3.584e-05: ** 3.6864e-05: ** 3.7888e-05: ** 3.8912e-05: * 3.9936e-05: * 4.1984e-05: * 4.608e-05: * 4.7104e-05: * 8.3968e-05: * 0.000139264: * 0.010747904: * 0.012320768: * 0.017301504: * 0.01835008: ** 0.019398656: ** 0.019922944: * 0.020447232: * 0.02097152: * 0.021495808: ** 0.022020096: ** 0.02359296: * 0.037748736: * 0.040894464: * 0.042991616: * 0.044040192: * 0.04718592: * 0.049283072: * 0.071303168: ** 0.075497472: *** 0.081788928: * 0.08388608: * 0.090177536: * 0.096468992: ** 0.142606336: * 0.14680064: ** 1.476395008: *Examples:
GC idle took 0.02 second:

GC fractional took 1.2 second and 1.8 second:
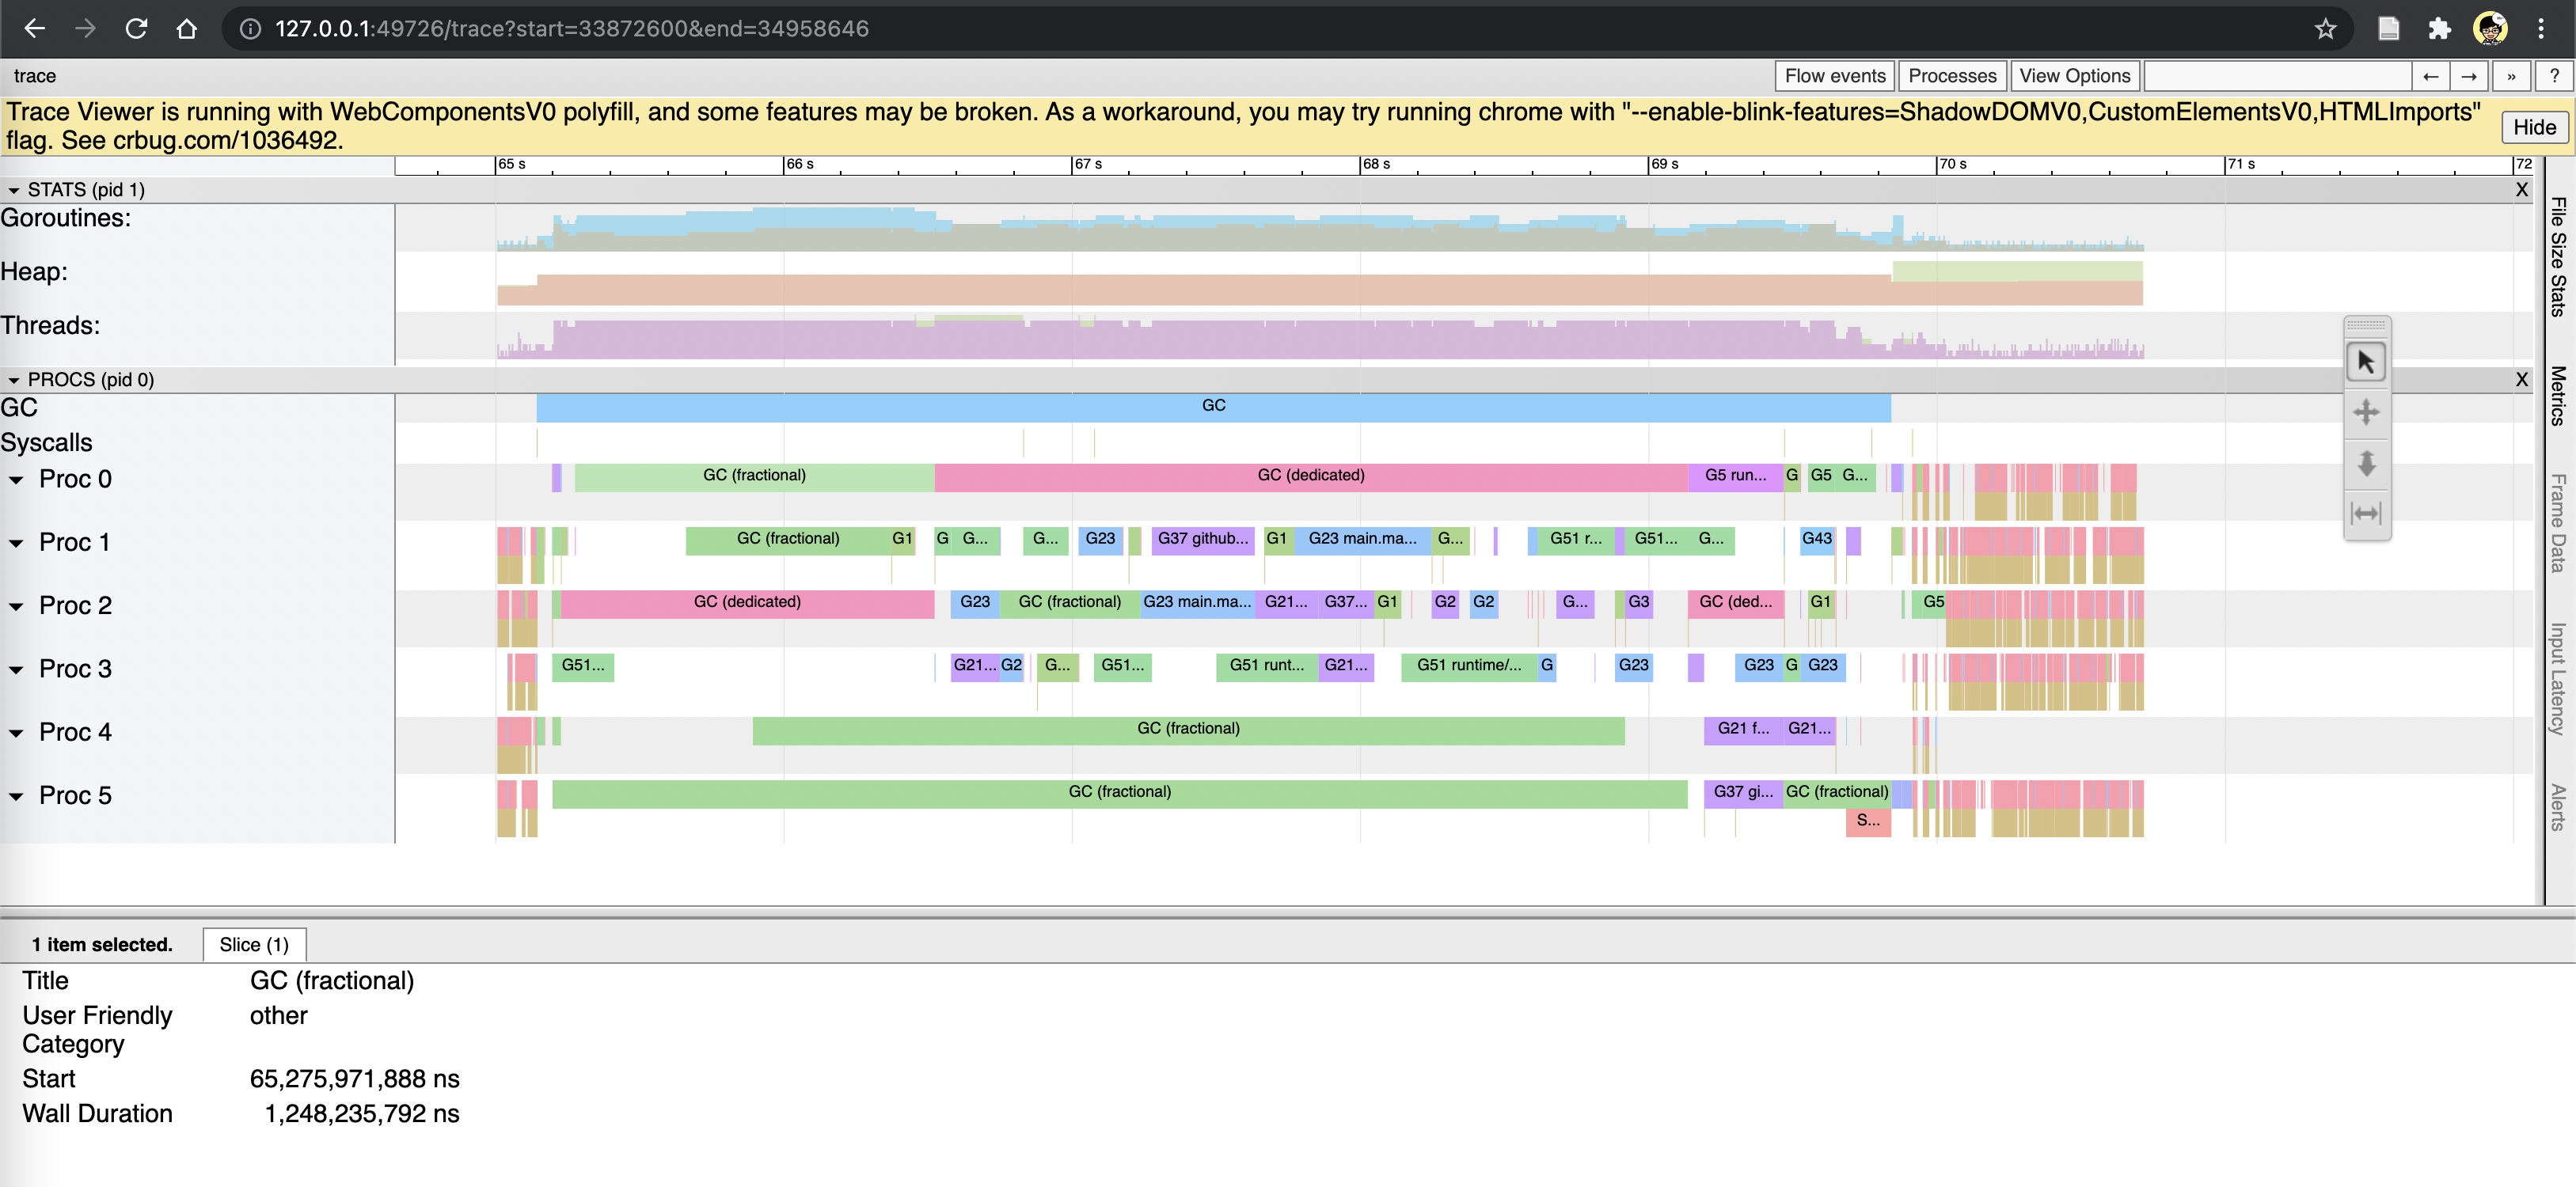
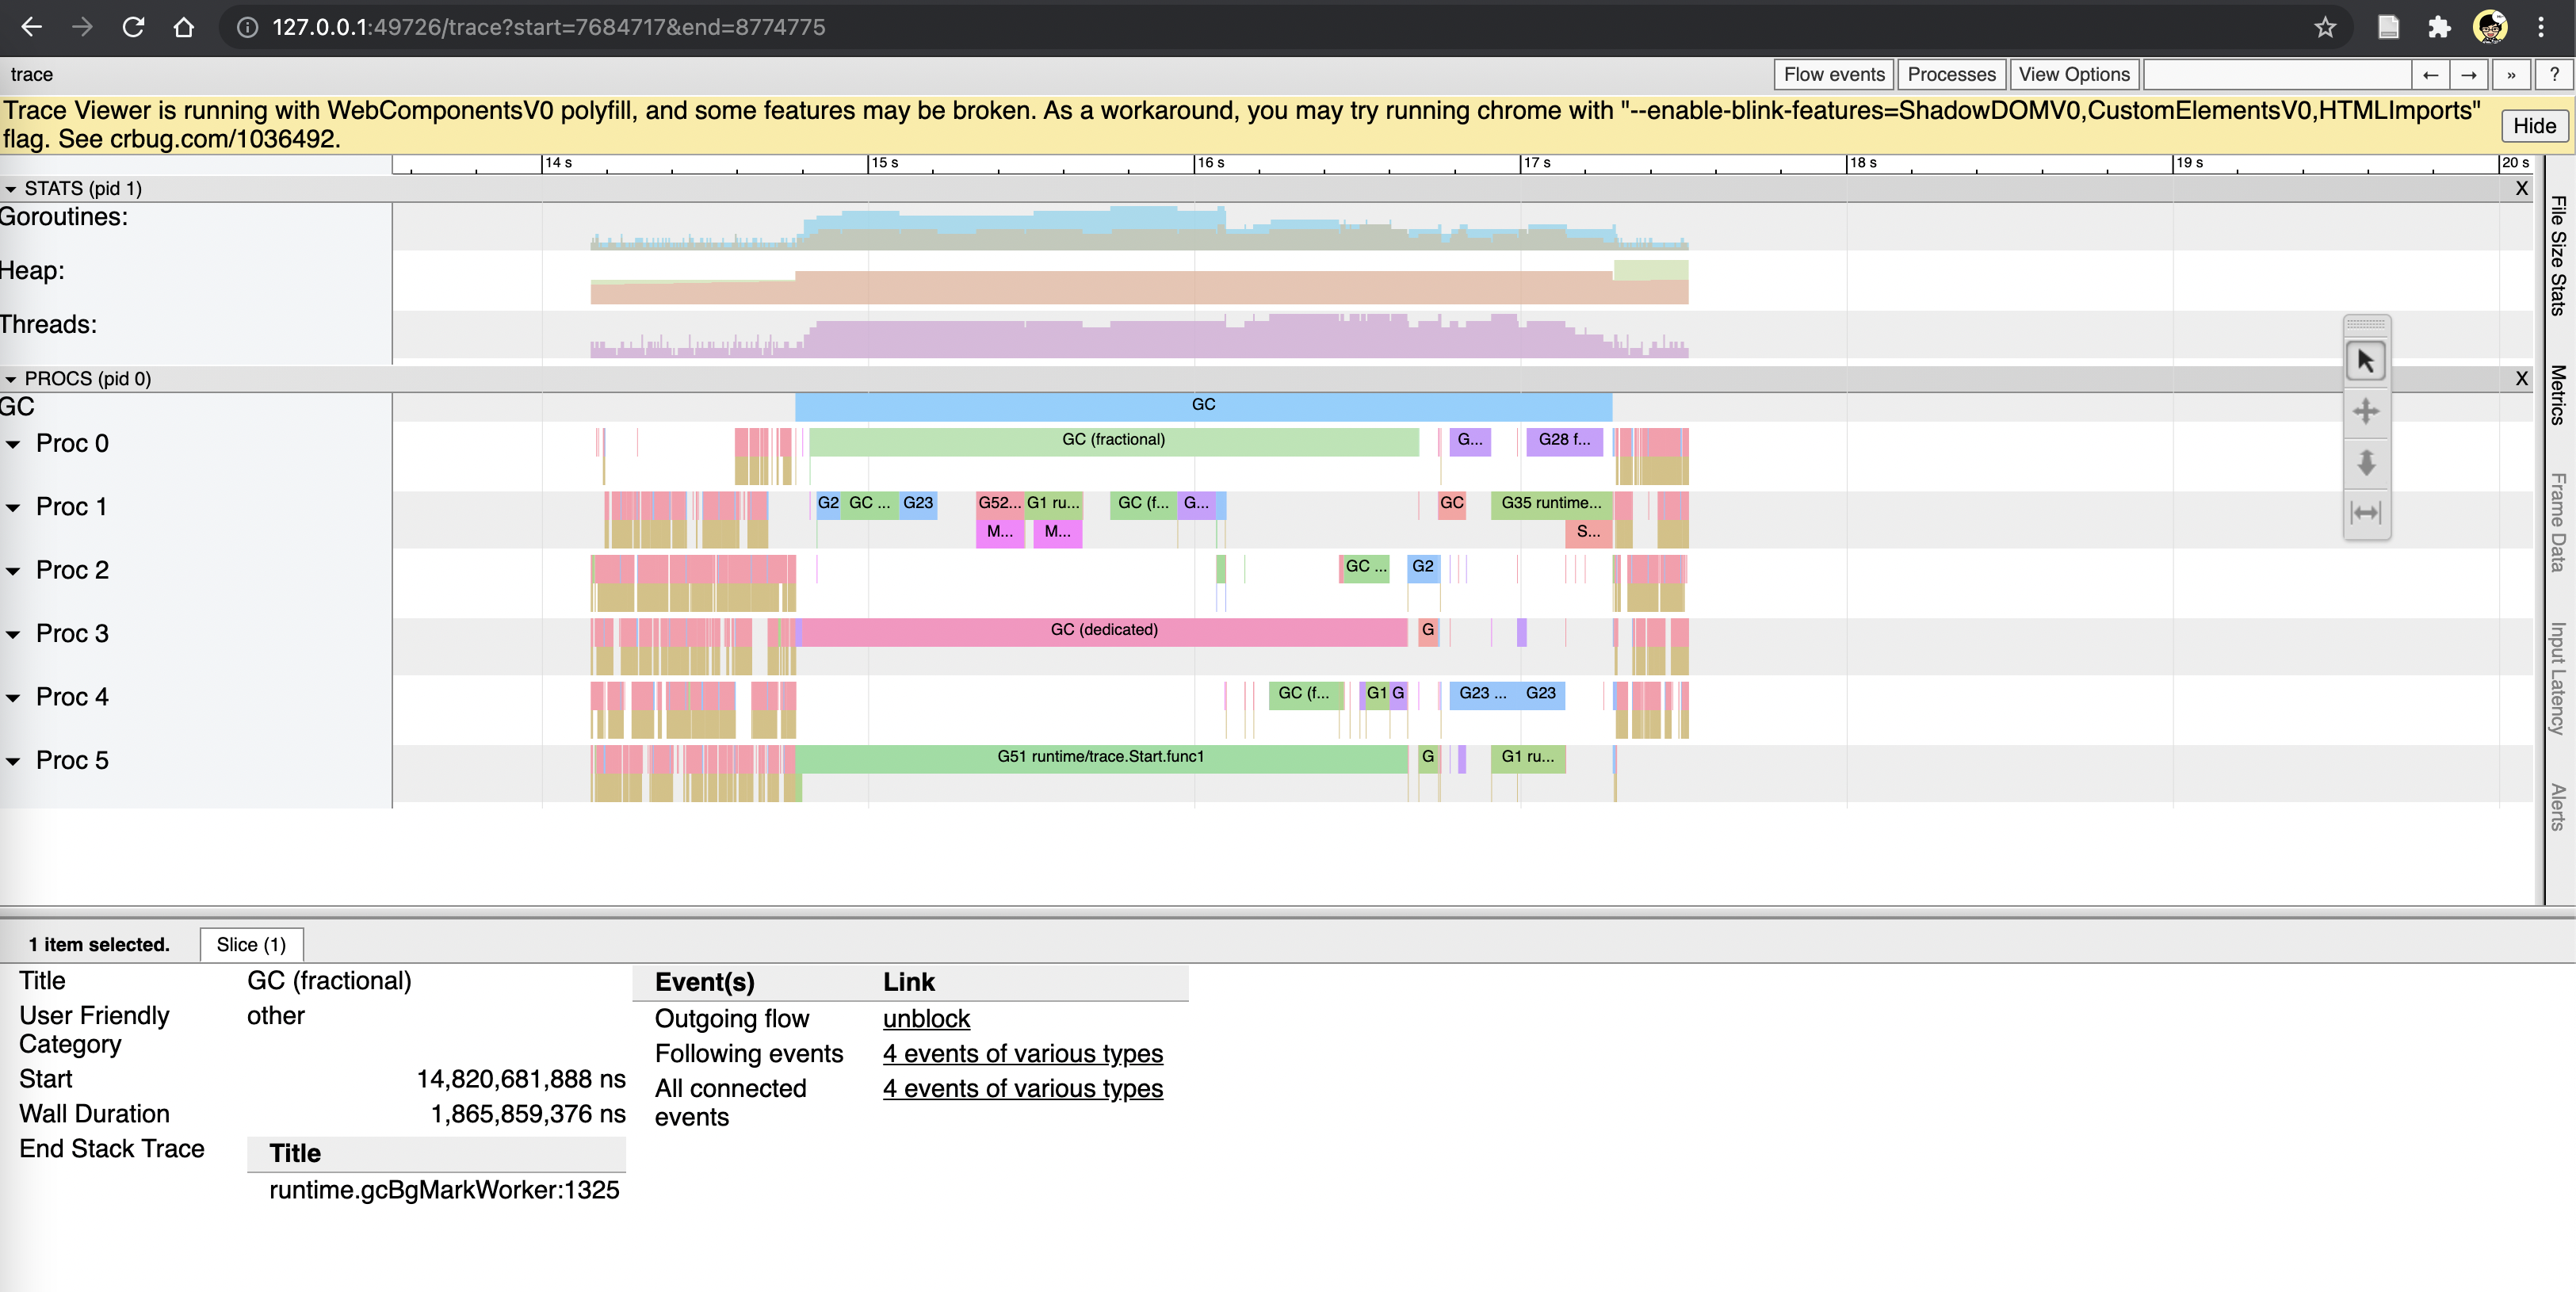
Sweep termination took 1.8 second:

I hope I found good examples, if not: there are more examples, see the trace profile:
https://drive.google.com/file/d/1OaMruMiu8RWBXclQDRuf7MGDkzjkR4PP/view?usp=sharing
I had a few running cases where the max observation was 4 seconds (didn't collect trace profile for this case, but the reproducer should be able to observe that again):

The reproducer (depend on develop branch f52dd5f2461b4b6396df83a6a723037f74a75a72):
package main

import (
	"image/color"
	"time"

	"fyne.io/fyne/v2"
	"fyne.io/fyne/v2/app"
	"fyne.io/fyne/v2/canvas"
	"fyne.io/fyne/v2/container"
	"fyne.io/fyne/v2/layout"
	"fyne.io/fyne/v2/test"
	"fyne.io/fyne/v2/widget"
)

func main() {
	app := app.NewWithID("iosrend")
	win := app.NewWindow("Some Window")

	cells := make([]fyne.CanvasObject, 0, 80*25)
	for i := 0; i < 80; i++ {
		for j := 0; j < 25; j++ {
			cells = append(cells, canvas.NewRectangle(color.RGBA{R: 255, G: 255, B: 255, A: 128}))
		}
	}
	container := container.New(layout.NewGridLayout(25), cells...)

	c := 0
	b := widget.NewButton("START", func() {
		for i := 0; i < 80; i++ {
			for j := 0; j < 25; j++ {
				index := i*25 + j
				obj, _ := container.Objects[index].(*canvas.Rectangle)
				if c == 0 {
					obj.FillColor = color.RGBA{R: 20, G: 30, B: 100, A: 128}
				} else if c == 1 {
					obj.FillColor = color.RGBA{R: 100, G: 20, B: 30, A: 128}
				} else if c == 2 {
					obj.FillColor = color.RGBA{R: 30, G: 100, B: 20, A: 128}
				}
				obj.Refresh()
			}
		}
		c = (c + 1) % 3
	})
	go func() {
		tk := time.NewTicker(50 * time.Millisecond)
		for range tk.C {
			test.Tap(b)
		}
	}()

	win.SetContent(fyne.NewContainerWithLayout(layout.NewBorderLayout(nil, b, nil, nil), container, b))
	win.ShowAndRun()
}
Reacted by Oleg KovalovThanks for the examples. The GC idle and fractional traces aren't STW, Something odd appears to be happening in the GC idle example you gave because only G37 is running for a long time; that may or may not be a runtime issue, but it wouldn't show up as pause time. The sweep termination trace, however, is STW. Do you know which of the traces you uploaded is that one? We'd need to look at the stack trace of G21 at the end of the STW to get a sense of where this is. From the screenshot, G21 is clearly doing some extremely long (~35 second?!) operation.
Thanks for the examples. The GC idle and fractional traces aren't STW, Something odd appears to be happening in the GC idle example you gave because only G37 is running for a long time; that may or may not be a runtime issue, but it wouldn't show up as pause time.
@aclements , thanks for the follow-up. I wasn't unable (or patient enough) to open the slowly loaded huge trace file, but from the collected runtime/metrics, the data shows the largest STW was ~4s. From the traces, it seems that those areas are not working on more rendering work (issue GPU draw calls). Such a phenomenon is always surrounded by GC events, hence I had the assumption that it has some trouble to collaborate with GC.
The sweep termination trace, however, is STW. Do you know which of the traces you uploaded is that one? We'd need to look at the stack trace of G21 at the end of the STW to get a sense of where this is. From the screenshot, G21 is clearly doing some extremely long (~35 second?!) operation.
Yes, you can download the trace file here:
https://drive.google.com/file/d/1OaMruMiu8RWBXclQDRuf7MGDkzjkR4PP/view?usp=sharing
and the G21 is in http://[::]:8080/trace?start=46979199&end=48050088G21 suppose to do work in the application lifetime, except for a clear request. As the name of G21 revealed, it is a goroutine for an unbounded channel where the implementation is just a for loop that takes some input from the channel, append to a slice buffer, then send out if there is a receiver waiting. Here is the code:
type UnboundedCanvasObjectChan struct { in, out chan fyne.CanvasObject }

func NewUnboundedCanvasObjectChan() *UnboundedCanvasObjectChan {
	ch := &UnboundedCanvasObjectChan{
		in:  make(chan fyne.CanvasObject, 128),
		out: make(chan fyne.CanvasObject, 128),
	}
	go func() {
		q := make([]fyne.CanvasObject, 0, 1<<10)
		for {
			e, ok := <-ch.in
			if !ok {
				close(ch.out)
				return
			}
			q = append(q, e)
			for len(q) > 0 {
				select {
				case ch.out <- q[0]:
					q = q[1:]
				case e, ok := <-ch.in:
					if ok {
						q = append(q, e)
						break
					}
					for _, e := range q {
						ch.out <- e
					}
					close(ch.out)
					return
				}
			}
			if cap(q) < 1<<5 {
				q = make([]fyne.CanvasObject, 0, 1<<10)
			}
		}
	}()
	return ch
}

func (ch *UnboundedCanvasObjectChan) In() chan<- fyne.CanvasObject { return ch.in }
func (ch *UnboundedCanvasObjectChan) Out() <-chan fyne.CanvasObject { return ch.out }
21 remaining items
Oh interesting; thanks you for the rapid clarification! Now I need to go back to debugging the application a bit more, since there is something happening I don't understand...
It is my understanding that when the kernel returns a block of zeroed memory all the virtual addresses point to a single physical write protected page of zeros. The first write to a page ends up allocating a physical page, zeroes it, and associates the virtual memory to the physical memory. This copy (or zero) on write greatly reduces the latency of asking for zeroed memory and then does the zeroing incrementally on demand when the page is written to.
Can we mimic this approach for large allocations? I suspect it can’t be done in user space but perhaps we can round trip the memory to the kernel so when it returns it works like fresh memory.
If this works then the problem with allocating, deallocating, and reallocating large objects will also see reduced latency. I have no idea how large of an allocation would be needed for this to be a win.
That's an interesting idea. You can force this via
madvise(MADV_DONTNEED)on Linux: the next access will always return zeroed memory, on-demand. I suspect it's more expensive than just zeroing for O(10s of pages) or less since they get recycled often (previous experiments withMADV_DONTNEEDindicated that calling it on ~every span allocation leads to a bad time).But, for larger allocations that need to be zeroed anyway, it might not actually matter (or, the latency win far outweighs any throughput loss). This could be a much simpler and safer way to achieve the latency improvement vs. the chunking approach. Thanks for the suggestion Rick!
The one downside is I don't think a similar approach will work on non-Linux platforms. For instance, the comparable mechanism on Windows does actually cause a fault. On the BSDs there's only
madvise(MADV_FREE)which I think is much lazier and doesn't make the "zeroed on access" guarantee.This issue is currently labeled as early-in-cycle for Go 1.22.
That time is now, so a friendly reminder to look at it again.Reacted by Oleg Kovalov and tb1989This is going to be a good bit easier to do with the new allocation headers landing in Go 1.22. Punting to Go 1.23, but this time for sure. :)
Reacted by black23eepReacted by Josh Bleecher Snyder, Felix Geisendörfer, Oleg Kovalov, Dominik Honnef and Paško ZdilarThis issue is currently labeled as early-in-cycle for Go 1.23.
That time is now, so a friendly reminder to look at it again.Change https://go.dev/cl/577495 mentions this issue:
runtime: make zeroing of large objects containing pointers preemptibleReacted by Paul Bauer, Jannis M. Hoffmann, Nick Ripley and Felix Geisendörfer- moved this from In Progress to Done in Go Compiler / Runtime / Command
on Apr 9, 2024 - added a commit that references this issue
on Apr 9, 2024 - locked and limited conversation to collaborators
on Apr 9, 2025


What version of Go are you using (
go version)?What operating system and processor architecture are you using (
go env)?go envOutputWhat did you do?
We have a big entity cache inside an application. So it's loading in background goroutine.
And when the application allocates a slice in the background the latency inside all response handlers increases.
Got a reproducer
What did you expect to see?
Worker gorotine(loop in example) should not pause more than 1-5ms.
What did you see instead?
43ms pauses