The Lexer-Parser-Interpreter Project aims to tokenize the different parts of SIMPLE code in a .txt file and the parse the
tokens to ensure the SIMPLE code input is a 'Valid Program' or 'Invalid Program'.
When Lexer.java is passed a .txt file, it should return tokens:
IDTOKEN- a continues String of letters and integers. An ID must have a letter at the beginning of the String.INTTOKEN- a continuous String of exclusively integers.ASSNMTTOKEN- an assignment operator,=.PLUSTOKEN- an addition operator,+.EOFTOKEN- a-, signalling the End Of File.
Lexer.java should be able to output the above as Tokens, extrapolated from the .txt file, with an
EOFTOKEN -
at the end of every tokenized .txt file.
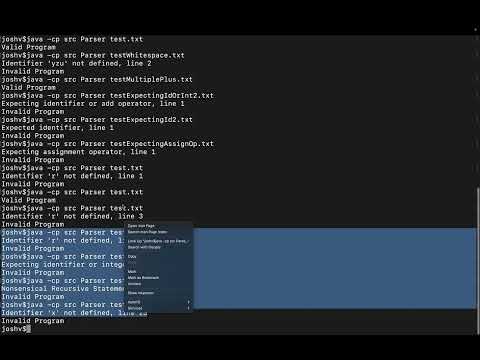
When Parser.java is passed a .txt file, it should ouput:
Valid Programor
ERROR: [Type of Error & what the program was expecting], line where error is found
Invalid Program
Last, but not least, ByteCodeInterpreter.java interprets the bytecode that Parser generates, and changes memory
accordingly. For example, if we have the following .txt file:
plain.txt

x = 5
y = x + 6
Parser will produce the following bytecode:
[1, 5, 2, 0, 0, 0, 1, 6, 2, 1]Then, the ByteCodeInterpreter will step-in and interpret the bytecode and change the memory according to the bytecode
commands and operands. The memeory would look like:
[5, 11, 0, 0, 0, 0, 0, 0, 0, 0, 0](the default size of memory is 10, but this is able to be adjust to any desire size).
- Ensure that you have Java installed on your machine. You can check if Java is installed by running:
java -versionTo run the Lexer.java program on your local machine, follow these steps:
-
Clone the Repository:
- Open your terminal and run the following command to clone the repository:
git clone https://github.com/usf-cs514/lexer-parser-interpreter-joshvasquezr.git
- ```
- Navigate into the project repository
```bash
cd lexer-parser-interpreter-joshvasquezr
-
Compile the Code
- Use the following command to compile the Java files:
javac src/Token.java src/Lexer.java
-
Run
Lexer.java- To run the program use the following command:
java -cp src Lexer test.txt
-
Change
.txtfile- If you want to use
Lexer.javato parse another file, simply substitute your file name for test intest.txt.
- If you want to use
To run the Parser.java program on your local machine, follow these similar, but different, steps:
- Follow steps 1 and 2 for
Lexer.javaand clone the repository AND navigate to the project repository on your machine - Compile the Code
- Use the following command to compile the Java files:
javac src/Token.java src/Lexer.java src/Parser.java src/idTable.java
- Run
Parser.java- To run the program use the following command:
java -cp src Parser test.txt
- Change
.txtfile- If you want to use
Parser.javato validate another file, simply substitute your file name for test intest.txt.
- If you want to use
To run the ByteCodeInterpreter.java program on your local machine, follow these similar, but different, steps:
- Again, follow steps 1 and 2 for
Lexer.javaand clone the repository AND navigate to the project repository on your machine - Compile the Code
- Use the following command to compile the Java files:
javac src/Token.java src/Lexer.java src/Parser.java src/idTable.java src/ByteCodeInterpreter.java
- Run
Parser.java- To run the program use the following command:
java -cp src ByteCodeInterpreter test.txt
- Change
.txtfile- If you want to use
ByteCodeInterpreter.javato interpret another file, simply substitute your file name for test intest.txt.
- If you want to use
-
This project was a fun challenge. Adding in new elements such as ArrayList<> data types, continuing to practice Object-Oriented Programming principles, and figuring out how to parse and tokenize text from a
.txtfiles. This project required an understanding of each method:getIdentifier(),getInteger(),getNextToken(), andgetAllTokens(). I will briefly describe my thought process behind each method...getAllTokens()- returns aListArray<Tokens>. It retrieves each Token from the file by calling thegetNextToken()method.getNextToken()- based on what character the global variableindexis at, it will determine whether the Next Token will be anID,INT,=,+, or-and return that Token.- the logical implementation was simple. If the current character is a letter, call
getIdentifier(). If the current character is an integer, callgetInteger(). If the current character is an=or+, return the appropriate Token albeitASSMNTTOKENorPLUSTOKEN. Or finally, if all Tokens have been identified, return theEOFTOKEN.
- the logical implementation was simple. If the current character is a letter, call
getInteger()- this will return aStringof integers. In SIMPLE, an integer can ONLY be a continuous String of integers. No spaces, no special symbols, no letters.- since we know our current index holds an integer, thanks to the
getNextToken()logic, all I need to do is check that as long as the current character is an integer, I can keep appending it onto thesbTokenStringBuilderI initialized. However, once my current character is no longer an integer I will return the contents ofsbTokeninStringform.
- since we know our current index holds an integer, thanks to the
getIdentifier()- not quite as exclusive asgetInteger(), this will return a String that can be a mix of letters and integers. However, its only requirement is that the ID (or Identifier) MUST start with a letter. After the first character, it must be a continuous String of letters or integers. Again, no spaces, no special symbols.- Again, thanks to
getNextToken()'s logic, I know the current character is a letter, so all I need to check for is if the current character is either a letter or an integer. If it is, I will simply append the current character tosbToken. Otherwise, I will return the contents ofsbTokenback togetNextToken().
- Again, thanks to
Two occurrences made this project slightly harder than I had anticipated.
- The first, was my mistake. I started coding
the logic to
getIdentifier()andgetInteger()before I fully understood the function ofLexer.java, and more specifically, before I understood the roles ofgetNextToken()andgetAllTokens(). This caused me to write the code forgetIdentifier()andgetInteger()as returning ALL POSSIBLE ID's and int's with one call ofgetIdentifier()orgetInteger(). The nice part is that the logic for both methods only needed to be simplified. - The second, was my difficulty with adding the
EOFTOKENas the last Token of the list of TokensgetAllTokens()would return. The difficulty was two-fold. I would either get the correctEOFTOKENfor thetestExpectingIdOrInt2.txtandtestWhitespace.txtor all the rest of the files except those previous two. If I was able to get anEOFTOKENat the end of the rest of the files, I would have twoEOFTOKENSat the end oftestWhitespaceandtestExpectingIdOrInt2.txt.- Solution to
EOFTOKENproblem: I simply added anifstatement within thewhileloop ingetAllTokens(). Thisifstatement checked to see if theListArray<Tokens>already had anEOFTOKENin it. If it did, it would simply break thewhileloop and return theListArray<Tokens>. However, ifEOFTOKENwas not in the ListArray, then it would append anew Token(EOFTOKEN, " -")to theListArray<Tokens>.
- Solution to
-
This project built upon the base of
Lexer.javaby adding the functionality of validating a program's code. The primary principles I used in this project were: getter() methods, private and public modifiers for data members, Object- Oriented Programming prinicples,ArrayListandHashMapdata structures. I was able to gain a better understanding of how OOP offers offers cross-class functionality. Within theParser.javaclass, I used the following methods:parseProgram(),parseAssignment(),parseIdentifier(),parseAssignmentOp(),parseExpression, andgetNextToken(). WithinidTable.java, I used the following methods:idTable()as my constructor,getAddress(),add(), andtoString(). FinallyToken.java, was updated to contain three getter() methods;getType(),getValue(), andgetLine(). I will also briefly describe my thought process and the structure of my code:parseProgram()- uses a while loop to loop through each new expression with an assignment declaration- i.e. x = 3 + 1 z = 2
- it will loop through x = 3 + 1 and then z = 2
- i.e. x = 3 + 1 z = 2
parseAssignment()- checks for correct structuring of new assignment / expression. First, an identifier is expected andparseIdentifier()is called, then an Assignment Operator is expected soparseAssignmentOp()is called, then the contents of the Expression are expected soparseExpression()is called. If the program is not in that order, then an ERROR is thrown.parseExpression()- goes through each token following the assignment operator, and checks that they're in a logically correct order.- Valid Program: x = 1 + 2 + 3
- Invalid Program: x = 1 ++3 + y
-
The goal of this project was to interpret our already tokenized and validated
.txtfile. I will describe how I went about doing this.- Step one, create bytecode based off of the
.txtfile fed to the Parser. This was done by creating anArrayList<Integer> bytecodedata member and using theadd(int x)function to add bytecode to the array. I did this by storing the value of mycurrentID(i.e. x = 5;currentID= x). Then when the program is inparserExpression(), if thecurrentTokenis an identifier, it will append the LOAD command tobytecode, which is 0, and the address ofcurrentTokenfound in thesymbolTable. IfcurrentTokenis an integer, the program will append the LOADI command tobytecode, which is 1, and the value ofcurrentToken. Finally, if parseExpression recognizes that a new variable will be assigned to a new expression, it will the append the STORE command tobytecode, which is 2, and the address ofcurrentID. - Once, the bytecode is generated, we move onto the interpreter step. This is when
ByteCodeInterpreter.javacomes into the picture. Here we use therun()method to loop through thebytecodearray two-by-two. We are doing this two-by-two because each command (LOAD, LOADI, STORE) is paired with an operand, be it an integer index or value. I will briefly detail each helper method forrun():load()- accesses thememoryArrayList to extract the value found at the specified index. Then adds it to theaccumulator.loadi()- directly adds the integer value to the accumulatorstore()- checks if there's space in the memory to store another integer. If there is enough space left, it will set the specified index to the value of theaccumulatorand then setaccumulatorback to 0.
In
run()if the current index is a LOAD (or 0), then it will callload(), else if the current index is a LOADI (or 1), then it will callloadi(), else if the current index is a STORE (or 2) it will callstore()and pass the necessary arguments to these methods. - Step one, create bytecode based off of the
To ensure the correctness of the Lexer, I tested it using the comprehensive set of unit tests that was provided in LexerTest.java.
Each test checks if the lexer correctly tokenizes the input and handles different combinations of identifiers, integers,
assignment operators, and plus signs.
-
Basic Tokenization Test:
- Test file:
test.txt - Description: Verifies that the lexer correctly identifies
ID,INT,ASSMT,PLUS, andEOFtokens. - Expected resulst:
Lexer.java
[ID xyz 1, ASSMT = 1, INT 33 1, ID zz12 1, ASSMT = 1, INT 99 1, PLUS + 1, INT 88 1, PLUS + 1, ID xyz 1, EOF - 1]
Parser.java
Valid Program
ByteCodeInterpreter.java
Valid Program
Symbol Table: {xyz=0, zz12=1}
ByteCode: [1, 33, 2, 0, 1, 99, 1, 88, 0, 0, 2, 1]
Memory: [33, 220, 0, 0, 0, 0, 0, 0, 0, 0]
- Test file:
-
Assignment Operator Test:
- Test file:
testExpectingAssignOp.txt - Description: Ensures that the lexer properly handles cases where assignment (
=) occurs between identifiers and integers. - Expected results:
Lexer.java
[ID x32 1, ASSMT = 1, INT 54 1, ASSMT = 1, INT 87 1, EOF - 1]
Parser.java
Expecting assignment operator, line 1
Invalid Program
ByteCodeInterpreter.java
Expecting assignment operator, line 1
Invalid Program
- Test file:
-
Identifier and Integer Test:
- Test file:
testExpectingIdOrInt2.txt - Description: This test validates that the lexer can handle a mix of identifiers and integers, especially when two consecutive integers are encountered.
- Expected results:
Lexer.java
[ID x 1, ASSMT = 1, INT 1 1, ID y 1, ASSMT = 1, INT 1 1, EOF - 2]
Parser.java
Expecting identifier or add operator, line 1
Invalid Program
ByteCodeInterpreter.java
Expecting identifier or add operator, line 1
Invalid Program
- Test file:
-
Multiple Plus Test:
- Test file:
testMultiplePlus.txt - Description: Verifies the lexer's behavior when multiple plus (
+) operators appear. - Expected results:
Lexer.java
[ID x32 1, ASSMT = 1, INT 77 1, ID yyy9 2, ASSMT = 2, ID x32 2, PLUS + 2, INT 5 2, PLUS + 2, INT 4 2, PLUS + 2, ID x32 2, EOF - 2]
Parser.java
Valid Program
ByteCodeInterpreter.java
Valid Program
Symbol Table: {x32=0, yyy9=1}
ByteCode: [1, 77, 2, 0, 0, 0, 1, 5, 1, 4, 0, 0, 2, 1]
Memory: [77, 163, 0, 0, 0, 0, 0, 0, 0, 0]
- Test file:
-
Whitespace Handling Test:
- Test file:
testWhitespace.txt - Description: Tests how the lexer handles input with whitespace between tokens.
- Expected results:
Lexer.java
[ID x32 1, ASSMT = 1, INT 83 2, ID yzu 2, ID rt 2, ASSMT = 2, INT 2 2, EOF - 3]
Parser.java
Identifier 'yzu' not defined, line 2
Invalid Program
ByteCodeInterpreter.java
Valid Program
Symbol Table: {rt=1, x32=0}
ByteCode: [1, 83, 2, 0, 1, 2, 2, 1]
Memory: [83, 2, 0, 0, 0, 0, 0, 0, 0, 0]
- Test file:
-
Expecting Identifier Test:
- Test file:
testExpectingId2.txt - Description: Ensures that the lexer behaves correctly when it encounters a sequence of integers and expects an identifier.
- Expected results:
Lexer.java
[INT 32 1, ASSMT = 1, INT 54 1, EOF - 1]Parser.java
Expected identifier, line 1
Invalid Program
ByteCodeInterpreter.java
Expected identifier, line 1
Invalid Program
- Test file:
-
Test Out of Bounds
- Test file:
testOutOfBounds.txt - Description: Ensures that the interpreter behaves correctly when encountered with a file that tries to exceed the available memory space.
- Expected results:
ByteCodeInterpreter.javaValid Program Run Time Error: Address '10' out of range. Symbol Table: {a=0, b=1, c=2, d=3, e=4, f=5, g=6, h=7, i=8, j=9, k=10} ByteCode: [1, 1, 2, 0, 1, 2, 2, 1, 1, 3, 2, 2, 1, 4, 2, 3, 1, 5, 2, 4, 1, 6, 2, 5, 1, 7, 2, 6, 1, 8, 2, 7, 1, 9, 2, 8, 1, 10, 2, 9, 1, 11, 2, 10] Memory: [1, 2, 3, 4, 5, 6, 7, 8, 9, 10]
- Test file:
Each test case compares the expected token output against the actual tokenized result and fails if there is a mismatch.