clarify naming convention - #671
Conversation


|
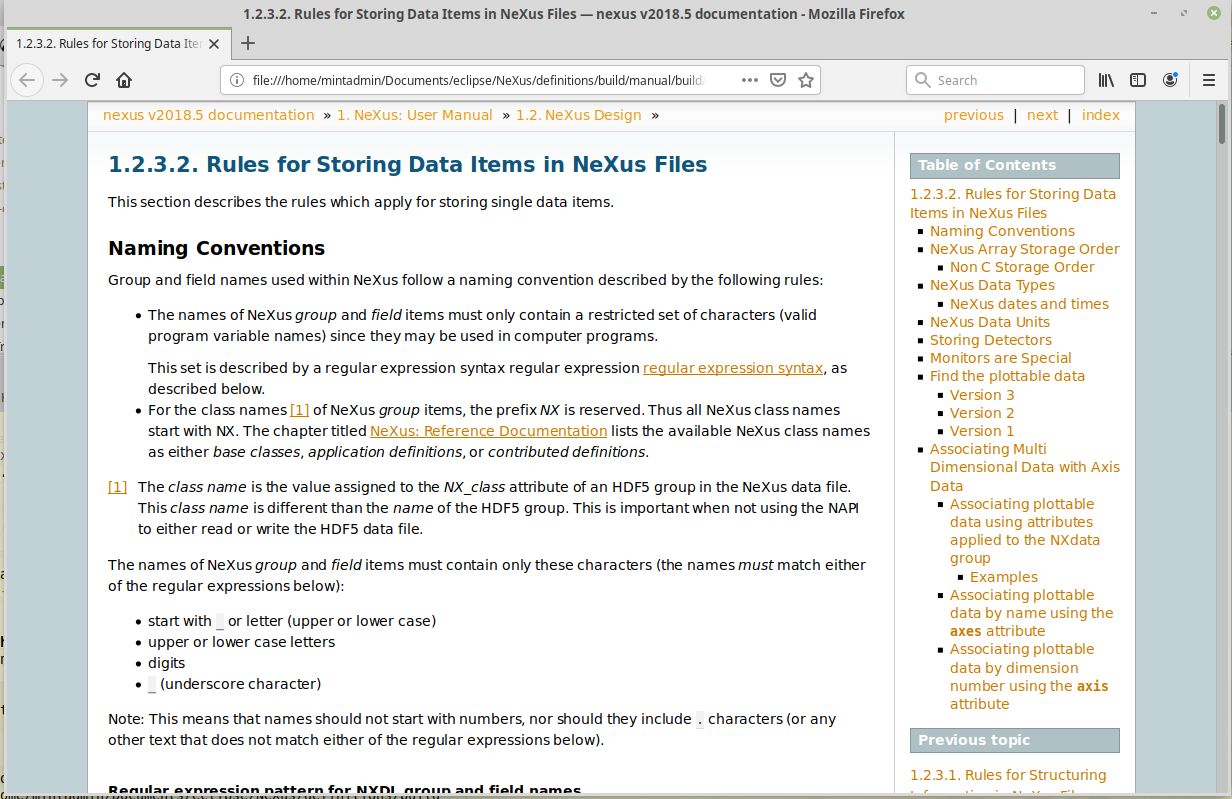
@vasole: Here's a snapshot of what the documentation looks like when it is built:
|

|
I certainly preferred the interpretation of NeXus being attribute based leaving freedom to the names. To me this whole thing of changing a recommendation to a rule is a hidden attempt to workaround the limitations imposed by trying to access HDF5 fields not as keys in a dictionary containing valid paths in a file system but as attributes of some instance. This rule is like forbidding to use file names in a file system if they contain a dot or they starting by a number. Therefore, I would prefer somebody else to approve this PR that in my opinion deserves discussion at highest level. |

|
To be clear, this PR is a change in the documentation only. The intent of the naming convention has always been that the names should be valid program variable names, dating to the original design of NeXus using HDF4. I've add @mkoennecke as a reviewer since he is one of the founders. |

|
If I remember correctly, this whole naming convention came into being in order to make our lives easier. Names such "*.-' will cause all sorts of problems when programming. May be, the whitespace language can work with that. But as far as I know there is no HDF5 interface to whitespace.... The . (period) has special meaning in HDF-5 path descriptions and is therefore best avoided. Not using upper case has been our practice for a long time. Thus, I believe we make no error when we forbid it. Also, I do not really understand Armandos argument:
Please elucidate. |

|
I don't have strong opinions on whether these should be rules or strong recommendations, but to answer @mkoennecke, HDF5 (or at least h5py, with which I am more familiar) does allow white spaces, periods, and, as far as I can tell, any other unicode characters in object names. As @vasole points out, this is not a problem when the object names are treated as dictionary keys, but doesn't allow them to be treated as attributes. NeXpy allows both when possible, because it's more convenient to type attributes, but if the field name violates Python naming conventions, then you have to use the dictionary form, which is recommended for use in Python scripts. |
|
Just as an example, I was able to create the following tree using the nexusformat package: So the naming restrictions are probably a little outdated now that unicode is in such widespread use, but it would certainly be more convenient for me if they were preserved, since I prefer typing in the attribute form. |
|
Elucidation: today the whole point of not allowing a dot at all or a number as starting character of a field is to allow to use things like nexusformat accessing the fields as attributes of some object instead of using the correct way: accessing them by the path. As Ray points out, if you want to make sure you do not run into trouble, you should avoid doing so in scripts to avoid collisions between field names accessed as attributes and actual class methods or actual attributes. That makes the interest of the whole approach doubtful. For instance, keys, attrs and value are perfectly valid NeXus names that could potentially give troubles trying to access them as attributes as they could interfere with actual h5py methods. |
|
comment updated (I wrote file names instead of field names) |
|
I should probably clarify my position about attribute names. NeXpy allows the attribute form, Of course, it's different if you are writing robust code. Then you should always use the dictionary form if the field name is arbitrary to avoid the kind of conflicts @vasole describes. The fact that the Resisting the use of unicode characters in NeXus object names might end up being a problem in the long term, but if it's a problem for people writing code in other languages, I don't object to keeping the restrictions for now. |
|
I would like to clarify that what bothers me about being a rule and not a recommendation are
|
|
As a reminder, for the ipython interactive users, the automatic completion is also available when using dictionaries. From the h5py documentation (http://docs.h5py.org/en/stable/config.html):
|
|
My 2c's worth: I believe (but it is not in the manual) that the NIAC in some stage decided to use only english names for groups and fields. This avoids the unicode discussion. UTF8 content, for example in a text field like title, is OK. I was not aware of this python dot notation. Would this not be thrown off when a dot is part of the name? Now I am entering rant mode: I have a deep dislike for special characters, spaces and such in names. This is a disease inherited from windows. Causes all sorts of problems with quoting, counting spaces and what not, especially when working on the command line. Please outvote me on this, if you like. Names starting with a number would work mostly, but are not allowed in some programming languages. Thus I always tend to use thing01, thin02, thing03 when I have multiple things. And cannot work with a list. But this is a matter of taste. But I am afraid, deciding these things requires a proper vote by the NIAC in order to clarify majorities. |
|
Variable names starting by a number are not allowed almost anywhere. Names (=character strings) starting by a number are allowed everywhere. If the documentation upgrades from recommendation to rule, it prevents things like having: |
|
I'm sure I voted in favour of the more restricted name sets, although that was before Unicode became ubiquitous. I think we will need to discuss this at the next NIAC meeting before allowing a major relaxation of the rules, since there may be other side effects that we haven't thought of. In the meantime, |
|
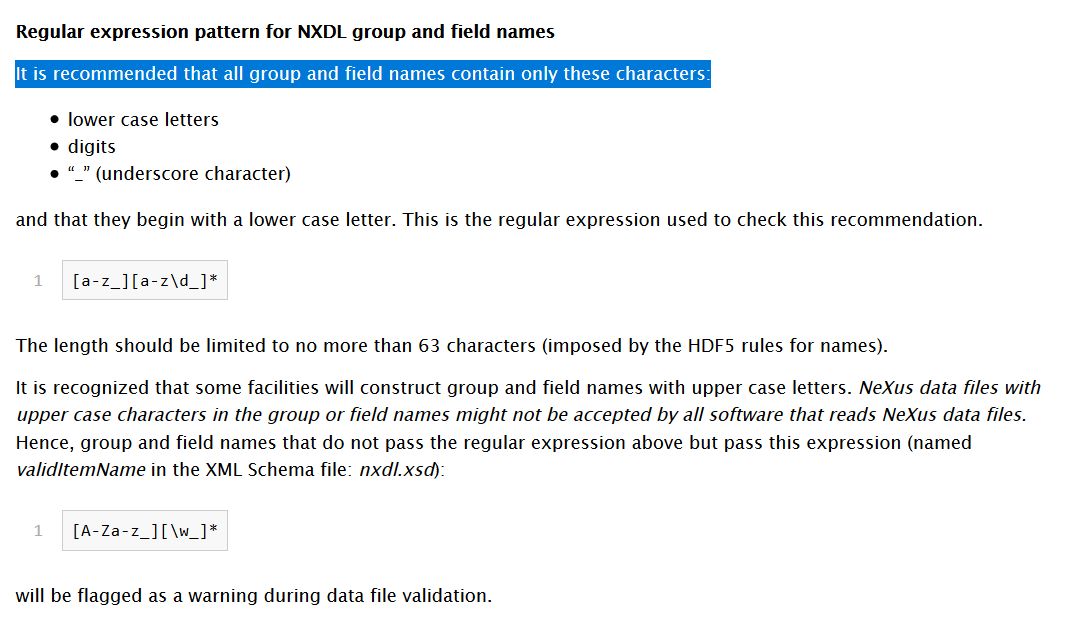
Again, this PR is only a change in the documentation (#544) to clarify the NeXus naming convention for groups and fields, not a change in the NeXus rules. A major point of this discussion focuses on this specific text in the manual, mostly on the one word recommended:
The context is highlighted in this screen shot of the section: It is obvious from the intensity of the discussion of this PR that the manual has not clearly expressed the NeXus standard. Some have interpreted the word
We need help, gentle yet insistent help, to make this manual better. |
|
It is still a problem that we present two regular expressions. Since both describe group and field names that are acceptable, providing two expressions is obviously a source of confusion. Looking at the various files contributed to our examples repository, restriction to lower case names is used by most of the example files but not by all of the NeXus community. In my view, restriction from using upper case characters in group and field provides no value to the NeXus standard. I propose we only state the one that allows both upper and lower case characters: |
|
2020 Code Camp can discuss but NIAC should review this before resolving. |

|
Maybe it is time to reconsider and allow group and field names composed of only underscore ( |
|
Allowing only underscore characters |
|
When the DetailsWith this revision, travis-ci is expected to pass. |
|
The |
|
@vasole Please review. We believe this is ready to be merged. |
prjemian
added
the
NIAC vote needed


|
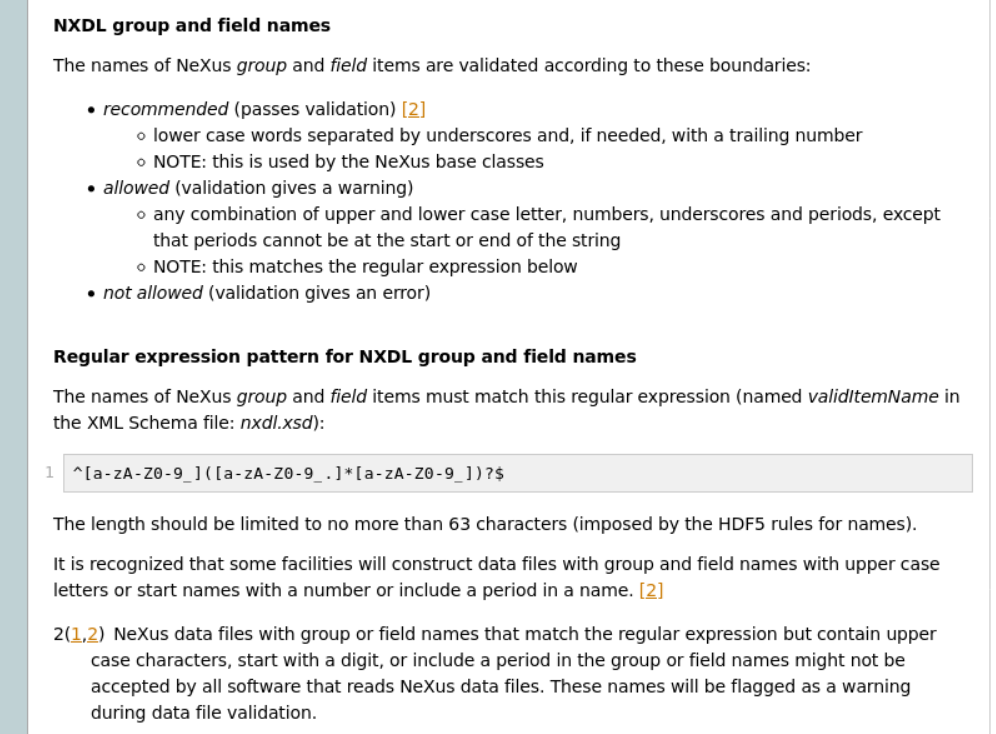
What we need to express are the boundaries between what names are:
|
|
taking the idea to start from Ben's suggestion above, this regexp: |
|
https://regex101.com/r/1nJ3xb/3 regexp: revised test list |

|
|
|
Proposal: Clarify naming convention for the names of groups and fields as the following:
The NIAC recognises that the majority of the world uses characters outside of the basic latin set (Standard ASCII) currently included in the allowed names. The restriction given here reflects current technical issues and we expect to revisit the issue and relax such restrictions in future. All NIAC members are asked to cast their vote by attaching a thumbs up emoji to accept, a thumbs down to reject and any other emoji to abstain. |
|
At NIAC2020, it was suggested to add this text:
|

9 participants


fixes #544