A quick switcher plugin for Obsidian with fuzzy search across all your notes.
- Instant Search: Searches as you type.
- Fuzzy Search: Quickly find notes by title or content using fuzzy matching.
- Content Context: See a snippet of the matching content directly in the search results.
- Multiple Search Providers: Choose between a fast, in-memory MiniSearch index or Obsidian's native search engine.
- Real-time Indexing: Automatically updates the search index when notes are created, modified, or deleted.
- Semantic Search: Understands the meaning of your query to find the most relevant files, even if exact keywords aren't present.
- Custom Vocabulary: Easily define vectors for new terms. Create a note where headings are your new words and the text below provides context. A command then batch-processes this file to teach your vault the new vocabulary.
- Live Heading Filter: Instantly filter the active note to show only matching headings and their content.
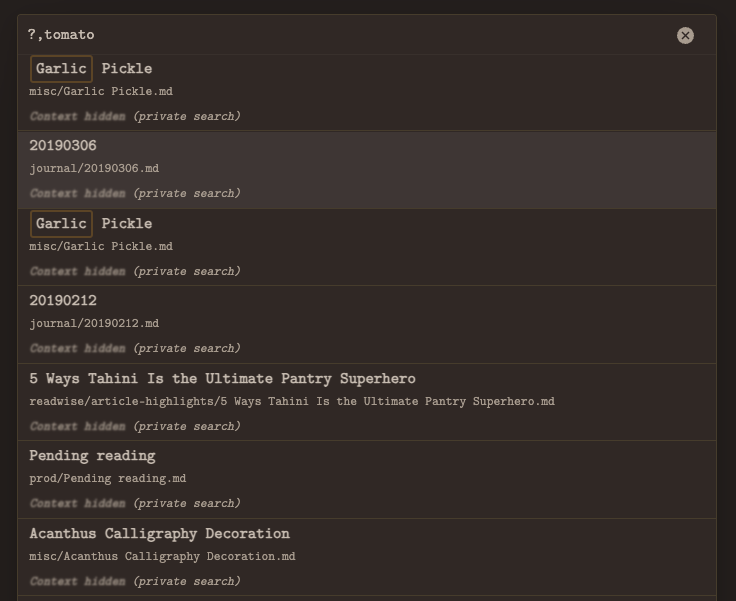
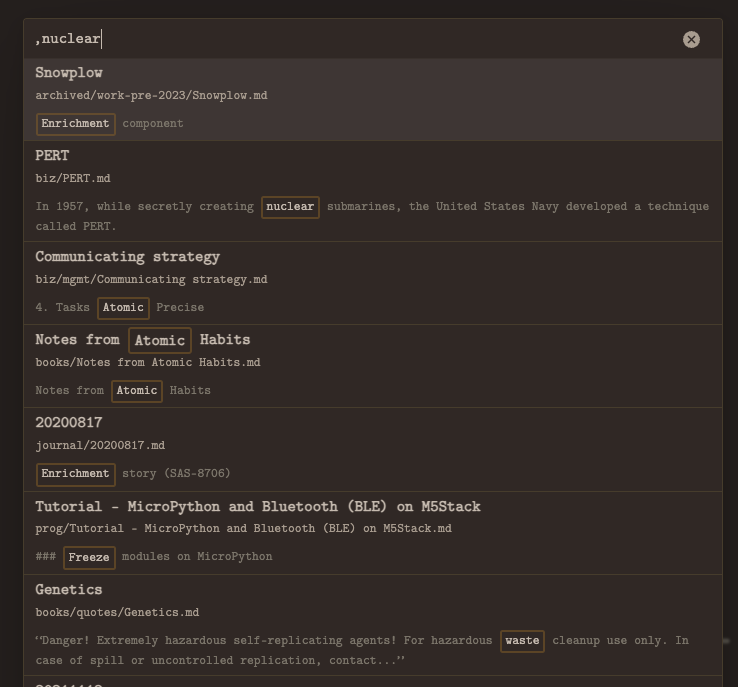
- Open Search: Use the command palette (
Ctrl/Cmd + P) and search for "Clau: Open Search". - Type your query:
- Private Search (
?): Start your query with a question mark to hide all context previews. This needs to be first. - Ignore Privacy (
!): Start your query with an exclamation mark to show all context previews, even for notes in private folders or with private tags. This needs to be first. - Title-Only Search (
- Fuzzy Search (
.): Start your query with a dot to enable typo-tolerant fuzzy matching. This needs to be first. Does not combine with semantic search, and presenting context depends a lot on the search term. - Concatenated Title Search: Titles with no spaces (e.g.,
thisHasNoSpaces) can now be found by searching for parts of the concatenated words (e.g.,hasNo). This works automatically for all title searches. - Term Exclusion (
-): Add a hyphen before a word to exclude notes containing it. Does not combine with semantic search. - Path Exclusion (
-/): Add-/before a path to exclude notes from that folder. Does not combine with semantic search (yet). - Modifiers can be combined: For example,
! . project spec -wipwill perform a fuzzy, title-only search for "project spec" while ignoring privacy and excluding notes with "wip". Note that order is important for most of these, and semantic search does not work yet with all of them. - Filter by Heading (
#): Start your query with a single hash (#) to enter a special filtering mode for the currently active note. This will immediately close the search modal. As you continue to type, the note's content will be filtered in real-time to show only headings that match your query, their sub-headings, and their content. Parent headings are kept visible to maintain context. PressEscapeto exit the filter mode and restore the full view. This is a standalone mode and does not combine with other modifiers.
- Private Search (
- Re-build index: If you encounter issues with search results, you can manually rebuild the index by searching for "Clau: Re-build index" in the command palette. Index is rebuilt automatically periodically.
You can teach Clau new, domain-specific words that don't exist in the base GloVe model using two methods. The file-based method is recommended for defining multiple terms.
-
Create a dedicated note (e.g.,
my-vocabulary.md). It's best to place this in a folder that you've configured Clau to ignore in the settings. -
In this note, use Markdown headings for each new word you want to define.
-
Under each heading, write a space-separated list of related words that define the term's context. Repeating a word gives it more weight.
# Spark

big data distributed computing cluster rdd dataframe sql streaming mapreduce hadoop parallel processing analytics data engineering apache distributed processing

# Scala

functional programming jvm object-oriented immutable sbt akka concurrent scalable type inference functional jvm functional static types
-
With this note as the active tab, open the command palette and run
Clau: Generate vectors from active file. -
Clau will process the entire file, generate vectors for all defined headings, and rebuild the semantic index.
You can use a Large Language Model to help generate the context words with a prompt like the following:
Generate a weighted list of keywords representing the core concepts of the technology specified below. Weight the list by repeating keywords. The most central concepts should be repeated most frequently. Important secondary concepts should be repeated less often. Related but non-essential terms should appear only once. The output must be a single line of text containing only space-separated, lowercase keywords. Do not include titles, explanations, or any other text.
The word to provide synonims for is
For quick, one-off definitions, select a word in any note and invoke the Clau: Vectorize selected word command from the command palette. A modal will appear where you can paste a body of text to define the word's context.
This feature allows you to select multiple notes and copy their content to the clipboard, formatted for use as a context in a Large Language Model (LLM) prompt.
- Open the command palette and run the command:
Select files to copy content. - Use the search bar to find the files you want to include. Click on a file in the search results to add it to your selection.
- Selected files appear in a list at the bottom of the modal. You can manage your selection here:
- Click the Remove button next to any file to exclude it.
- Click Clear All to empty your selection.
- Once you are satisfied with the list, click the Copy Content of X File(s) button.
This will copy the formatted content to your clipboard and close the modal.
The content of the selected files is concatenated into a single block of text. Each file is clearly delineated with a header containing its path, making it easy for an LLM to distinguish between different sources of information.
The format is as follows:
--- FILE: path/to/first-note.md ---
Content of the first note...

---

--- FILE: path/to/second-note.md ---
Content of the second note...
Why not use OmniSearch?
Tweaking your own plugin is kind of fun, also sometimes I need plugins with the minimum amount of dependencies so I can confirm the code is safe. This is small enough I can check everything manually, and does exactly what I want.
I'm getting a replacement to the QuickSwitcher that works better for how I want to move across notes. Having my own plugin has let me create the headings filter (which is a feature I find handy), as well as having a pretty fast and effective (extensible) semantic search.
To enable and use the semantic search functionality, you need to set up the GloVe word embeddings:
-
Download GloVe Vectors:
- Download the
glove.6B.zipfile from the Stanford NLP website. - Extract the
glove.6B.100d.txtfile (or your preferred dimension,100dworks well on a Mac and iPads) from the zip. - Place this file in a subfolder within your vault, for example,
your_vault/embeddings/glove.6B.100d.txt.
- Download the
-
Prepare GloVe for Desktop (Splitting):
- The plugin expects the GloVe file to be split into smaller parts for efficient loading on desktop (Obsidian doesn't "see" very large files for performance reasons).
- Use the
glove-tool.goscript (available in the plugin's GitHub repository) to split the file. Run it from your terminal:go run glove-tool.go split -input "your_vault/embeddings/glove.6B.100d.txt" -output-prefix "your_vault/embeddings/glove.6B.100d_part_"
- This will create files like
glove.6B.100d_part_1.txt,glove.6B.100d_part_2.txt, etc. - In Clau settings, set "GloVe path format" to
embeddings/glove.6B.100d_part_{}.txtand "Number of GloVe file parts" to the number of files generated. - Alternative: You can also run the Python script in
split_file.py(run it likepython split_file.py -input your_file.txt -lines 50000) to split these vectors, useful if you don't care about mobile or don't have Go installed. I didn't bother getting the pruner in Python though.
-
(for mobile use) Export Vault Vocabulary:
- In Obsidian, go to Clau settings, navigate to the "Semantic Search" section, and click the "Export Now" button under "Export vault vocabulary".
- This will create a file named
embeddings/vault_vocab.txt(or your configured path) containing all unique words from your notes.
-
(for mobile use) Generate Pruned GloVe for Mobile (Optional but Recommended):
- For better performance on mobile devices, it's recommended to create a smaller, pruned GloVe file containing only words relevant to your vault and their nearest neighbors.
- Use the
glove-tool.goscript again:go run glove-tool.go prune -glove-input "your_vault/embeddings/glove.6B.100d.txt" -vocab-input "your_vault/embeddings/vault_vocab.txt" -output "your_vault/embeddings/enhanced_pruned_vectors.txt"
- In Clau settings, set "Pruned GloVe file path" to
embeddings/enhanced_pruned_vectors.txt.
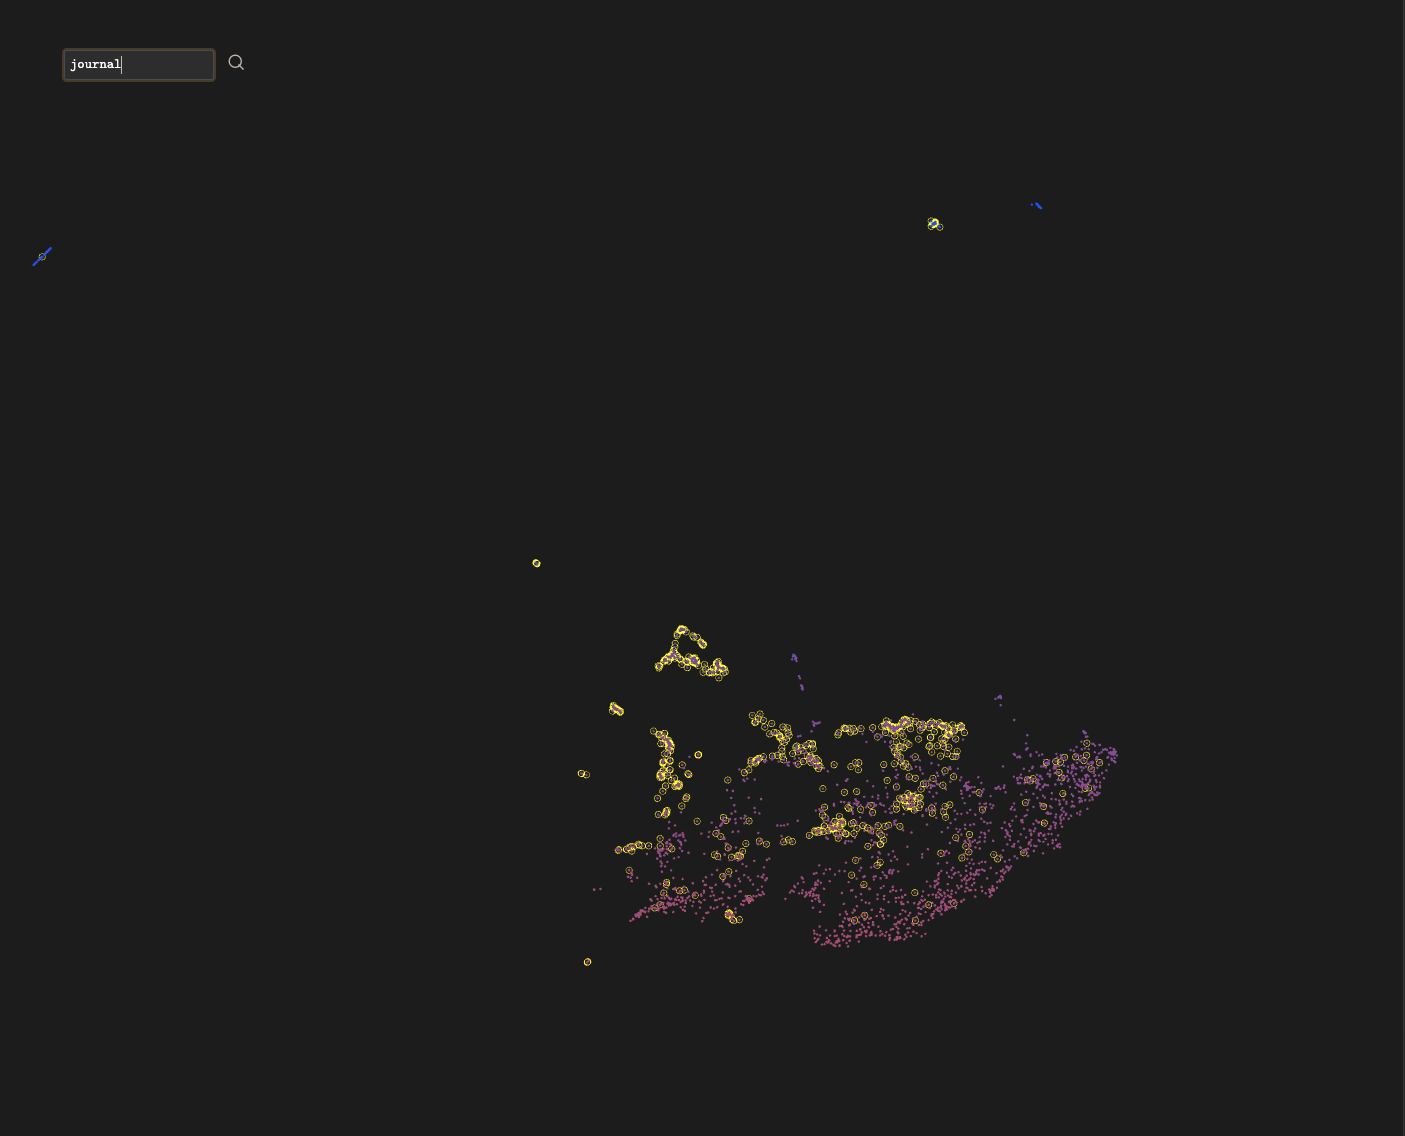
If you have semantic search configured properly you can create a UMAP plot of your vault. There is also a search field that will search using minisearch (full terms, no frills for now) by default, and will search semantically when adding a , at the beginning. Looks like this:
- Download the latest release files (
main.js,styles.css,manifest.json) from the Releases page of the GitHub repository (or the zip file, contains all of these). - Find your Obsidian vault's plugins folder by going to
Settings>Aboutand clickingOpennext toOverride config folder. Inside that folder, navigate into thepluginsdirectory. - Create a new folder named
clau. - Copy the
main.js,manifest.json,viz-bundle.js, andstyles.cssfiles into the newclaufolder. - In Obsidian, go to Settings > Community Plugins.
- Make sure "Restricted mode" is turned off. Click the "Reload plugins" button.
- Find "Clau" in the list and enable it.