Repository navigation
Clustering
DIAMOND clusters protein sequences analogous to CD-HIT or UCLUST based on a user-defined clustering criterion, finding a set of representative sequences (also called centroids) and assigning each input sequence to the cluster of one representative such that the clustering criterion vs. the representative is fulfilled. The clustering criterion is defined by sequence coverage of the local alignment as well as its sequence identity (see below). Note that due to the heuristic nature of the cascaded clustering algorithm, these cutoff values serve to guide the computation, but their fulfillment is not always guaranteed (also see Advanced options)
Basic command line example:
# fast clustering with linear scaling (30% identity cutoff)
diamond linclust -d INPUT_FILE -o OUTPUT_FILE --approx-id 30 -M 64G
# sensitive clustering using all-vs-all alignment (30% identity cutoff)
diamond cluster -d INPUT_FILE -o OUTPUT_FILE --approx-id 30 -M 64G
The linclust workflow is faster and more efficient, but less sensitive. Both workflows can be used to cluster
at any sequence identity threshold. For clustering very large datasets at higher identities of >50% the linclust
workflow is particularly recommended as clustering based on all-vs-all alignment can become very expensive here.
There is also the deepclust workflow which is identical to cluster except that
the default value for --approx-id is 0 instead of 50.
When using the clustering feature, please cite:
- Buchfink BJ, Barbé É, Ashkenazy H, Reuter K, Kennedy JA, Drost HG, "Clustering the protein universe of life using DIAMOND DeepClust", Nature Methods 23, 724-727 (2026). doi:10.1038/s41592-026-03030-z
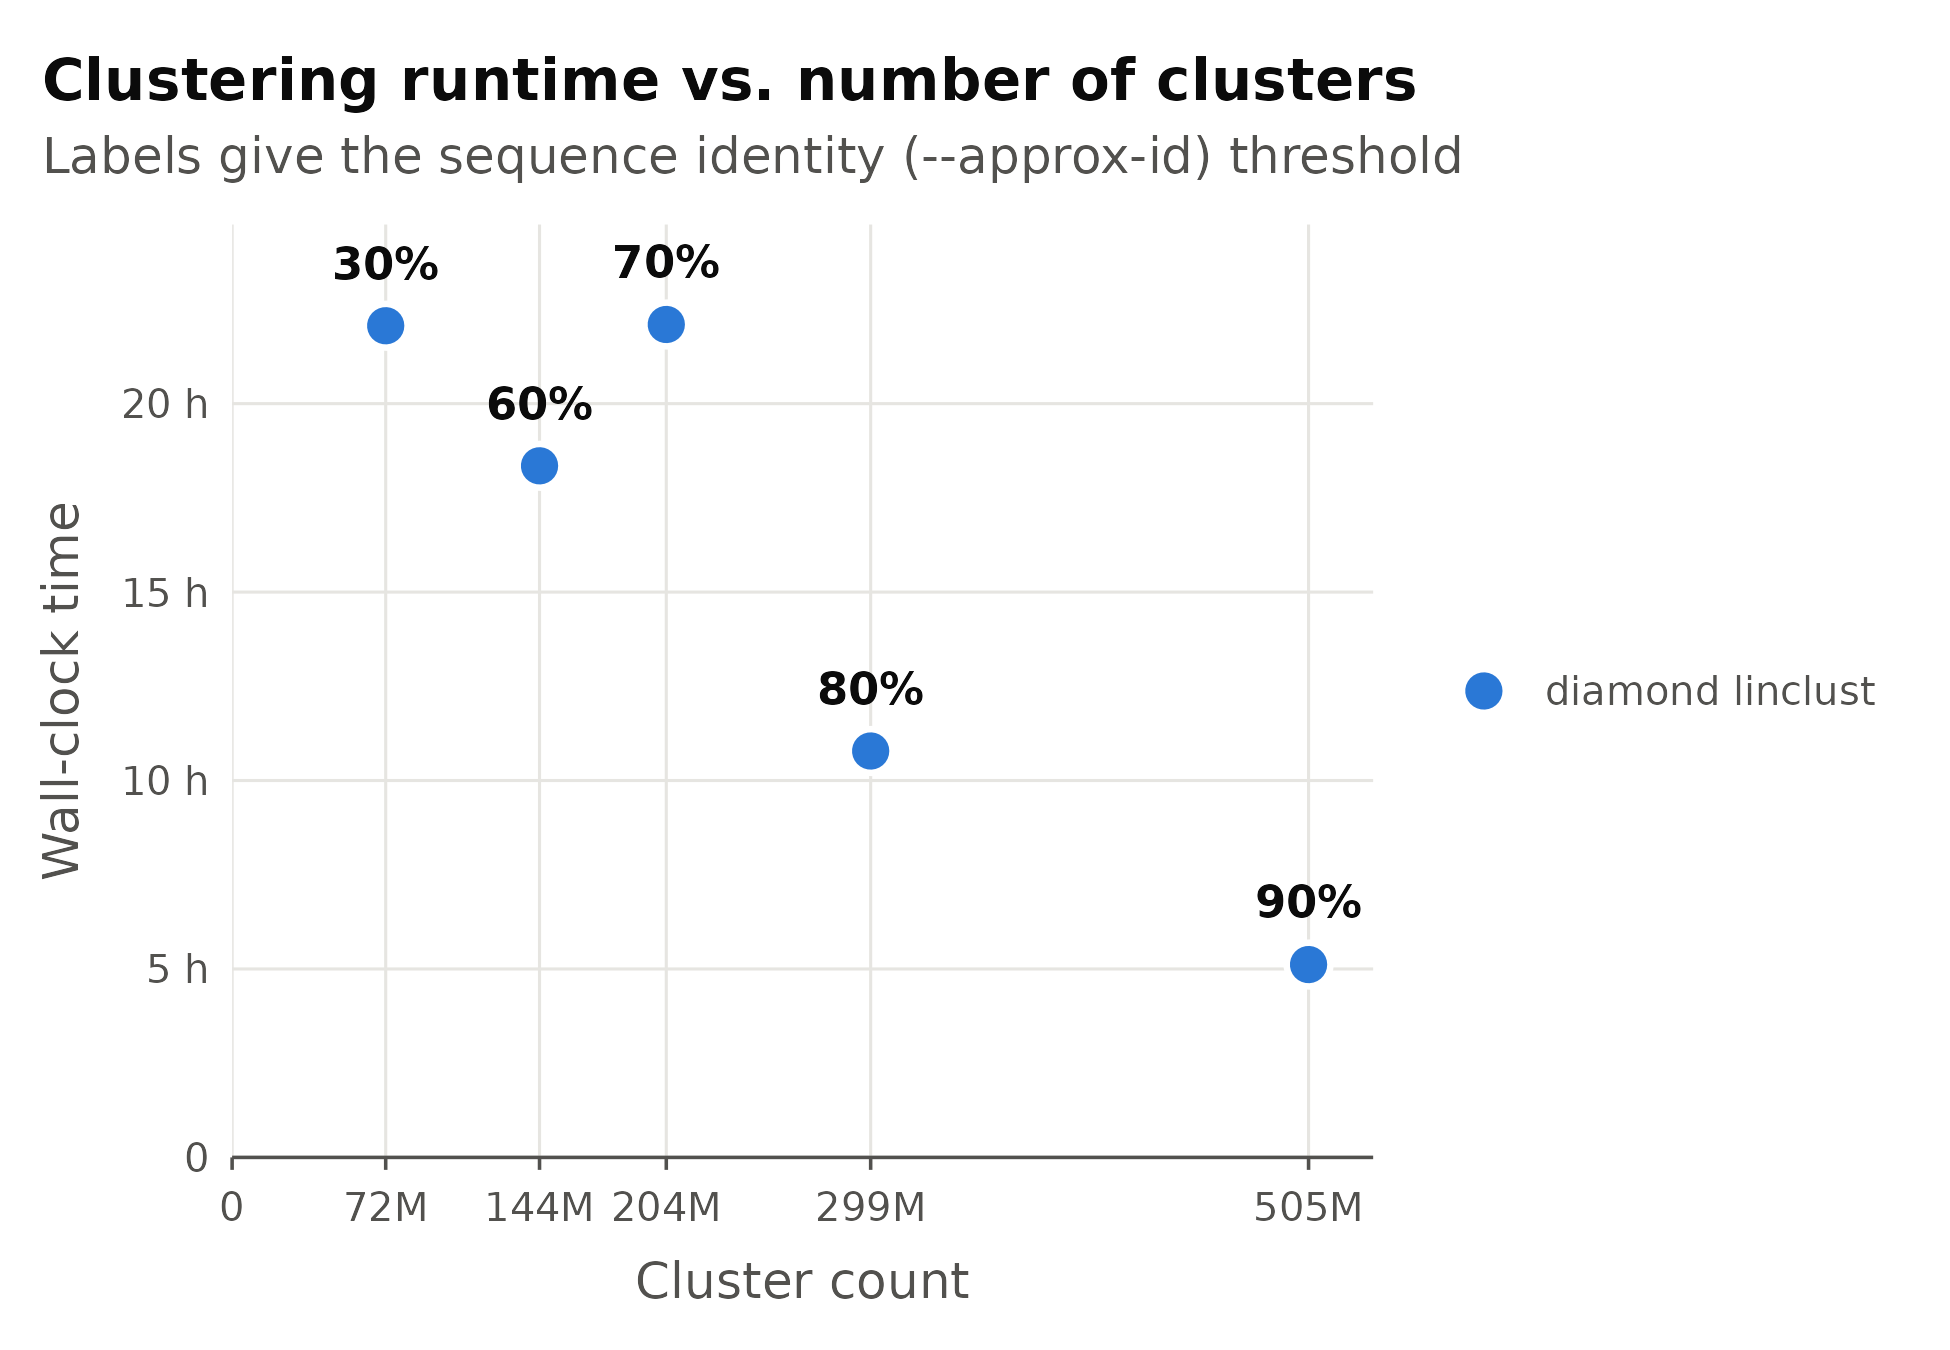
Benchmark. Time and cluster count for clustering the NCBI nr database (1.1 billion sequences) using DIAMOND v2.2.8 with 80% cluster member (uni-directional) coverage on a server with 64 cores (Intel Ice Lake) and 512 GB of memory.
Cluster an input database of protein sequences.
-
--database/-dThe input sequence database. Supported formats are FASTA, BLAST and DIAMOND (
.dmnd) format. -
--out/-oOutput file. This is a 2-column tabular file with the cluster representative accession as the first column and the cluster member sequence accession as the second column. More elaborate output can be retrieved using the
realignworkflow. -
--memory-limit/-M #Set a memory limit for the diamond process (for example:
-M 64G). Note that higher numbers increase the performance by a lot, so it is strongly recommended to always set this option.This is not a hard upper limit and may still be exceeded in certain cases. Decrease this number in case the tool fails due to running out of memory.
Higher numbers for
-Malso increase temporary disk space use, so reduce this number if a run fails due to this.Note that this option affects the algorithm and therefore the results. Clustering is a heuristic procedure with no unique solution.
-
--headerEnable a header line in the output file.
-
--approx-id #The identity cutoff for the clustering (in %). Note that for performance reasons, the setting refers to the approximate sequence identity derived as a linear regression from the bitscore, not the actual number of identities in the alignment. The default value is 90% when running
diamond linclust, 50% when runningdiamond clusterand 0% when runningdiamond deepclust. -
--id #The identity cutoff for the clustering (in %). This refers to the actual number of identities in the alignment (traceback identity) and overrides the
--approx-idparameter. Using this option incurs a performance reduction (option supported since v2.2.1). -
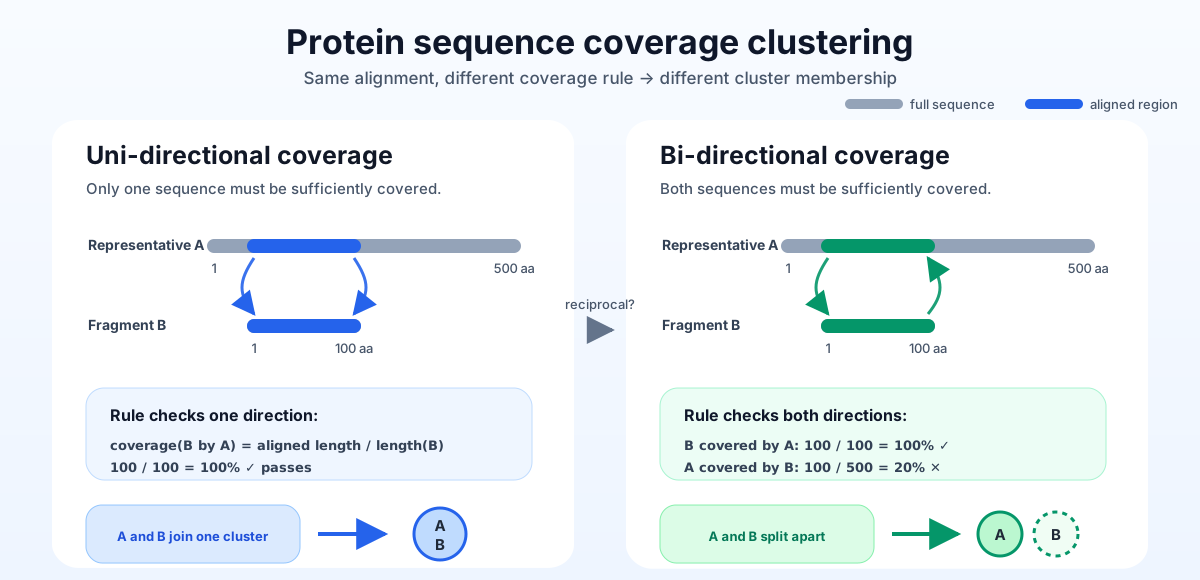
--member-cover #The minimum coverage of the cluster member sequence by the representative (in %). This is a uni-directional coverage i.e. a minimum coverage of the representative is not required. The default is 80%.
This is the tool's default mode and generally recommended for processing large datasets, the application is mainly compression/dimensionality reduction, or the data may contain many fragments, as usually happens.
-
--mutual-cover #The minimum coverage of both the cluster member sequence and the cluster representative sequence (in %). This enables bi-directional coverage clustering and overrides the
--member-coveroption.This is a more conservative setting for clustering full-length protein sequences and cluster members being required to share the same domain architecture.
-
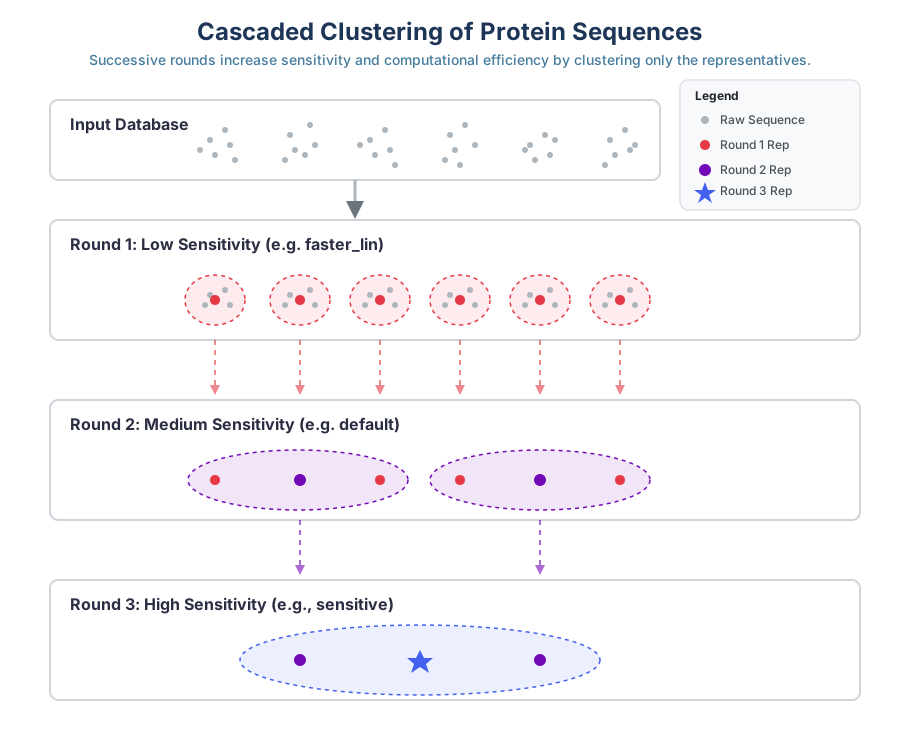
--cluster-stepsSet the sequence of clustering rounds for cascaded clustering as a space-separated list. Permitted keywords are the sensitivity switches of the alignment workflow (e.g.
sensitive). The suffix_lincan be appended to trigger linearization of the search (linclust mode) (e.g.faster_lin fast default sensitive very-sensitive). When missing, this parameter is automatically chosen based on the--approx-idparameter.
-
--parallel-tmpdirShared working directory for running multiple processes: read more
Given a clustering computed by the clustering workflows as input, this workflow computes alignments of all sequences in the original database against their assigned representative sequences.
-
--clustersThe clustering as 2-column tabular format. -
--outfmt/-fSet the output format. Only tabular format is supported for this workflow. The default corresponds to the format-f 6 qseqid sseqid approx_pident qstart qend sstart send evalue bitscoreof the alignment workflow, where the query and subject correspond to the representative and the cluster member sequence respectively.
These parameters of the cluster workflow apply accordingly: --database/-d, --out/-o, --header,
--memory-limit/-M.
Many (but not all) options of the alignment workflows can also be used for the clustering workflows,
e.g. --threads/-p, --evalue/-e.