


DimonSmart.PdfCropper is a cross-platform .NET library that intelligently trims PDF pages to actual content using two different methods.
The library exposes a simple API through PdfSmartCropper.CropAsync, which accepts a PDF document in memory and returns a new PDF with recalculated CropBox and TrimBox on every non-empty page.
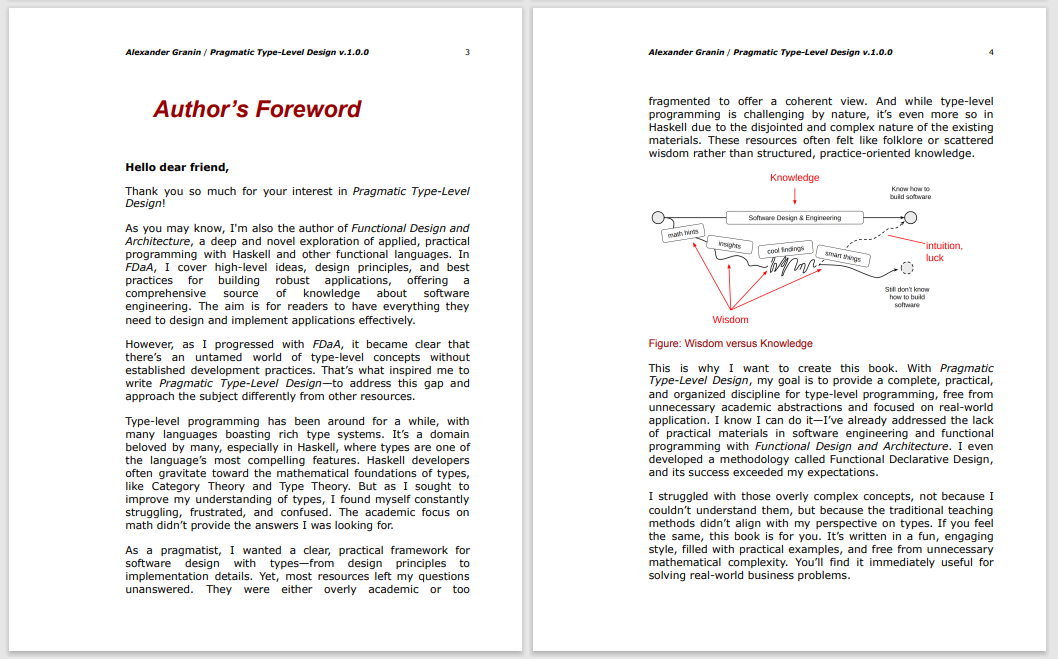
Here's a visual example of what PdfCropper does - it removes unnecessary margins and whitespace:
| Before Cropping | After Cropping |
|---|---|
 |
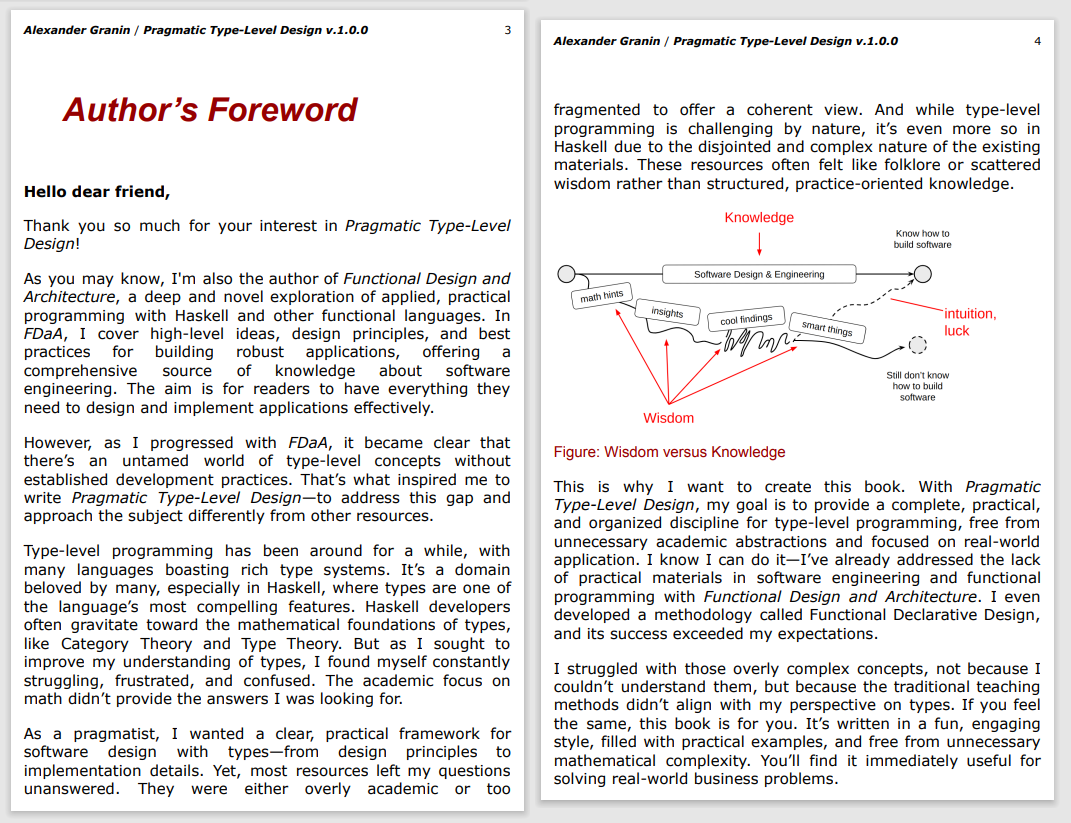 |
Example pages from "Pragmatic Type-Level Design" by Alexander Granin
The CLI utility is particularly useful for reading e-books with minimal margins, making them more comfortable to read on tablets and e-readers by removing excessive whitespace around the content.
Need the tool without compiling it yourself? Grab the latest self-contained Windows build here:
- DimonSmart.PdfCropper.Cli.exe – portable single-file executable that works on any 64-bit Windows machine.
Each tagged release also contains the NuGet package and the CLI executable as downloadable assets.
✅ Windows - Full support
✅ Linux - Full support
✅ macOS - Full support
✅ Other Unix systems - Compatible with .NET runtime
Target Frameworks: .NET 8.0, .NET 9.0, .NET 10.0
Install the package via NuGet:
dotnet add package DimonSmart.PdfCropperOr via Package Manager Console:
Install-Package DimonSmart.PdfCropper
- Two cropping methods:
- ContentBased (default): Analyzes PDF content (text, vectors, images) directly - fast and preserves quality
- BitmapBased: Renders pages to images and analyzes pixels - more accurate for complex layouts
- Preserves the existing content streams, metadata, fonts and resources
- Leaves empty pages untouched and keeps
MediaBox,BleedBoxandArtBoxintact - Handles rotated pages and maintains deterministic output
- Extensible logging through
IPdfCropLoggerinterface - Built on top of iText 9.3 and PDFium (for bitmap rendering)
using DimonSmart.PdfCropper;

byte[] cropped = await PdfSmartCropper.CropAsync(inputBytes, CropSettings.Default);
CropSettings.Default uses the ContentBased method, keeps a 0.5pt safety margin, and leaves document metadata untouched.
To set different margins per side, use CropMargins:
var settings = new CropSettings(
    CropMethod.ContentBased,
margins: new CropMargins(left: 2f, bottom: 1f, right: 3f, top: 2f));using DimonSmart.PdfCropper;
var profile = PdfCropProfiles.Aggressive;
byte[] cropped = await PdfSmartCropper.CropAsync(
inputBytes,
profile.CropSettings,
optimizationSettings: profile.OptimizationSettings,
logger: null);The aggressive preset removes edge-touching artefacts, applies maximum Deflate compression, enables smart mode, removes unused objects and metadata, clears document info, and strips embedded standard fonts.
The library ships with ready-to-use profiles for common scenarios:
| Key | Description | Crop settings | Optimization settings |
|---|---|---|---|
simple |
Default behaviour for quick cropping. | Content-based, keeps edge content, 0.5pt margin. | No extra optimisation (same as PdfOptimizationSettings.Default). |
ebook |
Recommended for reading PDFs on e-readers. | Content-based, ignores artefacts that touch the page edge, excludes repeated content, 1pt margin. | Default optimisation. |
aggressive |
Tight crop plus the strongest clean-up and compression. | Content-based, ignores edge artefacts, excludes repeated content, 0.25pt margin. | Full compression, smart mode, unused-object removal, metadata cleanup, PDF 1.7 target. |
Retrieve a profile via PdfCropProfiles.Simple, PdfCropProfiles.Ebook, or PdfCropProfiles.Aggressive. You can also resolve a profile dynamically by key: PdfCropProfiles.TryGet("ebook", out var profile).
using DimonSmart.PdfCropper;

public sealed class MyLogger : IPdfCropLogger
{
    public void LogInfo(string message) => Console.WriteLine($"[INFO] {message}");
    public void LogWarning(string message) => Console.WriteLine($"[WARN] {message}");
    public void LogError(string message) => Console.Error.WriteLine($"[ERROR] {message}");
}

var logger = new MyLogger();
byte[] cropped = await PdfSmartCropper.CropAsync(inputBytes, CropSettings.Default, logger);
Every overload throws PdfCropException with a PdfCropErrorCode when the input PDF is invalid, encrypted, or fails to process.
The repository includes a console application that wraps the library. This CLI tool is especially useful for preparing e-books and documents for comfortable reading on tablets and e-readers by removing excessive margins and whitespace.
Perfect for e-book readers: Transform PDF books with large margins into reader-friendly versions that utilize screen space more efficiently.
# Run the ready-made Windows build (download link above)
DimonSmart.PdfCropper.Cli.exe input.pdf output.pdf

# Use the e-book preset (ignores edge artefacts, keeps 1pt margin)
DimonSmart.PdfCropper.Cli.exe input.pdf output.pdf --preset ebook

# Apply the aggressive preset with verbose logging
DimonSmart.PdfCropper.Cli.exe input.pdf output.pdf --preset aggressive -v

# Emit detailed diagnostics for a single page
DimonSmart.PdfCropper.Cli.exe input.pdf output.pdf --debug-page 2

# Apply per-side margins
DimonSmart.PdfCropper.Cli.exe input.pdf output.pdf --margin-left 1 --margin-right 3 --margin-top 2 --margin-bottom 0.5

# Merge multiple PDFs matched by a mask into a single output
DimonSmart.PdfCropper.Cli.exe "scans/*.pdf" merged/scans.pdf --merge

# From source (cross-platform)
dotnet run --project src/DimonSmart.PdfCropper.Cli/DimonSmart.PdfCropper.Cli.csproj -- input.pdf output.pdf --preset simple--preset <simple|ebook|aggressive>- Apply a predefined set of crop/optimisation options-m, --method <0|1>- Cropping method:0= ContentBased (default, analyzes PDF content)1= BitmapBased (renders to image, slower but more accurate)
--margin <points>- Uniform safety margin in points around content (default: 0.5)--margin-left <points>- Left safety margin in points--margin-bottom <points>- Bottom safety margin in points--margin-right <points>- Right safety margin in points--margin-top <points>- Top safety margin in points--merge- Crop every matched input and merge the results into a single PDF. Requires an explicit output file path without wildcards.-v, --verbose- Enable verbose logging--debug-page <n>- Emit extended diagnostics for a single page (1-based index). Enables info logging if none is set.- All low-level switches (
--margin,--margin-left,--compression-level,--smart, etc.) remain available to fine-tune or override a preset
Tip: When using --merge, the output argument must be a file (for example merged/book.pdf). Directory paths or wildcard masks are not allowed because the tool produces one PDF.
| Feature | ContentBased | BitmapBased |
|---|---|---|
| Speed | ⚡ Fast | 🐌 Slower |
| Quality | ✅ Preserves vector quality | ✅ Preserves vector quality |
| Accuracy | Good for standard documents | Better for complex layouts |
| Use case | Most PDFs | PDFs with complex graphics |
- Library target frameworks:
.NET 8.0,.NET 9.0,.NET 10.0 - Cross-platform support: Windows, Linux, macOS, and other Unix systems
- Dependencies:
- iText 9.6.0 (PDF manipulation)
- PDFtoImage 5.2.0 (PDF to bitmap rendering) - includes native libraries for all platforms
- SkiaSharp (image processing) - cross-platform 2D graphics
- Tests are located in
tests/PdfCropper.Testsand use xUnit - Build with
dotnet build PdfCropper.sln - Run tests with
dotnet test PdfCropper.sln - CI/CD: Automated builds and tests via GitHub Actions - see GitHub Actions Setup
- Linux: Requires
libfontconfig1andlibgdiplusfor optimal PDF rendering - macOS: No additional dependencies required
- Windows: No additional dependencies required
public interface IPdfCropLogger
{
    void LogInfo(string message);
    void LogWarning(string message);
    void LogError(string message);
}public interface IPdfCropDebugLogger
{
bool ShouldLogDebugForPage(int pageIndex);
int MaxObjectLogs { get; }
}public enum CropMethod
{
ContentBased = 0, // Analyzes PDF content
BitmapBased = 1 // Renders to bitmap
}