Repository navigation
v1.0.0b1
Pre-release
[BETA] This is a beta release, and I would love to get feedback on this direction!
It's finally here! This is the first beta of BERTopic 1.0 (there will definitely be more).
My idea was to rewrite a lot of what was under the hood while its API stays as it was wherever possible. This would make it easier for future development and increase stability of the underlying code.
As with any pre-release, you can only install it when explicitly running:
pip install bertopic==1.0.0b1
Nothing changes for those that are using BERTopic in production or in their pipelines, you will still install 0.17.4 unless you specifically run the above command.
If anything breaks (and I have no doubt it will with this first beta), please let me know in the issues.
Some code will need a small update, which the migration guide shows for every change.
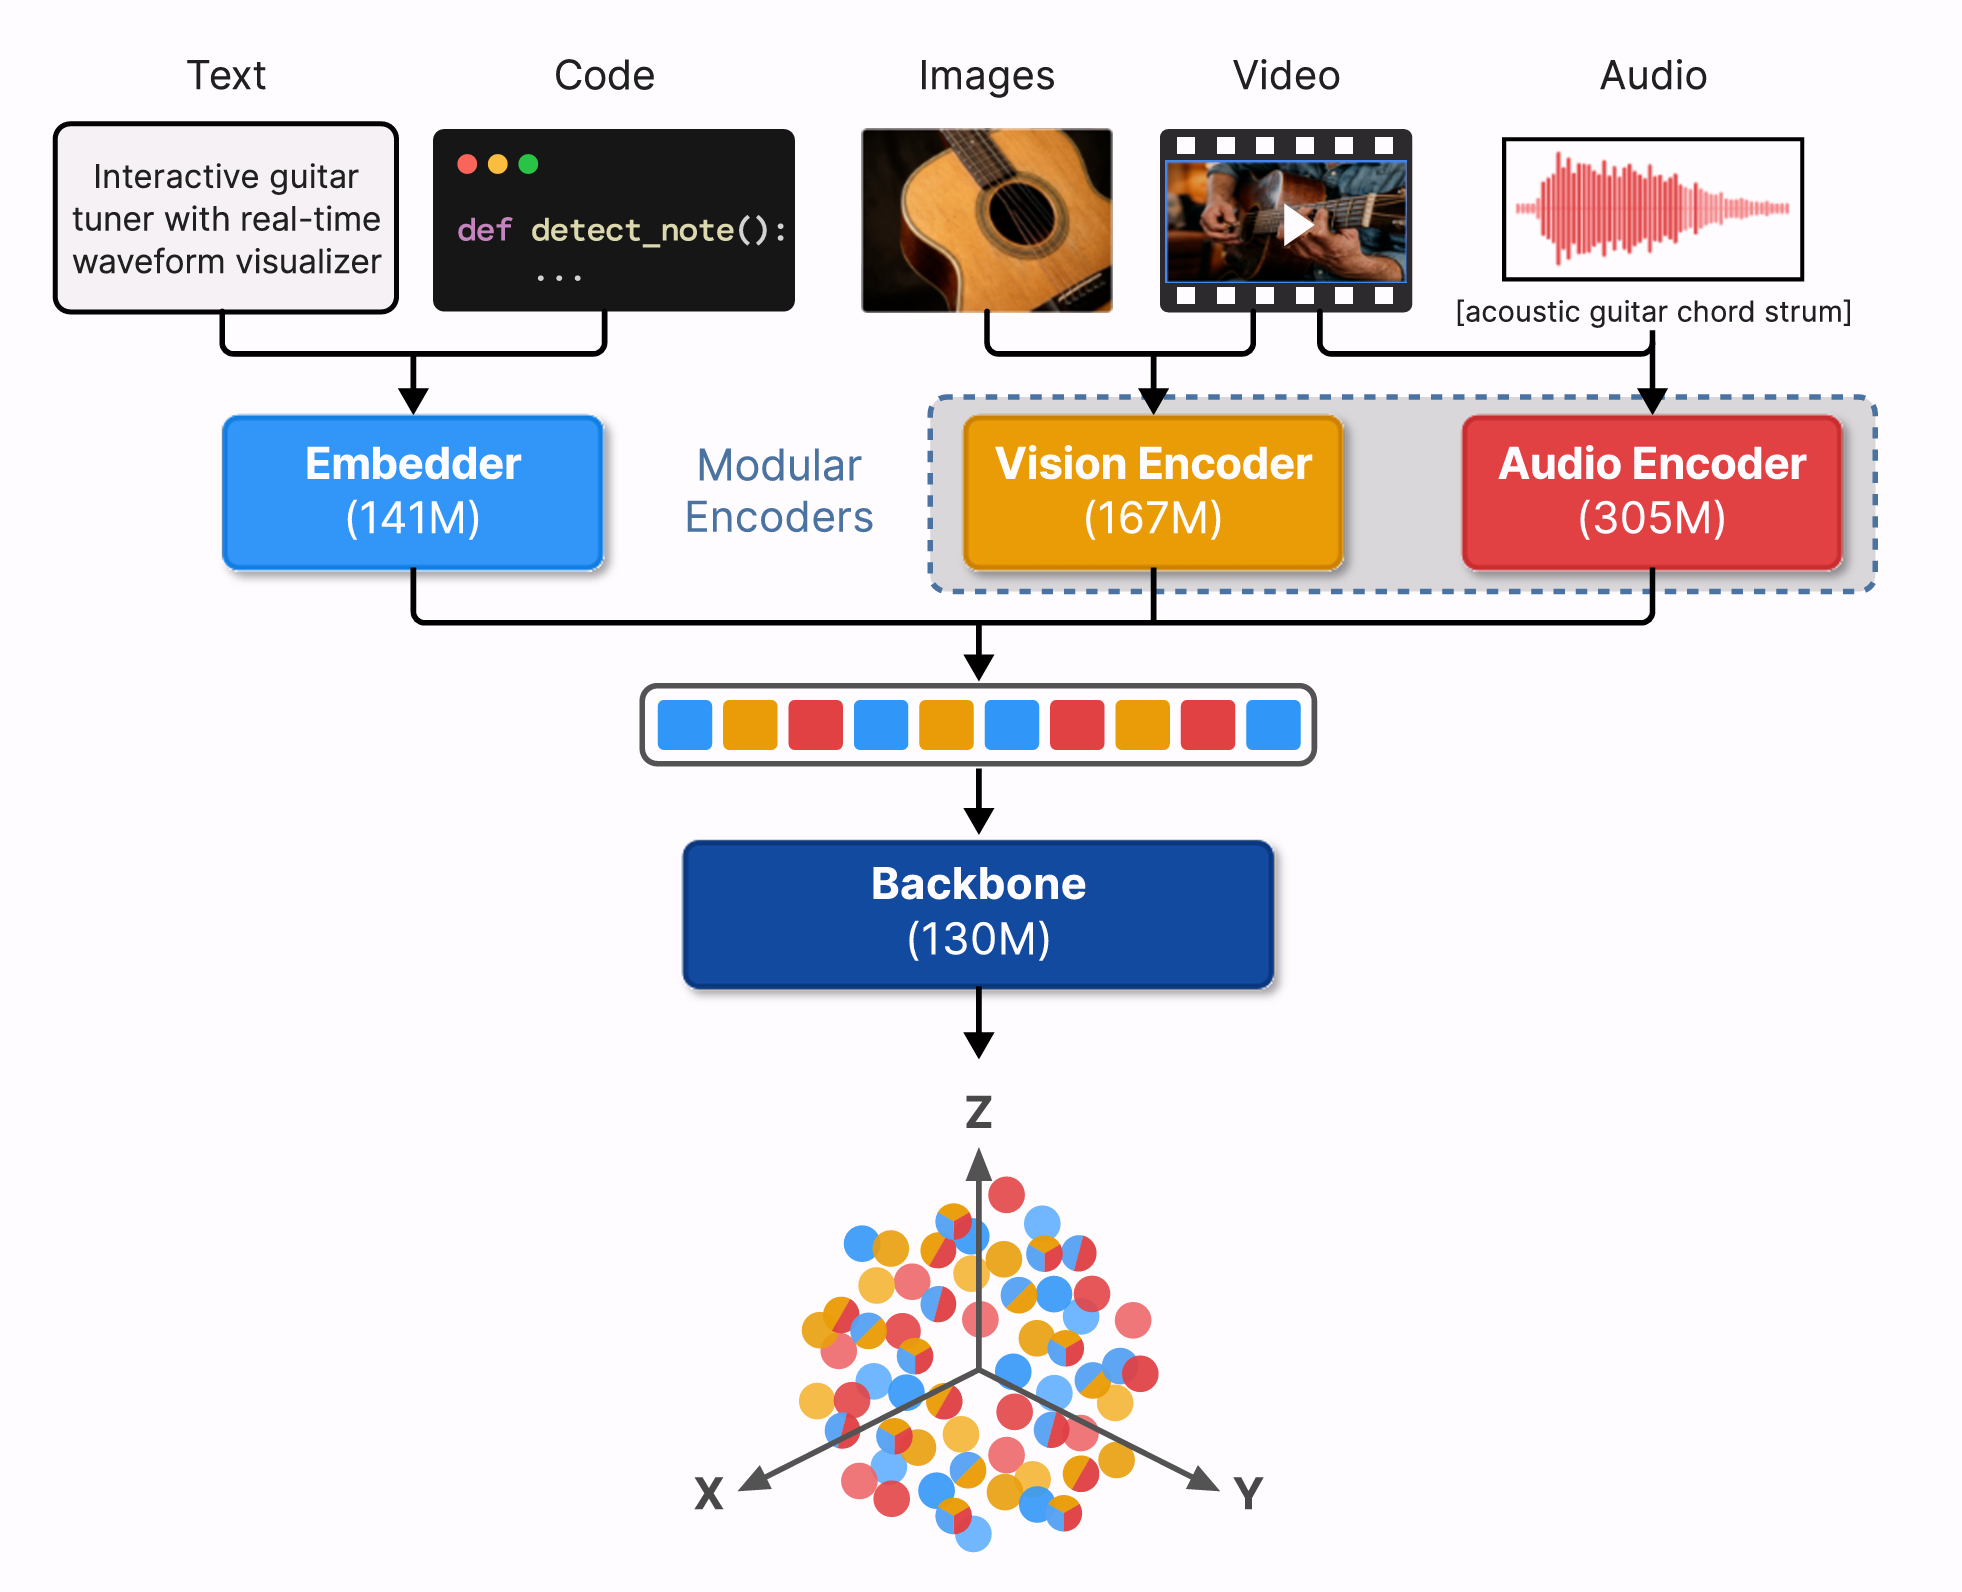
EmbeddingGemma 2, the new default embedding model, embeds text, code, images, video and audio in one space.
Highlights:
- Multimodal topic modeling with text, images, audio, video and code
- Pass them to
.fit_transformwithimages=,audio=,video=andcode=, with or without documents MultiModalRepresentationdescribes images and frames of videos with a vision model and transcribes audio with a speech model, such as Whisper, so topics of media get keywords too- See each topic's collage, frame sheet and audio montage with
.visualize_media()
- Pass them to
- EmbeddingGemma 2 is the new default embedding model
BERTopic()uses its text model for every language, andBERTopic(embedding_model="google/embeddinggemma-2")also embeds images, audio and video in the same space- BERTopic embeds the first 1,024 tokens of each document, since the model sets no length limit of its own
- LLM representations were rewritten around one request loop, with
Ollamaas a new representation model, structured output and current default models - Get polars instead of pandas dataframes with
bertopic.set_output("polars") - Added support for Python 3.14
- 80 issues fixed, all listed below
Multimodal:
.fit,.fit_transform,.transform,.update_topics,.merge_topics,.reduce_topicsand.reduce_outlierstakeimages=,audio=,video=andcode=- With as many documents as items, each document describes the item at its position, as a caption does
- With any other number, the documents are rows of their own, so you can model unrelated documents and media together
- Media can be passed as file paths, which is advised, or in memory
MultiModalBackendtakes one model for every kind, or a model for each kind withimage_model=,audio_model=,video_model=andcode_model=.embed_media(items, modality)embeds items of one kind, such as.embed_media(images, "image")- Media is embedded a few items at a time (16 images, 4 recordings or 1 video), since one video can be thousands of tokens
MultiModalRepresentationreplacesVisualRepresentation- It describes up to nine items of each kind per topic, with a model for each kind (
image_model=,audio_model=andvideo_model=), and the descriptions become the topic's keywords - A model can be a name, a transformers pipeline or any callable, such as a call to an API
- Items that already have text, such as captioned images, keep it
- Video is described through three frames of each clip, taken from the middle of equal stretches of the clip, which you can change with
nr_frames=
- It describes up to nine items of each kind per topic, with a model for each kind (
- Every topic gets one summary per kind of media: a collage of its images, a frame sheet of its videos and a montage of the first two seconds of its recordings
representative_items_holds every topic's representative media, andrepresentative_images_its collage.get_topic_info()shows them in aRepresentative_Itemscolumn
.visualize_media()shows each topic's collage, frame sheet and montage in a table, which a notebook shows inline.visualize_document_datamap()takes the same media as.fit, and shows an image, or a video's middle frame, when you hover over its point- Saving with
safetensorsorpytorchkeeps every summary, and the representative items as their paths - Two new extras:
pip install bertopic[audio]andpip install bertopic[video]
Embeddings:
- EmbeddingGemma 2 (
google/embeddinggemma-2) is the default embedding model for every languageBERTopic()loads only its text model, and passing its name loads the full model, which also embeds images, audio and video- Documents get its
Clusteringprompt, and short texts that BERTopic compares with documents, such as search terms, zero-shot labels, seed words and keywords, are embedded without it - Without a GPU that runs bfloat16 natively, as on most CPUs, a model loaded by name runs in float32, which is several times faster there
- A custom backend can define
embed_wordsto embed those short texts differently from documents .update_topicstakesembeddings=to calculate the topic embeddings from your document embeddings
Representations:
.get_representation(topic, aspect)returns a topic's full representation, such as itsKeywords, an LLM'sLabel, aStructuredJSONanswer or itsMedia, while.get_topickeeps returning words and scores- LLM representations share one request loop, so a custom LLM representation only needs to implement
_generate(prompt)- Added
Ollamaas a representation model - Pass
json_schema=True, or a schema of your own, for a structured answer, which is kept as aStructuredJSONrepresentation - An answer without a label, or a prompt that OpenAI refuses for its content, gets "No label returned" and a warning, so one topic does not stop the fit
OpenAIandLiteLLMdefault togpt-6-lunaandCoheretocommand-r7b-12-2024
- Added
TextGenerationsends models with a chat template their prompt as a chat message, and usesDEFAULT_CHAT_PROMPTfor them by defaultLlamaCPP("model.gguf")works again and uses the chat template in the GGUF, with a 16,384-token context
Changes in behaviour:
These change your output without raising an error:
probabilities_has one column per topic, including the outlier topic when there is one, and each row sums to 1. The matrix from.transformhas the same columns, and.delete_topicsadds the probabilities of a deleted topic to the outlier topic- Representative documents are sampled differently than in 0.17.4, so they can differ, and a topic no longer lists the same document twice
evolution_tuning=True, the default in.topics_over_time, now averages each timestamp with the previous one as documented, and global tuning uses each topic's own row.update_topicskeeps your vectorizer, c-TF-IDF and representation models instead of resetting them to their defaults.topics_over_time,.topics_per_classand.hierarchical_topicsshow c-TF-IDF keywords. Passuse_representation_model=Trueto run your representation model on every timestamp, class or merged topicnr_topicsand.reduce_topicsnever merge zero-shot topics, which keep their names, sonr_topicsmust be larger than the number of zero-shot topics plus the outlier topicMaximalMarginalRelevancewithout an embedding model returns itstop_n_wordsinstead of 30 words.find_topicsno longer returns the outlier topic- A topic that is listed twice in a plot's
topics=is drawn once .get_document_info(docs, df=df)puts the columns ofdffirst
API Changes:
The migration guide shows the code for each of these:
VisualRepresentationis replaced byMultiModalRepresentation(image_model=...)- Fitted attributes, such as
topics_,topic_sizes_andc_tf_idf_, can no longer be overwritten. Use.update_topics(docs, topics=new_topics)instead, and removetopic_model.topics_ = ...from online topic modeling, since.partial_fitnow keeps track of all topics itself - The media aspect no longer gets a column of its own in
.get_topic_info(), andtopic_aspects_holds its captions LangChaintakes a chat model instead of a chain,Coheretakes acohere.ClientV2,LlamaCPP'spipeline_kwargsis nowgenerator_kwargs, andOpenAIno longer acceptschat=TrueTopicMapper,topic_mapper_andmappings_are removed- An
embedding_modelthat BERTopic does not recognise, such as a lambda, raises aTypeErrorinstead of being replaced byall-MiniLM-L6-v2 - Models that 0.17.4 or earlier saved with
safetensorsorpytorchload as before, but a pickled model, which.savegives by default, has to be saved again withsafetensorsin 0.17.4 first - A saved pointer to a model with a
Clusteringprompt, such asgoogle/embeddinggemma-300m, now embeds new documents with that prompt
Under the hood:
- Topics are no longer tracked in pandas dataframes.
Topics,Topic,Corpus,TopicMappingandTopicHierarchyhold all topic and document information, andtopic_model.topicsgives you theTopicsobject - Each row of the
Corpushas a modality, which is what multimodal topic modeling builds on - Representations are typed:
Keywords,Label,StructuredJSONandMedia - Probability columns follow the topic IDs, and one mapping keeps predictions, probabilities and topics in line through merging, reducing and deleting topics
- Dataframes are created through narwhals, so BERTopic returns pandas by default and polars with
bertopic.set_output("polars") hierarchy_holds the last calculated hierarchy, which.get_topic_tree()uses when you pass none- A much larger test suite, with tests on the topic data layer, rules that hold for every fitted model, the public signatures of 0.17.4, and every LLM representation without an API key
- Custom representation models implement
.extract_topics(topic_model, corpus, topic_representations, c_tf_idf)and return a representation for each topic, such asKeywordsorLabel MultiModalBackend.embed_imagesis replaced by.embed_media(images, "image"), and.embedno longer takes imagesTextGenerationtakestext-generationpipelines only, since transformers 5 removedtext2text-generation, and a prompt with a chat template written in by hand gets it twiceWordDocEmbedderandBaseEmbedder'sword_embedding_modelare removed- CI runs on Python 3.11 to 3.14
Dependencies:
- Python 3.11 or newer, so Python 3.10 is no longer supported
sentence-transformers>=6.1andtransformers[vision]>=5.19, which installs Pillow and torchvision since EmbeddingGemma 2 needs them even for textnarwhals>=2.0- polars is optional, for
bertopic.set_output("polars") - New extras:
audio(librosa and soundfile) andvideo(torchcodec)
Fixes:
- Probabilities and
.transformprobabilities_has a column for every topic, including the outlier topic, so each row sums to 1 and every column lines up with its topic (#905, #1508, #1807, #2017)- Probabilities follow the custom topics passed to
.update_topics(#1387) .visualize_distributionshows the outlier topic (#1424)- Documents are optional in
.transform, so you can predict from embeddings alone (#366) .transformtakes a single document with a 1-D embedding (#2018)
- Outlier reduction and
.update_topics.update_topicskeeps your vectorizer, c-TF-IDF and representation models, so stop words and n-grams survive outlier reduction (#1638, #2114, #2148)- Topic embeddings follow the documents in
.update_topics, also after saving and loading, andembeddings=gives the exact centroids (#1861, #2198, #2316) .reduce_outlierson a merged or loaded model raises a clear error that points to.update_topics(docs)(#1944)
- Topic reduction, merging and deleting
nr_topics="auto"works when every document is an outlier (#1559, #1893, #1925).merge_modelskeeps custom labels and representative documents (#1692, #2222).delete_topicsworks after.set_topic_labels, and.topics_over_timeafter.delete_topics(#2529, #2530).hierarchical_topicsand.topics_over_timeon a merged model raise a clear error that points to.update_topics(docs)(#1682, #1700, #2152, #2343)- Documented that saved models do not keep their representation models, so set
topic_model.representation_modelafter loading to update aspects with.reduce_topics(#2035)
- Zero-shot and guided topic modeling
- Hierarchical topics and topics over time
- Distances within floating-point noise of zero no longer crash
.hierarchical_topics(#1418, #1573) - The progress bar of
.hierarchical_topicsfollowsverbose(#1908) .hierarchical_topics(use_representation_model=True)names the merged topics with your representation model (#2503)- Evolution tuning in
.topics_over_timetakes effect (#2370)
- Distances within floating-point noise of zero no longer crash
- Online topic modeling
- Saving and loading
- Representations
- LLM representations
- Added
Ollama(#1824) and movedLangChainto chat models (#2187) OpenAIno longer forcesstop="\n", which GPT-5 rejects and which cut thinking models short (#2423, #2469, #2481)- A prompt that OpenAI refuses for its content, or an empty answer, gets "No label returned" instead of stopping the fit (#2342, #1979, #2353)
- Every LLM representation is tested without an API key (#2051)
- Added
- Embeddings and installation
import bertopicno longer fails when an optional package, such asopenaiorlangchain, cannot be imported (#1655, #1973)- The minimum version of sentence-transformers is one that BERTopic runs on (#2331)
- An
embedding_modelthat BERTopic does not recognise raises aTypeErrorinstead of being replaced by MiniLM (#1952) - Model2Vec backends no longer share their distillation vocabulary (#2544)
- A vocabulary of a single word works (#2034)
- Documented that
language="english"removes characters such as German umlauts, whichlanguage="multilingual"keeps (#2468)
- Visualizations and search
custom_labelswith an aspect works in.visualize_hierarchyand.visualize_topics_over_time(#1503, #1504).visualize_topicsraises a clear error with fewer than 3 topics (#1512, #2247, #2363)- A dataframe passed as
docsraises a clear error (#1589) .visualize_topics_per_classand.visualize_topics_over_timeno longer change the dataframe you pass (#2154).find_topicstakes a list of search terms (#2392, #2475)
- Multimodal
- Development
Thank you:
A big thank you to everyone who opened an issue that is fixed in this release: @1jamesthompson1, @6801318d8d, @aerithnetzer, @Afloat16, @ajdapretnar, @akalra03, @alegallo1511, @anirban-mu, @aw578, @aymanmh, @chadlillian, @chentitus, @daianacric95, @DamienBukudjian, @dhammo2, @donottakemyusername, @ElskeNijhof, @eschaffn, @felipeinagaki, @franz101, @GiannisKav, @gnimpf, @Hanqingxu123, @henrique-back, @huisman, @inesmcm26, @IsaacGreenMachine, @jhrystrom, @jianzhang-ia, @kevinmneal-archive, @luismavs, @mad-carto, @manas007, @mepearson, @MHZach, @mjaved-nz, @mzeres, @nabsiddiqui, @nhansendev, @noelleninja, @nrydanov, @OnAnd0n, @Paignn, @peiguo9028, @pidefrem, @PipaFlores, @powerhorse1986, @raffaelemancuso, @rap8, @rcprati, @rhys-thompson-deel, @sam-baumann, @schoobani, @sdehm, @sercankiyak, @shivamtawari, @shj37, @Skar0, @SkylarOconnell, @soonernotfaster, @stevetracvc, @sutgeorge, @terilias, @TheAIMagics, @vidieo, @yml-blog, @yourlogarithm, @zilch42, @zpbrent.