Repository navigation

Replies: 2 comments 1 reply

|
@cmuentes Hi, this looks like a bug. Also, could you please reset the generation settings to their defaults (ellipsis in the top-right corner → Generation Settings → Reset / Reset to System Settings) and see if that helps? We have a Poco F8 Ultra device as well, so I will take a look and share the resutls. |

|
I've currently got v1.18.0 (148). Settings screenshot is attached. Note that I've tried with context settings as low as 1024 all the way up to 8192 as part of this issue. 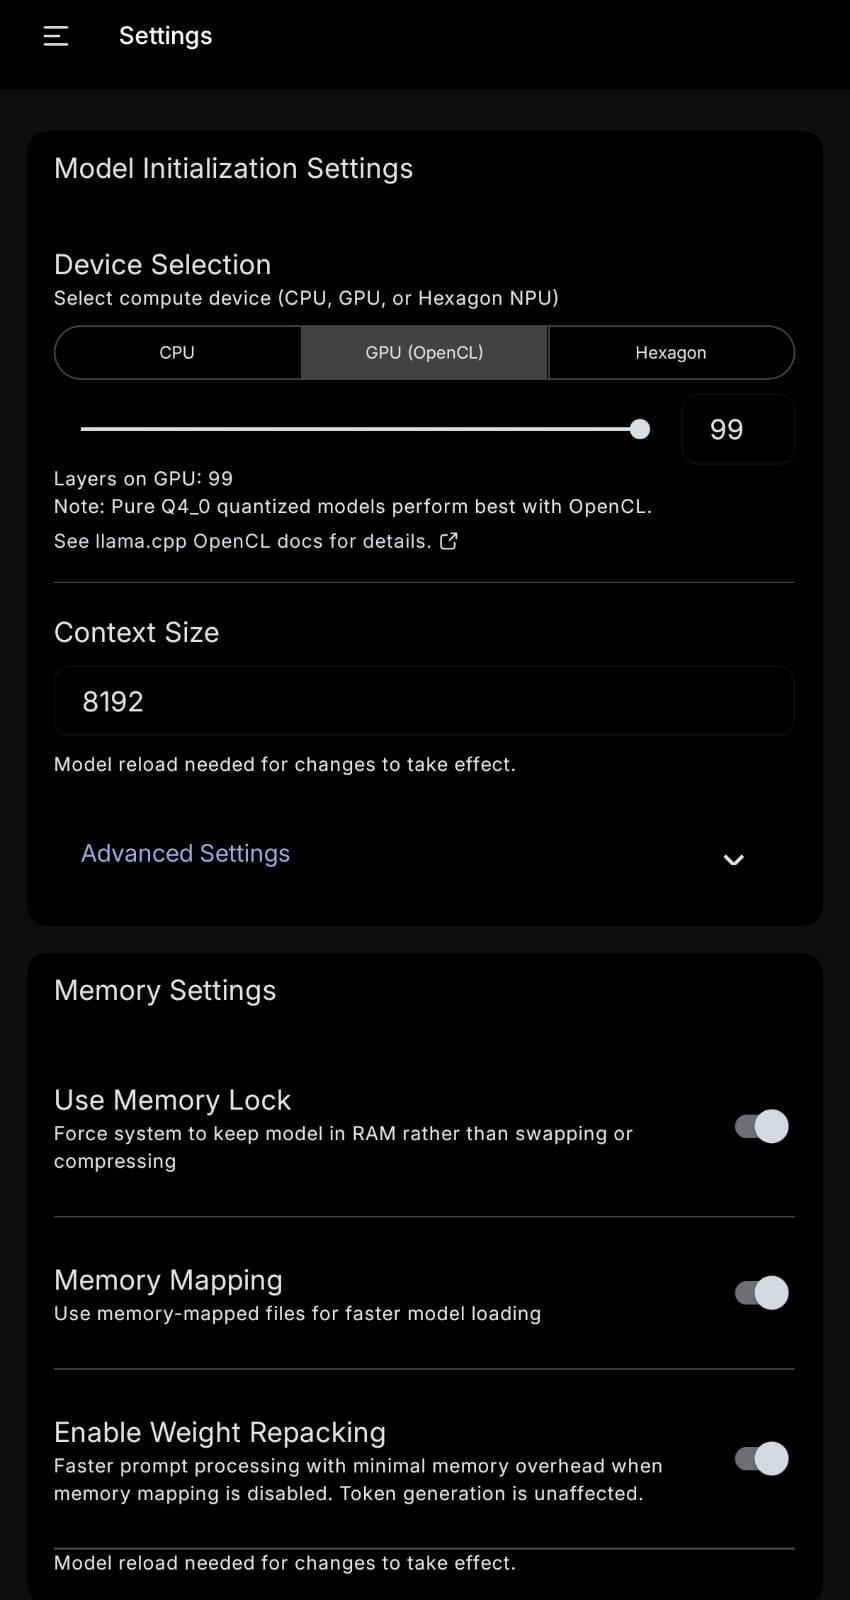
|

|
This is weird. I have the same phone and can't reproduce this issue (i tried 1.18.0 as well as 1.19.0). Have you tried resetting the generation settings? 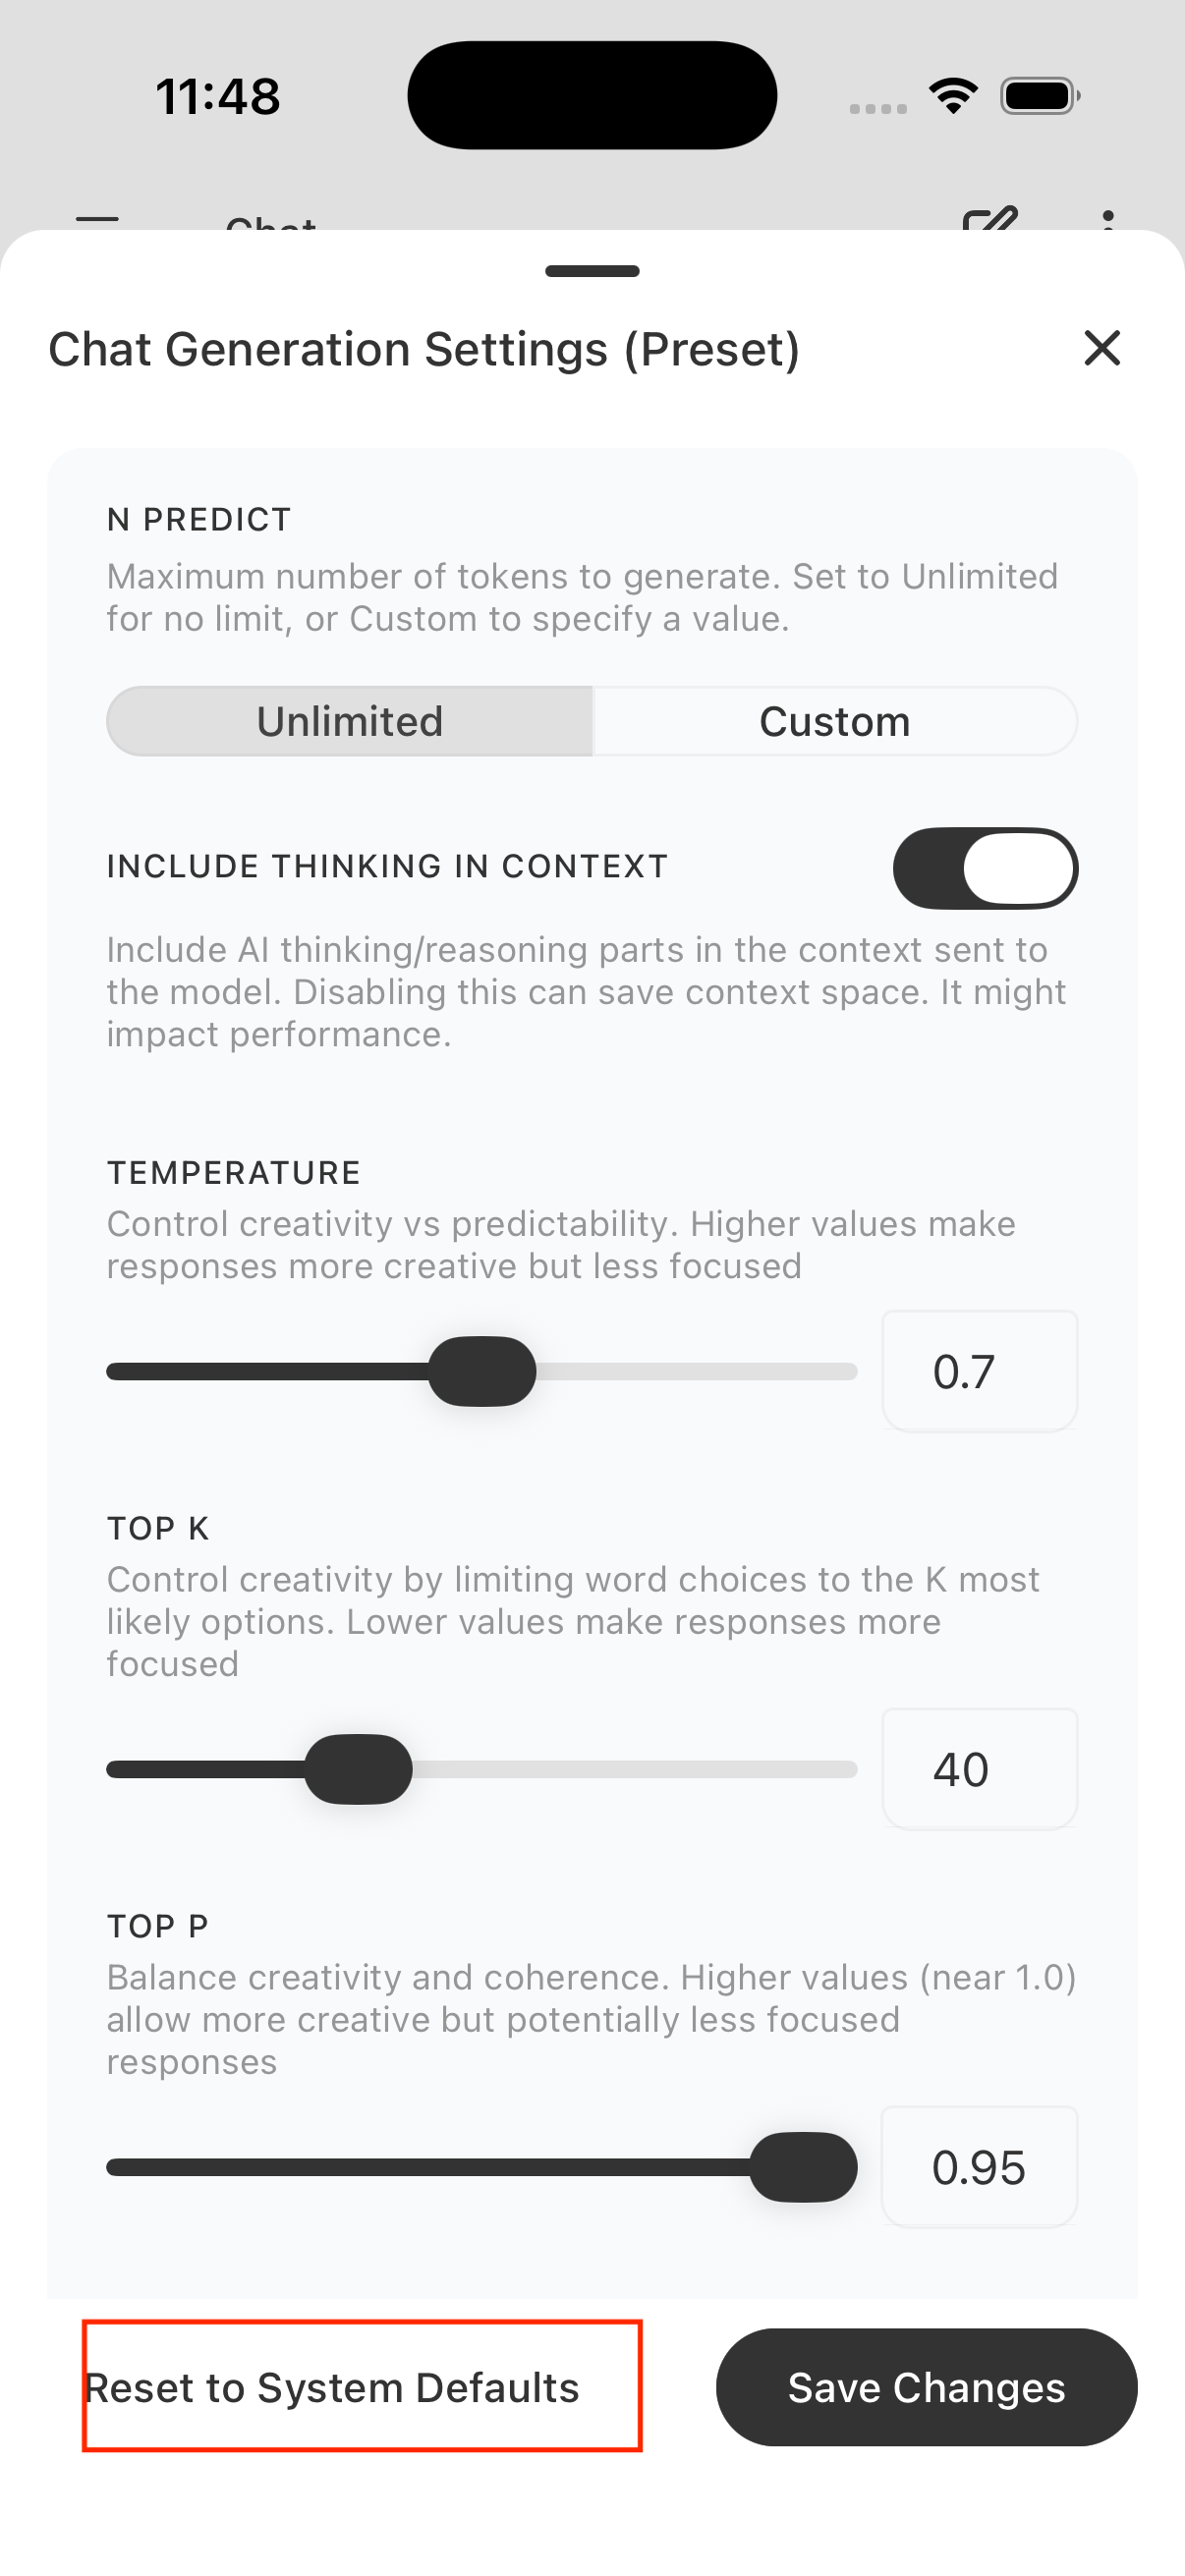
|


Uh oh!
There was an error while loading. Please reload this page.
Hello - I'm trying to set up a Perplexity-alternative using my Poco F8 Ultra with 16gb of RAM. I have the Gemma 4 E2B and E4B models working but for both models, but especially for E4B, my phone gets extremely warm (not too hot to the touch or anything) and I can watch my battery drain even though this phone has a pretty large battery. For that reason I've been looking for other small models, especially 4B models, that can maybe work as a "Flash" model for quick answers without the excessive heat or battery draining.
So I decided to try some of the models the PocketPal AI team wrote a blog post on, featuring models that did a good job with tool invocation and factual responses, but when I try them in the app, I get junk responses (see screenshots). I tried with a system prompt in a Pal, and without a Pal, and as you can see the models, specifically LFM2.5 1.2B Instruct, Qwen3.5 4B, and LFM2.5-2.6B but with and without Thinking on, each model's reasoning is broken. If Thinking is off, the model just outputs the garbage response as a chat response. What could I be missing? Again the Gemma 4 models work but burn through battery so I'm wondering what else I can do.
All reactions