


A curated collection of SuperMimic implementations, extensions, demos, and resources.
English · 简体中文
Original paper · Official website · Interactive demo · Community projects

World-model predictions
 Simulation |
 Real G1 |
Original footage: SuperMimic authors · Click a preview for the full video · Media credits
Start with the original work below, then choose an implementation by framework and task. This is a community-maintained resource list; the linked implementations are credited to their own authors.
- Original SuperMimic
- Community projects
- Related methods and baselines
- Data and learning resources
- Contributing
- Citation
- Acknowledgements and license
- Star History
SuperMimic: Scaling Humanoid Whole-Body Control with One Differentiable World Model
Qiayuan Liao, Yiyang Shao, Junfeng Long, Kevin Zakka, Roberto Horowitz, Pieter Abbeel, and Koushil Sreenath.
UC Berkeley · CoRL 2026 Oral
Paper · PDF · Project · Video · Browser demo
SuperMimic learns shared humanoid dynamics from simulator transitions and improves a motion-tracking policy through short imagined rollouts. The world model and policy are updated in the same training loop; policy gradients pass through the learned model. Method overview.

Original paper, Figure 2 · Framework, p. 4 · Algorithm A.1, p. 15
The world model is fit on 8-step replay windows; the policy and critic learn from 32-step imagined rollouts. During the policy update, model weights stay fixed while gradients pass through the model to the policy. Blue dashed arrows show gradients; ❄️ marks frozen weights and 🔥 marks weights being trained in that phase.
The authors report surpassing SONIC's released-checkpoint return after 3 hours on one H100, with 25 / 129,514 failed motions, and 0 / 129,514 after 9.8 hours on two H100s. These are training-motion coverage results, with different training hardware and data from SONIC. See the official results and compute accounting.
Official code status — checked 2026-10-28: the official website links the paper, video, and browser demo, but does not link a training-code repository. The projects below are community implementations and extensions.
39 projects · choose by strengths. ⭐ highlights documented results, reusable tools or clear learning examples. Categories can have several complementary picks, placed first below. Results and demos are upstream reports, not independently rerun here; each entry links to its reviewed revision.
| Explore | Recommended projects and strengths |
|---|---|
| 🚀 Real robots (2) | SuperMimic-Repro-Sim2Real — G1 hardware demos and deployment notes |
| 🔬 Reproductions (5) | supermimic_vibed — LAFAN1 training baseline SuperMimic-Reproduced — BONES-SEED experiment logs and weights SuperMimic Mjlab — step-by-step ablations and released checkpoints |
| 🧩 Method variants (6) | InstantTrack — 15-minute LAFAN1 target on one RTX 5090, three seeds MorphMimic — world-model / policy sharing across G1, X2 Ultra and T2 |
| 👁️ Perception & terrain (4) | InstinctMJ — depth-aware world model and terrain tracking Go2-SuperMimic — quadruped chase / dodge with released actors |
| 🦾 Manipulation & hands (4) | supermimic_manipulation — three ARX5 arm tasks, weights and reset banks Dex SuperMimic — Wuji hands: cube reorientation, pen spinning and weights In-Hand Rotation mjlab — LEAP hand: world-model / PPO simulation comparisons |
| 💪 Muscles & interaction (3) | muscle-supermimic — two muscle-driven bodies, held-out KIT evaluation |
| 🛠️ Training stacks (6) | UniSuperMimic — UniLab integration and both motion-data pipelines ScaleBFM_Plus — humanoid transformer integration and held-out evaluation |
| 🤖 Robot ports (6) | SuperMimic Retargeted — G1 / A3 / X2 Ultra retargeting and coordinate checks |
| 💡 Learning examples (3) | FlatWorld — see the learning loop in a 2D multi-skill demo |
Real-robot runtimes and sim-to-real transfer paths.
Repository · Quickstart · v1.1 field notes · G1 deployment
- By NJU R&L Group Embodied Lab. Extends the CuboiLeo mjlab baseline with custom dance/video-motion tools, clip-specific fine-tuning, ONNX export and G1 deployment through native MuJoCo and the Unitree SDK.
- Upstream report: v1.0 publishes a roughly 46-second real-G1 dance assembled from four motion segments. In v1.1, the clip-specific
e24_0355000policy completed a roughly 22-second dance twice on the real G1, including two rapid turns and a one-foot landing jump; nine earlier models had failed this clip. Both v1.1 runs used a slack safety tether, and repeating one model is not an ablation. - Useful context: The v1.1 checkpoint is specialized to that single dance, not general motion tracking. Paper-style observations and anchor-augmented training remain separate configurations. Source snapshot.
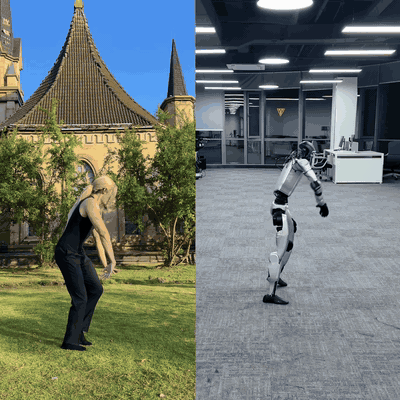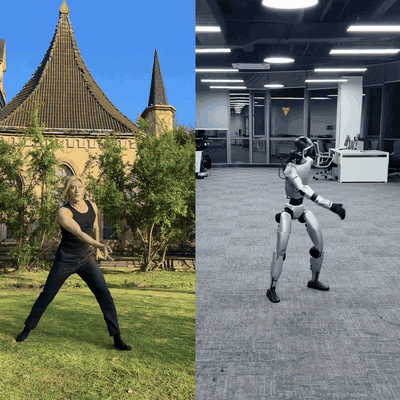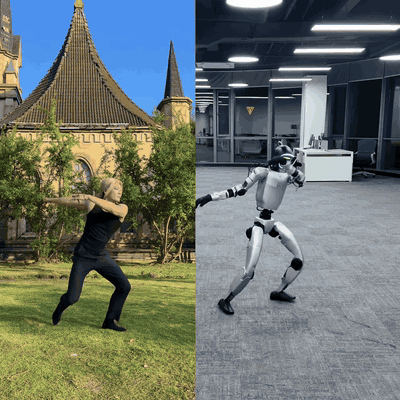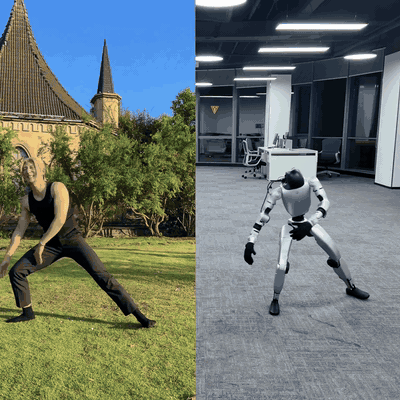
Real G1 · v1.1 clip-specific dance; human reference on the left, robot on the right
Repository · MuJoCo guide · Real-G1 guide
- By KyrieYoung926. A deployment runtime for a SuperMimic-Reproduced policy on the 29-DoF G1, using ONNX Runtime, MuJoCo and Unitree SDK2.
- What it provides: Provides both simulation and real-G1 demos, with separate guides for fetching deployment assets and running the policy on each target.
- Useful context: This repository covers deployment, not a new training benchmark. Motion data, model weights and robot assets retain their own terms beyond the code license. Source snapshot.
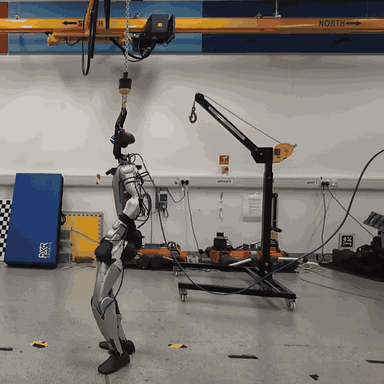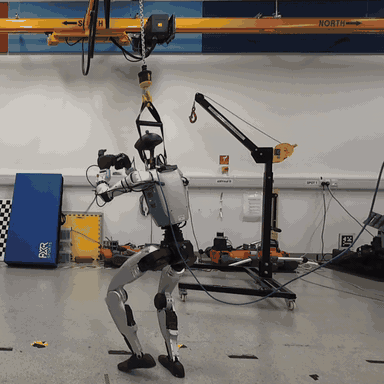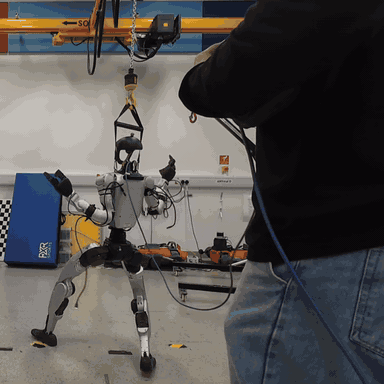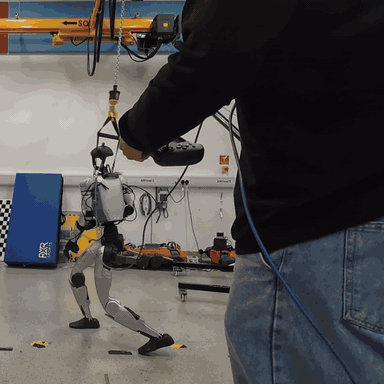
Real G1 · upstream deployment demo
Reimplementations of the original method, with training, evaluation and reproduction notes.
Repository · Setup and usage · Results
- By Chong Zhang. An independent G1 implementation on Isaac Lab 3, with a kit-less setup, training, full-clip evaluation and rendering tools.
- Upstream report: On 40 LAFAN1 clips, normalized return 0.829 and 0 / 40 failures after 1.47 hours on one RTX PRO 6000 Blackwell.
- Useful context: The author describes it as a rapid, unreviewed reproduction. Documented deviations include disabled self-collisions, bf16 MLP computation and an extra reference-root orientation input. Source snapshot.
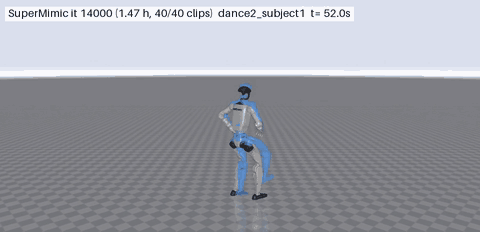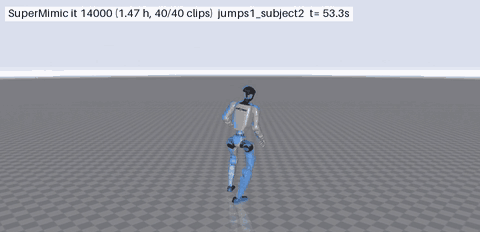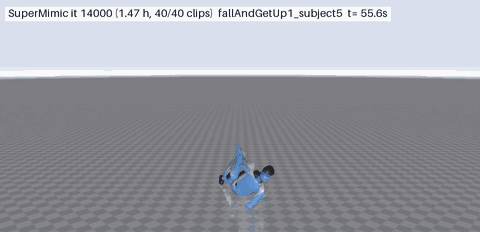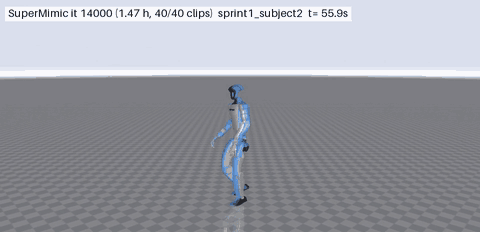
Simulation · LAFAN1 highlights
Repository · Setup · Experiment log · Checkpoint
- By CuboiLeo. A from-scratch mjlab implementation for G1, with Chinese reproduction notes, LAFAN1/BONES-SEED processing, multi-GPU training, an interactive replay viewer and a released full-data checkpoint.
- Upstream report: With paper observations, four RTX 5090s train on 129,943 BONES-SEED clips for 7.1 hours (about 28 GPU·h). The experiment log reports 0.930 return, 495 / 129,943 failures on that library; after excluding 452 clips by name, it reports 0.932 return, 145 / 129,491 failures (0.11%) on the filtered evaluation set. On LAFAN1, anchor-relative observations reach 0.904, 3 / 40 failures, while paper observations reach 0.56–0.59, 3–9 / 40 across three runs.
- Useful context: BONES-SEED clips are short (median 5.8 seconds), whereas paper-observation policies drift on 100–300-second LAFAN1 clips. The two observation settings are not directly comparable. The upstream README pairs 0.930 with the filtered failure count; the set-specific figures above follow the experiment log. Source snapshot.
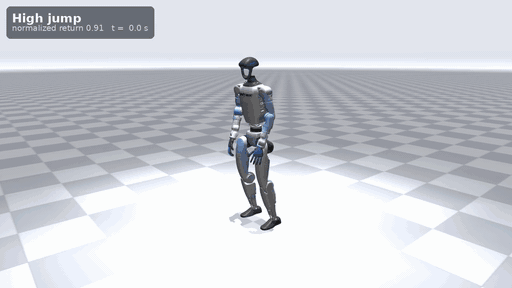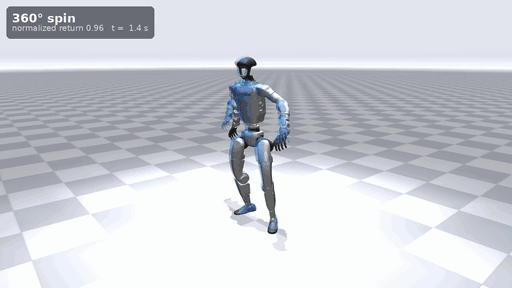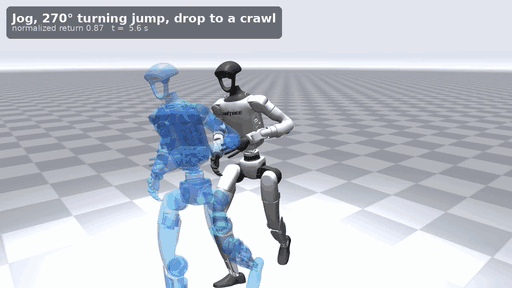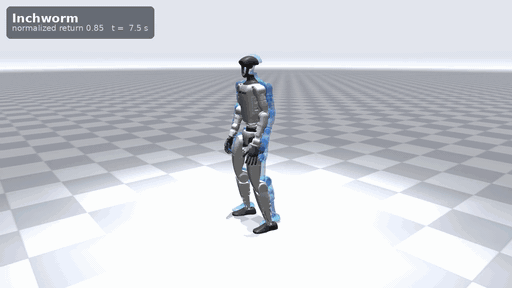
Simulation · one full-BONES-SEED policy across six challenging motion clips
Repository · Setup · Ablations and checkpoint
- By Breezewrf. An independent SuperMimic reproduction for Unitree G1 in mjlab, with a complete performance-improvement ablation study, multi-motion and velocity training, OOD playback, video-to-motion export, full-clip evaluation and released policy/world-model checkpoints.
- Upstream report: On all 40 LAFAN motions, the selected checkpoint achieves 40 / 40 successful motions, 100% mean completion and 0.8528 normalized return in fixed-start, full-clip deterministic evaluation. Training for 15,000 iterations takes approximately 4 hours on one RTX A6000 48 GB, with 4,096 environments and FP32 networks.
- Useful context: Documents the full progression from Actor/Critic input normalization through a torso-frame motion orientation anchor, world-model normalization and a corrected cosine learning-rate schedule: mean normalized return 0.6016 → 0.8130 → 0.8504 → 0.8526 at 15,000 iterations over all 40 motions. The final rerun mean is distinct from the selected checkpoint score above. Source snapshot.

Simulation · 12-second excerpt from the 60.8-second playback demo; click for the full upstream GIF
Repository · Setup · Results log
- By dhmbb2. An independent G1 reproduction in mjlab, covering PPO-Sim/PPO-WM comparisons, horizon and critic ablations, push recovery and velocity-control experiments.
- Upstream report: On one RTX A6000, LAFAN1 normalized return reaches 0.833 at 1.34 hours and 0.946 with 0 / 40 failures at 12 hours, using complete deterministic clip evaluation.
- Useful context: The experiment log distinguishes reproduced, partial and pending results. BONES-SEED remains data-gated, hardware transfer is out of scope, and the A6000 timings are not H100 timings. Source snapshot.

Report screenshot · reproduction and ablations on one RTX A6000
Repository · Reproduction analysis · Evaluation videos
- By rzc156. An independent mjlab reproduction derived from CuboiLeo, configured for one 16 GB RTX 5080 with 2,048 training environments and additional anchor-relative observations.
- Upstream report: The 40k checkpoint reaches 0.8515 mean / 0.8608 step-weighted return with 2 / 40 failures after 2.7 hours. The 48k checkpoint averages 0.8375, 4–6 / 40 failures, after 3.3 hours over three evaluations.
- Useful context: This is a single training seed, and the extra anchor observations make it non-equivalent to the paper-observation protocol. The author highlights 40k as the preferred checkpoint but notes that 40k/44k/48k differences still require multiple seeds. Source snapshot.
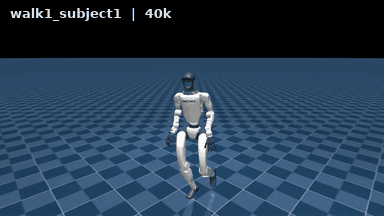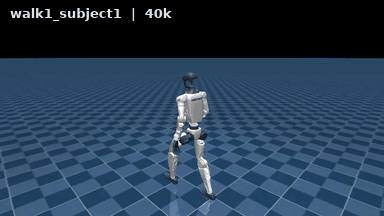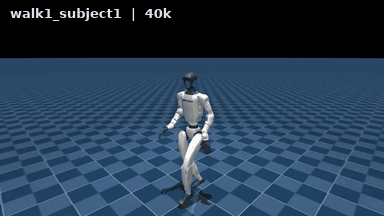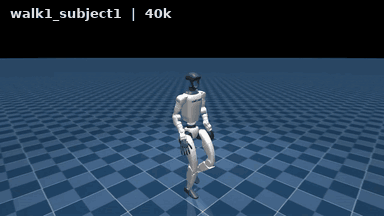
Simulation · 40k checkpoint on a 15-second LAFAN1 walk clip; click for all seven videos
Algorithm changes, multi-robot morphology adaptations and focused control studies.
Repository · Setup · Results and ablations · Training presets
- By Huy-Quang-Dao. Builds on the mjlab port of supermimic_vibed for G1, combining GPU training-loop optimizations, EMA policy weights, a smaller world model and failure-focused resets; the main preset also adds a contact reward during imagined rollouts.
- Upstream report: On one RTX 5090, all three seeds reach return ≥ 0.82 and 0 / 40 failed LAFAN1 clips in about 15 minutes, with mean return 0.831 at that point. The reported 2.2× speed-up is against the author's SuperMimic + EMA baseline on the same machine; the 6× figure uses their plain reimplementation.
- Useful context: Time marks the first of three consecutive qualifying checkpoints, excludes offline evaluation and is not an end-to-end setup time. Evaluation covers the training clips in simulation; no larger motion library or real-robot results are reported. Model size, update count and training reward differ from the baseline; this is not a cross-project speed ranking. Source snapshot.

Upstream simulation · same 15-minute training budget; SuperMimic + EMA (left), InstantTrack (right), fall-and-get-up motion
Repository · Setup · Method differences
- By Lizhi Yang et al. Extends SuperMimic in mjlab to share a world model, a policy, or both across G1, X2 Ultra and T2, conditioning the networks on robot morphology. The new
--goal-anchor robotmode expresses the motion goal relative to the robot's own anchor to correct drift. - What it provides: Supports full-motion tracking and sparse five-point goals for the pelvis, wrists and ankles; the project includes a browser demo and teleoperation/deployment instructions.
- Useful context: Robot-anchor mode requires the robot's world position and heading at deployment from motion capture or a state estimator. Robots are mapped to a common 29-joint layout, and the documentation also covers termination modeling, normalization, warm-up and actuator-delay randomization. Source snapshot.

Simulation · one shared policy for G1 / X2 Ultra / T2
Repository · Install · Results
- By Shimingyi. Builds on supermimic_vibe for G1 in mjlab, mixing residual upper-body actions with absolute leg actions, weighting world-model losses and balancing motion sampling.
- Upstream report: With the recommended preset on one RTX 4090, full-length LAFAN1 evaluation reports 0 / 40 failures and return 0.91 after 0.83 hours; training time excludes evaluation.
- Useful context: The recommended preset changes the method and data sampling. The 306-hard-motion-only run and full BONES-SEED training are separate experiments. Source snapshot.
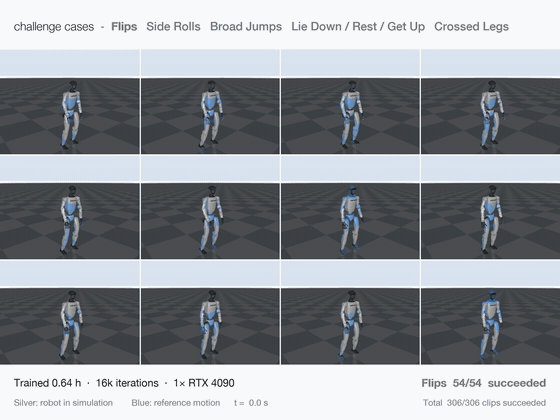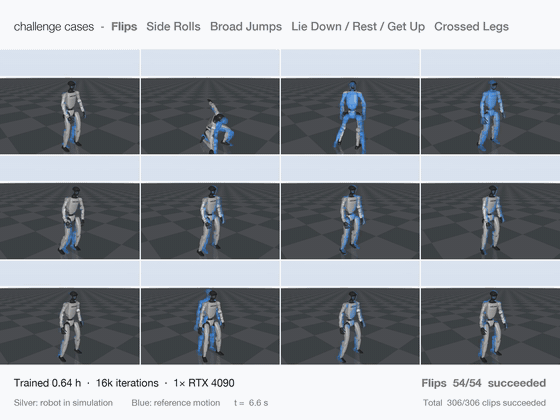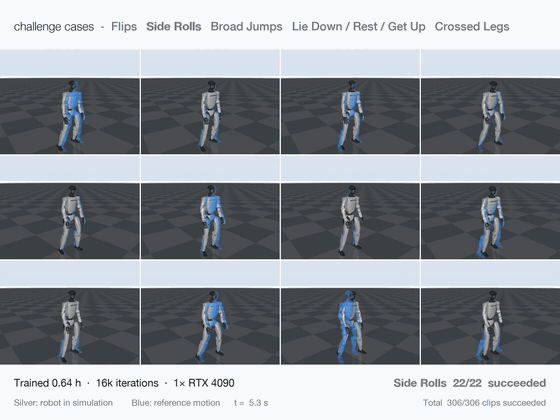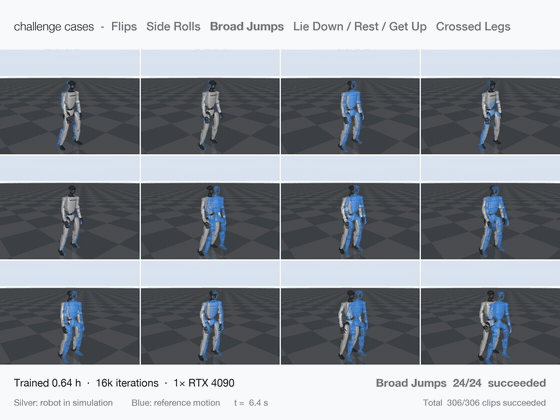
Simulation · challenging motion clips
Repository · Setup · Results
- By Alchedata. Ports the method to H1 with JAX and LocoMuJoCo, adding a full-state ODE world model and anti-saturation regularization alongside the MLP, residual-expert, action-sensitivity and trust-aware variants.
- Upstream report: With fixed 5,000-iteration checkpoints and 160 initial states, adding anti-saturation to the Euler ODE model reduces aggregate failures from 15 / 480 to 1 / 480 over three seeds. Seed 43 improves from 878.71 / 15 failures to 935.38 / 0 failures, while seed 42 becomes slightly worse, so this is not a uniform score increase.
- Useful context: The reward is LocoMuJoCo episode return, not the G1 normalized tracking score. Midpoint ODE acceleration runs are still in progress and are not included as completed results. Source snapshot.

Upstream training curves · ODE and anti-saturation variants at fixed 5k evaluation checkpoints
Repository · Installation · Implementation comparison
- By btx0424. Studies goal conditioning for G1 in mjlab: concatenating the goal with proprioception versus using FiLM to modulate the policy layers. The latest revision adds an HL-Gauss critic, gradient checks and selectable heading- or pelvis-frame world-model coordinates.
- Useful context: Provides configurable observations, anchor choices and Viser playback. Its implementation table explains differences from the paper and supermimic_vibed, including self-collisions and observation inputs. Source snapshot.

Historical implementation table excerpt · 2026-10-26 snapshot; current comparison linked above
Repository · Experiment details · Reproduction notes
- By JackMin7. Adapts SuperMimic's differentiable world-model loop to a static G1 standing task and compares it with an RSL-RL PPO baseline derived from BeyondMimic.
- Upstream report: With the same 29-DoF G1, task, reward and about one hour of training on 256 environments, MBRL succeeds 32 / 32 times in both the 20-second and 60-second tests; PPO succeeds 12 / 32 and 16 / 32. Mean 20-second joint RMSE is 0.144 versus 0.415 rad.
- Useful context: Single training seed, shared GPU, no disturbances, and the 32 rollouts are copies rather than independent seeds. The project does not claim training-speed or real-robot gains. Source snapshot.
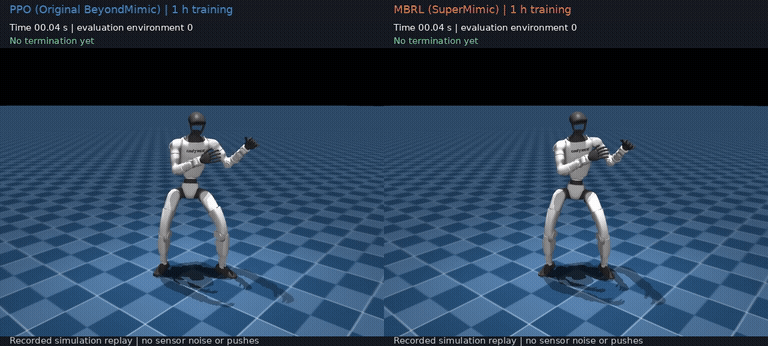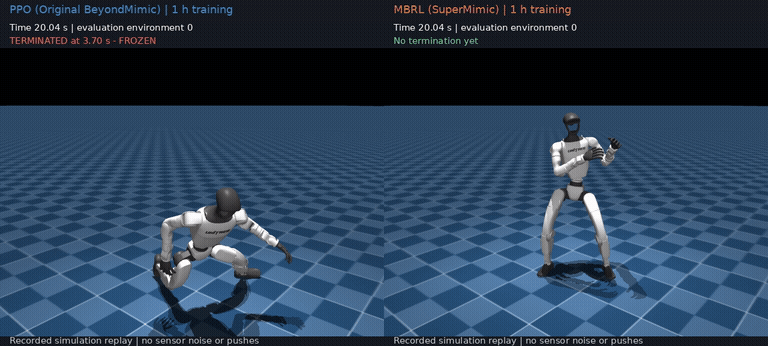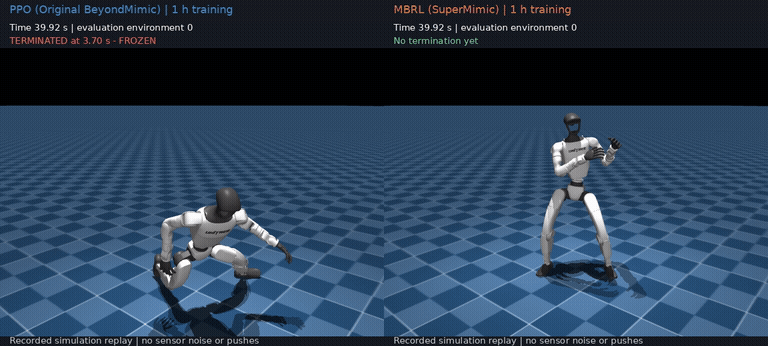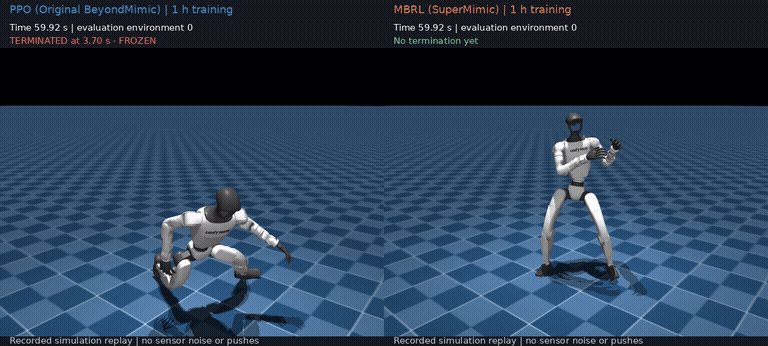
Simulation · 60-second PPO / MBRL comparison at normal speed; PPO freezes after termination
Vision, height-scan, terrain and quadruped task adaptations.
Repository · Method and results · Releases
- By Project Instinct. Extends the method to perceptive G1 tracking and goal-reaching parkour in mjlab / instinct_rl. The world model predicts robot state and depth-encoder latents; components are adapted from supermimic_vibed.
- Upstream report: 97% full-motion success across 10 motions on 5 terrains after 8,000 iterations / 3.2 hours on one RTX 3090; one seed, 12–13 episodes per motion, camera noise enabled.
- Useful context: Use the supermimic branch. This is terrain tracking, distinct from flat-ground LAFAN1; external checkpoints require joint-order adaptation. Licensed CC BY-NC 4.0. Source snapshot.

Method diagram · robot-state and visual-latent prediction
Repository · Quickstart · Pretrained policies
- By Zhengtianjin. Adapts SuperMimic to Unitree Go2 chase-and-dodge tasks in mjlab, covering flat ground, obstacles and terrain with LiDAR or height-scan inputs.
- What it provides: Publishes separate flat, obstacle and terrain actors, plus evaluation and recording tools. Actor-only downloads support playback; resuming training also needs the world model and critic.
- Useful context: Simulation only, with ground-truth target perception. The released terrain policy still has falls and bar collisions under the hardest settings. Source snapshot.
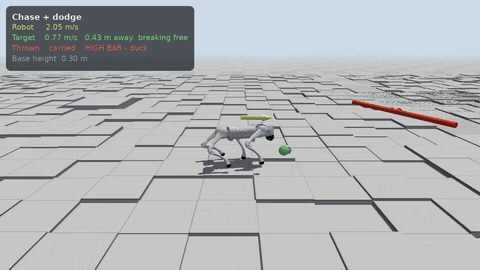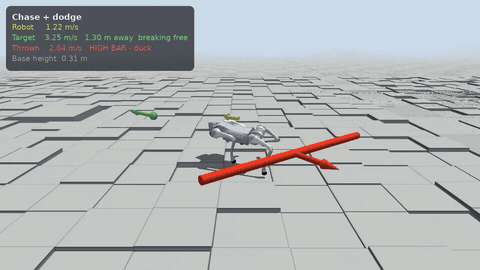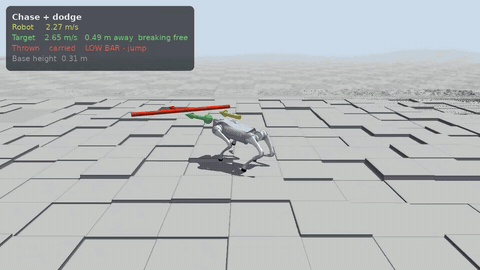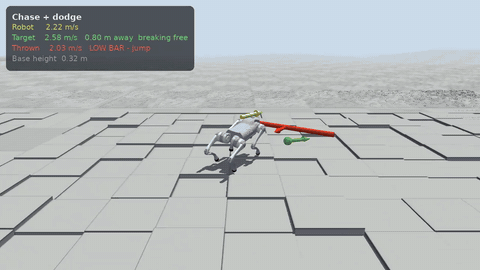
Simulation · Go2 terrain chase and dodge
Repository · Data setup · Checkpoint
- By yhx1203. A five-skill G1 parkour adaptation built on mjlab and PHP Parkour motion-matching data, using a shared differentiable world model and BPTT policy learning.
- Upstream report: Trains a policy to clear a 130 cm obstacle in just over 4 hours on one GPU, ships the resulting checkpoint and provides browser-based playback.
- Useful context: The PHP motion bundles are not distributed with the repository and must be supplied separately. This is one upstream demonstration and training-time claim, not an independent benchmark against PPO or SuperMimic. Source snapshot.

Simulation · five-skill PHP parkour policy; 11.5-second upstream demo
Repository · Method · Progress
- By mode1223345. Builds on supermimic_vibed in Isaac Lab 3, pretraining a heightmap autoencoder and freezing one shared encoder for the actor, critic and world model.
- What it provides: Documents four flat-ground/step-terrain control experiments and separate reconstruction checks; the published control comparisons remain in progress.
- Useful context: Maps come from simulator ground truth. Real-depth reconstruction and hardware perception are not integrated, and inherited baseline scores do not establish gains from the encoder. Source snapshot.

Training curves · 2026-10-24 snapshot; control comparisons in progress
Arm, hand and object-interaction tasks, with dexterous manipulation grouped here. The exploratory Ref2Dex contact-control project is listed under Inspired experiments.
Repository · Setup · Results
- By Zhiqiang Zhou (emoPointer). Adapts SuperMimic to state-based manipulation with a simulated ARX5 arm in mjlab / MuJoCo Warp across the Lemon, BoxInBin and MugHang tasks.
- Upstream report: Held-out reset banks with 256 complete episodes per task at 4,000 iterations reach 100.0% Lemon, 94.9% BoxInBin and 96.9% MugHang success; the runs take 1.8 / 1.9 / 2.8 hours on one A100 80 GB while sharing the GPU.
- Useful context: OmniReset-style reset categories shorten the effective horizon, and contact-based success tests use differentiable geometric surrogates during imagination. The policy observes low-dimensional state only; released checkpoints and reset banks are on Hugging Face. Source snapshot.
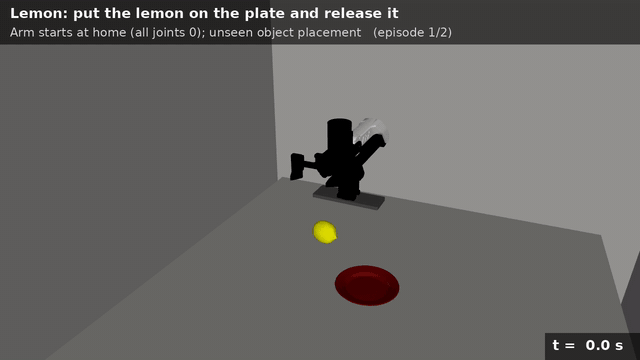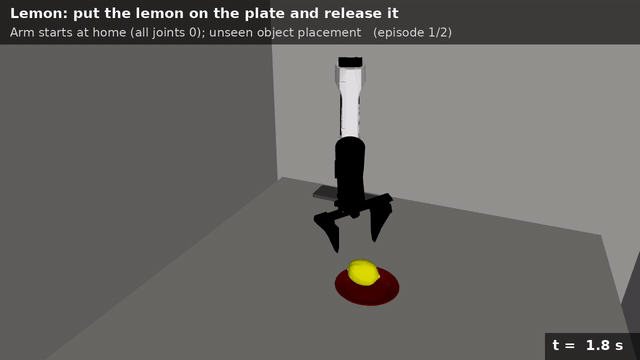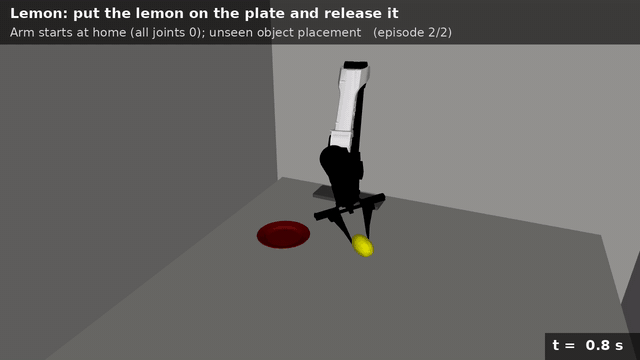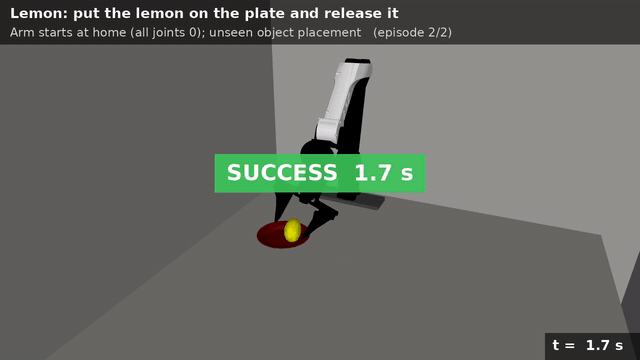
Simulation · ARX5 Lemon task · two held-out resets
Repository · Installation · Demos · Checkpoints
- By CumulusAlpha. Adapts world-model-based policy training to Wuji Hand 1/Hand 2 cube reorientation and Wuji Hand 2 pen spinning, using mjlab / MuJoCo Warp and the InstinctMJ task framework.
- What it provides: Three task configurations, bundled hand and cube assets, Viser playback, and three 8,000-iteration checkpoints in the
pretrained-wuji-v2release. - Useful context: This is a dexterous-manipulation adaptation with a different task and reward from humanoid motion tracking. Source snapshot.
 Wuji Hand 1 · cube reorientation |
 Wuji Hand 2 · pen spinning |
Repository · Install · Results · Checkpoints
- By Msornerrrr. Applies SuperMimic-style world-model policy learning (an MLP world model refit online, backpropagation through imagined rollouts, a TD(λ) critic and weight averaging) to the LEAP Hand in mjlab / MuJoCo Warp, next to PPO baselines on the same environments: palm-up cube yaw, SO(3) cube reorientation (PPO only) and palm-down fingertip rotation of 22 objects, on a servo model identified on the real hand. Checkpoints for both methods are released.
- Upstream report: On cube yaw, the world-model policy reaches PPO's level (≈0.26 reward/s) after 25 minutes and 18M env steps, where PPO needs 6.5 hours and 262M, and ends at 0.292 vs 0.261. On palm-down fingertip rotation (64 rollouts per object, 60 s, randomized pad friction 0.25–1.2), a joints-only world-model policy reaches 933° rewarded yaw with 4.0% drops, against 675° / 10.4% for the deployed PPO student distilled from a teacher, and 944° / 2.1% for the privileged PPO teacher.
- Useful context: World-model results are in simulation; the real-robot videos (yaw and SO(3)) show PPO policies. Fingertip numbers use the repository's own evaluation (rotation reward capped at 0.3 rad/s; a drop is 30 mm of drift). Single runs per configuration; wall-clock times are on one RTX 4090. Source snapshot.
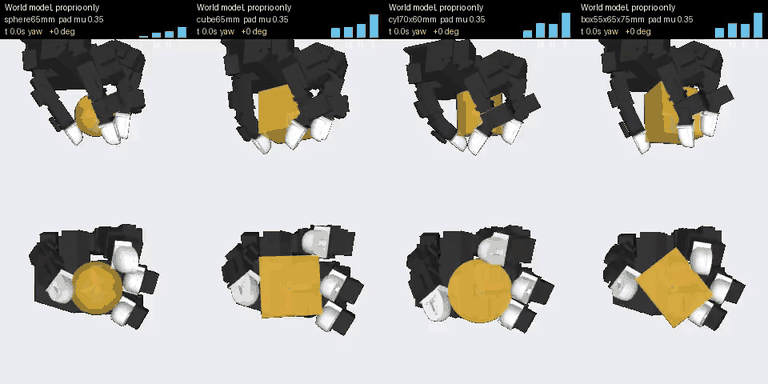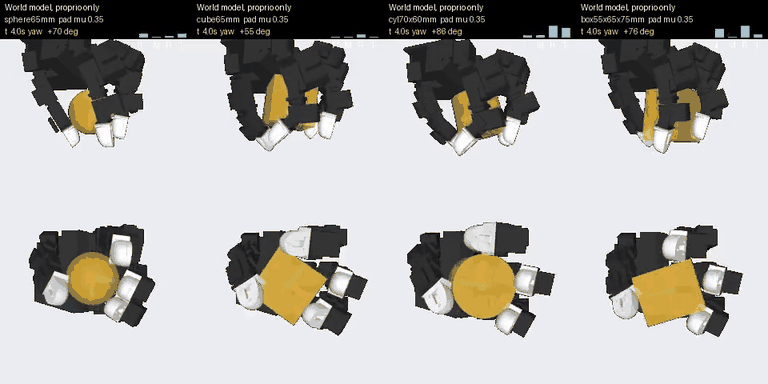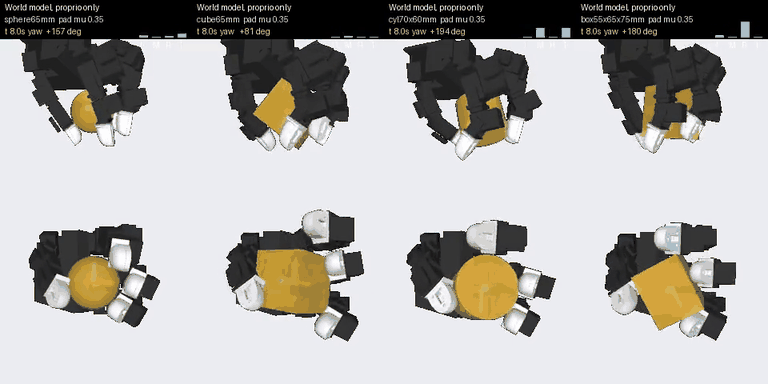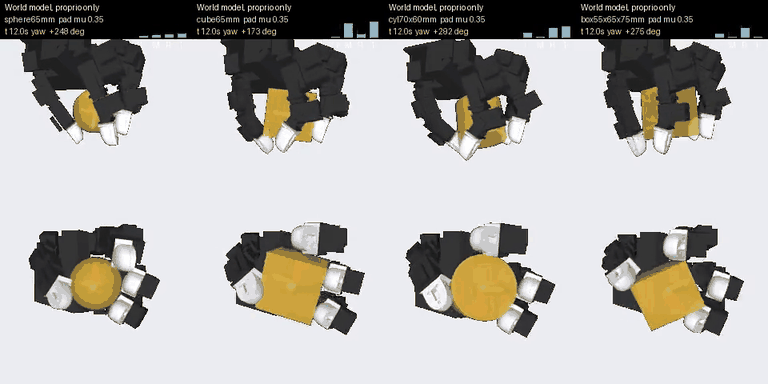
Simulation · palm-down fingertip rotation, joints-only world-model policy
Repository · Quickstart · Results and protocol
- By shuayyy. Compares SuperMimic and PPO-Sim on shared G1 walking, squatting and box-lifting tasks in mjlab; the repository also contains a separate AMP-PPO stack.
- Upstream report: Box-lift success reaches 100% at 31 million environment steps, reported for two SuperMimic seeds with 64 randomized evaluation episodes; success means finishing within 10 cm of the reference box height.
- Useful context: Those SuperMimic scores used clean observations. The newer evaluation adds observation noise, and the published checkpoints have not been re-evaluated under that setting. Source snapshot.
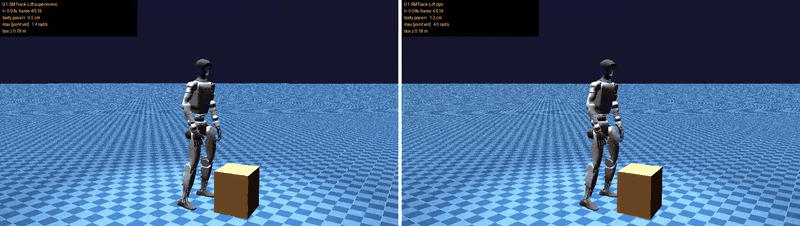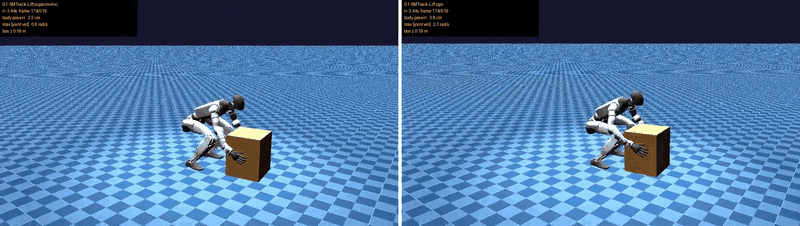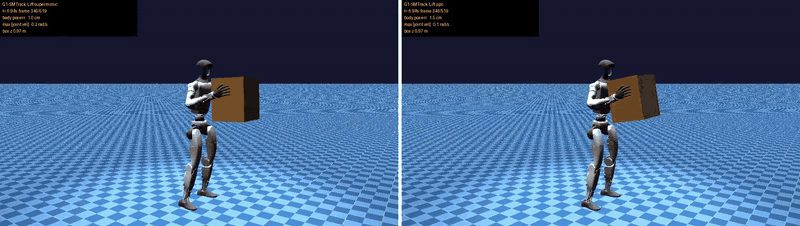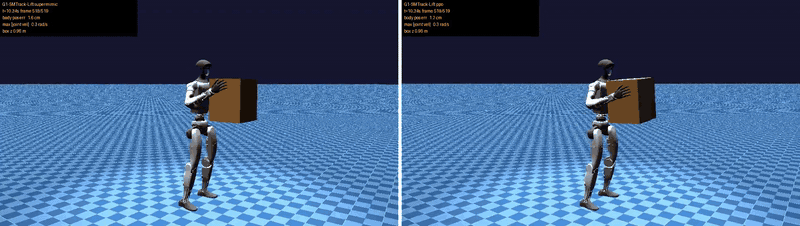
Box lift · SuperMimic 12k / PPO-Sim 6k iterations
Muscle-actuated bodies, physical interaction and contact-focused diagnostics.
Repository · Setup · Status
- By Kaibo He (kaibohex). Extends SuperMimic to muscle-driven whole-body tracking on MS-Human-700 (700 muscles) and MyoFullBody (354 muscles) in mjlab / MuJoCo Warp.
- Upstream report: On MuscleMimic's 108 held-out KIT clips with 4,096 environments on one RTX 5090, MS-Human-700 reaches 0.91 normalized return after 10.1 hours (iteration 16k, 104 / 108 tracked); MyoFullBody reaches 0.83 after 6.0 hours (iteration 10k, 101 / 108 tracked).
- Useful context: Active development. The policy controls muscle excitation at 100 Hz, and the project provides a differentiable torch muscle model plus retargeting tools. The retargeted KIT data is gated and subject to AMASS terms; MS-Human-700 is provided as a Git submodule. Source snapshot.
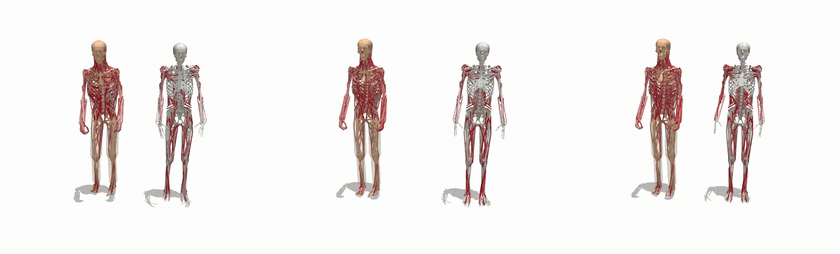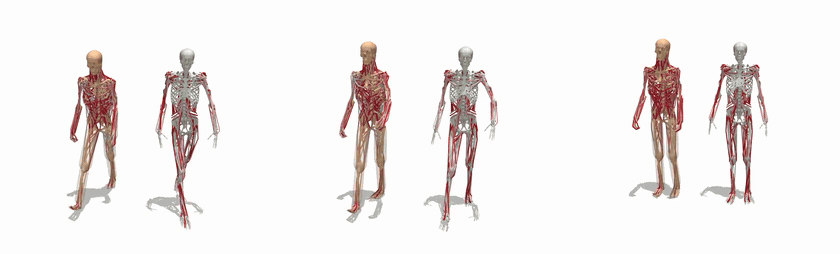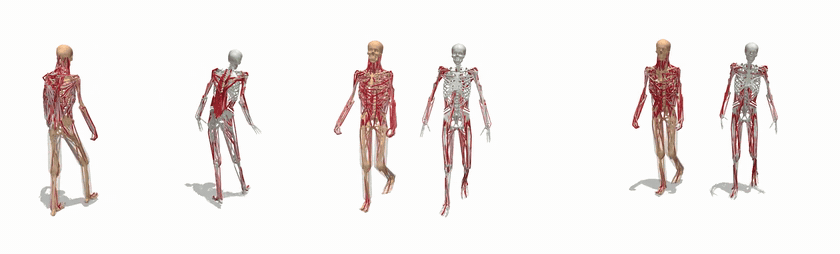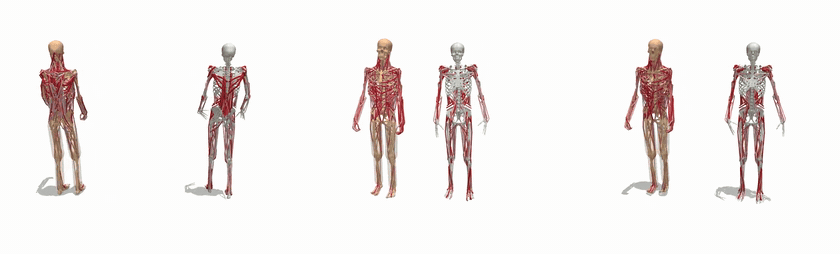
Simulation · MS-Human-700 and MyoFullBody · iteration 10000
Repository · Current status · Skateboarding report
- By shangchaohu718. Builds on UniSuperMimic for G1 interaction experiments, retaining a frozen tracker while developing separate interaction policies in UniLab / MuJoCo.
- Upstream report: A separate skateboarding policy completes 30-second simulated runs from one standard and eight held-out perturbed initial states, traveling 39.87–42.13 m.
- Useful context: Tracking and skateboarding are selected as separate branches. A shared world-model-driven interaction actor is not established; box handling and stairs remain unsuccessful in the reported prototype. Source snapshot.

Report screenshot · tracking checkpoints 500–6000; separate from skateboarding
Repository · Results · Quickstart
- By liudi159. A focused G1 backflip study on Isaac Lab 3 and one RTX 5090, tracking leg symmetry, contact forces, penetration and landing stability.
- Upstream report: The final V14 checkpoint completes the rotation and landing hold, but the original strict evaluation records one frame of non-foot penetration and fails acceptance.
- Useful context: An independent rerun changes the borderline contact outcome. Both records are retained, so the clip should not be read as robust success or reproduction of all paper experiments. Source snapshot.

Simulation · final V14 policy; strict evaluation failed
Integrations and reusable training or evaluation stacks.
Repository · Installation · Results
- By Motphys. Ports supermimic_vibed to a UniLab Manager-Based G1 task, with LAFAN1 and BONES-SEED data pipelines, selectable simulation backends, deterministic full-clip evaluation and video export.
- Upstream report: At iteration 12,000, the LAFAN1 checkpoint reports 0.827227 with 0 / 40 failures. A same-machine LAFAN1 rerun used for the new BONES-SEED comparison reaches 0.8336, 0 / 40; on 129,487 BONES-SEED clips, one RTX 5090 trains for 2.55 hours and scores 0.9262 on a random 10,000-clip subset, with 30 / 10,000 failures (0.3%).
- Useful context: The BONES-SEED result is a sampled evaluation, not the full library, and all published tracking numbers use mjwarp. MuJoCo and Motrix entry points do not establish equivalent training results. Source snapshot.
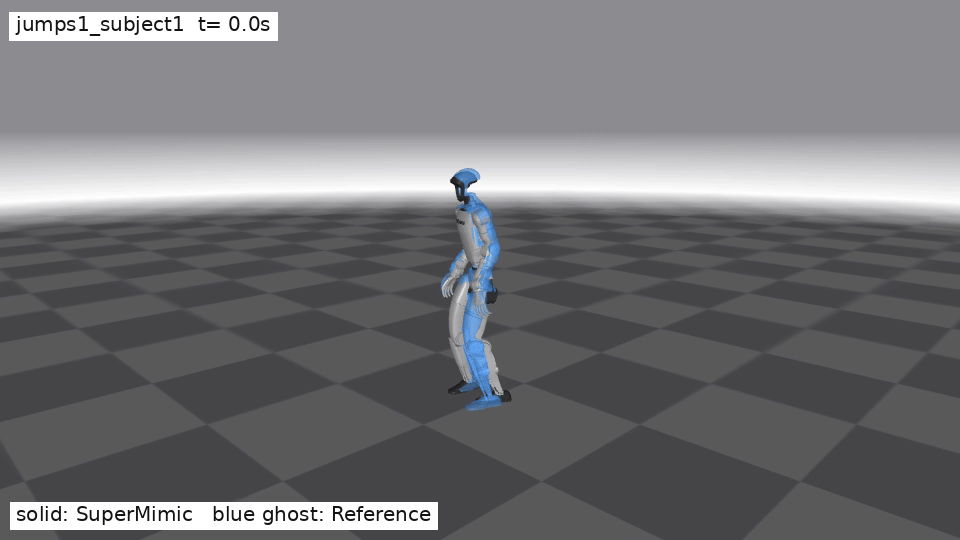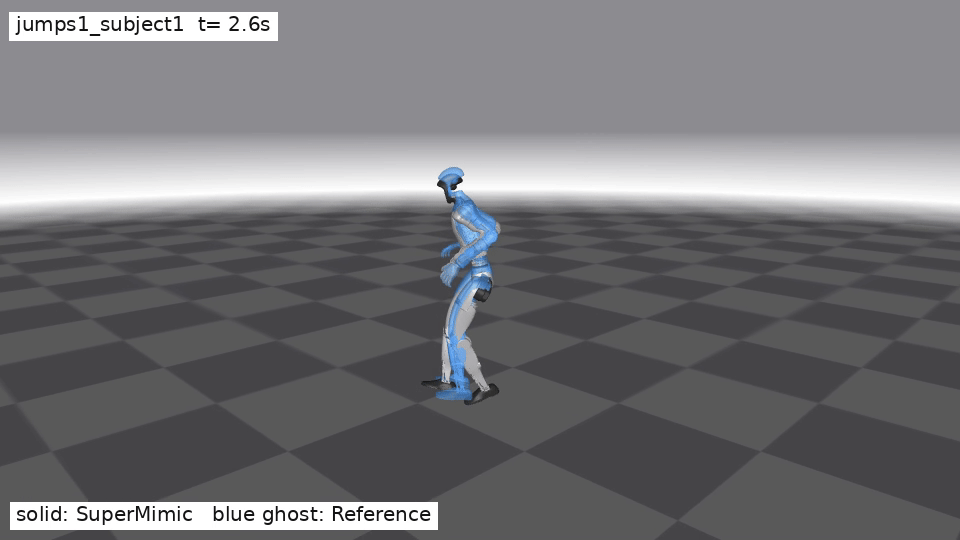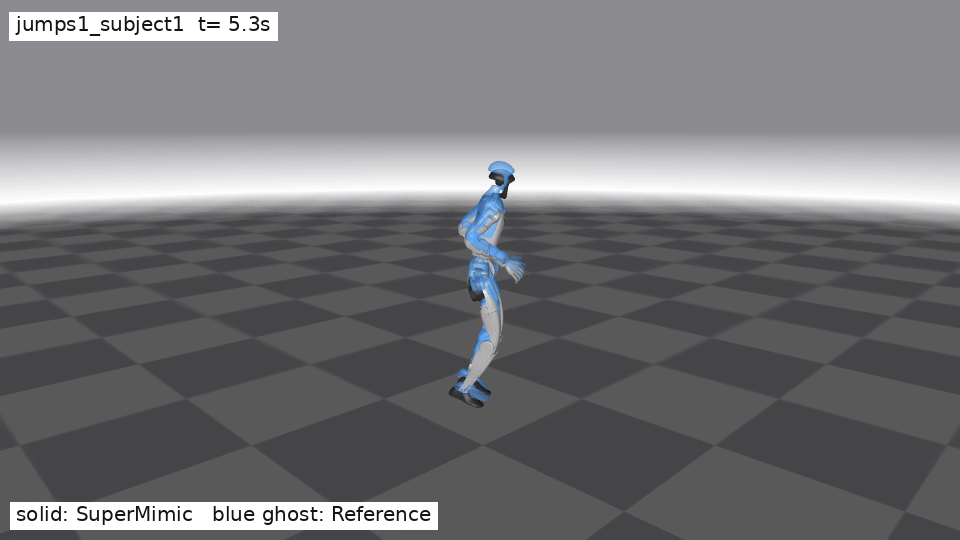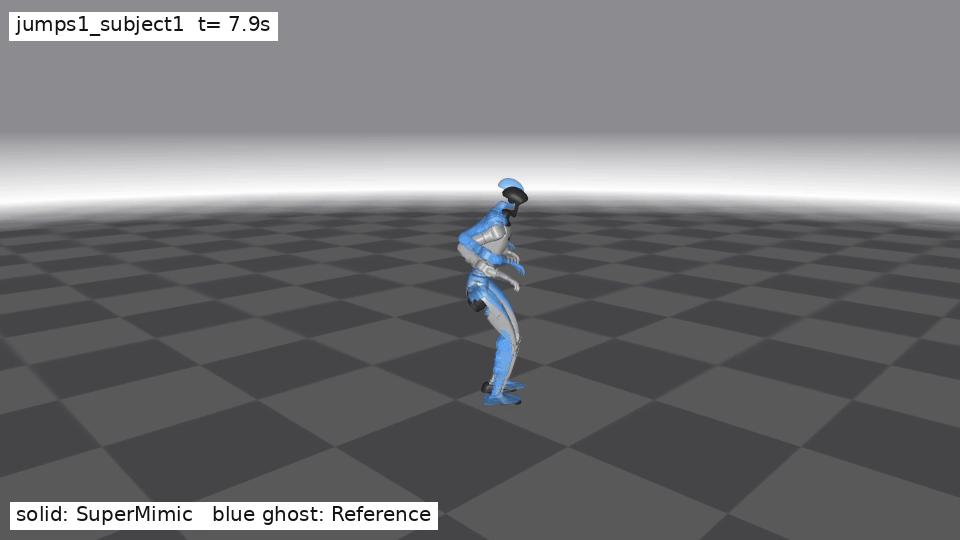
Simulation · G1 jump tracking
Repository · Training and results · Released checkpoint
- By Hxxxz0, building on ScaleBFM. Integrates SuperMimic-style world-model learning and 32-step BPTT into ScaleTrack for G1 in IsaacLab / RSL-RL, retaining the humanoid transformer and tracking modes, with PPO-compatible policy export and playback.
- Upstream report: Training on 309 h / 138k clips from BONES-SEED, any4hdmi and LAFAN1 for 8.3 h on 16 RTX 5090s yields 99.5% tracking success on 2,575 held-out motions. On 386 dynamic test motions, both this policy and the official ScaleBFM-M checkpoint succeed on 376 / 386, with mean global body-position errors of 6.35 cm and 6.43 cm, respectively.
- Useful context: This is a community extension of ScaleBFM. The reported 26× per-step speedup compares 0.65 s on 16 RTX 5090s with PPO's 17.0 s on 8 RTX 5090s; it is not a matched-compute or time-to-quality comparison. Source snapshot.

Simulation · official ScaleBFM-M (left) and SuperMimic (right), unseen LAFAN dance · Source: Hxxxz0 / ScaleBFM_Plus
Repository · Training guide · Results
- By Horizon Robotics. Integrates SuperMimic into HoloMotion’s G1 assets, HDF5 motion data and Hydra workflow, sharing tasks and evaluation with PPO on MuJoCo Warp and Isaac PhysX.
- Upstream report: The selected MuJoCo Warp recipe completes 32 / 40 LAFAN1 training clips after 30 minutes on one RTX 5090.
- Useful context: The validated route uses a compact policy. The preview shows short excerpts from a separate run; it does not replace complete-clip evaluation or establish the planned large-policy integration. Source snapshot.
Simulation · PPO / SuperMimic, two backends
Repository · Install · Results and limits
- By Renforce Dynamics. Provides a shared Isaac Lab / PhysX workflow for retargeting, training, full-clip evaluation and export across G1, Go2, A3, T1, Bumi and Pi+, plus Go2 task policies.
- Upstream report: Re-evaluation of the 32,000-iteration G1 parent checkpoint reports normalized return 0.8694663 and 0 / 40 LAFAN1 failures.
- Useful context: Results use PhysX, while supermimic_vibed uses MuJoCo Warp. Robot-specific motion libraries and training histories differ; held-out motion generalization remains unmeasured. Source snapshot.
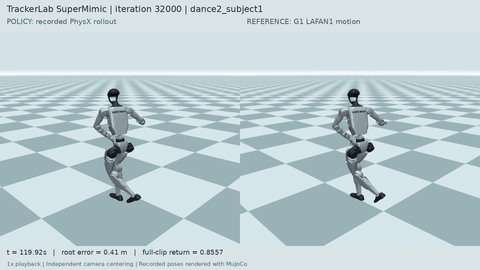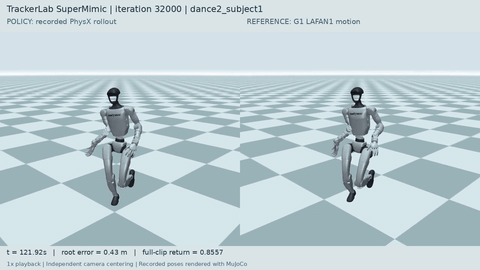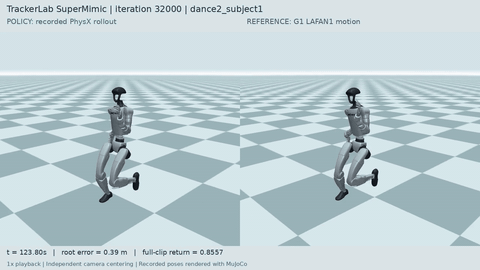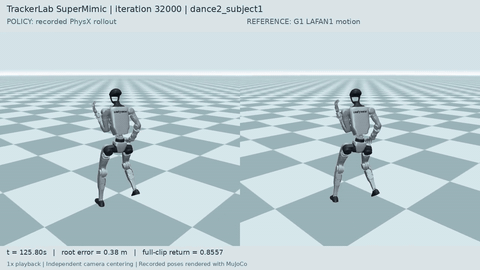
Simulation · G1 policy / reference dance
Repository · Setup · Custom-task guide
- By chu-fa. Packages a reusable SuperMimic learner and runner for Isaac Lab custom tasks, with a separately installable AGIBOT A3 example.
- What it provides: Provides task contracts, setup instructions and backend validation records. A custom task must supply differentiable state, observation, reward and termination functions.
- Useful context: Targets the Isaac Lab 3 development API. The A3 preview uses separately initialized segments; convergence, backend equivalence and hardware deployment are not established. Source snapshot.
A3 reference / policy · separately initialized segments
Repository · Preview release · Evaluation and limits
- By OMEGA-i. An independent MuJoCo Warp implementation for G1, H2 and A3, with motion retargeting, policy/world-model ONNX export and WebGPU browser previews.
- Upstream report: Publishes separate train40 and held-out val37 evaluations for G1/H2. The G1 55.5k preview reports 0.7990, 3 / 40 failures on train40 and 0.3103, 31 / 37 failures on val37; A3 100k full-clip evaluation is pending.
- Useful context: An experimental preview with limited held-out tracking and documented later-checkpoint regressions. Supply licensed motion data; no top-level code license was found at the reviewed revision. Source snapshot.
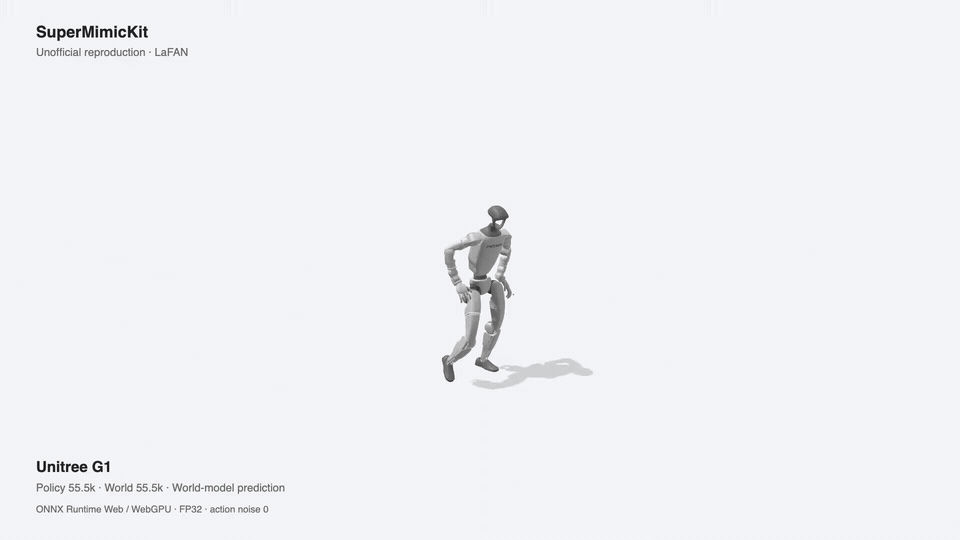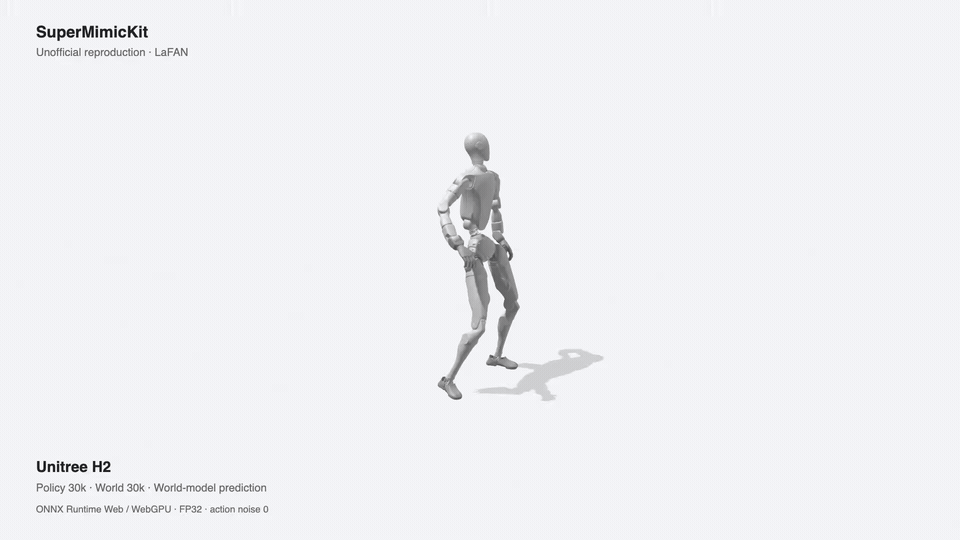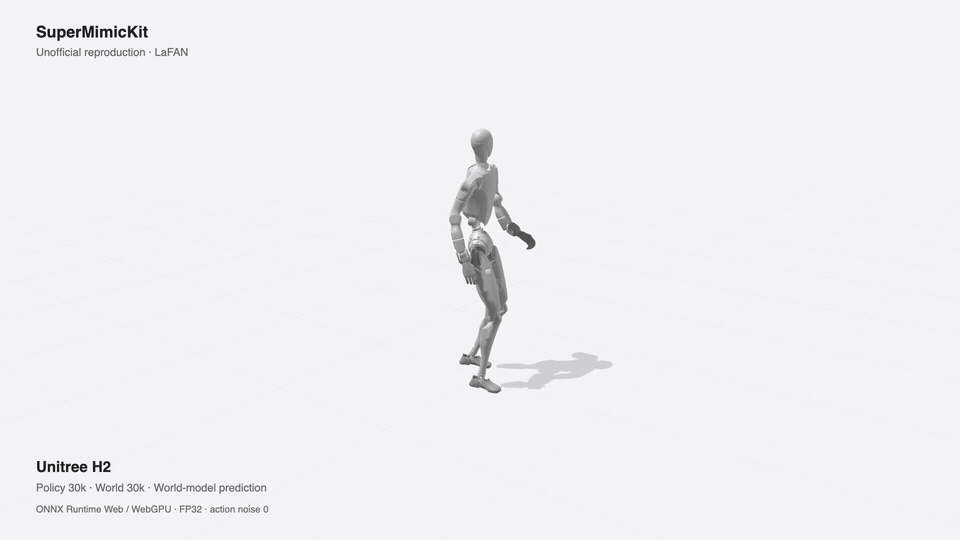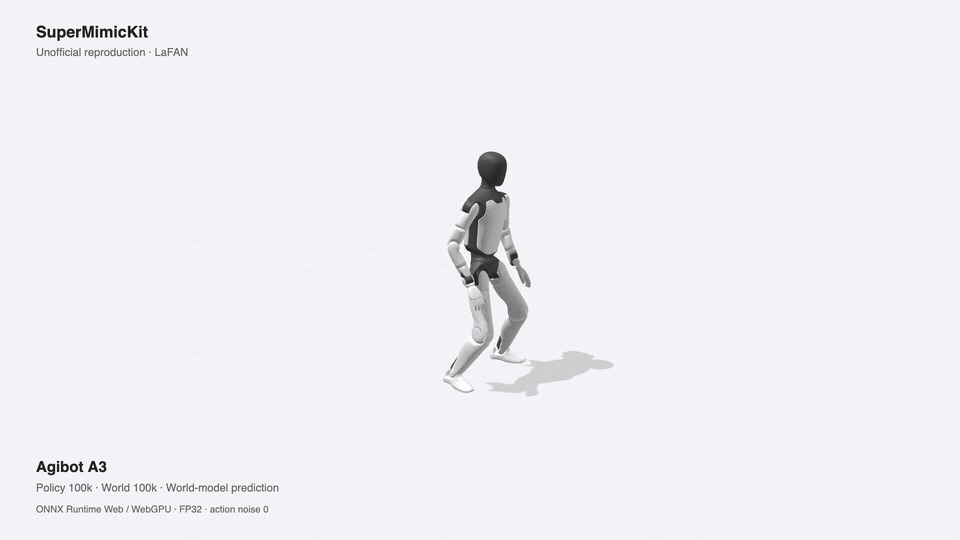
Browser preview · G1 / H2 / A3
Robot-, simulator- and hardware-specific ports, together with motion-retargeting tools.
Repository · Quickstart · Data guide
- By tianshuwu. Extends the CuboiLeo mjlab baseline to G1, A3 and X2 Ultra, adding robot-specific kinematics, SOMA retargeting, coordinate corrections and foot-contact checks.
- What it provides: Publishes LAFAN1/BONES-SEED preparation workflows and historical evaluation records. Training weights are not distributed, and motion data must be prepared separately.
- Useful context: The reported policies use extra anchor-relative observations computed from simulator truth. These require corresponding state estimation on hardware; real-robot transfer is not validated. Source snapshot.
Simulation · G1 / X2 Ultra / A3
Repository · Setup · Results
- By wenconggan. Adapts the Isaac Lab 3 implementation to the 21-DoF DroidUp E1, with standalone native-MuJoCo sim-to-sim playback and evaluation.
- Upstream report: The 164k checkpoint completes 40 / 40 training motions, return 0.8559, in Isaac Lab. A separate 168k checkpoint completes 10 / 10 sampled eight-second segments in native MuJoCo.
- Useful context: Complete-clip evaluation and independently initialized short segments use different protocols. Neither result measures unseen-motion generalization or hardware transfer. Source snapshot.
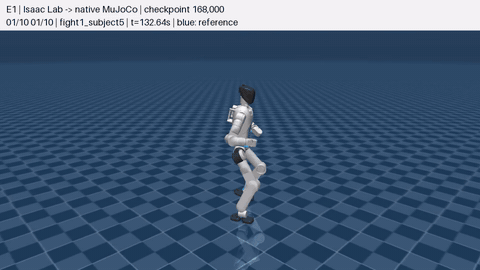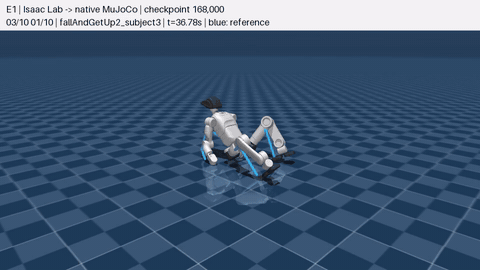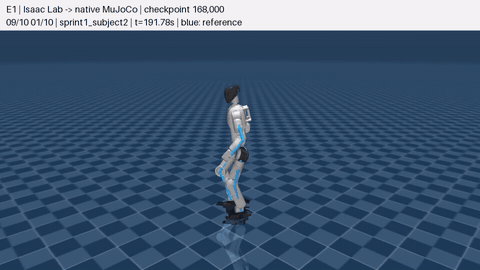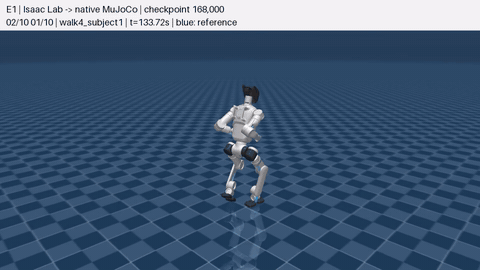
E1 sim-to-sim · native MuJoCo
Repository · Setup · Results
- By liuskywalkerjskd. Ports supermimic_vibed to the 31-DoF LimX Oli in Isaac Lab 3, adding motion retargeting, robot kinematics and full-motion video export.
- Upstream report: At iteration 18,000, the original 40-motion LAFAN1 evaluation reports return 0.6783 and 36 / 40 completed clips, after about 2.20 hours on one RTX 4090.
- Useful context: The displayed walking clip is a selected excerpt. Use the full-library evaluation when judging tracking coverage. Source snapshot.
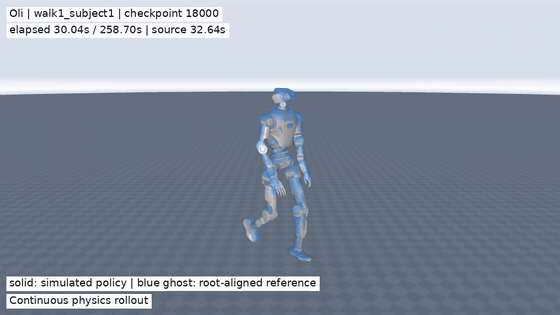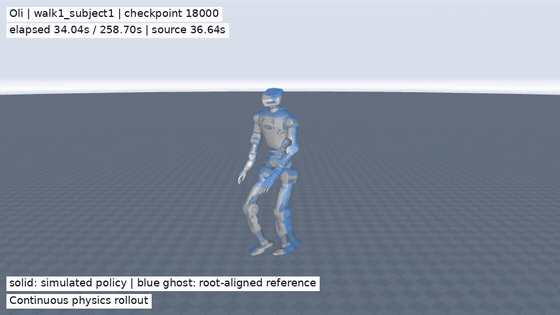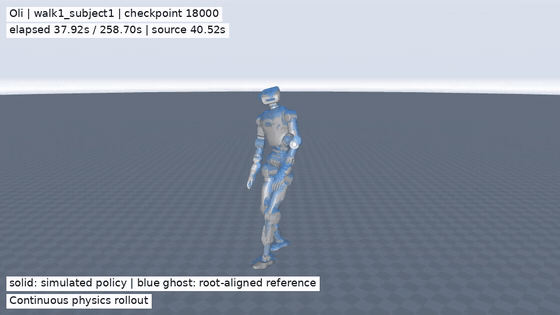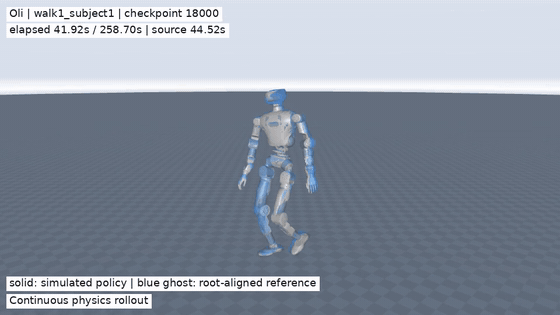
Simulation · selected Oli walking excerpt
Repository · Run the released model · Results
- By WXyuany. Adapts the CuboiLeo G1 baseline to Apple Silicon, using CPU MuJoCo for physics and PyTorch MPS for learning, with released weights and playback tools.
- Upstream report: For the released 21k checkpoint on a 24 GB Apple M5, seed 0, the original 40-motion evaluation reports return 0.7081 and 25 / 40 completed clips; a fresh-environment check completes 26 / 40.
- Useful context: Return is normalized by executed steps without zero-padding after failure, and the actor uses nine extra anchor-observation dimensions. Read return together with completion; held-out generalization is untested. Source snapshot.
Simulation · G1 walking on Apple M5
Repository · Setup · Evaluation
- By panhainan2020. A standalone mjlab / CPU MuJoCo port of supermimic_vibed for G1, with observation-compatibility profiles, inference weights and held-out 100STYLE evaluation.
- Upstream report: The fixed 98k policy completes 40 / 40 LAFAN training motions at return 0.8713, and 3,569 / 3,573 unseen 100STYLE clips at 0.8045, without fine-tuning.
- Useful context: The datasets differ in duration and retargeting. “Completed” means no termination was triggered; this does not reproduce the paper’s full training schedule or all experiments. Source snapshot.

Report screenshot · LAFAN training motions and unseen 100STYLE clips
Repository · Setup · Results
- By RadiantForever. Downstream port of SuperMimic to the wheeled-legged wheelbipe V14_2. The humanoid motion library is replaced by a velocity-command library; a 6-DoF action policy (four leg targets plus two wheel speeds) is optimised inside the differentiable world model, with PhysX / Isaac Lab as the data source and no PPO in the loop.
- Upstream report: On a 16-command grid the unified checkpoint reaches 0 / 16 falls and normalized return 0.983; a speed-focused checkpoint tracks 1.40 m/s at 0.01 error, and yaw reaches 10.21 rad/s (1.62 rev/s) with a 0.20-0.28 m leg cycle. Single RTX 4090, 4096 environments, 3.72 h cumulative over resumed runs; one run, no seed sweep.
- Useful context: A pretrained PPO policy for the same robot is mixed into the world-model buffer for the first 800 iterations only, and no teacher-free ablation was run, so these numbers are not attributable to the method alone. The port requires the robot USD asset from the upstream repository; there is no URDF. Source snapshot.

Simulation · four commanded conditions: 10 rad/s yaw (top-left), 0.20-0.28 m leg cycle (top-right), 1.5 m/s forward with leg cycle (bottom-left), yaw with leg cycle (bottom-right)
Ideas transferred to other control settings, with different tasks and evaluation protocols.
Repository · Quickstart · Reference motions
- By swaggyliu. Recreates the shared-world-model and imagined-policy-learning loop in FlatWorld with an eight-joint 2D humanoid and motion-tracking tasks.
- What it provides: Provides training, reference baking, per-skill rendering and a 33.3-second multi-skill promo covering walking, running, jumping, dancing, fighting, crouching and fall/get-up.
- Useful context: References are procedural, LAFAN-like 2D motions, not the LAFAN1 dataset. The character also uses a mild root assist, so this is an illustrative adaptation rather than a G1 benchmark. Source snapshot.

2D simulation · full 33.3-second multi-skill promo
- By hitsz-oyx. Explores action-conditioned contact dynamics and short-horizon BPTT for the Inspire hand in Isaac Gym / DExplore, combining contact memory with native collision-geometry queries.
- What it provides: Separately records behavior cloning, dynamics fitting, bounded actor/critic updates and native-physics evaluation.
- Useful context: Improved reference survival comes with lower mean return in the reported comparison. Reliable model-based manipulation gains are not established, and contact proxies are not certified grasp success. Source snapshot.

Report screenshot · native-physics comparison; higher reference survival, lower mean return
- By azizkhadraoui. Transfers SuperMimic-style gradient-based learning to G0.5 VLA steering on LIBERO: a noise policy is trained through a frozen flow sampler using world-model and critic gradients.
- Useful context: This is one task-specific steering experiment within a broader VLA stack. The linked script identifies the relevant method; the repository’s other planning and memory results are separate experiments. Source snapshot.

Code index screenshot · world-model / critic steering experiment
These works provide methodological background or comparison points; they are separate research projects.
| Work | Connection | Primary resources |
|---|---|---|
| SuperTrack (2021) | Earlier character motion tracking through a learned differentiable world model and gradient-based control learning. | Author explanation · Paper |
| BeyondMimic (2025) | Humanoid motion tracking and guided diffusion control; supermimic_vibed references its actuator and task conventions. |
Project · Paper |
| SONIC (2025) | Large-scale humanoid motion tracking; the original SuperMimic work compares against a released SONIC checkpoint. | Project · Paper · Code |
- LAFAN1 retargeting dataset — G1 motion assets used by
supermimic_vibed, UniSuperMimic, and SuperMimic-Reproduced. Follow each repository's preparation instructions and the dataset's own terms. - BONES-SEED — the motion-data source used for the original paper's large-scale benchmark. The raw dataset and paper-filtered evaluation set have different counts. Access requires accepting the dataset's terms on Hugging Face.
- Official interactive demo — explore the original policy in the browser before choosing a training stack.
- Official method explanation — simulator collection, model fitting, and policy learning.
- InstinctMJ releases — upstream distribution of task data and model assets; check the release description for the relevant branch and task.
Have a new implementation, extension, tutorial, or demo? Open a pull request using the contribution guide. Include the original source, the relationship to SuperMimic, the relevant branch, and evidence for any result you quote.
When building on the method, cite the original SuperMimic paper and credit the implementation you use. BibTeX below follows the official project:
@inproceedings{liao2026supermimic,
  title     = {{SuperMimic}: Scaling Humanoid Whole-Body Control
               with One Differentiable World Model},
  author    = {Liao, Qiayuan and Shao, Yiyang and Long, Junfeng and
               Zakka, Kevin and Horowitz, Roberto and Abbeel, Pieter and
               Sreenath, Koushil},
  booktitle = {Conference on Robot Learning (CoRL)},
  year      = {2026}
}Thanks to the original SuperMimic authors and all community maintainers. The presentation of this list is inspired by Awesome Nano Banana Images and Awesome World Models.
The original curation text in this collection is released under CC0 1.0. Third-party code, papers, datasets, and media retain their respective rights and terms. This includes the original paper figure and official video previews stored in this repository; they are not covered by this collection's CC0 dedication. Community media previews and credits follow the same attribution rule.
If this list helps you, consider starring the repository so more people can discover it.