Repository navigation

llm-app is now serviette. This repository used to host Pathway's LLM app templates. They are all still available, unchanged, in
pathway/examples/llm-app. The repository itself now hosts serviette, a no-code RAG server built from what we learned from those templates.
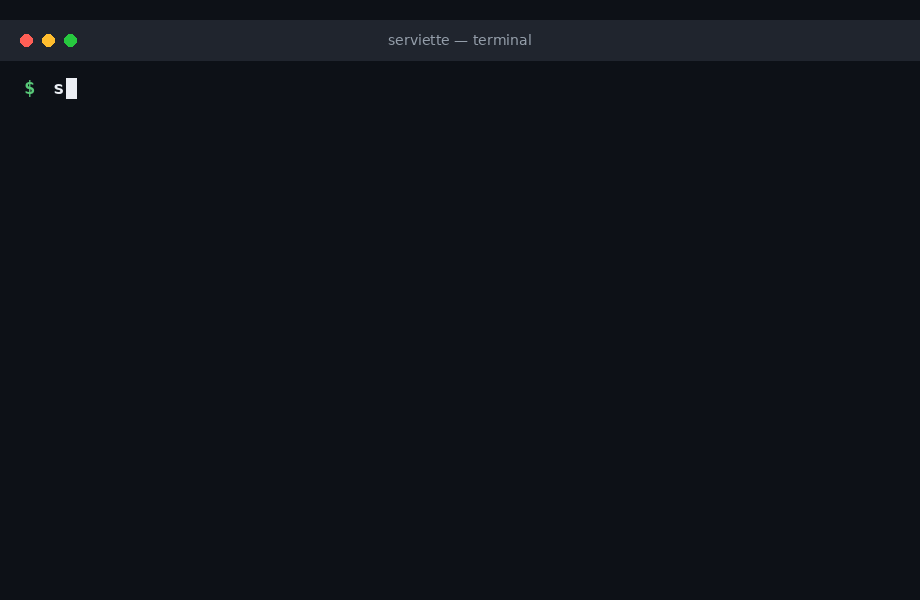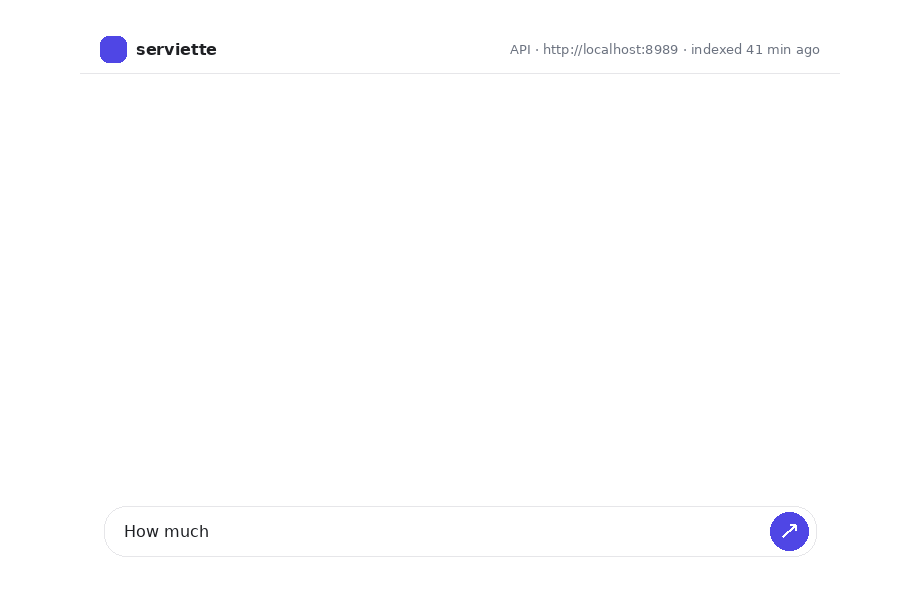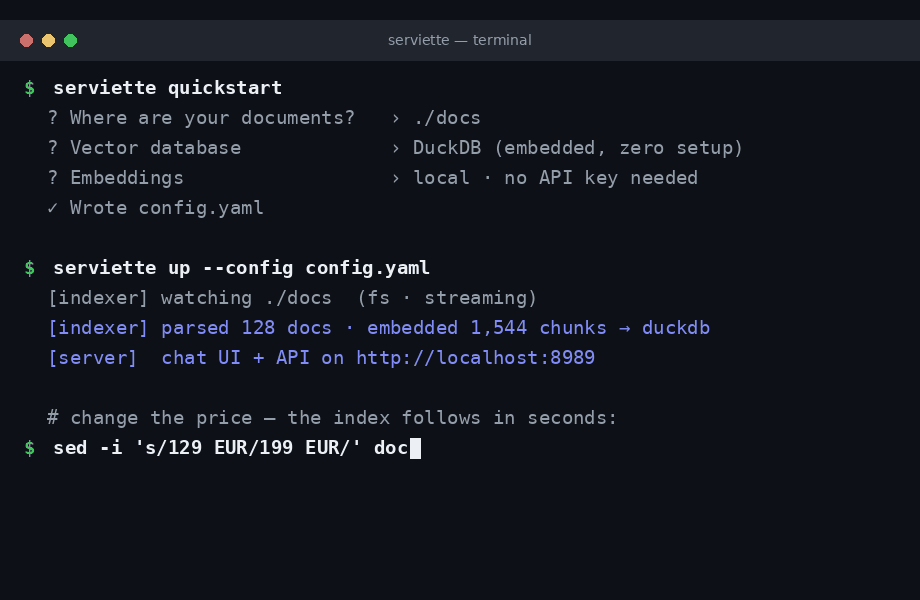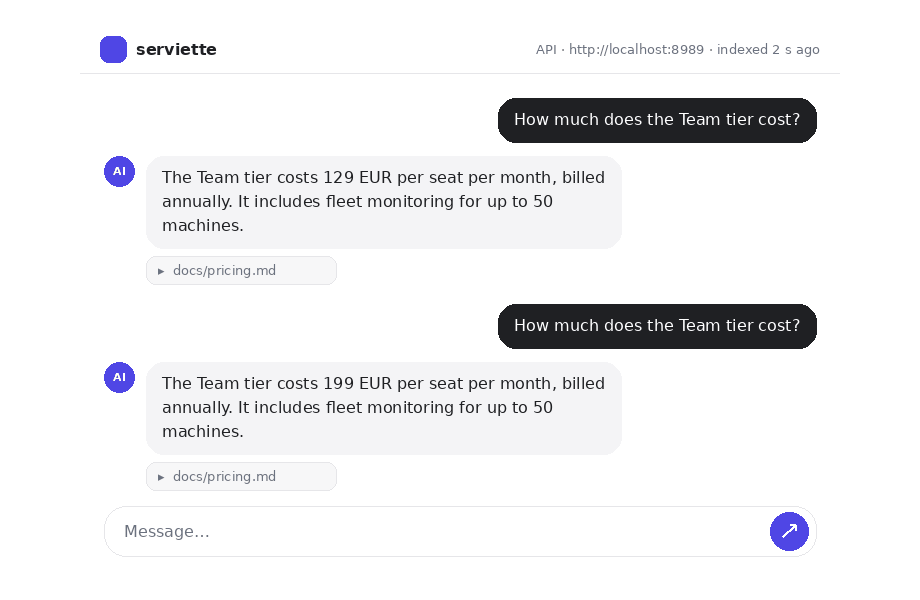
serviette is a no-code RAG server that keeps its answers in sync with your documents. Point it at a folder, pick a vector database and an embedder in one YAML file, and you get a chat UI and a REST API that answer from those documents and cite their sources. Edits, new files and deletions show up in the answers within seconds, with no re-indexing step.
Try it
pip install serviette
export PATHWAY_LICENSE_KEY=...        # free: https://pathway.com/framework/get-license
export OPENAI_API_KEY=sk-...
serviette demo --embedder openai      # → chat at http://localhost:8989
To run it on your own documents, use serviette wizard and then serviette up. See the README.
What's inside
- No code: one YAML file, or have
serviette wizardgenerate it. - 8 vector databases: DuckDB (embedded, the default), pgvector, Qdrant, Milvus, ChromaDB, Weaviate, Pinecone, MongoDB Atlas. Each one has integration tests against a real instance.
- Live sources: local folders, Google Drive, S3/MinIO, SharePoint, FTP/SFTP/WebDAV.
- Multimodal: PDFs with tables, Office documents and scans by default. Audio and video are added automatically when the corresponding API keys are set.
- Retrieval options, each enabled in config: hybrid BM25 + vector search, reranking, adaptive RAG, query decomposition and MMR.
- Fully local option: local embeddings with DuckDB, with no API keys for indexing.
- Separate indexer and server: the server is stateless and scales horizontally, and the indexer splits work across worker processes.
Benchmarks
- Indexing: 50 GB of text (26M pages, 17M files) in 6 hours on a 96-core machine with local embeddings, with peak indexer memory of 14.65 GiB. See the benchmark details.
- Accuracy: 0.50 gold-article recall on FRAMES, versus 0.15 for the paper's BM25 baseline. Adding serviette to gpt-5 improves gpt-5's accuracy by +5.2 pp. See the full report.
Coming from llm-app?
| llm-app template | Where it is now | Closest serviette feature |
|---|---|---|
question_answering_rag |
templates/question_answering_rag | serviette up: chat + /api/v1 |
document_indexing |
templates/document_indexing | serviette indexer + /api/v1/retrieve |
adaptive_rag |
templates/adaptive_rag | rag.adaptive |
multimodal_rag |
templates/multimodal_rag | multimodal parsing, on by default |
video_rag_twelvelabs |
templates/video_rag_twelvelabs | video parsing via TWELVELABS_API_KEY |
private_rag, slides_ai_search, drive_alert, unstructured_to_sql_on_the_fly, document_store_mcp_server |
templates/ | — |
The cookbooks are in examples/llm-app/cookbooks. Old links to pathwaycom/llm-app redirect here.
Feedback
Questions and ideas are welcome in Discussions, on Discord or in issues. If you need conversation memory, user accounts or a hosted setup, tell us what your case needs.