Repository navigation
Releases
Releases · Anbu-00001/Anamnesis
v0.6.0

The rest of the 0.5.0 audit, an experiment on the whole tool built before any of its data,
and a way for a person to bet on their agent. 0.5.0 was never published as a release, so
this is the first since 0.4.2, and its notes below are part of what 0.6.0 ships.
Upgrading
--checknow also refuses commands that cannot fail through a wrapper or a shell:
env true,sh -c true,bash -c 'exit 0',nice -n 5 true,timeout 30 true,sleep 1,
a barels,cat,env, and a constanttestsuch astest 1. A command with real
arguments is still accepted (ls build/out,test -f Cargo.toml,env RUST_LOG=debug cargo test,timeout 600 cargo test,sh -c 'cargo build && cargo test').- A run that the runner says ran no tests is no longer graded: pytest exit 5 or "collected 0
items", unittest "NO TESTS RAN", go "[no test files]", "no tests found", "ran 0 tests". The
same goes forana runon a command that only lists or builds tests (--collect-only,
--co,--no-run,--list), and for a command that never started (the shell could not find or run it).
Added
outcomes.jsonl: one line per test run the post-tool hook sees, pinned or not. It holds
the runner,bareorana_run, the exit status, what the grader made of it,after_edit,
the repo, the model and the session's prompt number, and never the command, its output or
the prompt. It prints nothing. It is the outcome a trial of the whole tool needs
(docs/MEASUREMENT.md, addendum 4, which sets that trial's rules before any data and says
what is still to build before it can start, not before 2027-01-04).- Day one shows your calls. Below the 20 graded calls a verdict needs, the report lists
the latest graded calls (id, the chance you gave, what happened, its Brier score), newest
first, and marks a sure call that missed. Ids only, never statements: the JSON also reaches
a model through MCP.so_farin--json. - Is the outcome log seeing the runs?
validation/outcome_coverage.pymatches each run
the pre-tool hook let go ahead with its outcome line. The rule set before the trial: 95% or
more over 14 days, or the logger is fixed first. - An owner's protocol, given at session start. A
protocol.mdbeside the agent ledger is
passed to the model by the session-start hook, labelled as the owner's, cut at 6000 bytes,
and withheld in an OFF week. Putting standing instructions there instead of in the agent's
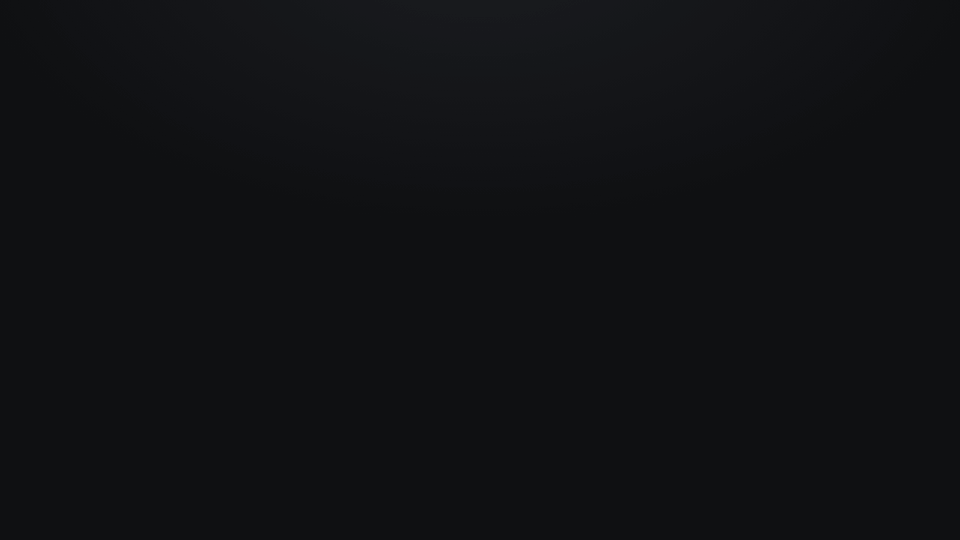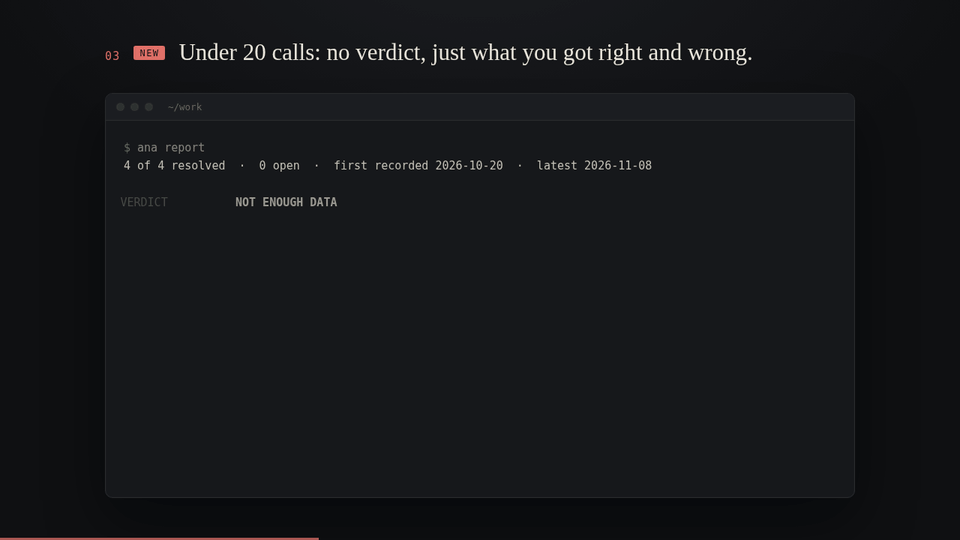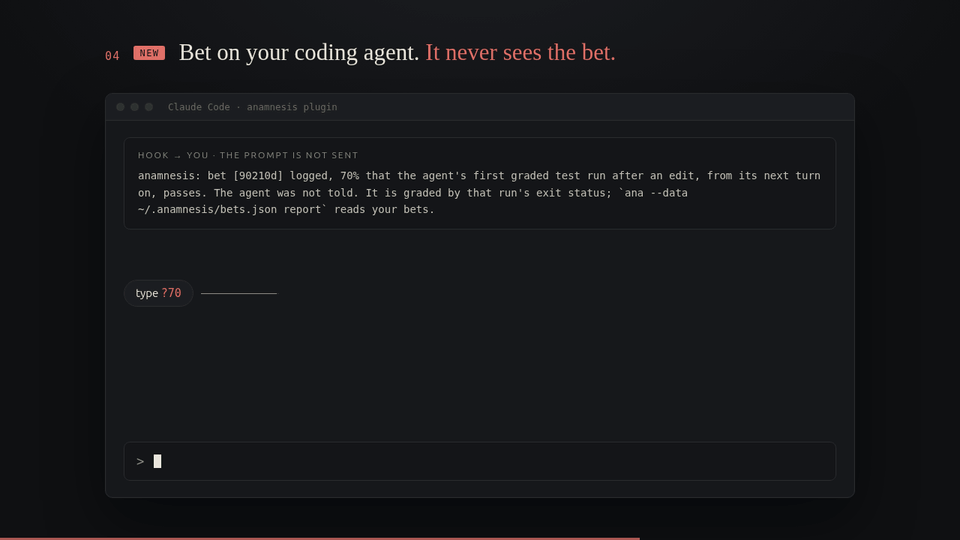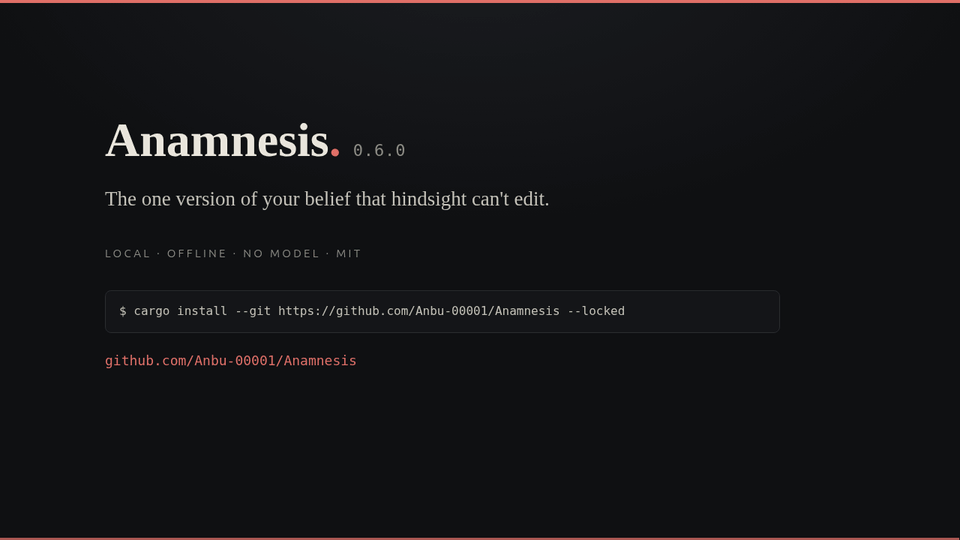
global instructions is what lets the weekly trial switch them off. No file, no change. - Bet on your agent. Type
?70as a whole prompt: a 70% bet that the agent's first graded
test run after an edit, from its next turn on, passes. The UserPromptSubmit hook blocks the
prompt, so it never reaches the model, and leaves its text out of the block message. The
post-tool hook grades it from the exit status and tells you only. Bets live inbets.json
beside the agent ledger, which the agent's tools never read;ana --data ~/.anamnesis/bets.json reportscores how far you trust your agent. - Is each hook alive, and what does it cost?
ana wherelists every hook event with when
it last ran here, how often, and how many bytes of its output reached the model (about a
quarter as many tokens). A hook that never fires is otherwise silent. - Audit sampling, opt-in (
ANAMNESIS_AUDIT_RATE=0.2). A turn is drawn with that chance,
by the hook rather than the agent. Every bare test run after an edit in a drawn turn is
refused until it goes throughana runwith a pinned forecast. The claims calibration is
read on are then a random sample of the agent's checks, not ones it picked. The protocol log
is nowv: 4, withaudit_pandaudit_drawn. Not meant to be on before addendum 3's
reading: it changes what that trial measures. - Pooling across volunteers.
crossover_report.py --exportprints one line with no ids,
times or repos: the protocol's hash, the within-pair differences and the e-value.
validation/pool_evalues.pycombines such lines into a mean e-value (valid under any
dependence), a product (valid if independent) and a pooled sign-flip test. Cargo.tomlcarries cargo-binstall metadata for the release assets.- The weekly trial can be enrolled and read.
ana trial startwritestrial.jsonbeside
the agent ledger once: a start Monday, no earlier than 2027-01-04, and a seeded draw of which
week of each pair is ON.ana trial statusnames the week, never the arm. In an OFF week
nothing reaches the model: no session-start line, no checkpoint, no pin refusal, no
post-tool context, empty MCP instructions. Grading, the ledger and the logs go on, and the
person still gets their messages. Without a trial nothing changes.
validation/crossover_report.pyreads it by addendum 4's rules (exact sign-flip test,
anytime-valid e-value, adherence) and has a--selftest. - File edits are logged to
outcomes.jsonl, one line each, with no file name or content.
The plugin registers aPostToolUsematcher onEdit|Write|MultiEdit|NotebookEdit. Hooks
installed by hand need that matcher added, pointing atpost-tool.sh. - A weak quiet test is not shown in green. When the test would miss most errors of 30%,
the badge and card read "Nothing found yet" in grey, not "No miscalibration found" in green. - Easy calls are named. When 30% or more of the graded calls were said at 95% or more
either way, the report adds a line saying so, with the Brier score on the rest (at five or
more of them). Such a record does not get the top label. Sure things lower a Brier score
without showing much judgement. - Release binaries carry a build attestation (
actions/attest-build-provenance).
install-ana.shverifies it withgh attestation verifywhenghis installed and signed
in, and aborts if verification fails. Otherwise it prints the command to run. Releases
before 0.6.0 have none, and the installer says so. - Windows.
install-ana.shinstallsana.exeunder Git Bash (MINGW, MSYS, Cygwin on
x86_64). The launchers look for~/.anamnesis/bin/ana.exe, and the release smoke test runs
the installer and a session-start hook under Git Bash on Windows. - The
decideVERIFY line now says how to check: run it here if you can, and read the primary
source if it lives off this machine.
Checked, and kept
- The decision gate does something. The proposal was to remove
ana decideif it gave the
same verdict for at least 90% of claims at every stake. On the 2,265 first forecasts in
the author's agent ledger, the most common verdict covered 49% at stake 1, 69% at 2, 87% at
5 and 88% at 10 and 20, and less again with the map scoped to one model. It stays.
Fixed
- The Stop hook counted a claim as overdue only by its
--bydate. It now uses the due date
the evidence order uses (evidence::came_due: the--bydate, or 1 to 7 days after it was
logged, by kind), and the message says so.
0.5.0 was never released on its own; its changes ship in this release too. See CHANGELOG.md.
Verify a download: gh attestation verify <file> -R Anbu-00001/Anamnesis.
v0.4.2
v0.4.2-rc.1
v0.4.2-rc.1
v0.4.1
v0.4.1-rc.1
v0.4.1-rc.1
v0.4.0
v0.4.0-rc.1
v0.4.0-rc.1