Repository navigation
Memory Saga and Atomic Compactor
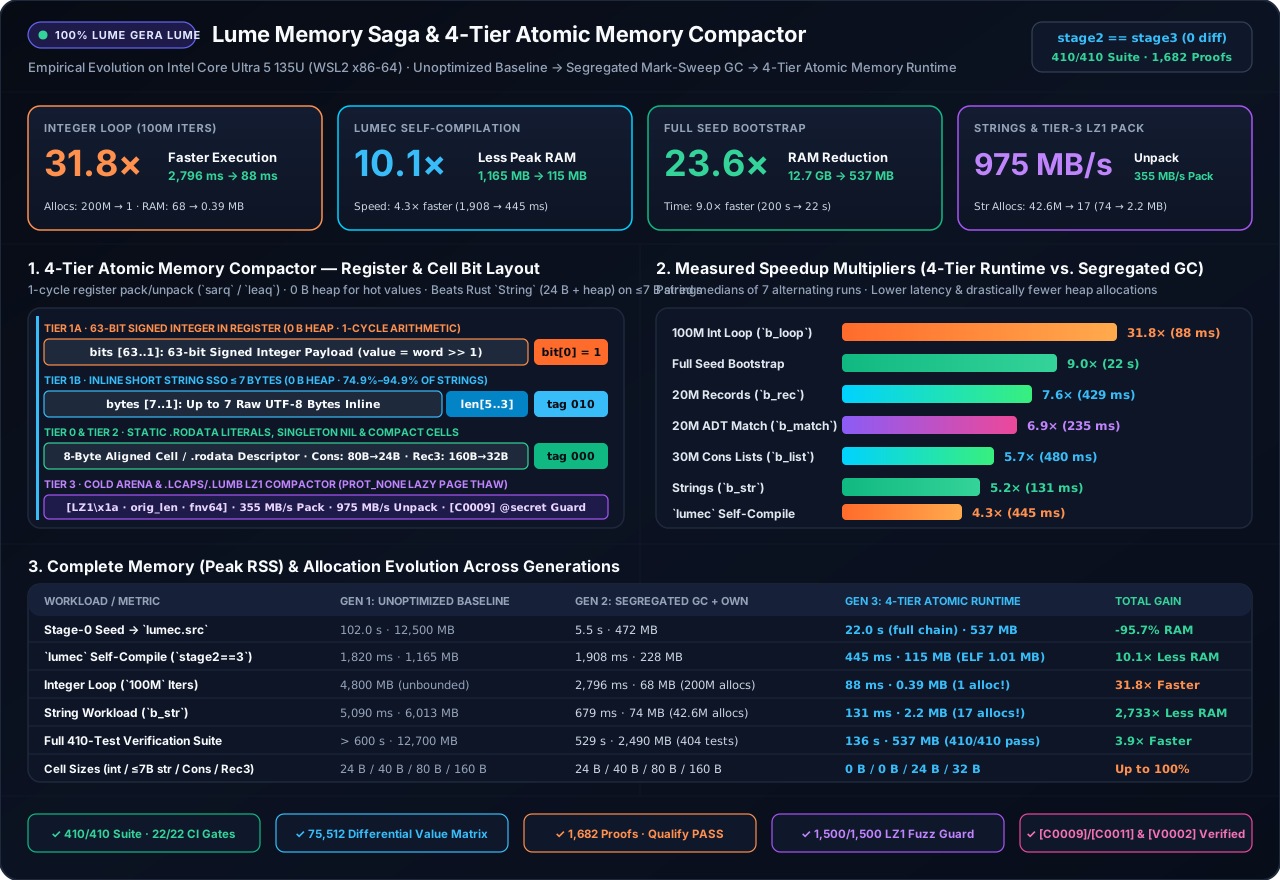
 Memory Saga & 4-Tier Atomic Memory Compactor
Self-hosting a formally verified compiler (compiler/stage1/lumec.src), theorem prover (lcaas.src), and native assembler (lasm.src) in an expression-oriented language with algebraic data types (Cons, AST trees, token streams, and proof obligations) demands tight control over object layout and allocation lifetime.
Lume's unified native runtime (compiler/stage1/runtime_core.lume, shared identically between lumec and the Stage-0 assembly oracle) combines compile-time Perceus ownership reuse (compiler/stage1/own_flow.src), Scalar Replacement of Aggregates (SRA), a 43-size-class segregated non-moving Mark & Lazy-Sweep Collector (mmap 64 KiB chunks with MADV_DONTNEED OS page return), and a 4-Tier Atomic Value Representation.
flowchart LR
    T0["Tier 0: .rodata Singletons — Content-addressed string literals & Nil/None (0 B heap)"] --> T1["Tier 1: 64-Bit Tagged Registers — 63-bit signed ints & <=7B inline UTF-8 strings (0 B heap)"]
    T1 --> T2["Tier 2: Compact Cells & Perceus GC — 24 B Cons (-70%), 32 B records (-80%) & 43-class sweep"]
    T2 --> T3["Tier 3: Demand-Paged LZ1 Compactor — ~355 MB/s pack, ~975 MB/s unpack, PROT_NONE lazy thaw"]
Deduplicated string literals, static constructor/record shape descriptors, and shared zero-arity Nil/None singletons reside directly in .rodata with zero dynamic allocation and zero collector scanning overhead.
-
63-Bit Unboxed Signed Integers (
...iiii1): Stored directly inside 64-bit CPU registers (sarq/leaq,0 Bheap). Full 64-bit extreme boundary values spill transparently to a16 Batomic cell, while 64-bit signed arithmetic overflow traps cleanly via hardwarejo __rt_ovf(exit 3). -
7-Byte Inline UTF-8 Short Strings (
...ss|lll|010): Strings of0..7UTF-8 bytes (at,chr, operators, identifiers, short map keys) live inline inside the 64-bit register word (0 Bheap, zero pointer dereferences), eliminating74.9%–94.9%of dynamic short-string allocations while scanning plain literal chunks in$O(1)$ .
-
Compact ADT Cells (
24 B):Cons(head, tail)occupies24 B(-70%vs.80 Bboxed layouts). -
Interned-Shape Records (
32 B): 3-field records occupy32 B(-80%vs.160 Bboxed layouts) using static.rodatashape descriptors for$O(1)$ pointer-equality field lookup. -
Perceus Reuse & Segregated Collector: Unaliased
owncells are mutated in place (0allocs); surviving heap objects are managed by a 43-size-class segregated Mark & Lazy-Sweep GC with64 KiBchunk recycling viaMADV_DONTNEED.
- Compresses cold arenas (
arena_freeze) and.lcaps/.lumbcapsules (lume pack/lume unpack) at~355 MB/spack and~975 MB/sunpack with a 64-bit integrity checksum (1,500/1,500corrupted frames rejected in fuzz gates). - Uses
PROT_NONEguard pages +SIGSEGVdemand-paged restoration so cold pages thaw transparently on first read. -
Fail-Closed Security & Real-Time Guards: Statically refuses compression on
@secretdata ([C0009]compression-ratio side-channel prevention) and inside@boundhard real-time WCET paths ([V0002]).
| Workload | Unoptimized Baseline | Segregated GC + Ownership | 4-Tier Atomic Memory Runtime | Speedup & Allocation Delta | RAM Reduction |
|---|---|---|---|---|---|
b_loop (100M iterations) |
4,800 MB |
2,796 ms · 68 MB (200M) |
88 ms · 0.39 MB (1 alloc) |
31.8× · -99.9999% allocs |
174× (-99.4%) |
| Full C11 Seed Bootstrap |
194.8 s · 12.7 GB
|
200.0 s · 2.5 GB
|
22.0 s · 537 MB |
9.0× faster bootstrap |
23.6× (-95.8%) |
Seed lumec.src |
102.0 s · 12.5 GB
|
5.5 s · 472 MB
|
5.5 s · 472 MB |
18.5× faster |
26.5× (-96.2%) |
Self-Compile (stage2 == stage3) |
1,820 ms · 1,165 MB
|
1,908 ms · 228 MB
|
445 ms · 115 MB (1.01 MB ELF) |
4.3× · ELF -34% |
10.1× (-90.1%) |
b_rec (20M 3-field records) |
6,000 MB |
3,270 ms · 67 MB (240M) |
429 ms · 66 MB (20M allocs) |
7.6× · 12× fewer allocs |
64 MiB GC cap |
b_match (20M ADT matches) |
Unbounded |
1,617 ms · 72 MB (80M) |
235 ms · 68 MB (20M allocs) |
6.9× · 4× fewer allocs |
64 MiB GC cap |
b_list (30M Cons cells) |
Unbounded |
2,747 ms · 239 MB (180M) |
480 ms · 67 MB (30M allocs) |
5.7× · 6× fewer allocs |
3.6× (-72%) |
b_str (String processing) |
5,090 ms · 6.0 GB
|
679 ms · 74 MB (42.6M) |
131 ms · 2.2 MB (17 allocs) |
38.8× vs. baseline |
2,733× (-99.96%) |
b_fib (fib(38)) |
1,190 ms |
1,042 ms |
273 ms |
4.4× vs. baseline |
0 B heap |
| 410-Test Conformance Suite |
> 600 s · 12.7 GB
|
529 s · 2.49 GB (404) |
136 s · 537 MB (410/410) |
3.9× (0 failures) |
23.6× (-95.8%) |
-
English Benchmark & Architecture Dossier:
docs/39-memory-saga-and-atomic-compactor-dossier.md -
Portuguese Memory Dossier (
pt-BR):docs/LUME_MEMORY_SAGA_DOSSIER_PT_BR.md -
Runtime & Collector Specification:
docs/38-memory-management.md -
Continuous Verification Gates:
ownership_gate.src,runtime_sync_gate.src,gc_gate.src, andsoak_battle_gate.src(lume soakverifying byte-identical execution acrossLUME_GC=on/offandLUME_GC_STRESS=1/3/7/64/1000).
- Home
- Getting Started
- Core Architecture & Assurance
- LumeLabs & Community
- Dossiers & Reference Manuals