Repository navigation
Enrichment
HOME > [SNOWPLOW TECHNICAL DOCUMENTATION](Snowplow technical documentation) > Enrichment > Enrichment
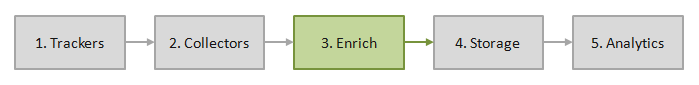
The Snowplow Enrichment step takes the raw log files generated by the Snowplow collectors, tidies the data up and enriches it so that it is:
- Ready to be analysed using EMR
- Ready to be uploaded into Amazon Redshift, PostgreSQL or some other alternative storage mechanism for analysis
The current enrichment process provides 2 options for developers to use:
- Using Scalding, a Scala implementation of Cascading, an ETL library that's written on top of Hadoop. This is the Hadoop Enrichment.
Snowplow uses Amazon's EMR to run the Enrichment process. The regular running of the process (which is necessary to ensure that up-to-date Snowplow data is available for analysis) is managed by EmrEtlRunner, a Ruby application.
- Using Scala and Amazon Kinesis for real-time processing of data.
In this guide, we cover: