Repository navigation
Releases
ChatLLM Web v3.2.0 — Local Agent Workspace

ChatLLM Web v3.2.0
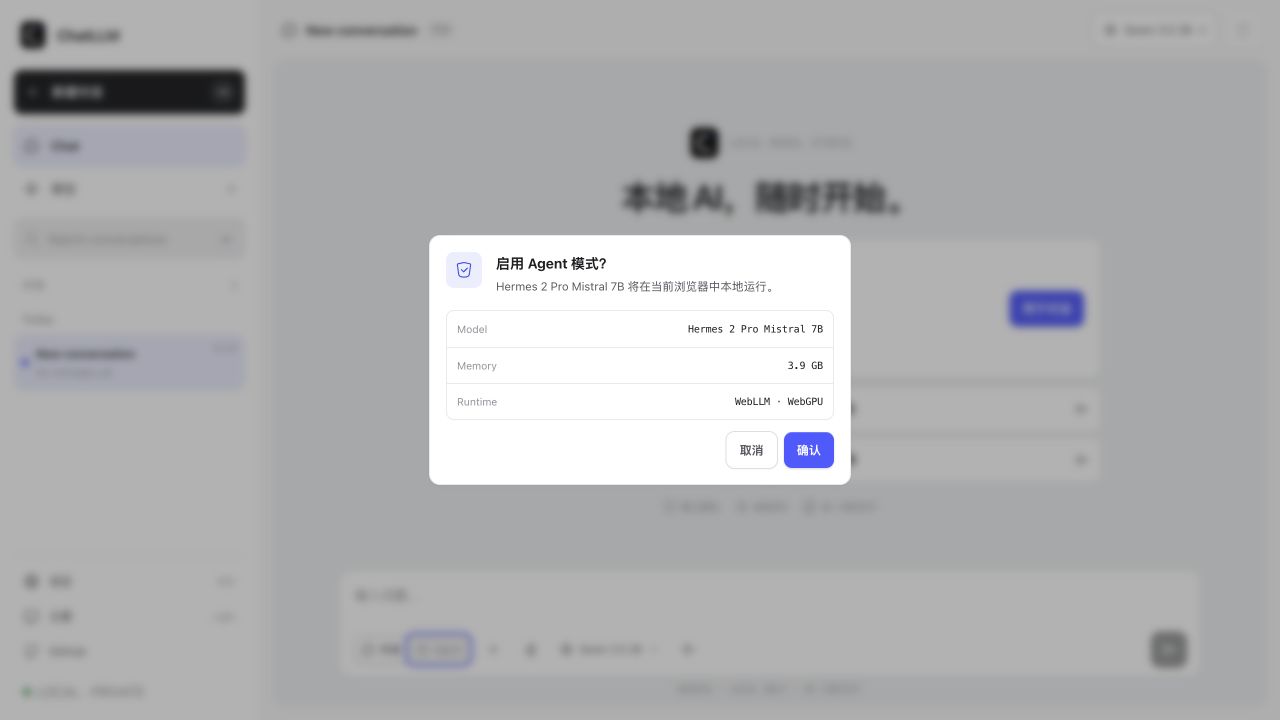
v3.2 turns the browser-native Local Model Studio into a Local Agent Workspace with native WebLLM function calling, observable tool runs, and approval-gated artifacts.
Highlights
- Per-conversation Chat and Agent modes.
- Native tool calling with Hermes 2 Pro Mistral 7B, Hermes 2 Pro Llama 3 8B, and Hermes 3 Llama 3.1 8B.
- Eight sandboxed local tools for selected context, arithmetic, and conversation artifacts.
- Automatic read-only tool execution and explicit diff approval for every artifact write.
- Beautiful UI Agent Run Rail, Tool Chips, Task Rows, Diff Table, and Artifact panel.
- Eight-step run limit with stop, retained progress, error attribution, and retry.
- Markdown, code, JSON, and text artifacts stored in IndexedDB and available for copy or download.
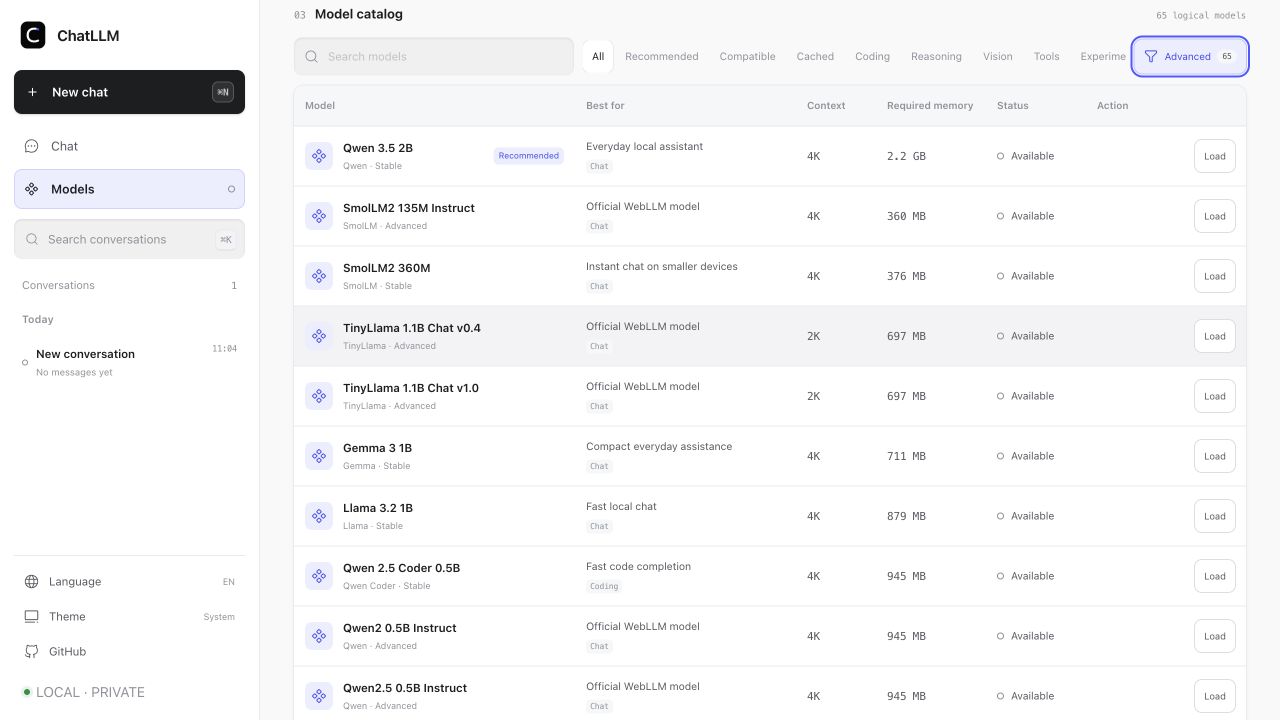
- 20 curated models and 65 logical models backed by 163 WebLLM 0.2.84 records.
Security boundary
- File tools can access only the files selected for the current run.
- Artifact tools can access only the current conversation.
- Arithmetic uses a dedicated parser without dynamic code execution.
- Artifact creation and replacement pause until the user approves the displayed line diff.
- Shell, direct disk writes, network search, MCP, RAG, and third-party data sources are outside the v3.2 runtime.
Data and upgrade
v3.2 starts with the new chatllm-v3.2 IndexedDB schema. Existing v3.1 browser data remains untouched and is not loaded into v3.2. Model assets already managed by the WebLLM Cache API remain provider-controlled browser cache entries.
Links
- Live: https://chatllm-web.pages.dev
- Repository: https://github.com/Ryan-yang125/ChatLLM-Web
- Models: https://chatllm-web.pages.dev/models
ChatLLM Web v3.1.0
ChatLLM Web v3.1.0
v3.1 expands Local Model Studio into a device-aware gateway to the WebLLM model ecosystem.
Highlights
- 18 curated models across chat, coding, reasoning, vision, and local tool-use categories.
- 65 logical models backed by all 163 records in WebLLM 0.2.84.
- Advanced catalog switch for the complete official model directory.
- Logical model grouping keeps quantization and 1K variants under one catalog item.
- Automatic
q4f16or compatibleq4f32selection from reported WebGPU features. - Stable, Experimental, Advanced, and Custom tiers.
- Recommended, Compatible, Cached, Coding, Reasoning, Vision, Tools, Experimental, and Custom filters.
- Search by model, family, capability, task, or official model ID.
- High-memory state based on declared VRAM and reported device memory.
- Active Advanced models remain available in the chat model picker.
Runtime
- WebLLM remains pinned to
0.2.84. - One Web Worker and one active engine remain the runtime boundary.
- Every built-in runtime record is passed through the 4K application configuration.
- Existing conversations preserve their selected runtime model ID.
- The early handwritten inference layer remains archived under
legacy/early-webllm-runtime.
Data and upgrade
v3.1 uses the existing chatllm-v3 IndexedDB schema. Conversations, attachments, preferences, custom models, and model caches remain available after the update.
Links
- Live: https://chatllm-web.pages.dev
- Repository: https://github.com/Ryan-yang125/ChatLLM-Web
- Models: https://chatllm-web.pages.dev/models
ChatLLM Web v3.0.0
ChatLLM Web v3.0.0
ChatLLM is now a complete browser-native Local Model Studio built around an agent-ready Beautiful UI component system.
Highlights
- Five curated WebLLM models with device-aware recommendation and 4K contexts.
- New
/modelsstudio for WebGPU insights, compatibility, caching, loading, switching, deletion, and custom MLC manifests. - Beautiful UI–based Chat Workspace, Prompt Bar, activity trace, recommendations, approvals, context cards, insight cards, and model catalog.
- Local TXT, Markdown, JSON, and code context with explicit limits.
- IndexedDB conversations, messages, attachments, preferences, and custom models.
- English and Simplified Chinese, light and dark themes, responsive mobile layouts, and reduced motion.
- Glimm WebGL sweep accents and Motion transitions.
- The original handwritten v1 inference core preserved under
legacy/early-webllm-runtime.
Model catalog
- Llama 3.2 1B
- Qwen 3.5 0.8B
- Qwen 3.5 2B
- Qwen 3.5 4B
- Qwen 2.5 Coder 3B
Local data
v3 starts with a fresh chatllm-v3 IndexedDB schema. The v2 localStorage conversation store remains separate.
Links
- Live: https://chatllm-web.pages.dev
- Documentation: https://github.com/Ryan-yang125/ChatLLM-Web#readme
ChatLLM Web v2.0.0
ChatLLM Web 2.0 is a complete rebuild for private, browser-native AI chat.
Highlights
- New Motion Lexicon v4 interface with responsive desktop and mobile layouts
- Current MLC WebLLM runtime with Llama 3.2 1B and an approximately 880 MB first download
- Web Worker inference with streaming Markdown, syntax highlighting, and math rendering
- Local conversations, search, Command-K palette, keyboard shortcuts, dark mode, and PWA support
- Production deployment on Cloudflare Pages
Breaking changes
- Removed the old Next.js, DaisyUI, Vicuna 7B, and bundled 2023 WebLLM paths
- Requires Node.js 20 or newer for local development
- Requires a current WebGPU-capable Chrome or Edge browser for inference
Links
- Live app: https://chatllm-web.pages.dev
- Source: https://github.com/Ryan-yang125/ChatLLM-Web
Validation
- TypeScript, ESLint, and Vitest passed
- Production build completed successfully
- Production dependency audit reports zero vulnerabilities
- Desktop, mobile, command palette, theme, and model load/cancel flows were browser-tested