Repository navigation
v1.0.2

What's new in v1.0.2
Rapid-MLX 1.0.2 generates video with synchronized sound, lets you stop a video job, and lets Desktop unload an idle model while the local API stays online. New installs start faster with a smaller default model, and the CLI accepts pasted Hugging Face links. It also fixes model selection, downloads, installs and Simplified Chinese and VoiceOver coverage found while testing 1.0.1.
Download: Rapid-MLX Desktop for macOS | CLI: rapid-mlx upgrade or curl -fsSL https://rapidmlx.com/install.sh | bash
Video with Sound: Pika H3 Flex
Pika H3 Flex generates video with a synchronized audio track, from a text prompt, a first frame, first and last frames, or image, video and audio references. Desktop adds MiniMax H3 and Pika H3 Flex to the Video tab and shows only the reference controls the selected model and this Mac support (#5557, #5559, #5570, #5581).
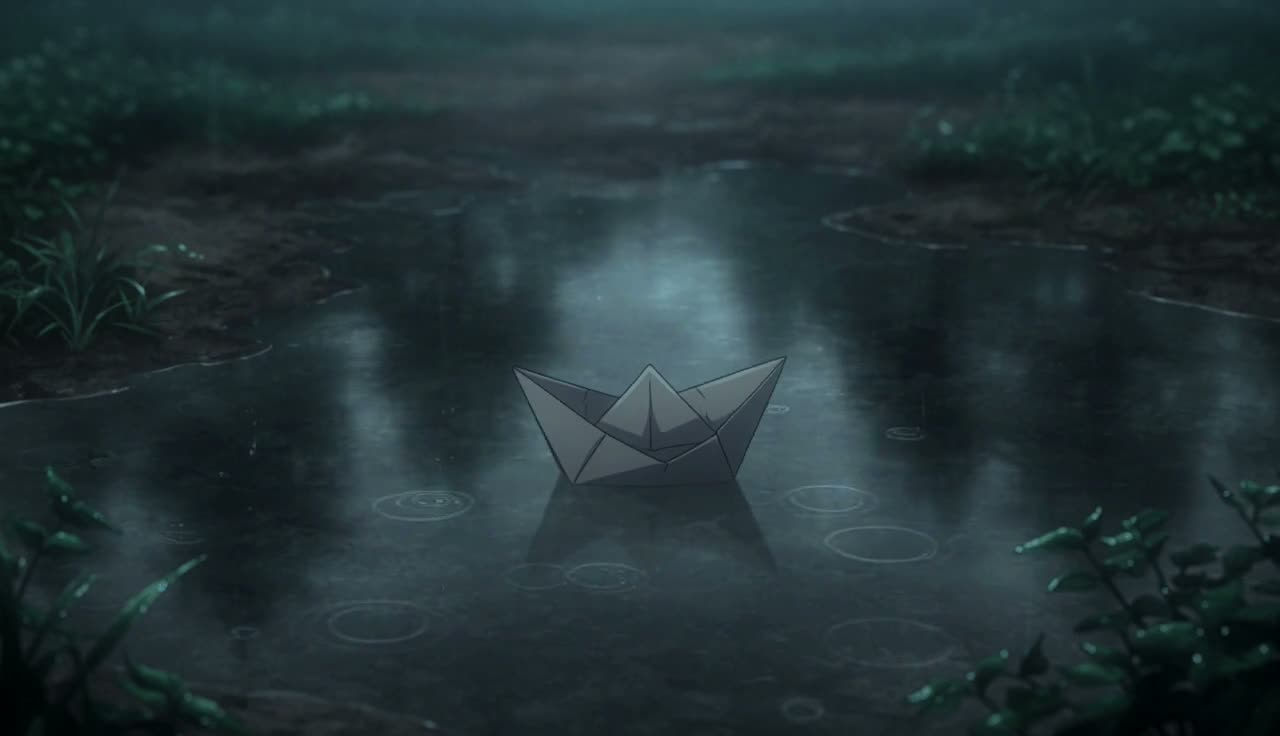
Generated locally with MiniMax H3 (Turbo, 8 steps, 720p). Click the image to play the 5-second clip.
| Mode | Inputs | Extra download |
|---|---|---|
| Text to video | prompt | none |
| First frame, or first and last frames | prompt + 1–2 images | none |
| References to video | prompt + image, video or audio references | about 69 GB on first use |
The reference assets are fetched only the first time you use references, so text and frame users skip about 69 GB; rapid-mlx pull pika-h3-flex --with-ref2va prefetches them (#5563). Desktop decodes video and audio references with its bundled media tools, with nothing extra to install.
Video jobs can now be stopped. Desktop shows Stop Generating, then “Cancelling…”, and keeps the job as “Cancelled”; the server cancels on every video backend and removes partial output (#5564, #5569).
Idle Unload Keeps the API Online
Desktop can unload an idle chat model without stopping the server. The next request, from Desktop or any client of the local API, loads it again. Settings adds a 5-minute option, and the sidebar shows unloaded and reloading states (#5580).
| After the idle timeout | 1.0.1 | 1.0.2 |
|---|---|---|
| Local API | stopped | keeps running |
| Model memory (Qwen3.5 4B, measured) | freed by stopping the server | 3.25 GB → 0.74 GB |
| Next request | start the server again | reloads the model automatically |
Speech models and older runtimes still stop the server when idle.
New Features and Improvements
- Faster first run: new installs start with LFM2.5 2.6B, a 1.6 GB download instead of 3.06 GB, so the first reply arrives sooner. Choosing a model that fits goes straight to “Download & start”; only a model this Mac cannot run opens the compatibility details. On Macs with 32 GB or more, Qwen 3.5 4B is one click away for image questions (#5614, #5615, #5626).
- Paste Hugging Face links:
serve,chat,run,pull,rm,infoandbenchaccept a pasted huggingface.co, hf.co or hf-mirror.com model URL and print theorg/namethey use.rapid-mlx pull <link> --check --jsonreports whether a model will run on this Mac without downloading it. In Desktop, paste a link into model management search, or choose Add from Hugging Face… in the model menu; unsupported models say why. When a repo also ships extra per-quantization folders, only the checkpoint that runs is downloaded (#5617, #5620, #5621, #5622, #5624, #5627, #5628, #5629). - Model picker: the chat picker lists downloaded models, the selected and serving models, and in-progress downloads (disabled); “Browse all models…” opens model management. Duplicate aliases are gone, draft-only MTP models are no longer offered as chat models, and video and catalog models show readable names (#5566, #5601, #5603, #5609, #5610).
- Simplified Chinese and VoiceOver: more of Settings, Audio, Images, Video and About is translated, including the benchmark meter axes and the Vision badge. VoiceOver reads the resident-model lock as “Kept in memory” and skips decorative symbols (#5540, #5602, #5603, #5611).
- Downloads:
pullchecks memory and free disk before downloading and shows the file plan, also for direct repository downloads (--no-preflightstages a model for another Mac). A slow-mirror fallback resumes the verified partial file instead of starting over (#5592, #5545). - Automatic MTP: the pinned MTP head downloads with its model when eligible, including on the first
serve, without a manual pull and restart. Offline mode and download opt-outs are respected (#5599, #5535). - Agents: agent setup finds the running server, waits while it downloads or loads, and can write configuration offline when you name a model. Agent configs use the memory-fitted context window (#5582, #5585, #5595).
- MTP on the server: the server keeps the prompt history the MTP head drafts from, so more drafts are accepted, and keeps the decode thread on performance cores. On an M5 Max 36 GB with Qwen3.8 27B 4-bit MTP, these measured +8% and +6% decode over HTTP; on an M3 Ultra we measured no change (#5571, #5586).
- Adaptive thinking: requests get a bounded reasoning budget from the server's configured effort, medium (2,048 tokens) by default, so answers start sooner. An explicit effort in the request still wins (#5604).
- Community Benchmark: fixed-schedule image benchmarks support 4-, 8- and 28-step models, and Desktop shows the protocol, step count and guidance that ran. Waits time out per output rather than per round (#5546, #5547, #5548, #5600).
- Terminal banner: interactive CLI commands open with a clear RAPID-MLX wordmark instead of the hard-to-read cheetah face (#5613).
- Privacy: anonymous setup measurements resume after relaunch and add fixed milestones for model choice, catalog failure and skipped setup. First-reply time is bucketed on device. Anonymous metrics also record which normalized model ids people check or add, so the catalog can prioritize them (#5550, #5608, #5620).
Bug Fixes
- Desktop no longer warns that a model “may crash your Mac” when the memory is only file cache: used memory now matches Activity Monitor (#5614).
- A video job whose server exits mid-generation stays in history with the failure reason instead of disappearing (#5588).
- Idle release keeps the saved chat model across relaunch, and a cancelled catalog refresh keeps speech and transcription selections (#5542, #5543).
- One unreadable cached model no longer hides the whole model list; Settings search finds compatibility aliases, and concurrent downloads keep overall progress (#5543, #5603).
- Share Compute keeps the recovery action when a saved key cannot be read, and receipts show the current model name (#5543).
- A prompt that can never fit returns a context-overflow error the client can act on, instead of a retryable “temporarily unavailable” loop (#5585).
- A failed processing step fails only the affected request or batch and keeps queued work running. Vision prompts are validated before encoding, and token counts include image expansion (#5537).
- DeepSeek V4 tool arguments keep literal thinking tags, and unsupported tool calling on the TensorFold runtime returns a clear error (#5537).
- Idle release no longer fires during speculative serving, uploads or Local Search indexing (#5544).
- Cancelling a pull during CLI startup prints “Cancelled” and exits cleanly, without a thread dump (#5545).
- An interrupted installer rebuild stops its subprocesses before restoring the previous environment, Apple Silicon Macs are no longer detected as Intel,
upgradechecks the environment that actually changed, anddoctorno longer shows credentials in source URLs (#5536). - Streamed WAV uploads of unknown length report the right duration, and local Kokoro voices, Dia playback speed and user-defined audio aliases work (#5535).
- Remote-code consent covers more vision processor routes, and readiness says why a model still needs consent (#5549, #5553).
- Harness commands that only
cdto the workspace root no longer ask for extra approval (#5596), and supported native model loaders no longer print a false unsupported-architecture warning (#5597).
Upgrade Notes
- Default model: only new installs start with LFM2.5 2.6B. Existing installs keep their saved model (#5615).
- MTP output: with the prompt-history fix, greedy output can differ from 1.0.1 where two tokens are exactly tied. The target model still verifies every emitted token (#5571).
- Thinking budget: adaptive-thinking requests without an explicit effort now stop reasoning at the server's configured budget, medium (2,048 tokens) by default (#5604).
- Pulls:
pullcan refuse a catalog model that does not fit this Mac; pass--no-preflightto download it for another machine (#5592). - Pika H3 Flex references: the first references job downloads about 69 GB; run
rapid-mlx pull pika-h3-flex --with-ref2vaahead of time to avoid the wait (#5563).
All changes
- chore: bump version to 1.0.2 (#5630) (f1aa011)
- fix(desktop): let pasted Hugging Face models download and delete (#5629) (ba9a045)
- fix(pull): fetch only the root checkpoint when a repo also ships quant folders (#5627) (6522eef)
- fix(desktop): judge pasted Hugging Face links in the sourceless app bundle (#5628) (47bde40)
- feat(desktop): make LFM2.5 2.6B the first-run default (#5615) (6096603)
- fix(desktop): keep Hugging Face add flow usable with no models and after deletes (#5624) (721e848)
- fix: restore green main after model reference check; reject config-only repos (#5622) (ebaa144)
- ci(desktop): watchdog detects stranded executors via heartbeats, not suite checkpoints (#5623) (068e0b4)
- feat(desktop): add models from a pasted Hugging Face link (#5621) (8ab6d73)
- feat(cli): machine-readable model reference check and model_ref_checked telemetry (#5620) (ff42750)
- feat(cli): accept pasted Hugging Face model URLs (#5617) (c4aea84)
- docs: rewrite AGENTS.md for external coding agents and point CLAUDE.md at it (#5619) (1ce914d)
- fix(desktop): start first-run downloads directly and drop the false memory warning (#5614) (6f2b036)
- docs: encourage AI-written pull requests (#5616) (69d800e)
- feat(cli): replace the cheetah face banner with a RAPID-MLX wordmark (#5613) (408216f)
- docs(release-notes): add release media and restructure v1.0.0 and v1.0.1 notes (#5612) (9ae8f7b)
- fix(desktop): localize Chinese benchmark labels and vision badge (#5611) (a67d34e)
- fix(desktop): name every catalog model instead of a generic "Model" label (#5610) (e2114cf)
- fix(models): hide draft-only MTP aliases from standalone selection (#5609) (0d75603)
- fix(desktop): keep first-run funnel across relaunch; add step milestones and reply-time bucket (#5608) (36b7e8f)
- test(mirror): recognize keyword calls in the serve wiring check (#5607) (21bb53f)
- fix(anthropic): bound adaptive thinking for local models (#5604) (72a2c33)
- fix(mtp): provision the default-on MTP sidecar with its target model (#5599) (7d03527)
- fix(connect): client SDK install hints target the user's project (#5595) (6b37d3e)
- fix(desktop): polish settings, downloads, model picker, and video controls (#5603) (dd27c01)
- fix(mac): finish zh-Hans and VoiceOver coverage for Audio, Images, Video and About (#5602) (967b6c6)
- fix(pull): refuse non-fitting or disk-overflowing pulls before downloading (#5592) (3060442)
- fix(mac): honest Community Benchmark protocol, schedule and availability labels (#5600) (069a4d6)
- fix(mac): friendly display names for video models (#5601) (2589987)
- fix(models): native loaders no longer trigger a false architecture warning (#5597) (34dc237)
- fix(harness): a leading no-op cd to the workspace root needs no approval (#5596) (0f0b5a0)
- fix(mac): keep a video job as failed when its server exits mid-generation (#5588) (09cc7f4)
- feat(mac): decode video and audio Ref2VA references with the bundled LGPL FFmpeg (#5581) (77f1cf4)
- fix(server): memory-fitted context window for every agent writer; never-fit prompts are context overflow, not 503 (#5585) (76798ce)
- perf(engine): keep the mlx-step thread on performance cores during decode (#5586) (c9c8841)
- fix(agents): setup no longer fails on a starting or absent server (#5582) (715f9a4)
- feat(mac): unload the idle model while keeping the local API online (#5580) (8178a75)
- fix(mtp): keep Qwen MTP head history on the server path (#5571) (fab94ae)
- docs: add a private knowledge base (local RAG) guide (#5579) (759afb6)
- feat(mac): generate H3 and Pika H3 Flex videos from the Video view (#5570) (dcb0065)
- feat(mac): stop an in-progress video generation from the Video view (#5569) (8edf388)
- feat(video): cancel in-flight video generation for every backend (#5564) (a77d899)
- fix(mac): show only downloaded models in the chat picker (#5566) (5cb28d9)
- ci: run desktop pytest jobs when shared pytest infra changes (#5568) (dff21d8)
- test: keep agent-profile isolation optional in minimal lanes (#5565) (dbf5bf9)
- fix(video): download Pika H3 Flex Ref2VA assets only when needed (#5563) (6951fe9)
- feat(video): add Pika H3 Flex Ref2VA reference-to-video mode (#5559) (8a88157)
- test: remove a class of nondeterministic unit-test failures (#5560) (3827ab8)
- ci: pin the release Xcode in one place; document the bump PR order and approval call (#5558) (bf9713a)
- feat(video): add Pika H3 Flex FL2VA video+audio alias (#5557) (3925fa8)
- ci(main-guard): retry runner-acquisition cancellations instead of alerting (#5555) (ff9655a)
- fix(catalog): qualify VLM aliases offline and pin remaining drafters (#5553) (dc37b6d)
- fix(pr_validate): reap test children on cancel, select guarded MLX tests, hard-fail codex review (#5538) (b232291)
- feat(telemetry): closed causes for failed serve starts (#5550) (d88d7e0)
- ci: run the hosted mac-only selection as one job (#5552) (a333930)
- fix(vlm): require consent for remaining forced-trust processor routes (#5549) (824eb06)
- ci: golden flows and release-toolchain compile on Desktop PRs; longer release CI wait; hosted mac-only tests (#5539) (8d8cbaa)
- fix(cli): smooth download and serve lifecycle UX (#5545) (1c54f9b)
- feat(bench): register fixed-schedule image benchmark protocols (#5548) (9fad16f)
- fix(mac): label community benchmark protocol from its id (#5547) (ecbc88a)
- fix(bench): 1.0.2 benchmark backlog fixes (#5546) (578605e)
- fix(server): isolate step failures and harden MLLM prompt admission (1.0.2 G1) (#5537) (c366775)
- fix(mac): Desktop model, speech, and Share Compute behavior fixes (#5543) (7f1a5b1)
- fix(audio,bench,serve): 1.0.2 audio/video backlog fixes (#5535) (302f655)
- fix(install,upgrade,doctor): close 1.0.2 installer and upgrade-verification gaps (#5536) (b94e299)
- fix(server,pr_validate): idle-release accounting, inherited-fd readiness, GPU lock and cache (#5544) (09fe890)
- fix(mac): complete Simplified Chinese coverage for Desktop UI and VoiceOver (#5540) (e57577f)
- fix(mac): keep the saved chat model across automatic idle release (#5542) (99b01e0)
- test(mac): make Share Compute ledger timing tests deterministic (#5541) (c5943b6)
Install: brew upgrade rapid-mlx or pip install -U rapid-mlx==1.0.2 (or just rapid-mlx upgrade).
Community: https://discord.gg/nZcXkUjY5R