Repository navigation

LocoMuJoCo now includes SuperMimic and supports real-robot deployment on the AgiBot X2 Ultra and the Unitree G1 through LocoMuJoCo Real.
🤖 Highlight: from LocoMuJoCo to the real robot
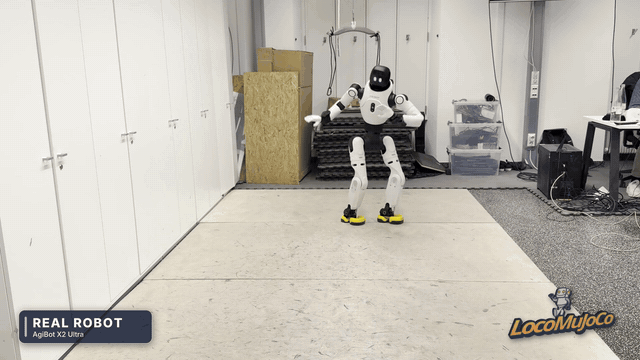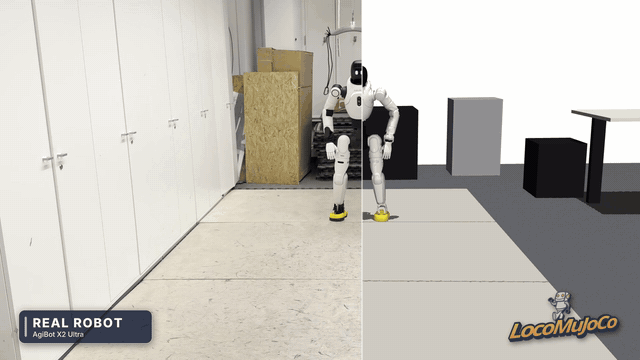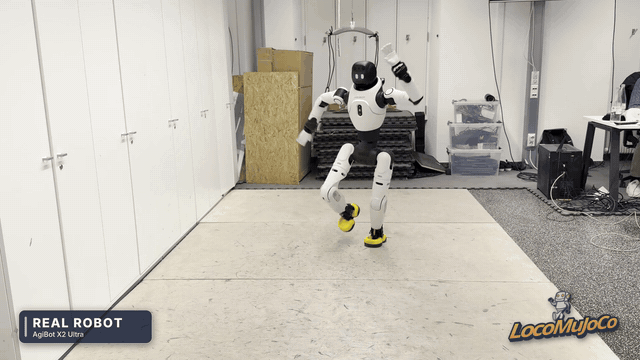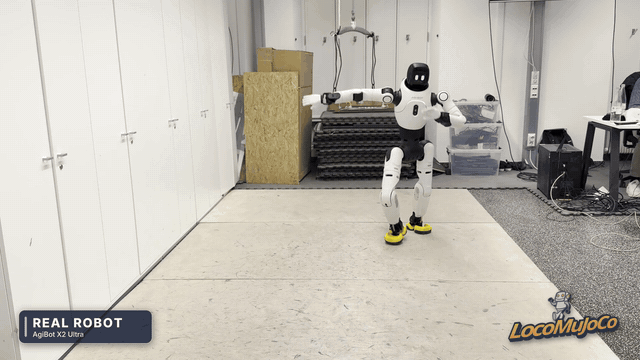
LocoMuJoCo Real is the companion repository for taking policies trained in LocoMuJoCo to a real robot. It covers the Unitree G1 (G1Real) and the AgiBot X2 Ultra (X2UltraReal); both pipelines have been run on the robot.
-
Deployable training setups. For each robot an environment with position servos, the observations the robot can measure, a tracking reward and sim-to-real randomization, with ready-to-run configs for motion tracking with PPO and with SuperMimic:
python training/<robot>/train.py             # PPO
python training/<robot>/train_supermimic.py  # SuperMimic
-
One path from checkpoint to robot, the same for both algorithms. Each stage removes one source of error:
- export the policy to a bundle that runs with only
numpyandmujoco(deployment/export_bundle.py), - validate the bundle against the training environment, term by term (
deployment/validate_bundle.py), - roll it out in plain MuJoCo (
deployment/rollout_mujoco.py), - sim-to-sim over the robot's middleware, Unitree SDK 2 (DDS) for the G1 and AimDK (ROS 2) for the X2 (
deployment/<robot>/sim2sim_bridge.py), driven by the controller that later runs on the robot, - the robot, hanging first (
deployment/g1/deploy_g1.py,deployment/x2/deploy_x2.py).
- export the policy to a bundle that runs with only
-
Motion data. LocoMuJoCo's default clips and LAFAN1 are retargeted to the robot on first use. LocoMuJoCo Real also documents how to load your own trajectories and how to convert and train on BONES-SEED.
The real robot deployment tutorial explains the stages and how to bring up another robot.
Warning
Running a learned policy on a real robot is hazardous. Hang the robot from a crane or gantry, keep the emergency stop in hand, and run every policy in sim-to-sim first.
🚀 SuperMimic
SuperMimicJax(from loco_mujoco.algorithms import SuperMimicJax): whole-body tracking with one differentiable world model, following SuperMimic. A world model is fitted on replayed transitions and the policy is improved by backpropagating through imagined rollouts, with a TD(λ) critic.- Imagination reuses the environment's own JAX observation, reward and termination functions, so the algorithm is agnostic to the robot, the observation and the reward.
- The environment steps run on MJX or on MjWarp (
use_mjwarp=True); under domain randomization the randomizer state is given to the dynamics model and the critic as context. - Training example on the Unitree G1 with
eval.pyand a per-clip evaluatoreval_clips.py, and the API documentation. - New building blocks that came with it: goals
TrajFutureFrames,RootOriRelTrajandTrackingError, and the BeyondMimic-styleSiteTrackingReward, which tracks the mimic sites and so needs no robot-specific body list. - Training runs at about 90 % of the speed of XMimic on the same hardware (Unitree G1, 4096 envs on MjWarp, 40 LAFAN1 clips, one RTX 3090).
Acknowledgements. Our implementation was written with BlinkMimic and XMimic as references. Thanks to their authors for making them available.
⚡ Simulation backends
- MjWarp is no longer flagged experimental; the warning and the 3 s pause on creation are gone.
- Fixed the MjWarp reset: an ended episode now restores every per-world field (before, only
qposandqvelwere reset, which broke tasks without a reference trajectory). - Under MjWarp the per-world index is available as
carry.env_id, so vmapped rewards can attribute the shared contact buffer (contact__worldid) to their own world. naconmaxis forwarded to MjWarp's data; models whose collision pairs the MJX JAX backend does not implement (e.g. the full-collision G1) can be created with MjWarp.- MuJoCo 4 is supported (MjWarp data creation, retargeting welds, viewer camera).
model_contact_conf=dict(self_collisions=False, condim=...)changes the robot's contact setup at construction.examples/speed_test.pyis now a throughput benchmark across MuJoCo, MJX and MjWarp with reduced and full collision models.
⛰️ Terrain
HeightmapTerrain: a static terrain loaded from a height map.npz, aligned with the world frame, for datasets whose clips are placed on the map. Collision through heightfield tiles, boxes or a per-env box pool.FlatTerrainis the new name of the default flat floor.StaticTerrainandDynamicTerrainremain the base classes:FlatTerrainandHeightmapTerrainare static,RoughTerrainis dynamic.HeightScanobservation: terrain heights on a grid around the root, in the root's heading frame.- Terrain overview and API documentation.
- All terrains share one height query (
get_height_at) and a documented lifecycle, and decide where episodes start.recenter_root_xycontrols whether episodes start at the origin or at the xy of the clip. - MjWarp shares heightfield data across worlds, so it now refuses terrains that write a heightfield per env (
RoughTerrain) with an error instead of simulating the wrong terrain. UseHeightmapTerrainthere.
🎞️ Trajectories and datasets
- The trajectory is an argument, not environment state.
ImitationFactory.makereturns(env, traj), andmjx_reset,mjx_step,resetandstepaccepttraj. Trajectories are padded to fixed shapes, so a jitted training function can be called with a different set of clips without recompiling (see Breaking changes). - Trajectory handler registry.
TrajectoryHandlersubclasses register like the other components and are selected withth_params=dict(name=...):RandomStartTrajectoryHandler(default),RandomTrajFixedStepTrajectoryHandlerandFixedStartTrajectoryHandler. The oldrandom_start/fixed_start_confkeys keep working with aDeprecationWarning. - On-the-fly retargeting for new robots. If a default or LAFAN1 clip is not hosted for an environment, it is retargeted from a source environment on first use and cached.
loco-mujoco-retarget-for-new-env --env <Env>does this ahead of time for all clips. - Robot confs can set
joint_limit_solref/joint_limit_solimpfor retargeting. - The
smplextra installssmplxfrom PyPI instead of a fork. GoalTrajMimicandMimicRewardacceptsites_for_mimicandmain_site_name.
📦 Installation and packaging
- LocoMuJoCo is on PyPI:
pip install loco-mujoco. The examples and tutorials are in the repository. - Robot models are downloaded on first use (about 200 MB, cached in
~/.loco-mujoco-caches/robot_models) instead of being a git-URL dependency.loco-mujoco-download-modelsfetches them ahead of time, andLOCOMUJOCO_ROBOT_MODELS_PATHpoints to a local copy for machines without network access. - JAX is pinned to
jax<=0.10.1,!=0.10.0: JAX 0.10.0 and 0.10.2 fail to compile SuperMimic's training function on the GPU. - Only the
loco_mujocopackage is installed;docsandscriptsno longer end up as top-level packages. - New extras:
viser,usd,blender,test.requests,httpx,richandfilelockare declared. - New CLI:
loco-mujoco-show-variable(--nameor--all).
🖥️ Rendering
- Browser rendering with viser:
env.render_viser(),env.mjx_render_viser(state)andplay_trajectory(viser=True)serve the scene to a browser, which helps over SSH and on machines without a display (pip install -e ".[viser]"). - USD export:
env.render_usd(),env.mjx_render_usd(state)andplay_trajectory(usd=True)write an animated USD stage (pip install -e ".[usd]");scripts/blenderrenders it with Blender. - Rendering tutorial, tutorials
12_viser_rendering.pyand13_viser_rendering_mjx.py. - The observation summary is printed in the terminal when an environment is created (
print_obs_summary=Falseturns it off).create_observation_summarywrites a local HTML file instead of uploading it.
🧠 Algorithms
init_agent_stateseparates network initialization from training, and onebuild_train_fncovers fresh runs and resuming, so training can run in chunks (examples/training_examples/jax_rl_mimic/experiment_resume.py).- Reward normalization statistics moved from an environment wrapper into the agent state, so they are saved with the agent.
- Multi-GPU PPO: with
experiment.n_devicesthe training function runs underjax.pmapand averages the gradients across devices.training/ppo.pyin LocoMuJoCo Real is the reference driver. - Observation history can be limited to one group (
NStepWrapper(group=...),obs_history_group), so the critic is not stacked;get_obs_ind_by_groupaccepts a list of groups. - New in
loco_mujoco.algorithms.experimental:S2PGPPOJax,BPTTPPOJax,HistoryPPOJax,SACJax,TD3JaxandVanillaDaggerJax(DAgger distillation), each with a training example.
📚 Documentation and tests
- New tutorials: Adding a New Robot, Real Robot Deployment and Rendering in the Browser and Exporting to USD.
- The API documentation now covers SuperMimic, and the terrain page starts with an overview of the terrains.
- A much larger test suite. CI also runs on pull requests into
masteranddev, installs the optional extras and reports coverage. - Fixes found on the way: the
Forceobservation,mat2angle_xy/angle2mat_xy, muscle peak-force scaling of the skeleton models,randomize_link_mass=False, forward kinematics after the initial-state handler, a viewer crash when the window is closed, and thetorch_deviceargument of the SMPL motion transfer.
⚠️ Breaking changes and migration
| v1.1.0 | v1.2.0 |
|---|---|
env = ImitationFactory.make(...), env = RLFactory.make(...) |
env, traj = ImitationFactory.make(...); RLFactory.make returns (env, None) |
from loco_mujoco.trajectory import ... |
from loco_mujoco.core.trajectory import ... |
env.load_trajectory(traj) |
traj = env.process_trajectory(traj) |
TrajectoryHandler(model, traj=..., control_dt=...), env.th.traj |
the handler holds only the TrajectoryInfo; use the trajectory returned by the factory or by process_trajectory, and TrajectoryHandler.process(traj, model, dt) to fit a trajectory to a model |
train_fn = PPOJax.build_train_fn(env, agent_conf); train_fn(rng) |
agent_state = PPOJax.init_agent_state(env, agent_conf, rng); train_fn(rng, agent_state, traj) (same for GAIL and AMP). With several seeds: jax.vmap(train_fn, in_axes=(0, 0, None)) |
PPOJax.play_policy(env, agent_conf, agent_state, ...) |
add traj=traj for imitation tasks |
NormalizeVecReward, NormalizeVecRewEnvState wrappers |
removed; the algorithms normalize the reward themselves |
th_params=dict(random_start=False, fixed_start_conf=(0, 0)) |
still works, deprecated; use th_params=dict(name="FixedStartTrajectoryHandler", start_conf=(0, 0)) |
LOCOMUJOCO_CUSTOM_SMPL_CONF_PATH |
LOCOMUJOCO_CUSTOM_ROBOT_CONF_PATH (set it again with loco-mujoco-add-variable) |
DefaultDatasetConf(dataset_type="pretrained") |
removed, only "mocap" exists; anything else raises a ValueError |
create_observation_summary() returns a URL |
returns the path of a local HTML file |
env.mjx_reset(key)andenv.mjx_step(state, action)still work withouttrajand then use the trajectory the environment was created with. Passtraj(jax.vmap(env.mjx_reset, in_axes=(0, None))) to be able to swap it.- Dependencies:
jax<=0.10.1,!=0.10.0(GPU:pip install "jax[cuda12]<=0.10.1,!=0.10.0"). Theloco-mujoco-modelsgit dependency is gone; the models are fetched on first use, so offline machines needloco-mujoco-download-modelsbeforehand orLOCOMUJOCO_ROBOT_MODELS_PATH. - Python: unchanged, 3.10 or newer.
- MjWarp with
RoughTerrainnow raises an error at construction. - The default
terrain_typeis"FlatTerrain"instead of"StaticTerrain". Both give the same flat floor, andterrain_type="StaticTerrain"keeps working. - Removed: the console scripts
loco-mujoco-download,-download-realand-download-perfect(they pointed at functions that did not exist), and the unusedCollisionExtender,optimize_for_collisionsandMANO_Parser. - Environments print their observation summary on creation; pass
print_obs_summary=Falseto keep logs quiet.
🙏 Contributors
Thanks to @mdrolet01 for the trajectory handler registry, the handler's backend handling and the quadruped init-state fix (#92, #95, #96).
Full changelog: v1.1.0...v1.2.0
