Repository navigation
Explorer and results
Current 18-model catalogue and internal tests. The internal procurement view supports sorting, filters, source/output inspection and a request ledger. Counts use assigned tasks, missing values stay distinct from zero, and contested-label sensitivity remains separate from the primary analysis. No PBI is assigned.
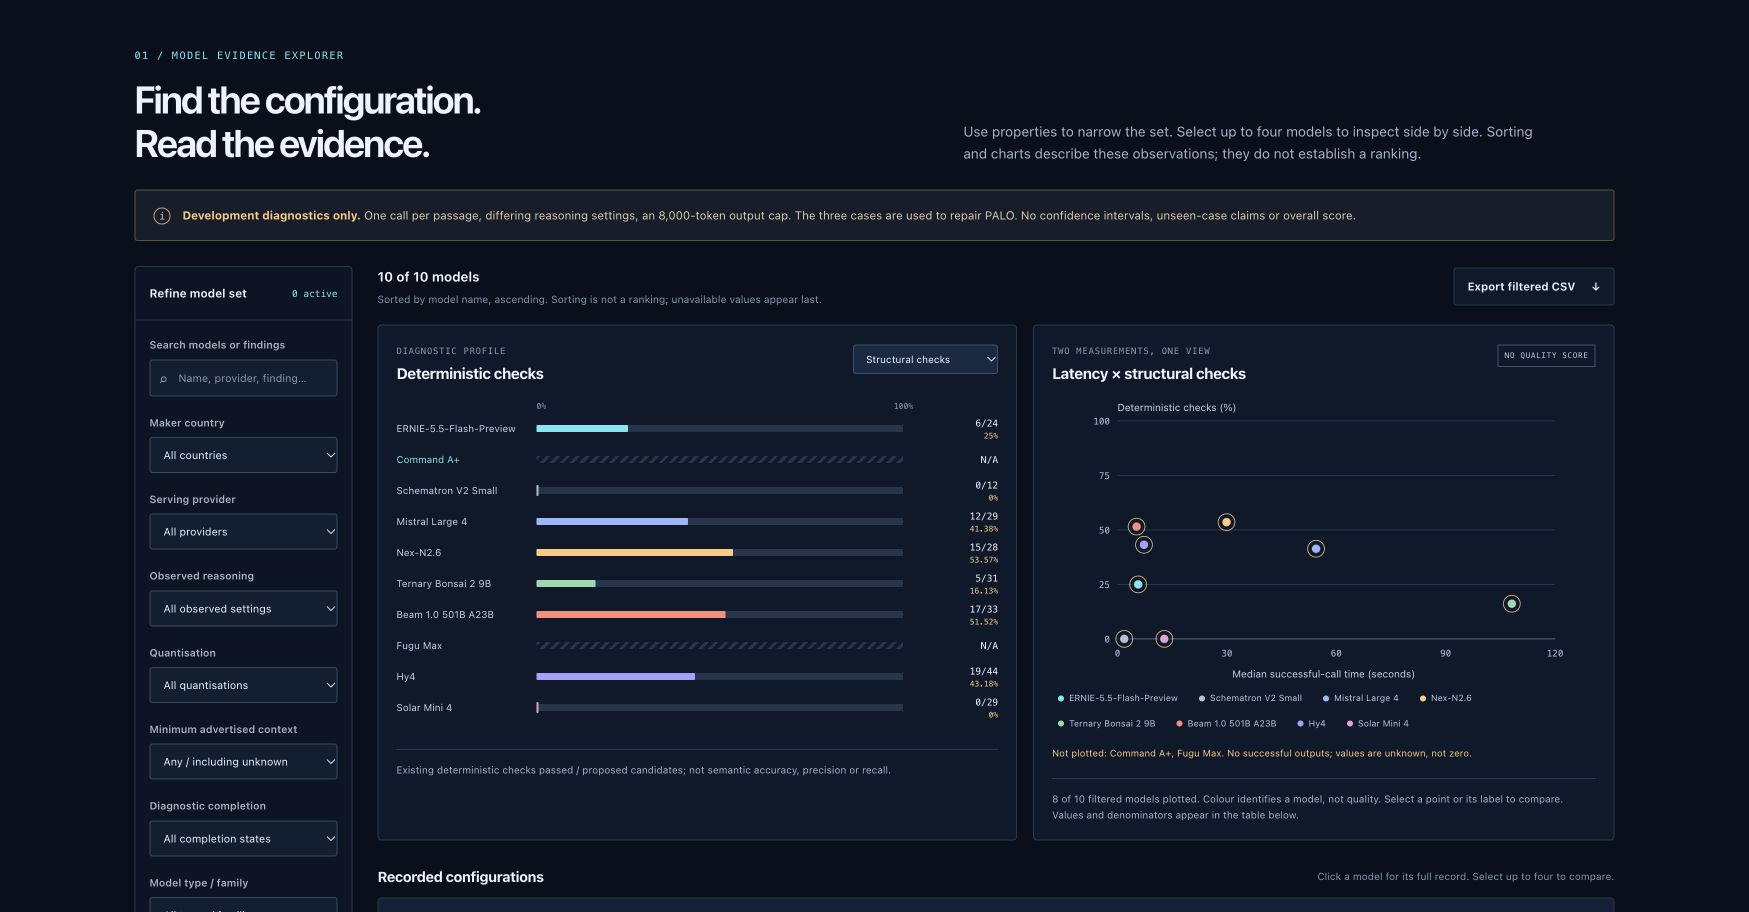
Actual retained capture; current wording and configuration disclosures have since been updated. It illustrates development diagnostics, not a qualified leaderboard.
Filter by model text, maker country, serving provider, observed reasoning, quantisation, advertised context, completion and family. Select up to four configurations for comparison. Export the filtered CSV to inspect the disclosed configuration fields and notes.
- Structural checks count accepted candidates under the retained deterministic checker. They are not semantic precision or recall.
- Latency summarises successful calls; completed/attempted counts disclose the denominator. Failed calls are not assigned artificial zero latency.
- Unknown charge values are separate from unresolved reservations and reported charges. These are not invoice-reconciled enterprise totals.
- Advertised context is not used context. Maker country does not establish data residency.
- Settings differ across the ten historical configurations. Sorting is not a scientifically supported rank.
The published set contains 26 retained attempts and no qualified held-out result. The model-output archive is inspectable and its structural counts can be replayed offline. That replay does not rerun models or supply independent semantic gold.
Diagnostic data | Reproducing results | Metrics
The review panel exposes 96/108 assigned judgments from GLM, Gemini and local Qwen over 36 selected items. Three items have observed disagreements. Missing GLM responses, Qwen array projection, source references and raw responses are retained. This purposive internal test does not change the primary scores or establish independent validation. Protocol and evidence.
Numerical quality, completion, cost and time ranks are suspended. The explorer retains descriptive sorting, configuration filters, charts, comparison and CSV/JSON exports. Agreement on classified responses, coverage and matches across all assigned opportunities are separate measures. The near-ceiling synthetic pilot cannot establish model superiority. Reviewer capture diagnostics are separate from model results.
Next-cycle case coverage and label adjudication describes draft development cases and human review gates. Coverage completeness is not statistical sufficiency.