Repository navigation
Releases
Ragbot 4.0.1

Retrieval helpers work again with every provider, and reranking orders results
by the model's judgment.
Fixed
- Query planning, expansion, HyDE, reranking and verification call the
bulk-tier model through the configured LLM backend at the least reasoning it
allows: thinking off for local models, the lowest declared effort for cloud
models. The helper used to call LiteLLM directly. That way:- A local Gemma 4 12B, which thinks by default, spent the reranker's whole
500-token budget reasoning and returned nothing, so reranking never ran. - Claude Haiku 5.5 and GPT-6 Luna rejected its fixed
temperature=0.3, so
every helper silently fell back for Anthropic and OpenAI chats. - API keys were looked up under the environment-variable name, which the
keystore does not use, so keys in~/.synthesis/keys.yamlnever reached
these calls.
The output budget now comes from the model'sdefault_max_tokens, and a
failed helper call logs the model and the cause.
- A local Gemma 4 12B, which thinks by default, spent the reranker's whole
- Reranking orders results by the LLM's judgment. Retrieval scores differ in
scale by source: cosine similarity for vector hits, a full-text rank that can
exceed 8 for keyword hits, and an RRF score near 0.03 for fused hits. Mixing a
raw score with the 0-10 judgment let keyword hits the model scored 0 outrank
the chunk it scored 10. On a personal workspace this buried the one relevant
note at eighth place, and the chat answered that it had no record. Now:- Retrieval strength is scaled to 0-1 before the mix.
- Results past the top 20 follow in retrieval order instead of re-sorting
above the reranked ones on raw scores. - A skipped rerank keeps the retrieval order.
- The context labels each chunk with the combined 0-1 score instead of its raw
score.
- Hybrid search fuses with RRF whenever either list has hits. It used to
return raw scores when one list was empty or keyword search failed, and those
outranked every RRF score in the shared sort. The HyDE boost now applies to the
key results are sorted by. thinking_effort: offswitches thinking off for local models. It used to
send no parameter, which left a model that thinks by default thinking. It now
sendsreasoning_effort: none, which LiteLLM passes to Ollama as
think: false.- Gemma 4 entries in
engines.yamldeclare their hybrid thinking. Ollama
reports the capability for all four. 12B, 26B and 31B think by default; E4B
does not. The 31B flagship now defaults to medium effort, as other local
flagships with thinking do.
Ragbot 4.0.0
Ragbot moves every dependency, runtime and model to its latest release. Backward
compatibility with superseded models, runtimes and SDK versions is not kept.
Changed
-
Models.
engines.yamlcarries only current models, verified against provider
documentation on 2026-11-06 (docs/model-catalog-2026-11-06.yaml):- OpenAI: GPT-6 Astra, GPT-6.1 Sol (default), GPT-6.1 Terra, GPT-6 Luna.
- Anthropic: Claude Fable 5.1, Opus 5.5, Sonnet 5.5 (default), Haiku 5.5.
- Google: Gemini 4 Argon, 3.8 Flash (default), 3.5 Flash-Lite.
- Local (Ollama): Gemma 4 (E4B, 12B, 26B, 31B), Qwen3.8 27B, the Qwen3.8 Flash-Next
preview, Muse Glimmer 30B, Nemotron 3.5 Super, Mistral Medium 3.5.
Every cloud model has a strict request contract. Superseded models are removed,
includinggemini-3.1-flash-lite-preview, which Google shut down on 2026-05-25, and
three local tags Ollama no longer serves locally. -
Embedding model. RAG embeds with Microsoft's
harrier-oss-v1-0.6b(MIT licence,
1,024 dimensions, 32K-token context) in place of all-MiniLM-L6-v2 (384 dimensions,
256 tokens).engines.yaml'sembedding:block is now the only place the model is set,
with a pinned Hugging Face revision; theEMBEDDING_MODELenvironment override is gone.- Queries carry the model's retrieval instruction (
web_search_query); documents carry
none. - Indexing embeds chunks in batches instead of one model call per chunk.
- Migration
0004_embedding_dimensions.sqlmoves both vector columns to 1,024
dimensions. It clears the chunk index and entity embeddings (entities are kept), so
every workspace needsragbot index --workspace <name> --forceafter upgrading. - The vector store reads its schema dimension and refuses to index or search with
vectors of another size;ragbot db initandragbot db statusreport it. - The API container keeps downloaded models in a
ragbot-hf-cachevolume. - The model needs about 4.2 GB while loading in float32. Docker Desktop's default 4 GB
is not enough; allow it at least 8 GB.
- Queries carry the model's retrieval instruction (
-
MCP SDK 2.x (#157). The client primitives, tasks, transports, OAuth callback, proxy
and Ragbot's MCP server are ported to mcp 2.3.0. -
Runtimes and images.
- Python 3.14 in CI and the backend image, which no longer installs a compiler.
- The backend image installs CPU-only torch from PyTorch's index. PyPI's Linux wheels are
the CUDA builds, which added 4.2 GB of GPU libraries to an image with no GPU to use;
the build now also runspip check. - Node 26 (active LTS) in CI and the web image.
- PostgreSQL 18 with pgvector 0.8.7 on a new volume;
scripts/migrate-postgres-16-to-18.shcopies an existing database across. - Jaeger v2.
-
Python packages. Every floor is raised to the latest release; openai 3.x is allowed now
that LiteLLM 1.108+ accepts it;google-generativeai(end of life) is removed, freeing
protobuf 7;appdirsis replaced byplatformdirs. -
Web packages. Every package is on its latest release (Next.js 16.4.5, React 19.3.1,
jsdom 31). TypeScript stays on 6.0 because typescript-eslint does not yet accept 7. -
Request handling.
- Anthropic requests never carry sampling parameters, and effort travels in
output_config. - Gemini thinking is set by level, never by budget.
- OpenAI requests use
max_completion_tokens.
The Claude version heuristics for superseded models are gone.
- Anthropic requests never carry sampling parameters, and effort travels in
-
Defaults come from
engines.yaml. The chat API default, the memory consolidator, cross-workspace synthesis and the eval runner no longer name models in code.
Fixed
- A reasoning model that spent its whole output budget thinking returned an empty reply with
no error. Every backend now raisesOutputBudgetExhaustedError, which names the budget
and says to raisemax_tokensor lower the thinking effort; a partial reply is still
returned. - A streamed chat that failed simply ended: the streaming thread dropped its exception.
chat_streamnow re-raises it asChatError, which the web UI shows. local_onlyand downgrade-to-local workspace policies recognised no configured local
model and suggested models that did not exist. Local models are now thoseengines.yaml
serves through Ollama, and Ollama:cloudtags are never treated as local.- The agent loop read an attribute mcp 2.x no longer has, which would have passed MCP tool
errors through as successful output. - The MCP server's HTTP transport resolves bearer tokens from the request it serves,
starts its session manager through the ASGI lifespan, and fails closed. - The OAuth callback page escaped nothing in its error message.
npm auditreports 0 vulnerabilities, down from 22 (1 critical), and CI now runs
next build.
Security
- Next.js advisories covering 16.0.0–16.4.0 (two unauthenticated remote code execution
issues among them) are resolved. Transitive advisories (sharp, brace-expansion,
minimatch, postcss-selector-parser, vite, zod, undici) are cleared by overrides and
lockfile updates. - 13 CVEs in
filelock3.32.7 are resolved:filelock4.2.9 installs. Every stable
LiteLLM release from 1.104.0 through 1.108.1 caps it below 4, so the LiteLLM floor is
the 1.109.0 release candidate, the first that accepts it; pip moves to 1.109.0 on its
own once that ships.pip-auditreports no known vulnerabilities. See
docs/security/dependabot-triage-2026-11.md.
Ragbot 3.8.1
Release3.8.1 refreshes the verified model catalog and model-specific thinking controls. Final provider request validation prevents extension bodies from overriding explicit model, effort or output limits; reasoning registration preserves unrelated prices and input allowances. Python CI, independent SDK/trimmer controls, web checks and the production build passed. No provider availability or inference-quality claim is implied.
v3.8.0: multi-org billing, CI, dependency refresh
Ragbot v3.5.0 — substrate cleanup
v3.5.0 — 2026-05-15
Substrate cleanup. Pgvector is the only vector backend, the agent loop
wires at startup, OTLP metric and trace export are independently
configurable, app loggers surface under uvicorn, and the regression
suite no longer fails on dev machines without heavy ML dependencies.
Breaking change: RAGBOT_VECTOR_BACKEND=qdrant and the bundled Qdrant
backend are removed. Operators who ran v3.4 with the Qdrant opt-in
must reindex their workspaces into pgvector before upgrading.
Removed
- Qdrant vector backend. Deleted
synthesis_engine.vectorstore.QdrantBackend,
the embeddedqdrant_data/storage path, theqdrant-clientdependency,
theRAGBOT_VECTOR_BACKENDenvironment variable, and theragbot-qdrant
Docker volume. Dead_qdrant_client/_get_qdrant_client/
get_qdrant_point_idhelpers inrag.pyandchunking/removed.
TheVectorStoreABC atsynthesis_engine.vectorstoreis retained so
substrate consumers outside Ragbot can plug in alternative backends
behind the same contract.
Changed
- Agent loop wires at startup. The FastAPI lifespan now constructs an
AgentLoopwith the lifespan's LLM backend, the resolved MCP client, and
aFilesystemCheckpointStore, then calls
api.routers.agent.set_default_loop()to register the singleton. The
/api/agent/runendpoint resolves against a real loop on a fresh install
— through v3.4 it returned"Agent loop is not configured". Shutdown
clears the singleton. - OTLP metric export is independently configurable. The substrate now
honours the OTEL standard per-signal env-var hierarchy:
OTEL_EXPORTER_OTLP_METRICS_ENDPOINT(per-signal override; accepts the
literal"none"to disable metric OTLP export) falls back to
OTEL_EXPORTER_OTLP_ENDPOINT. The bundled docker-compose stack sets the
metrics endpoint to"none"because Jaeger only accepts traces — the
UNIMPLEMENTEDerrors from earlier deployments are gone. Prometheus
exposition at/api/metricsis unaffected. - App loggers surface under uvicorn.
src/api/main.pycalls
logging.basicConfigat module-import time before uvicorn takes over,
soapi.main,api.routers.*, andsynthesis_engine.*log lines now
flow todocker logs ragbot-apialongside uvicorn's own access logs.
Override the level withRAGBOT_LOG_LEVEL. get_vector_store()returnsNonewhen pgvector is unreachable
instead of falling back through a backend chain. Callers inrag.py
treatNoneas "RAG unavailable; chat-only mode," so the user-facing
failure mode is graceful.
Fixed
/api/agent/runreturns 503 "not configured" — fixed by the agent
loop wiring change above.- OTLP metric export prints
UNIMPLEMENTED— fixed by the per-signal
endpoint split. - App-namespace logger lines invisible in container logs — fixed by
logging.basicConfiginsrc/api/main.py. test_sentence_transformers_imports_cleanlyfails on dev machines
without sentence_transformers installed — wrapped both Bug5
regression tests inpytest.importorskip("sentence_transformers")so
they skip cleanly on lightweight dev installs and still run in Docker /
CI where the dependency is present.
Test-suite delta
- v3.4.0 baseline: 871 passing, 25 skipped, 4 failing (3 Qdrant tests + 1
sentence_transformers env gap). - v3.5.0: 850 passing, 14 skipped, 0 failing (Qdrant tests gone with the
backend; sentence_transformers tests skip cleanly).
Ragbot v3.4.0 — agent loop, first-class MCP, skills runtime, cross-workspace synthesis
title: "Ragbot v3.4.0 — Ragbot becomes the conversational reference runtime of synthesis engineering"
slug: ragbot-v3-4-0
date: 2026-05-14
canonical_url: https://synthesisengineering.org/posts/2026/05/14/ragbot-v3-4-0/
categories:
- synthesis-engineering
- ragbot
- releases
tags: - ragbot
- mcp
- skills
- agent-loop
- synthesis-engineering
author: Rajiv Pant
Ragbot v3.4.0 — Ragbot becomes the conversational reference runtime of synthesis engineering
Ragbot v3.4 is the next-major-features release. It moves the project from a
polished 2024-paradigm chat-with-RAG product to a 2026-shaped conversational
AI runtime: explicit agent loop, first-class MCP in both directions, an
executable skills runtime, cross-workspace synthesis with visible
confidentiality boundaries, durable memory beyond vector RAG, and the
production-grade signals that make the architecture legible to engineering
leadership.
The synthesis-engineering positioning that the architecture had quietly
named for a year is now visible in the README, the ragbot.ai homepage, and
the in-product chrome. Ragbot is the reference runtime for the
conversational interaction primitive inside synthesis engineering, with
sibling reference implementations covering direct manipulation
(synthesis-console),
procedural execution
(Ragenie), and the
portable capability format
(synthesis-skills).
The family will grow as the methodology and the AI landscape evolve.
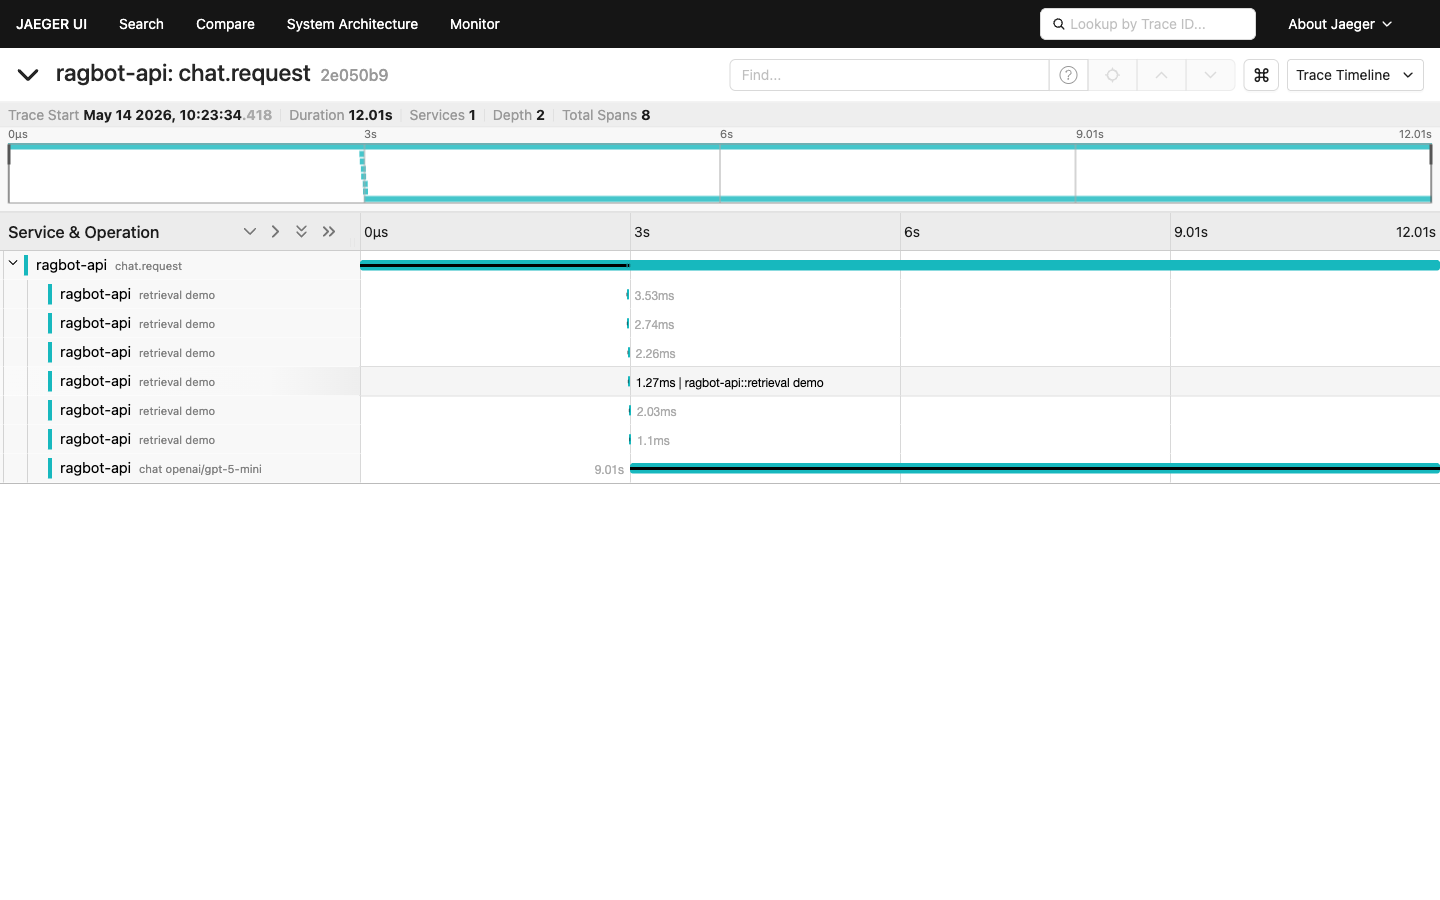
The architectural rationale behind v3.4 — the synthesis-ecosystem
framing, the HCI-primitives map, the deterministic-enforcement thesis —
will be published as a blog series at
synthesisengineering.org and
synthesiscoding.org following this
release.
Why this release matters
The 2026 center of gravity for chat-with-tools products has shifted from
"chat with retrieval" to stateful, tool-using agents with durable memory,
governed execution, and async background work. MCP is industry-default
infrastructure at 97M monthly SDK downloads and 5,800+ public servers.
SKILL.md is a cross-vendor standard adopted by Codex CLI, Gemini CLI, GitHub
Copilot, and Cursor. Memory has three layers in production. Observability
is a buying criterion, not polish. Local inference crossed the credibility
threshold with the Ollama 0.19 MLX backend on Apple Silicon.
Ragbot v3.3 was a polished 2024-paradigm product. It read clean. It worked
well. It did not look like a 2026 product to anyone who had seen the new
shape of the category. v3.4 closes that gap. Every architectural commitment
v3.4 ships traces back to a concrete shift in the category, not to feature
preference.
The 1.6%/98.4% ratio from VILA-Lab's Dive into Claude Code analysis
(source) is the design
instruction. AI decision logic is the small slice. Deterministic
infrastructure — permission gates, context management pipelines, tool
routing, recovery mechanisms — is the rest. v3.4 builds that
infrastructure for the conversational primitive.
Headliner 1: Agent loop runtime
Ragbot is now an execution surface, not just a chat surface. A hand-rolled
graph-state agent loop replaces the single-turn prompt → retrieve → call LLM → return path. The agent can decide between answering directly,
dispatching retrieval, calling a tool, running a skill, or fanning out to
sub-agents.
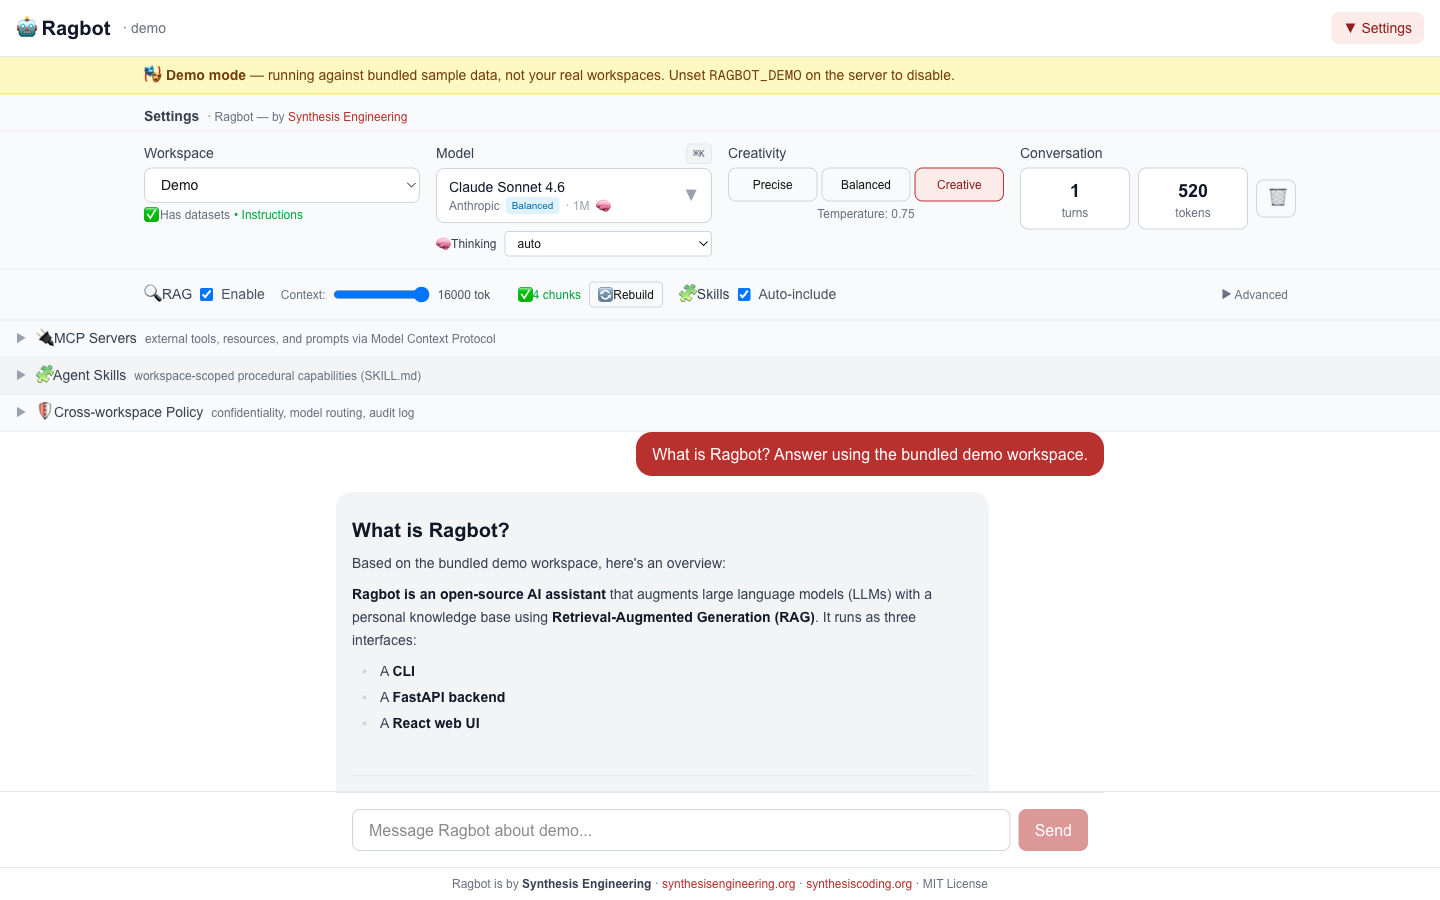
The loop is hand-rolled — no LangGraph, no CrewAI, no AutoGen. Use what
those frameworks teach; do not depend on them. The Plan-and-Execute pattern
is the default for compound questions with explicit replanning on failure.
The lead-agent-with-sub-agents pattern handles parallel research across
workspaces. Sandboxed code execution runs through E2B microVM or
self-hosted Daytona Docker for air-gapped installations; the disabled
sandbox fails closed with an actionable error rather than dropping into a
plain subprocess.
Permission gates fail closed at the tool boundary. The default behavior
denies any tool that does not match a read-only pattern or have an
explicit gate. The 98:2 ratio is enforced literally — most of the work is
the deterministic plumbing. State checkpoints are durable and replayable
through the ragbot agent replay command.
The chat-only no-tools mode remains available. The agent loop is opt-in
per session via the picker toggle or agent=true on /api/chat. Test
coverage gates the rollout: 45 tests across the agent loop core and the
agent capabilities surface (sub-agent dispatcher, sandbox, self-grader).
The {"$ref": "step_id.field"} placeholder syntax in plan-step inputs
lets a multi-step plan thread outputs without a separate scratchpad. The
self-grading loop ("Outcomes" pattern borrowed from Anthropic's
Code w/ Claude 2026 talks) lets the agent score its own output against a
written rubric and iterate.
Headliner 2: First-class MCP — client and server
Ragbot is now both an MCP client and an MCP server.
As a client, Ragbot covers all six MCP primitives — tools, resources,
prompts, Roots, Sampling, and Elicitation — plus MCP Tasks for
long-running calls. Most "MCP-supporting" chat products only implement
tools; doing all six is the engineering-judgment signal. OAuth 2.1 with
Dynamic Client Registration is supported for remote servers, with a
stdio + HTTP/SSE proxy so local stdio-default servers work without
leaking complexity into the user's setup.
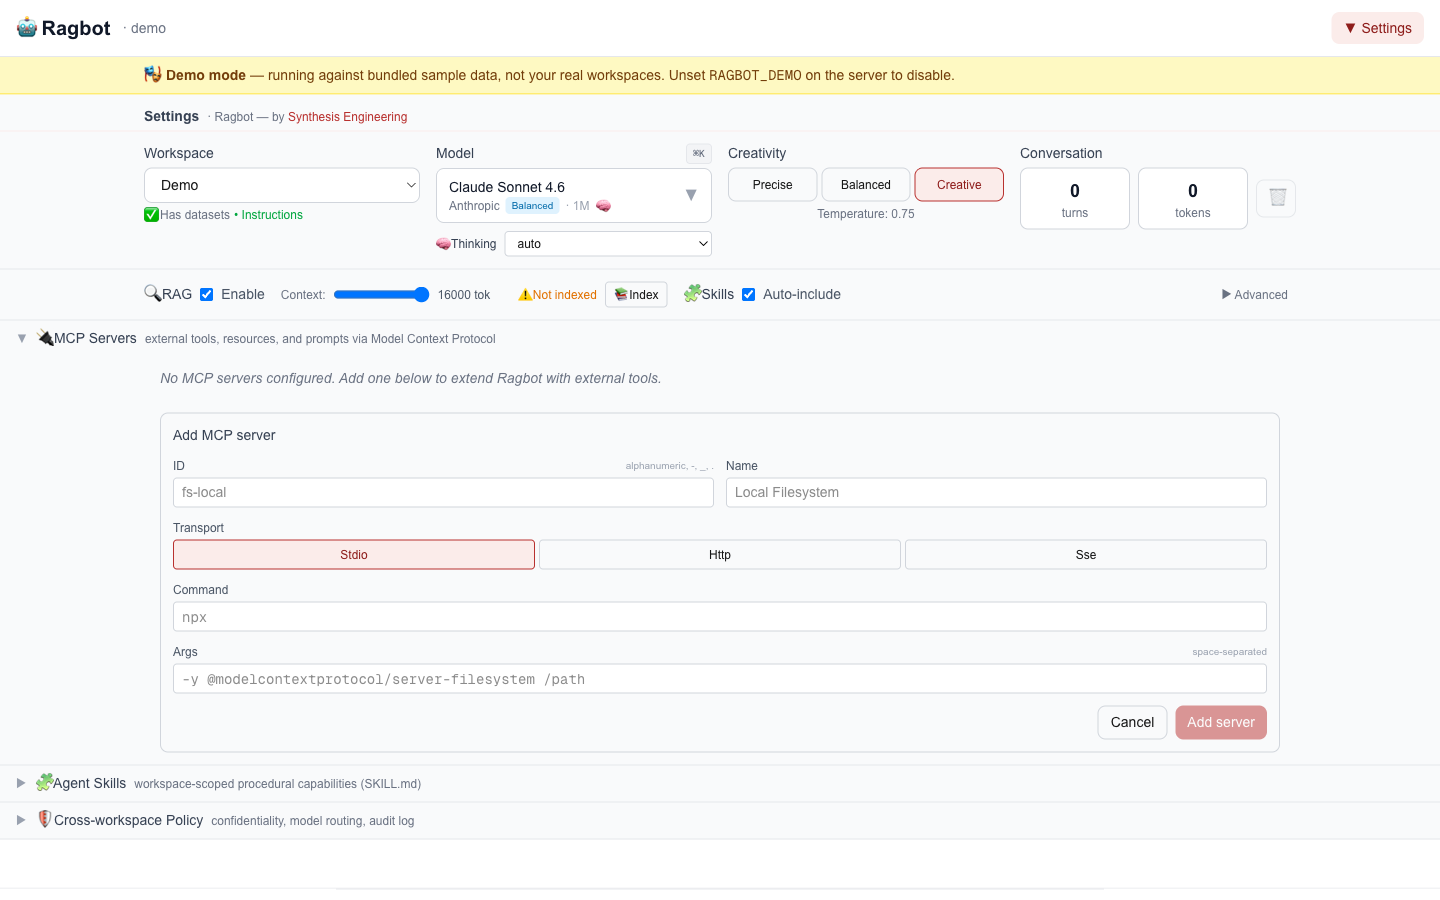
The MCP settings panel lists configured MCP servers, their connection
state, and the tools and resources they expose. Per-server toggles. Per
workspace allow/deny rules. The configured server list lives at
~/.synthesis/mcp-clients.yaml.
As a server, Ragbot exposes its workspace surface to other MCP-aware
agents — Claude Code, Cursor, ChatGPT desktop, Gemini CLI, and any other
client that speaks the protocol. Two transports: stdio for desktop
integrations, HTTP/SSE via StreamableHTTPSessionManager for network
clients. Bearer-token auth via ~/.synthesis/mcp-server.yaml with
per-token allowed_tools glob filtering.
Five exposed tools:
workspace_search(workspace, query, k)— vector + FTS search inside a
single workspace.workspace_search_multi(workspaces, query, k, budget_tokens)—
multi-workspace search with the confidentiality gate firing before
retrieval, so denied workspace combinations never read content.document_get(workspace, document_id)— retrieve a single document.skill_run(skill_name, inputs)— execute a discovered skill.agent_run_start(prompt, workspaces, ...)— start an agent run, return
a task ID. Pair with the existing agent endpoints for status/replay.
Three exposed resources: ragbot://workspaces, ragbot://skills,
ragbot://audit/recent.
Headliner 3: Skills as runtime
In v3.3, Ragbot read skills as markdown and indexed them for RAG. v3.4
makes skills executable in the progressive-disclosure model: names
and descriptions in the system prompt, full body on selection, scripts
and templates on tool call.
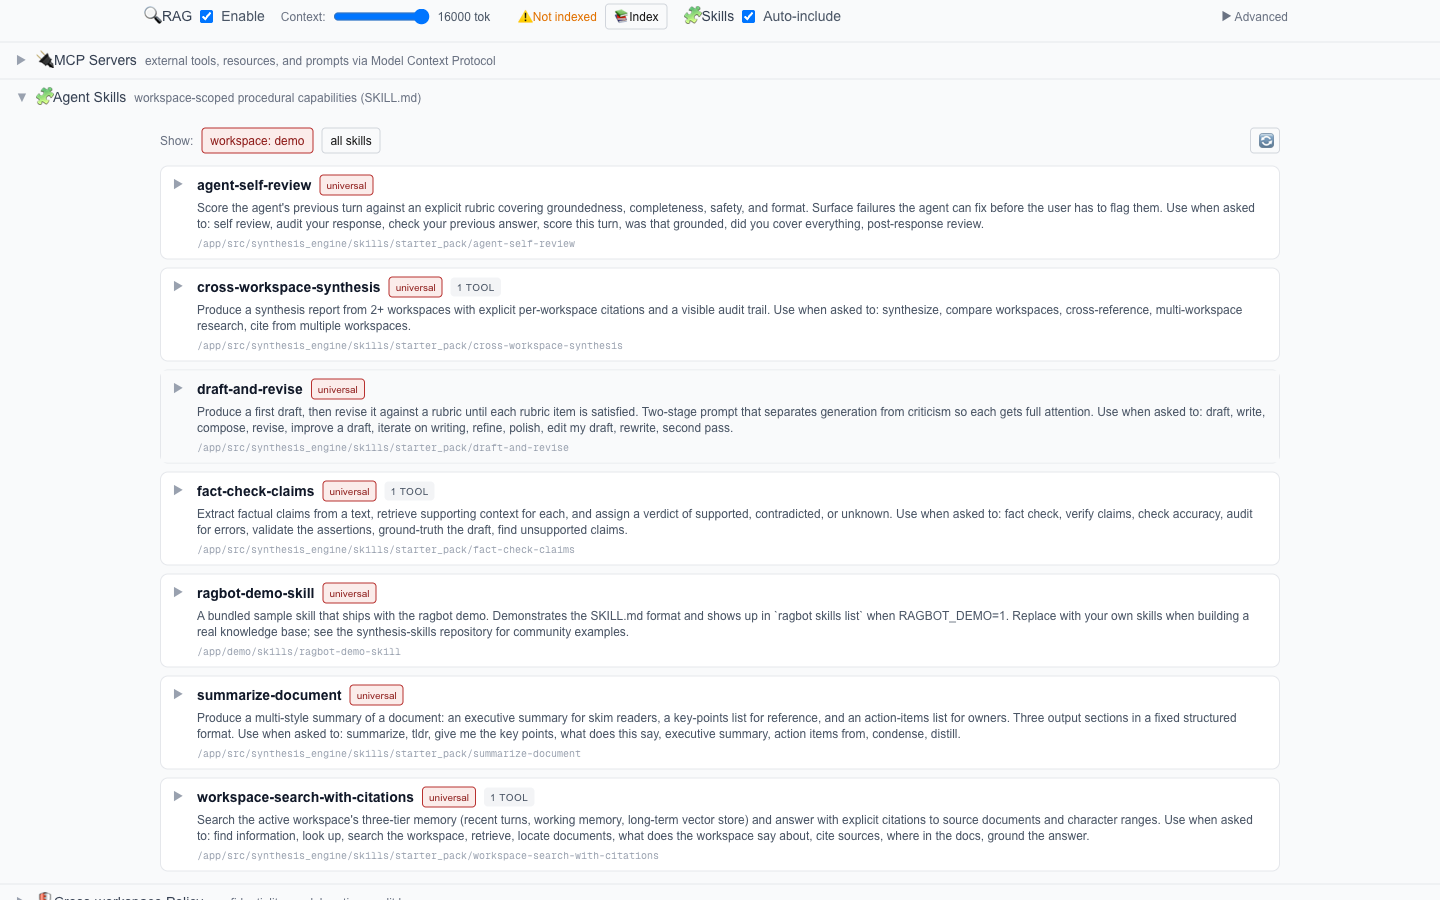
SKILL.md is now Ragbot's native extensibility format. A skill written
for Claude Code, Codex CLI, Cursor, or Gemini CLI runs on Ragbot without
modification. This makes Ragbot the third compatible runtime for the
SKILL.md format (after Claude Code and Codex CLI), which is the kind of
cheap-cost interoperability signal that compounds.
Six starter skills ship in the box:
workspace-search-with-citations— search the active workspace and
return results with[workspace:document_id]citations.draft-and-revise— multi-turn drafting with explicit revision passes.fact-check-claims— verify claims against the workspace and surface
uncertainty honestly.summarize-document— structured summarization with citation
retention.agent-self-review— the self-grading skill that powers the
"Outcomes" pattern.cross-workspace-synthesis— the brand-defining skill (described in
Headliner 5 below).
The npx skills add synthesisengineering/synthesis-skills install path
turns the 32 public synthesis-skills into runnable capabilities. Skills
discovery walks five roots in priority order:
synthesis_engine/skills/starter_pack/ (built-in),
~/.synthesis/skills/ (synthesis-engineering shared install),
~/.claude/skills/ (Claude Code private skills),
~/.claude/plugins/cache/<vendor>/skills/ (plugin-installed), and
per-workspace skill roots declared in compile-config.yaml. Later wins
on name collision, so operator-installed skills override built-ins.
CLI: ragbot skills list/info/run. REST: /api/skills with
?workspace=W filtering. UI: skills panel with one-click execution and
structured output rendering.
Headliner 4: Synthesis ecosystem positioning and rebrand
Ragbot is officially the reference runtime for the co...
v3.3.0 — Local Gemma support + redesigned model picker
Highlights
- Local model support via Ollama. New
ollamaengine adds Google's Gemma 4 family (E4B, 26B MoE, 31B Dense) as first-class models alongside the cloud providers. LiteLLM routes via theollama_chat/prefix. Docker stack reaches host Ollama viahost.docker.internal:11434out of the box (configurable withOLLAMA_API_BASE). - Model picker redesign. A single rich dropdown replaces the three-step Provider → Category → Model cascade. Display names ("Claude Opus 4.7" instead of
claude-opus-4-7). Pinned and Recent sections at the top. Type-ahead search.⌘K/Ctrl+Kglobal shortcut. Per-row badges for tier (Fast / Balanced / Powerful), context window, 🧠 thinking, 🏠 local. Pin/unpin persisted server-side. - User preferences API. New
/api/preferences/pinned-models(GET / PUT) and/api/preferences/recent-models(GET / POST). Pinned and recently-used model selections persist across sessions in~/.synthesis/ragbot.yaml. - Thinking control moves adjacent to Model. Renders inline below the picker, only for thinking-capable models.
- Security. LiteLLM pinned
>=1.83.0in requirements (excludes the compromised 1.82.7/1.82.8 range from the March 2026 supply-chain incident).
What's new
Local models
engines.yamlships a fourth engine block,ollama, withgemma4:e4b,gemma4:26b,gemma4:31b. No API key required.is_local: trueflag on local-provider models and providers, surfaced in/api/models/*so UIs can render the 🏠 badge and skip API-key plumbing.- Optional
OLLAMA_API_BASEenv var if you want to point the API container at a LAN-shared Ollama instance instead ofhost.docker.internal.
Model metadata
display_name,supports_thinking, andis_localadded to model responses in/api/modelsand/api/models/all.engines.yamlnow supports adisplay_namefield per model. Falls back to the canonicalnameif omitted._normalize_model_id→normalize_model_id(public), now idempotent for user-supplied prefixed IDs.
Preferences API
| Endpoint | Behaviour |
|---|---|
GET /api/preferences/pinned-models |
Returns current pinned model IDs |
PUT /api/preferences/pinned-models |
Replace the pinned list (deduped, order preserved) |
GET /api/preferences/recent-models |
Newest first, capped at 10 |
POST /api/preferences/recent-models |
Record one model use (move-to-front + cap) |
Persisted via the new keystore.set_user_config / _save_user_config write path; reads continue to work via the existing ~/.synthesis → ~/.config/ragbot fallback.
UI
- Trigger button shows the selected model's display name + provider name + tier badge + context + 🧠/🏠 icons.
- Open: search bar (autofocus) + Pinned + Recent + by-provider sections. Unavailable rows (no API key) render grayed with "🔒 No key".
- Keyboard: ↑↓ navigates, Enter selects, Esc closes, ⌘K opens.
- Cascading Provider / Category dropdowns removed.
Bug fixes
- Empty-output regression on non-flagship GPT-5.x and Gemini models on long-context RAG calls. The default thinking-effort policy was "off" for non-flagship models with thinking metadata. For models whose
modes:list declares nooffoption (OpenAI / Gemini reasoning is always-on), this meant noreasoning_effortwas sent and the provider's own default (medium) consumed the entire output-token budget on internal reasoning, leaving zero visible content. The default policy now uses the lowest listed mode (minimal) for these models. Claude (withmode: adaptive) continues to default tooff(correct Anthropic behavior). - CLI prefix-mapping consolidated. The hand-rolled if/elif block in
src/ragbot.py::run_chatnow calls the sharednormalize_model_idhelper, eliminating drift between the CLI and API code paths.
Docker
docker-compose.yml:~/.synthesismount switched to read-write so the preferences API can persistragbot.yaml.keys.yamlstill 0600 on the host; the chat path already reads keys, so write capability does not materially weaken the threat model.- Added
OLLAMA_API_BASEenv (defaults tohttp://host.docker.internal:11434) onragbot-api. - Added a legacy
~/.config/ragbotread-only mount so users on the pre-~/.synthesis/layout keep working without migration.
Internal
tests/test_models_integration.pyskips Ollama models that aren't currently pulled (graceful for clean clones).- Test suite: 270 → 327 passing.
PROVIDER_LABELSgainedollama.- Backend Pydantic
ModelInfoextended withdisplay_name,supports_thinking,is_local.
Quick start
Same as v3.2.x. For local Gemma:
brew install ollama
brew services start ollama
ollama pull gemma4:e4b      # 9.6 GB — fast tier
ollama pull gemma4:26b      # 18 GB — MoE
ollama pull gemma4:31b      # 20 GB — dense workhorse

docker compose up -d
# Open http://localhost:3000 and select an Ollama model from the picker.
Commits since v3.2.0
b211d65Fix default reasoning effort for non-flagship models with discrete modesd2efbedUpdate model picker UI6f107f9Update model API and preferences4d6feefUpdate Docker config and keystoreaf4f92cRefactor model ID normalization to shared helper9d5bd22Update LLM engine configuration and tests
v3.2.0 — Demo mode + refreshed screenshots
Highlights
- Demo mode via `RAGBOT_DEMO=1` or `ragbot --demo`. Hard-isolates discovery to the bundled `demo/ai-knowledge-demo/` workspace and `demo/skills/ragbot-demo-skill/`. Real workspaces declared in `
/.synthesis/console.yaml` and any glob-discovered repos under `/workspaces/*/` are invisible while demo mode is on. Auto-indexes the bundled content on first invocation. - `/health` and `/api/config` report `demo_mode: true` when active. The healthcheck's `vector_backend.workspaces` count is filtered to demo-visible collections so a real workspace count can't leak through the UI when other collections coexist on the same vector store.
- Web UI banner. A yellow "🎭 Demo mode" strip renders above the workspace picker whenever the server reports `demo_mode: true` — so screenshots taken in demo mode are unmistakably demo.
- Refreshed screenshots in `screenshots/v3.2/`, captured against an isolated Playwright Chromium instance running against demo mode. The README hero shots reflect the current Web UI.
Quick start
```bash
git clone https://github.com/rajivpant/ragbot.git
cd ragbot
cp .env.example .env
Add at least one API key (Anthropic, OpenAI, or Google).
pip install -r requirements.txt
docker compose up -d # bundled Postgres + ragbot stack
RAGBOT_DEMO=1 python3 src/ragbot.py chat -p "What is ragbot?"
```
Or for the Web UI:
```bash
RAGBOT_DEMO=1 python3 -m uvicorn src.api.main:app --port 8000 &
cd web && npm install && NEXT_PUBLIC_API_URL=http://localhost:8000 npm run dev
Open http://localhost:3000 — yellow demo banner confirms demo mode.
```
Tests
20 new demo-mode regression tests cover: env-var truthy/falsy recognition, bundled-path discovery, discovery isolation for both workspaces and skills, the demo-workspace-name constants. Final pass: 304 passed, 5 skipped.
Confidentiality posture
The bundled demo content was written from scratch for the demo, not derived from any real workspace. The discovery isolation guarantees real workspace names cannot leak into demo screenshots. The same screenshots in this release were captured by an isolated Playwright Chromium instance with no chrome / tab-bar / sidebar in frame, so even browser-level metadata is clean.
Setup
See README.md, CONFIGURE.md, and README-DOCKER.md.
v3.1.0 — LLM backend abstraction
Highlights
-
LLM backend abstraction. Every LLM call now routes through a swappable backend interface (
src/ragbot/llm/). Two backends ship:- litellm (default) — wraps
litellm.completion(). Best provider/model coverage, handles long-tail provider quirks. Pinned>=1.83.0(post-March-2026 supply-chain incident range). - direct — opt-in. Calls
anthropic,openai, andgoogle-genaiSDKs directly. Smaller dependency surface, no third-party gateway.
Selection:
RAGBOT_LLM_BACKEND={litellm|direct}. Adding a new backend (Bifrost, Portkey, OpenRouter, etc.) is one new file plus one selection arm. - litellm (default) — wraps
-
Web UI controls for reasoning effort (
auto,off,minimal,low,medium,high) and the cross-workspace skills auto-include toggle. -
/api/chatacceptsthinking_effortandadditional_workspaces— the same surface as the CLI flags. -
Provider-quirk handling lives in backends. Backends absorb GPT-5.x
max_completion_tokensrename, Claude 4.7+thinking.type.adaptiveshape, and the Anthropic-thinking-requires-temperature=1constraint. The chat code path stays clean.
Bug fixes (caught during manual testing)
- Chat CLI workspace lookup ignored
~/.synthesis/console.yamldiscovery; now honours overrides only and falls through to the full discovery chain. get_relevant_contextbudget loop usedbreakinstead ofcontinue, blocking smaller results when an oversized whole-file script chunk topped the rankings.- Anthropic + thinking now forces
temperature=1.0automatically. - Claude 4.7+ uses the new
thinking.type.adaptiveshape instead of LiteLLM's olderenabledshape (which 4.7+ rejects). transformers>=5.6.0pinned to tracktokenizers 0.22.xcompatibility (older transformers crashedsentence_transformersimport).
API additions
ChatRequest.thinking_effort: 'auto'|'off'|'minimal'|'low'|'medium'|'high'ChatRequest.additional_workspaces: string[](empty array opts out of skills auto-include; omitted lets the server auto-include)
Tests
- 26 new tests for the LLM backend abstraction (contract, selection, kwargs builder, direct healthcheck).
- 6 regression tests covering the bug fixes above.
- Final pass: 284 passed, 5 skipped.
Strategic note
LiteLLM remains a defensible default for ragbot in April 2026, primarily because of its provider/model coverage breadth. The March-2026 supply-chain incident (1.82.7–1.82.8) is bounded by the >=1.83.0 pin, but the API-compatibility lag for Claude 4.7+ shows the recurring tax of multi-provider gateways. The abstraction layer in this release is the response: keep LiteLLM as the default, make swap-in alternatives a configuration change rather than a code rewrite.
Setup
See README.md, CONFIGURE.md, and README-DOCKER.md.
v3.0.0 — Modernization release
Highlights
- Pgvector by default. PostgreSQL with the
pgvectorextension is the default vector backend, replacing embedded Qdrant. Native full-text search viatsvector+ GIN replaces in-process BM25. The legacy embedded Qdrant backend remains as an opt-in fallback (RAGBOT_VECTOR_BACKEND=qdrant). - Agent Skills as first-class content. Discover and index Agent Skills (
SKILL.mdplus references and scripts) from~/.synthesis/skills,~/.claude/skills, and plugin caches. Newragbot skills {list,info,index}CLI. The compiler can include skills via asources.skillsblock incompile-config.yaml. - Workspace-rooted layout. AI Knowledge repos are discovered across
~/workspaces/*/ai-knowledge-*and via the synthesis-engineering shared~/.synthesis/console.yamlsource list. Configuration moved to~/.synthesis/(legacy~/.config/ragbot/falls through). - Reasoning / thinking modes. Models that advertise thinking support (Claude Sonnet 4.6, Claude Opus 4.7, GPT-5.5, GPT-5.5-pro, Gemini 3.x) are wired through LiteLLM's
reasoning_effort. Flagship models default tomedium; override per-call (--thinking-effort high) or globally (RAGBOT_THINKING_EFFORT). - Cross-workspace retrieval.
get_relevant_contextauto-merges results from the user's selected workspace and the canonicalskillsworkspace via reciprocal rank fusion. Disable with--no-skills.
API additions
/api/chatacceptsthinking_effortandadditional_workspacesfields./api/configand/healthreport the activevector_backend(backend name, health, version, workspaces count).
Models (engines.yaml)
- Anthropic: Haiku 4.5, Sonnet 4.6 (default), Opus 4.7.
- OpenAI: GPT-5.4-mini, GPT-5.5, GPT-5.5-pro (flagship).
- Google: Gemini 3.1 Flash Lite, Gemini 3 Flash (default), Gemini 3.1 Pro (flagship).
Dependency notes
litellmpinned>=1.83.0(post-supply-chain-incident range; avoid 1.82.7-1.82.8).- Direct
google-generativeaiusage migrated togoogle-genai(the legacy SDK is end-of-life). - 259 tests pass on the release SHA.
Breaking changes
- Vector backend default flipped to pgvector. Existing Qdrant users can opt back in with
RAGBOT_VECTOR_BACKEND=qdrant. Postgres + pgvector is required for the default path; seeCONFIGURE.md. - Configuration home moved to
~/.synthesis/. Legacy~/.config/ragbot/{keys,config}.yamlis read as a fallback.
Setup
See README.md, CONFIGURE.md, and README-DOCKER.md for setup instructions.