Repository navigation
Processing text detection output #18425


|
Hii, I'm running PP-OCRv6_medium_det_infer, through ONNX |
Replies: 1 comment 1 reply

|
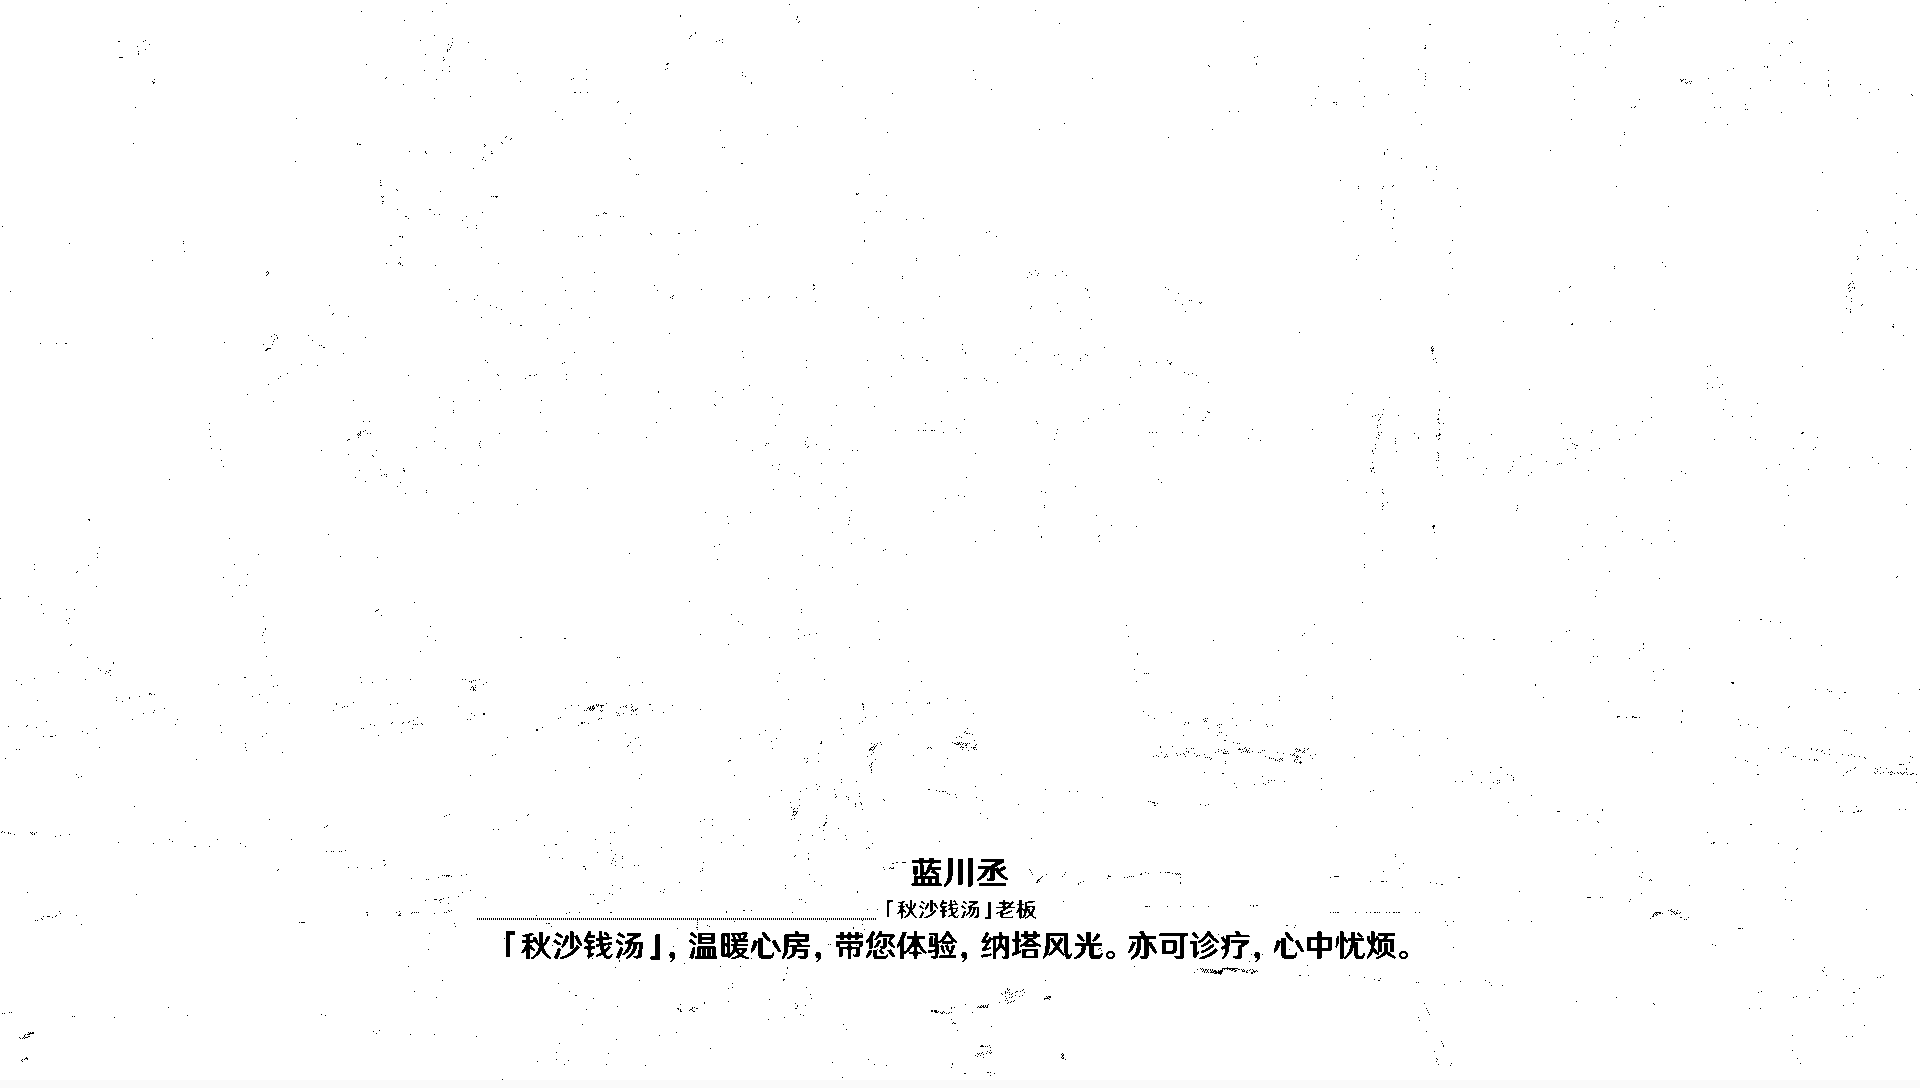
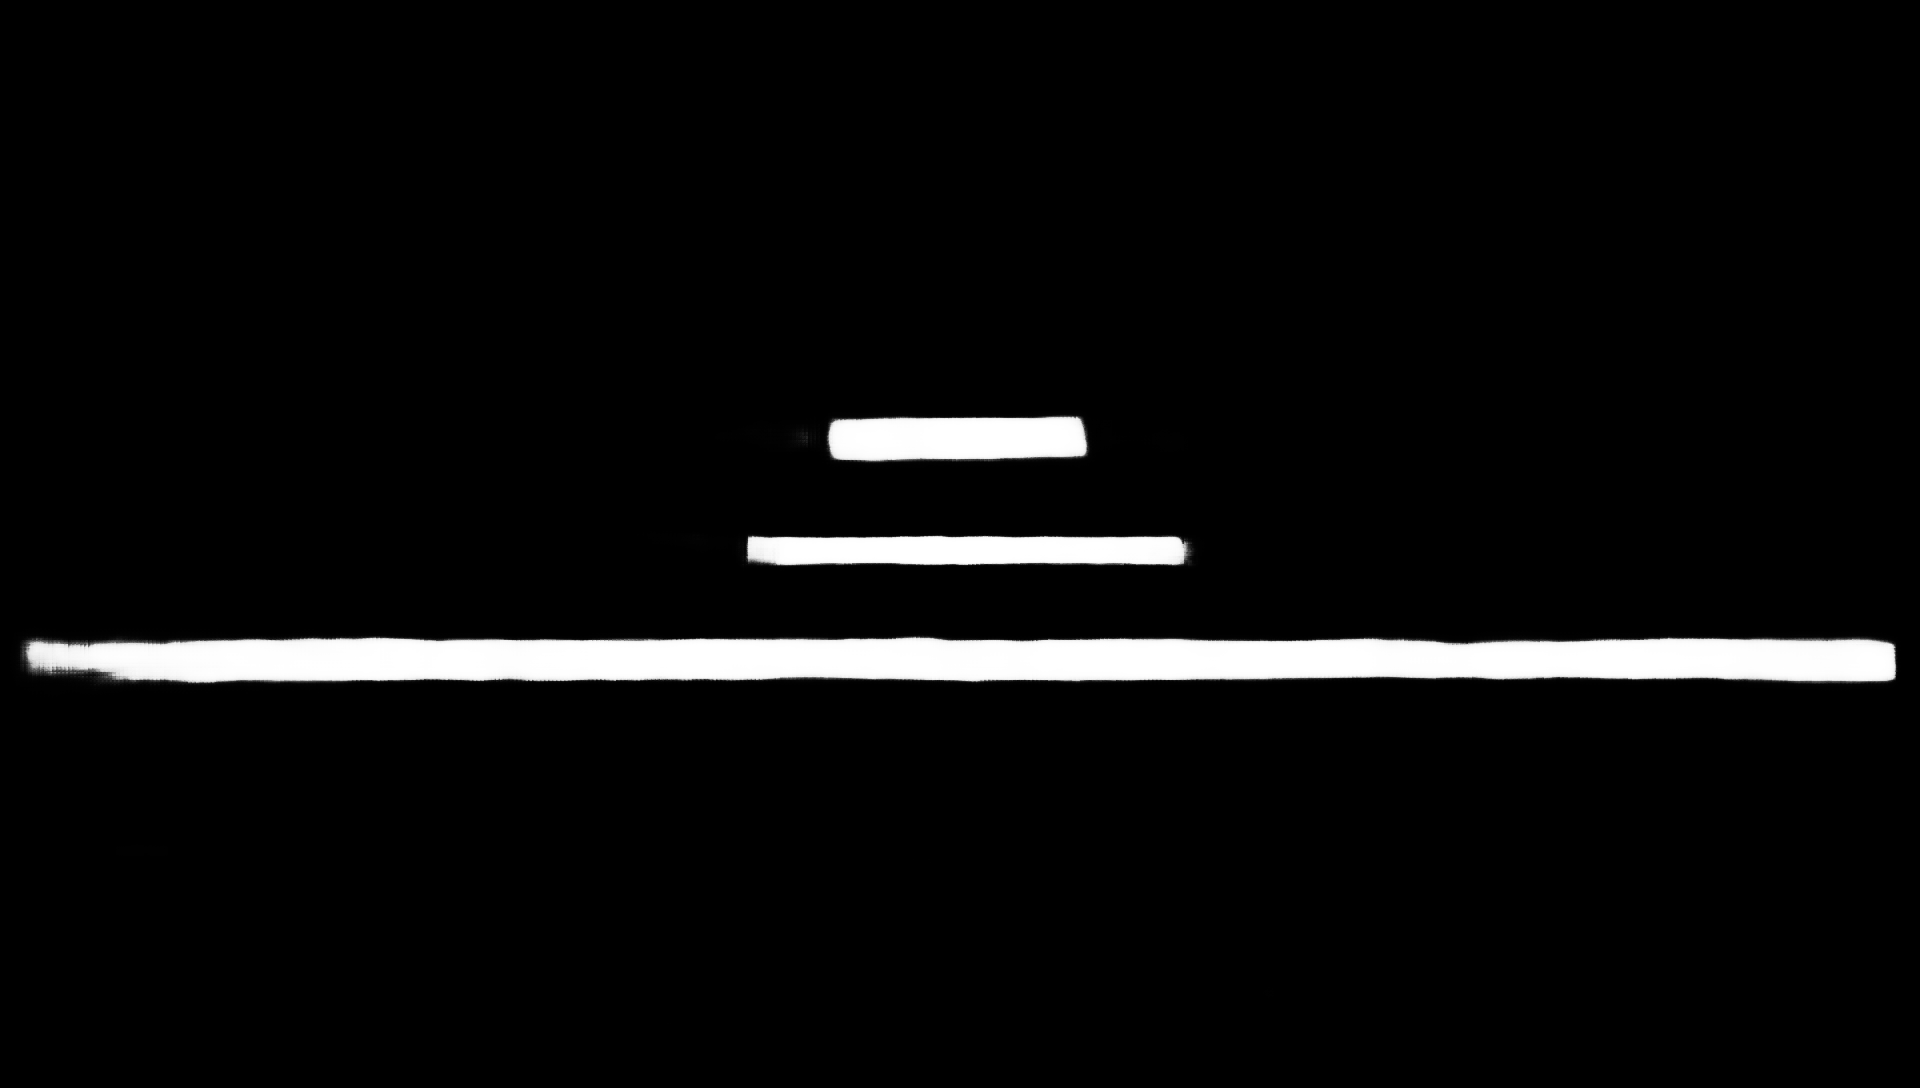
The output isn't moved and scaled by the model. The input tensor has the wrong memory layout: the image went in as HWC (interleaved RGB, the way OpenCV/PIL return it) without being transposed to the NCHW layout the model expects. When HWC bytes are read as CHW, each of the three "channels" contains one third of the image rows, stretched 3× vertically and 3× horizontally. Your screenshots match that exactly. Your text is in the bottom third of the image, so it ends up in the third plane at Horizontally, the middle third of each row maps to The fix is to normalize and transpose before running the model. This matches PaddleOCR's own detection preprocessing:
With the correct layout, the probability map lines up with the input pixel for pixel. If you resize the image so both sides are multiples of 32, scale the boxes back by |

|
It works! Thank youu |


The output isn't moved and scaled by the model. The input tensor has the wrong memory layout: the image went in as HWC (interleaved RGB, the way OpenCV/PIL return it) without being transposed to the NCHW layout the model expects.
When HWC bytes are read as CHW, each of the three "channels" contains one third of the image rows, stretched 3× vertically and 3× horizontally. Your screenshots match that exactly. Your text is in the bottom third of the image, so it ends up in the third plane at
text line | y in input | predicted y' | y in your output -- | -- | -- | -- name | ~873 | 443 | ~437 subtitle | ~908 | 548 | ~550 main line | ~945 | 659 | ~660y' = 3·y − 2·1088:Horizontally, the middle …