Repository navigation

🚀 Release v0.8.0
✨ Highlights
Container
Both linux/amd64 and linux/arm64 Docker containers are available on NGC as nvcr.io/nvidia/nemo-rl:v0.8.0.
Here are the major software components included in the container:
| Software Component | Version |
|---|---|
| NeMo-RL | 0.8.0 |
| NeMo-Gym | 0.7.0+1f8afc7 |
| NeMo-Automodel | 0.6.1+72dacef |
| Megatron-Bridge | 0.7.0+e0b5630 |
| Megatron-Core | 0.20.0+a694348 (via Megatron-Bridge) |
| PyTorch | 2.13.0 (2.11.0 in the SGLang and TensorRT-LLM environments) |
| vLLM | 0.29.0 |
| SGLang | 0.5.17.dev30+g3003d70f6 |
| TensorRT-LLM | 1.3.0rc21 |
| Ray | 2.58.0 |
| Transformers | 5.12.1 |
The NeMo-RL container is built on top of nvcr.io/nvidia/cuda-dl-base:26.05-cuda13.2-devel-ubuntu24.04 and uses Python 3.13.14.
If you would like to build this container, or nightly containers, yourself, we provide the exact instructions we use at https://docs.nvidia.com/nemo/rl/latest/docker.html#release-image.
Single Controller (beta)
NeMo RL v0.8 adds the Single Controller, a new async RL runtime (#3219, #3220, #3266, #3267, #3427). One CPU-only Ray actor runs two loops at the same time: a rollout loop that generates one prompt group at a time, and a train loop that trains as soon as enough groups are ready. The two loops share the TransferQueue data plane. Finished groups go into a replay buffer, and a sampler picks which groups each step trains on, so rollout batching is no longer tied to the training batch.
Compared with the existing async GRPO path, the Single Controller keeps the GPUs busier in two ways:
- Streaming: training starts as soon as
async_rl.min_groups_for_streaming_trainprompt groups are ready, instead of waiting for the full batch, so training and generation overlap more. Set it tonum_prompts_per_stepto keep full-batch steps. - Samplers:
in_ordermatches the existing async GRPO path (each dispatched batch trains at its planned step).weight_fifo,ready_first, andwindowedtrain on groups as they finish, so the trainer waits less;ready_firstalso uses late groups instead of throwing them away. The right sampler for your recipe depends on how much asynchrony (training on rollouts from older weights) your training can tolerate.
The Single Controller implements streaming as described in the StreamRL paper: instead of waiting for a full batch of rollouts (panel c), the trainer starts on groups as they finish (panel d). Figure 5 from StreamRL (Zhong et al., arXiv:2504.15930, CC BY-SA 4.0):

async_rl:
  min_groups_for_streaming_train: 8   # below num_prompts_per_step turns on streaming
  sampler:
    name: ready_first                 # in_order | weight_fifo | ready_first | windowed | custom
    max_staleness_versions: 1
How each sampler picks groups from the same buffer:

What it supports in v0.8:
- Megatron training backend only. Automodel training on the Single Controller is not supported yet and is coming in the next release.
- GRPO and PPO (#3773), with five samplers:
in_order,weight_fifo,ready_first(#3582),windowed, andcustom. PPO supports onlyin_orderwithout streaming. - vLLM or Megatron Inference for rollouts, colocated or not for Megatron Inference (#3727, #3730, #4009), plus NeMo Gym rollouts, Router Replay (R3) (#3378), VLM GRPO, and MOPD (#3768).
- Keeps training when things fail (#3589, #3590, #3591, #3592, #3665). Failed rollouts are retried within a budget or dropped. If a generation shard dies, the run rebuilds its refit group over the shards that are left and keeps going. Dead shards can be restarted and rejoin at the next refit. All of this is off by default; see
async_rl.rollout_failure,async_rl.generation_fleet_health, andasync_rl.generation_router. - Checkpoint and resume, including rollouts (#3429, #3480, #3923, #3924, #3925, #3898). Checkpoints keep finished rollouts that were not trained on yet, and re-run prompt groups that were still in flight. Periodic rollout snapshots save progress between trainer checkpoints. Works with both the
simpleandmooncake_cpudata-plane backends. - Exact token capture (#3837, #4129, #4191). For NeMo Gym rollouts, the exact tokens and logprobs produced by inference are captured and used for training, with no retokenization. Works with vLLM and Megatron Inference; images and video are captured on vLLM.
uv run examples/run_grpo_single_controller.py --config examples/configs/grpo_math_1B_megatron_single_controller.yamlThe Single Controller needs data_plane.enabled: true and (for vLLM) async_engine: true with non-colocated generation. Validation, reward shaping, and dynamic sampling are not supported yet. Example recipes:
- Async GRPO: grpo-llama3.1-8b-instruct-2n8g-async-1off-single-controller-streaming2.yaml
- Async PPO: ppo-qwen2.5-1.5b-gsm8k-2n8g-megatron-valuetp2sp-dynbatch-noncolocated-async-single-controller.yaml
- R3 with MoE: grpo-qwen3-30ba3b-10n8g-megatron-cp2-r3-async-single-controller.yaml
- Token capture with Megatron Inference: grpo-nanov3-30BA3B-2n8g-megatron_generation-noncolocated-async-gym-single-controller-token_capture.yaml
See the Single Controller guide for the required settings, the samplers, and the full list of supported features.
TensorRT-LLM Rollout Backend
NeMo RL v0.8 adds TensorRT-LLM as a rollout engine (#2420, #3130, #3418, #3537). With TensorRT-LLM and Dynamo (also new in v0.8), NeMo RL now has five rollout engines: vLLM, SGLang, Megatron Inference, TensorRT-LLM, and Dynamo. Set policy.generation.backend: trtllm. It works with both Megatron and Automodel training, colocated or non-colocated, and supports in-flight weight updates. An OpenAI-compatible HTTP server lets it drive NeMo Gym agentic rollouts such as SWE.
policy:
  generation:
    backend: trtllm
    trtllm_cfg:
      tensor_parallel_size: 1
      async_engine: true   # required
      gpu_memory_utilization: 0.6
TensorRT-LLM runs in its own trtllm uv environment. It was validated by matching vLLM convergence on math and SWE agentic RL; throughput tuning comes in a later release. Example recipes:
- Math: grpo_math_1B_trtllm.yaml
- Nemotron 3 Nano DAPO: grpo-dapomath17k-nanov3-30BA3B-8n4g-megatron-trtllm.yaml
- Async SWE agentic RL with Qwen3-30B-A3B-Thinking: grpo_qwen3_30b_async_swe_trtllm.yaml (see the SWE RL guide)
Faster Weight Refit: NCCL Reshard
Refit is the step that copies new weights from training to the rollout engine. NeMo RL v0.8 adds NCCL reshard refit (refit_transport: nccl_reshard) for non-colocated runs (#2971, #3477, #3739). Each training shard sends its large FFN and expert weights straight to the matching rollout shard, so no rank ever builds the full tensor. Small tensors still use the existing packed path. It works from Megatron to vLLM and from Megatron to Megatron Inference, including BF16 training with MXFP8 rollouts.
policy:
  generation:
    colocated:
      enabled: false
    refit_transport: nccl_reshard
Each weight slice crosses the network once, and generation GPUs in the same NVLink domain share it over NVLink. Refit latency with matched configurations:
| Model | GPU | Broadcast (NCCL) | NCCL reshard |
|---|---|---|---|
| Qwen3-235B-A22B | H100 | 6.4 s | 1.9 s |
| DeepSeek-V3 671B | H100 | 14.9 s | 2.6 s |
| DeepSeek-V3 671B | GB200 | 6.1 s | 2.3 s |
In a full run of the DeepSeek-V3 async performance recipe on H100, refit time dropped from 15.3 s to 3.1 s and step time from 33.2 s to 21.0 s (#4870). Most async performance recipes now use it (#3865, #4869, #4870), for example grpo-deepseek-v3-64n8g-async-1off.yaml.
v0.8 also adds two more refit transports. Each transport is picked with the single policy.generation.refit_transport key, so only one can be active.
NIXL checkpoint-engine refit
NIXL refit sends full weights over a UCX/RDMA fabric (#2608). On DeepSeek-V3 it was 1.54× faster than NCCL refit (9.25 s vs 14.21 s). It needs vLLM generation and works with Automodel or Megatron training.
policy:
  generation:
    colocated:
      enabled: false
    refit_transport: nixl
    refit_cfg:
      nixl:
        update_weights_bucket_memory_ratio: 0.05
        device: cuda
        backend_name: UCX
        release_after_refit: false
        shard_expert_weights: true
Example config: grpo_math_8B_megatron_nixl.yaml. See the checkpoint-engine refit guide for UCX settings, sharded experts, and FP8.

Sparse delta refit
Sparse delta refit sends only compressed weight deltas, for setups where the link between training and rollout is slow (#2444). vllm_zmq_sparse sends them through a ZeroMQ relay over TCP, and vllm_s3_sparse sends them through S3. It needs vLLM generation, Megatron training, and BF16/FP16 rollouts, and it works with GRPO only.
policy:
  generation:
    colocated:
      enabled: false
    refit_transport: vllm_zmq_sparse  # or vllm_s3_sparse
    refit_cfg:
      sparse:
        delta_compression:
          encoding: xor
        storage:
          s3_bucket: null  # required for vllm_s3_sparse
Example recipe: grpo-qwen3-30ba3b-4n8g-megatron-zmq-deltaweight-noncolocated.yaml. See the sparse delta refit design doc.
The new refit guide explains how to pick a transport. See also the NCCL reshard design doc.

Megatron Inference Rollouts
Megatron Inference (policy.generation.backend: megatron) is in active development, and v0.8 adds many features to it.
Colocated Megatron training and inference. Training and rollouts can share the same GPUs. New in v0.8:
- Async GRPO with colocated Megatron Inference (#2884). Before, async GRPO needed non-colocated generation.
- Colocated reshard: rollouts can use a different parallel layout from training on the same GPUs, for example training with TP4/CP2 and generating with TP4/EP4 (#3490).
- Colocated Megatron Inference also works with the Single Controller (#3730) and NeMo Gym (#3406), and now builds CUDA graphs (#3718).
policy:
  generation:
    backend: megatron
    colocated:
      enabled: true
    refit_transport: mcore
    mcore_generation_config:
      refit_backend: nccl
      tensor_model_parallel_size: 4   # rollout layout, can differ from training
      expert_model_parallel_size: 4
Other additions:
- MXFP8 rollouts from a BF16 trainer (#3731).
- Multimodal generation for Nemotron Omni images and video, matching vLLM accuracy (#3920).
- HTTP frontends on every model-parallel coordinator with prefix-cache-aware routing, for NeMo Gym (#3912), and the async scheduler on by default (#3762).
- Logprobs after top-p/top-k processing, so top-p/top-k runs are correct (#3392).
- NCCL refit in place of the nvshmem copy service: ~16–19 s per step and flat on a 30B-A3B MoE, where nvshmem grew from ~95 s to over 135 s (#3166).
Example recipe: grpo-nanov3-30BA3B-2n8g-megatron_generation-colocated-reshard-async-gym.yaml. See generation design doc.
Low-Precision Rollouts: MXFP8 and NVFP4
MXFP8 rollouts
Training stays in BF16, and vLLM converts the weights to MXFP8 at every refit, then rolls out in MXFP8 (#1887, #3652, #3477, #3478, #3630). It works with NCCL reshard refit, and batching the MoE weight shuffle cut the transfer time on Qwen3-30B-A3B from 5.9 s to 0.89 s (#3478). The shipped recipes keep the LM head, attention, and the first and last few layers in BF16, and use importance-sampling correction.
policy:
  generation:
    vllm_cfg:
      precision: "fp8"
      is_mx: true
      quantization_ignore_patterns:
        - model.layers.*.self_attn.*
        - model.layers.*.mlp.gate
      num_first_layers_in_bf16: 3
      num_last_layers_in_bf16: 18
    vllm_kwargs:
      moe_backend: flashinfer_trtllm
There are 10 MXFP8-rollout performance recipes for Qwen3-30B-A3B, Qwen3-32B, Qwen3-235B, DeepSeek-V3, and Nemotron 3 Super, sync and async, for example grpo-qwen3-235b-32n4g-async-1off-mxfp8-rollout.yaml. See the FP8 / MXFP8 guide.
End-to-end NVFP4 training with NVFP4 rollouts
On Blackwell, NeMo RL v0.8 can train routed-expert MLPs using NVFP4 (W4A4) forward computation with Transformer Engine and roll out in NVFP4 with matching per-token activation scaling (#3566, #3654). Persistent policy weights and refit payloads remain BF16, optimizer state remains FP32, and backward computation currently uses TE’s dequantized path. Attention, routers, shared experts, and selected boundary layers remain in BF16. On Qwen3-30B-A3B-Base over 900 steps with Router Replay, NVFP4 tracks BF16 on reward, validation accuracy, and response length, while:
- rollout throughput is 1.40× higher and step time is 14.2% lower
- end-to-end throughput is 1.15× higher
- rollout weights are 68% smaller, with 2.62× the KV-cache capacity
Training throughput is lower (0.84×), and refit takes longer.
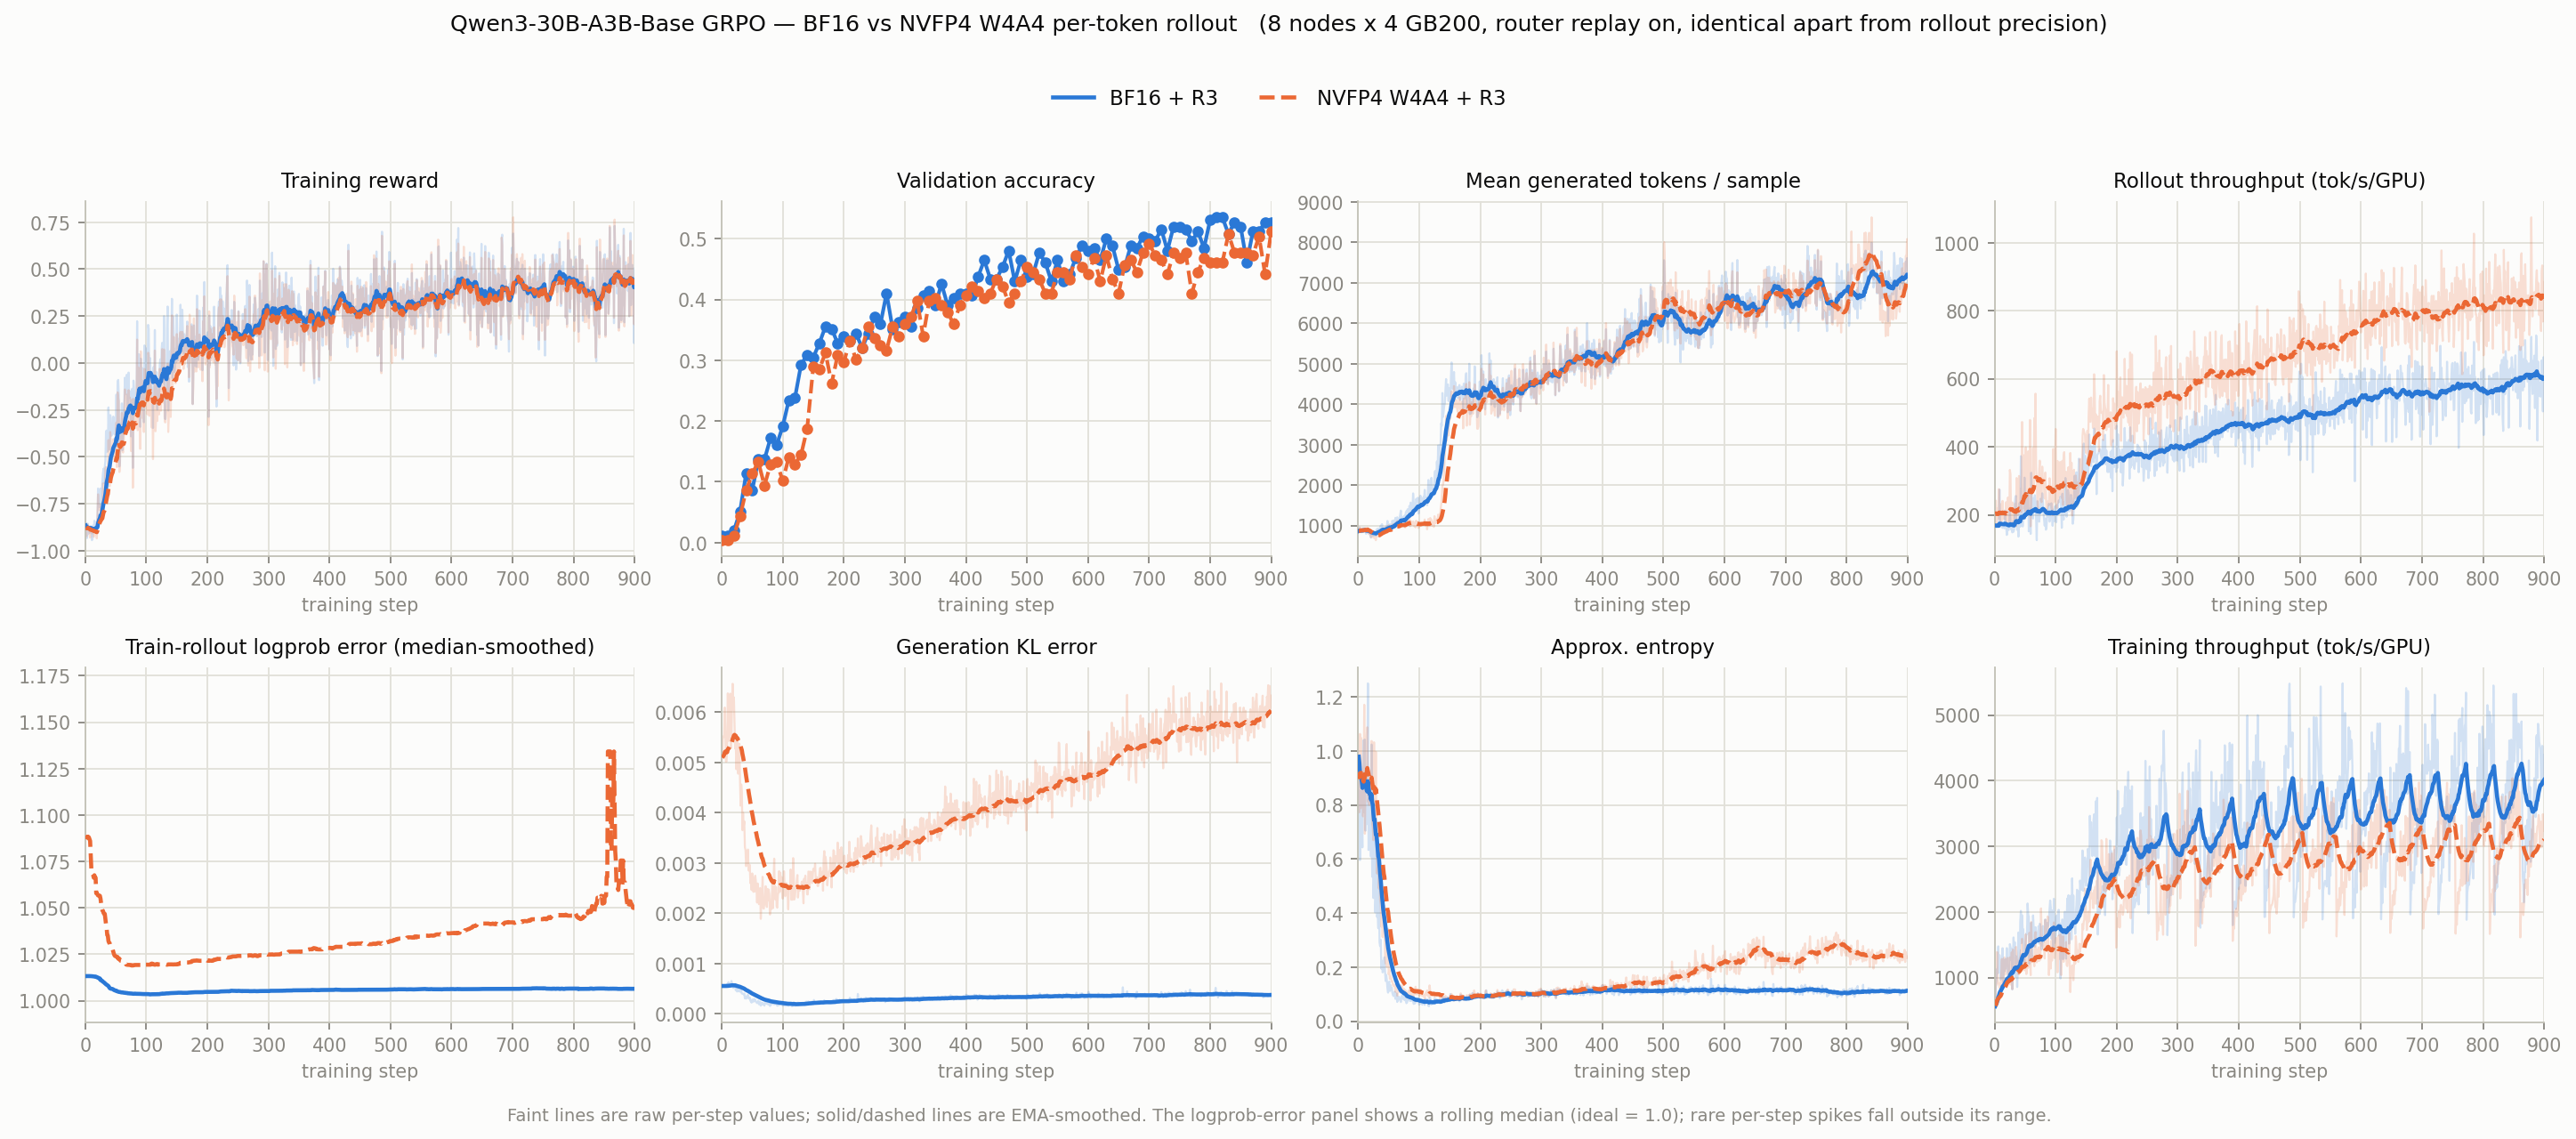
uv run examples/run_grpo.py --config examples/configs/recipes/llm/grpo-qwen3-30ba3b-base-8n4g-megatron-te-nvfp4-pertoken.yamlSee the NVFP4 per-token rollout design doc.
Quantization-aware RL with real NVFP4 rollouts for MoE and Mamba
Quantization-aware RL (QARL) with ModelOpt now supports real NVFP4 rollouts (W4A16 and W4A4) for MoE and hybrid Mamba models, including Qwen3-30B-A3B, Nemotron 3 Nano, and Nemotron 3 Super (#2983, #3308). On Nemotron 3 Super over 300 steps, W4A16 matches BF16 reward (~0.65), and W4A4 reaches ~0.58 while generating about 2.4× faster than BF16. An opt-in GPU-side export cuts step time by ~22–25% (#3308). The Nemotron 3 Super real-quant recipes currently fail on this release; see Known Issues.

See the Quantization-Aware RL guide.
PPO: Non-Colocated, Async, and Critic Warm Start
PPO, added in v0.7, grows several new modes in v0.8:
- Non-colocated generation (#3262): vLLM runs on its own GPUs while the policy and critic share the training GPUs. Set
policy.generation.colocated.enabled: false. - Async PPO (#3410): generation runs all the time while the policy and critic train, with staleness bounded by
ppo.async_ppo.max_trajectory_age_steps. Sync and async PPO show no regression in reward, validation accuracy, or logprob error. - Critic warm start (#3821, #4213):
ppo.warm_start_value_checkpointstarts the critic from a separately pretrained value checkpoint, so you don't pay for critic warmup in every run. - Separate critic epochs (#3829):
ppo.critic_ppo_epochs. - Faster GAE (#4156): when
gae_gammaandgae_lambdaare both 1.0, GAE uses a vectorized path. On a 196K-token SWE PPO batch this saved about 20 s per step. - PPO on the Single Controller (#3773).
Sync (blue) vs async (yellow) Megatron PPO on Qwen2.5-1.5B GSM8K, from #3410:

Example recipes:
- Automodel: ppo-qwen2.5-1.5b-gsm8k-1n8g-automodel-noncolocated-async.yaml
- Megatron: ppo-qwen2.5-1.5b-gsm8k-2n8g-megatron-valuetp2sp-dynbatch-noncolocated-async.yaml
See the PPO guide.
Nemotron 3 Ultra Post-Training
In v0.7, the Nemotron 3 Ultra recipe lived on the separate ultra-v3 branch. NeMo RL v0.8 brings the Nemotron 3 Ultra (550B-A55B) post-training recipe to main (#3276, #3529, #3452). It includes seven stage configs (student RLVR 1 and 2, MOPD, and the reasoning, IFBench, RLHF, and SWE teachers) and a single launcher. With EXTERNAL_JUDGES=1, the GenRM and NL2Bash judges run as separate vLLM pools next to training instead of inside the training Ray cluster.
EXTERNAL_JUDGES=1 bash examples/nemo_gym/nemotron-3-ultra/ultra_launch.shThe training data blends are on Hugging Face at nvidia/Nemotron-RL-Ultra-Training-Blends. See the Nemotron 3 Ultra guide.
Nemotron Omni: Multimodal Agentic RL
NeMo RL v0.8 adds training for the Nemotron Omni models on the Megatron backend (Nemotron 3 Nano Omni GRPO on the Automodel backend shipped in v0.7; see the Automodel section of the Nano Omni guide):
- Nemotron Nano Omni image GRPO (#3290).
- Nemotron Super Omni GRPO with MTP (#3494): MTP training and MTP speculative decoding with context parallelism. Over 50 steps on 16 nodes, mean reward went from 0.45 to 0.53, with about 75% draft acceptance.
- Multi-turn, multi-image, tool-calling GRPO with NeMo Gym (#3414), sync and async.
- Video in NeMo Gym, sync and async (#3648).
- Super Omni image MOPD (#3430) and the MPO preference algorithm for Omni Nano and Super (#3345).
- Multimodal payload deduplication (#3527):
grpo.deduplicate_multimodal_data: truestores each image or video once instead of once per generation, which cut rollout-to-policy data by about 15× at 16 generations per prompt.
Multi-turn tool-calling GRPO on Nemotron Omni, from #3414:

Example recipes:
- Super Omni with MTP speculative decoding: vlm_grpo-nemotron-super-omni-120ba12b-16n8g-megatron-tp8ep16cp2-async-gym-mtp-specdec.v1.yaml
- Multi-turn tool calling: vlm_grpo-nemotron-omni-30ba3b-circle-click-2n8g-megatron-tp2ep8.v1.yaml
See the Nemotron 3 Nano Omni guide, the Super Omni MOPD guide, and the Omni MPO guide.
SFT v2 with Megatron-Energon
NeMo RL v0.8 adds SFT v2, a single-controller SFT loop with Megatron-Energon multimodal data loaders (#3917), plus Energon-side sequence packing (#4105). The existing SFT loop is unchanged (data.backend defaults to hf). SFT v2 currently supports the Megatron backend with data.backend: energon.
uv run --locked examples/run_sft_v2.py --config examples/configs/recipes/vlm/vlm_sft-qwen2.5-vl-3b-instruct-clevr-1n2g-megatrontp1-energon.v1.yamlSFT v1 (blue) vs SFT v2 (orange) loss on Qwen2.5-VL-3B CLEVR, from #3917:

See the SFT guide and its SFT v2 / Energon section.
Model Support
Nemotron
- Nemotron 3 Ultra full post-training recipe on
main— see the highlight above. - Nemotron Nano Omni and Super Omni — see the highlight above.
- Nemotron 3.5 Lightning (30B-A3B) DAPO on Automodel (#3383): dapo-nanov3.5-30BA3B-4n8g-automodel-ep8.yaml. See the Nemotron 3.5 Lightning guide.
- MTP speculative decoding for Nemotron 3 Super and Ultra, with the MTP drafter updated at every refit (#2999).
Additional Models
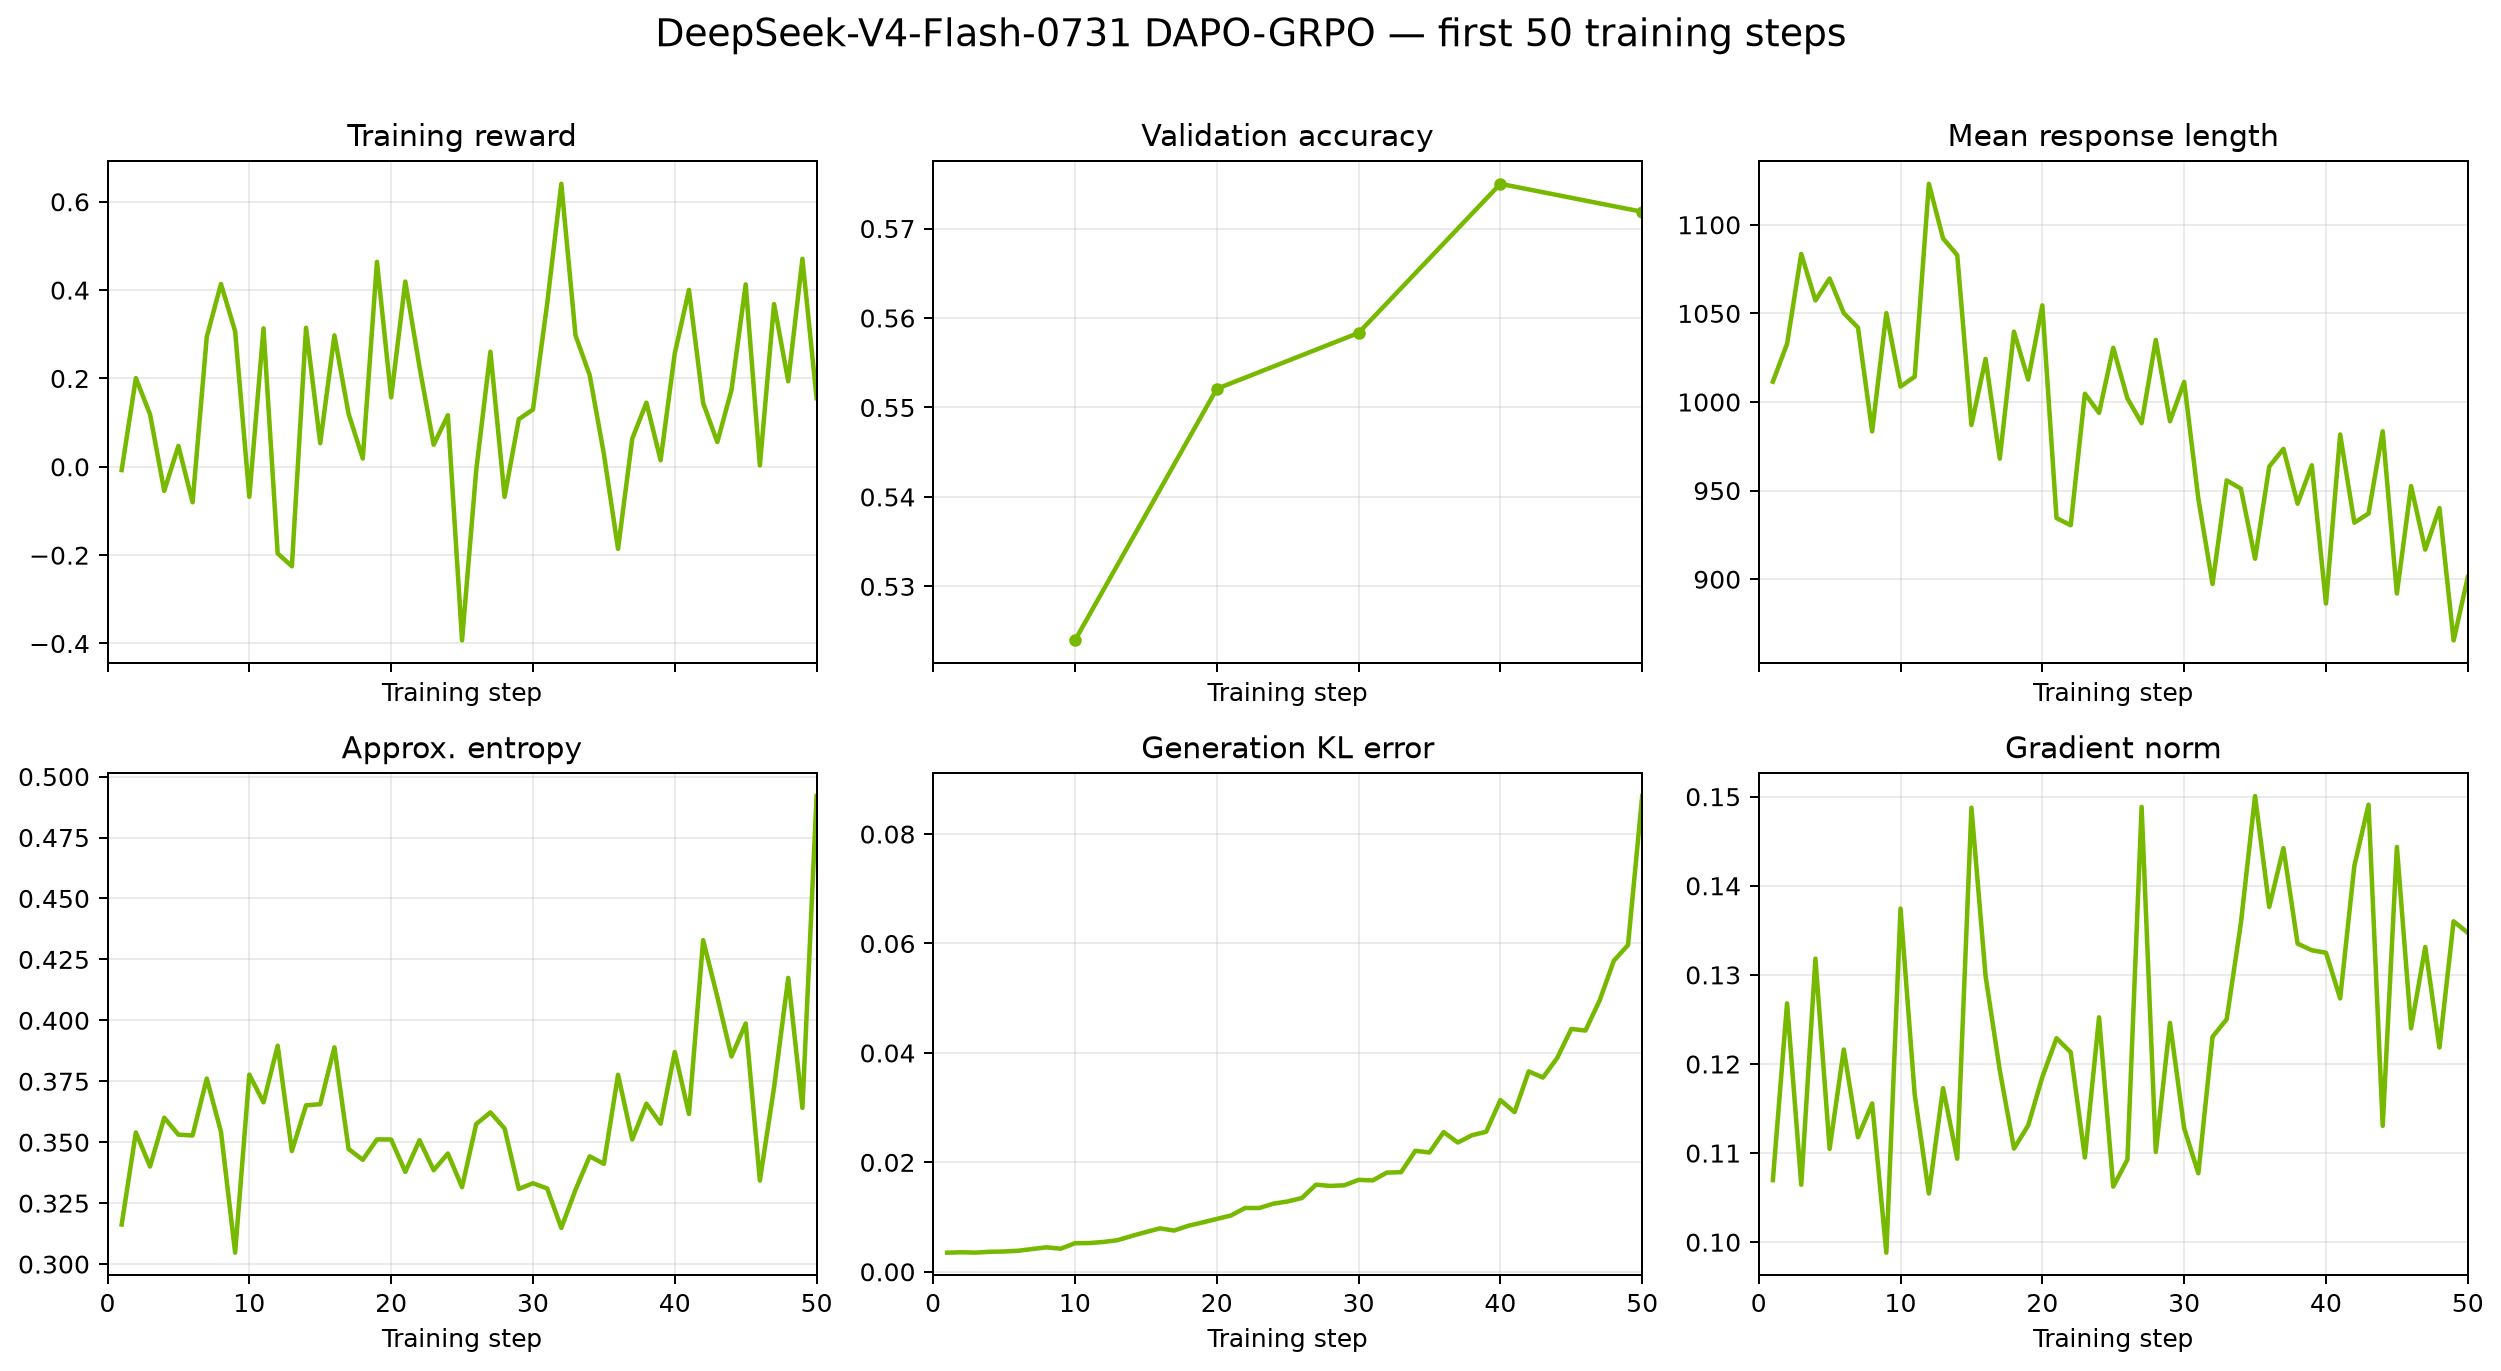
- DeepSeek V4 Flash GRPO on Automodel with FP8 vLLM rollouts (#3595): grpo-deepseek-v4-flash-0731-16n8g-automodel-cp8ep128.yaml. See the DeepSeek V4 Flash guide.
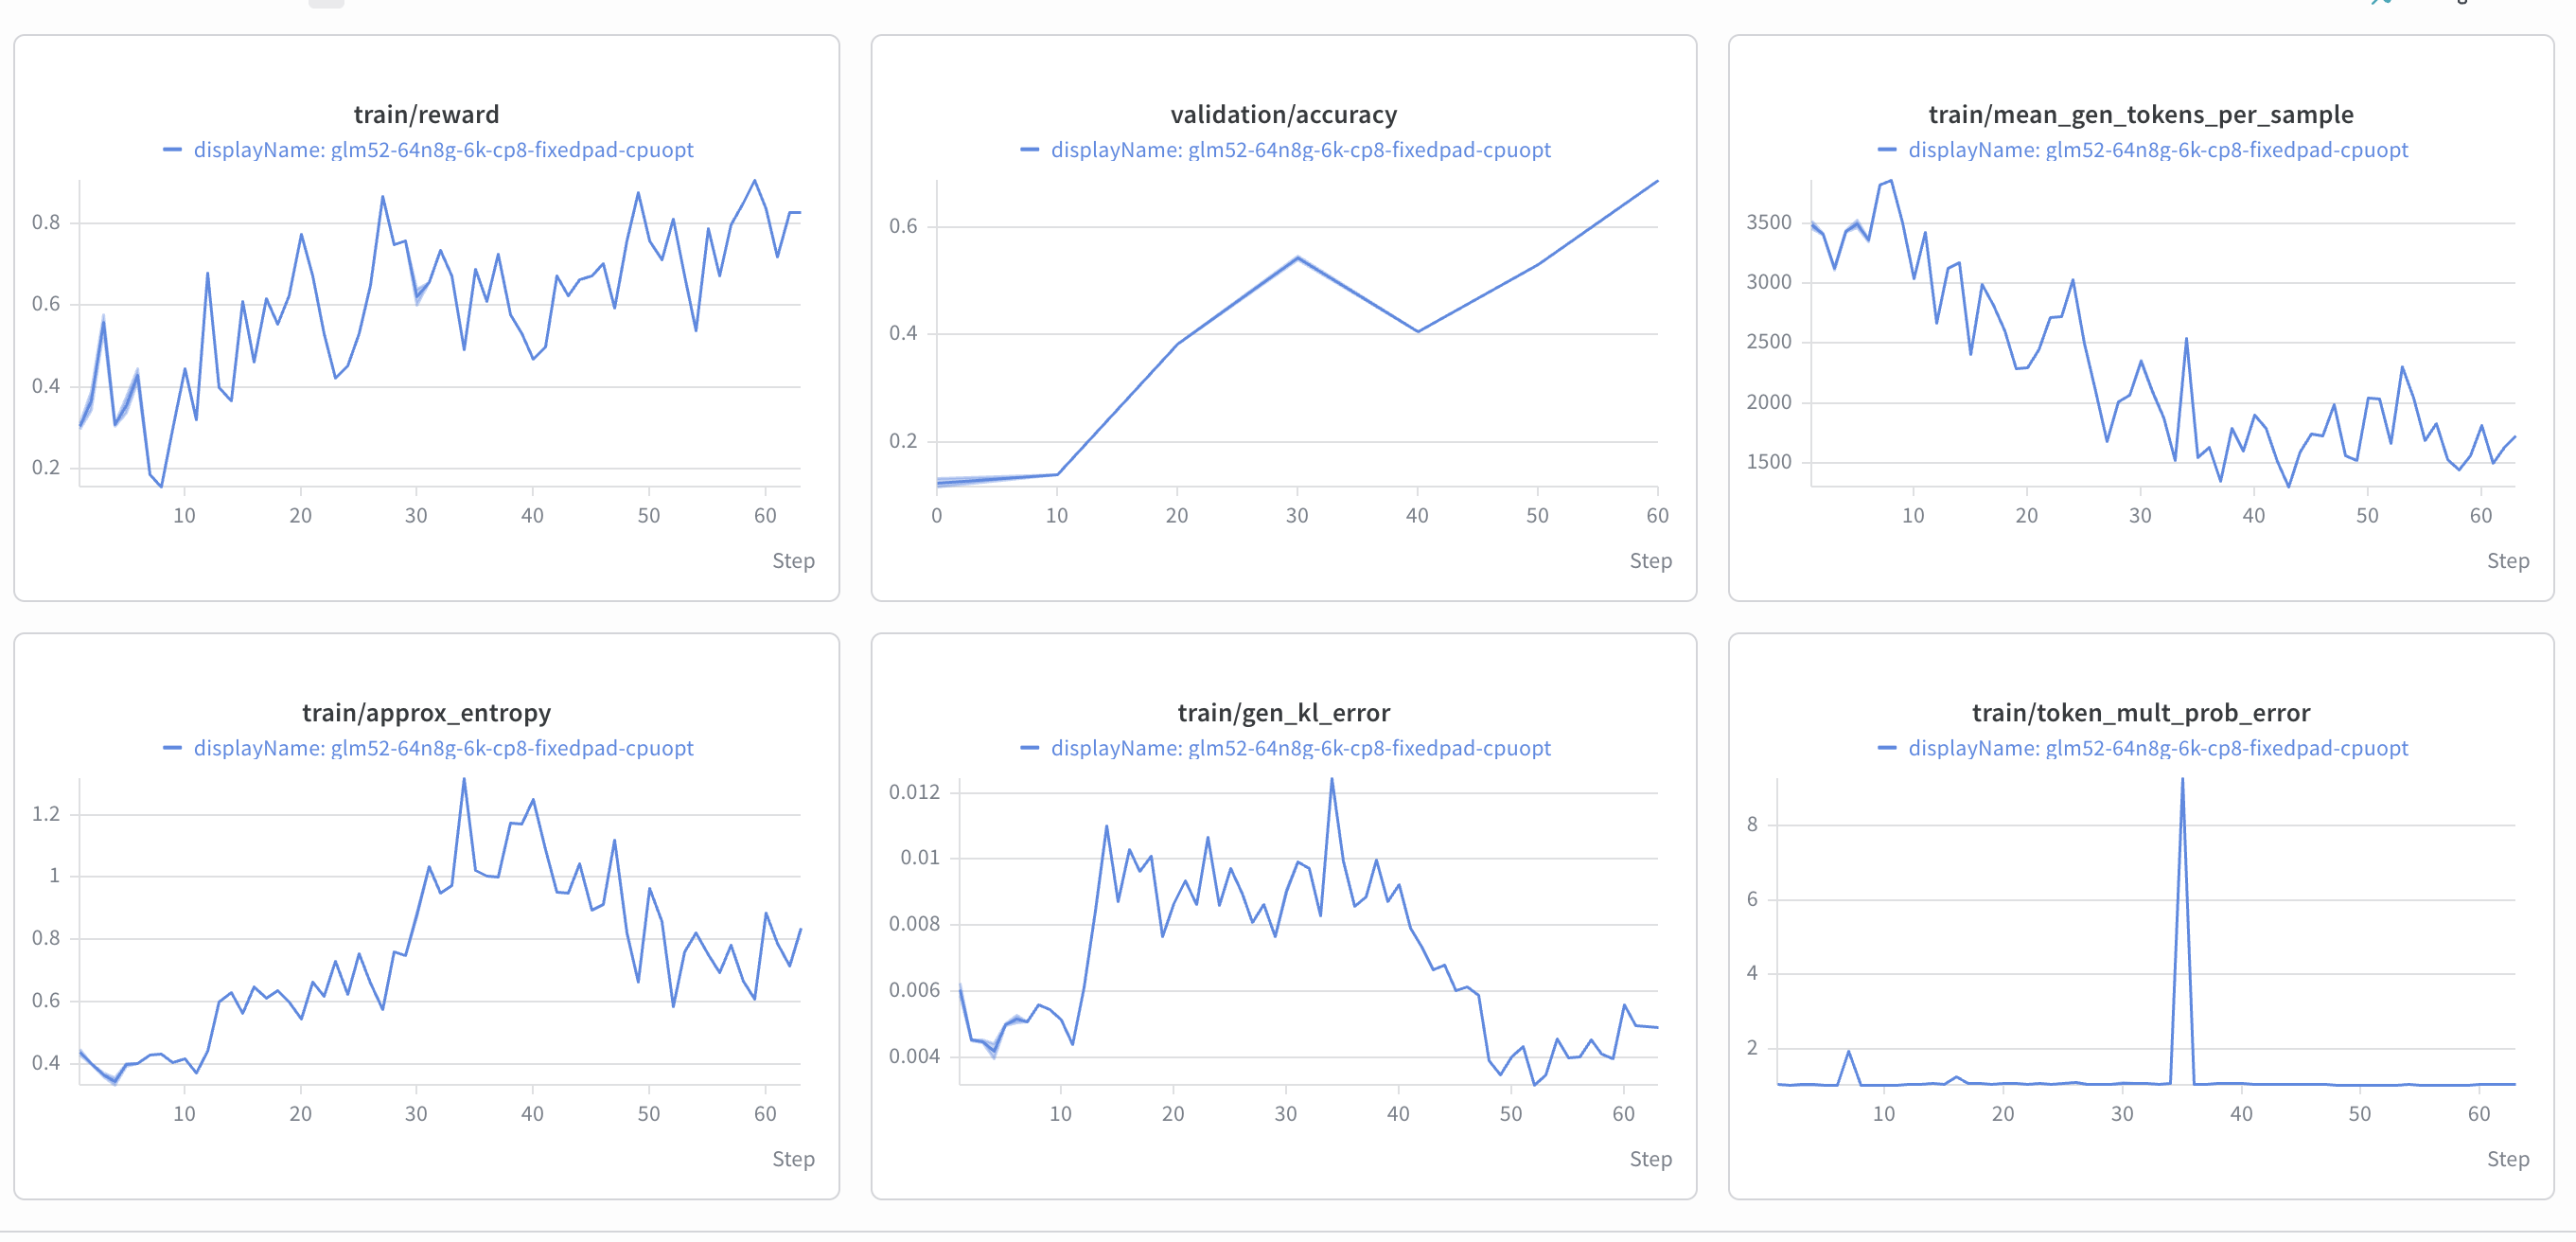
- GLM-5.2 GRPO on Megatron, up to 131K context (#3502, #4667): grpo-glm5.2-72n8g-megatron-noncolocated.yaml. See the GLM-5 guide.
- MiniMax-M3 text GRPO on Automodel (#4143): grpo-minimax-m3-32n8g-automodel-cp8ep128-noncolocated.yaml. See the MiniMax-M3 guide.
- Qwen3.8-27B GRPO on Megatron (#3678): grpo-qwen3.8-27b-2n8g-megatron-tp4pp2cp2.yaml.
- Gemma 4 12B, plus context-parallel recipes for Gemma 4 E2B, 26B-A4B, and 31B (#3911): dapo-gemma4-12b-it-2n8g-automodel.yaml. See the Gemma 4 guide.
- Qwen3.5 blockwise FP8 rollout and training (#2744).
- Qwen2.5-Omni-7B audio + video GRPO (#2823): Daily-Omni accuracy went from 0.498 to 0.590. See the audio-visual GRPO guide.
- Flow-GRPO for Qwen-Image (#3408), the first diffusion-model RL recipe, under
research/flow_grpo/. On an OCR reward, exact match went from 0.465 to 0.648. See its README.
| DeepSeek V4 Flash | GLM-5.2 | MiniMax-M3 |
|---|---|---|
 |
 |
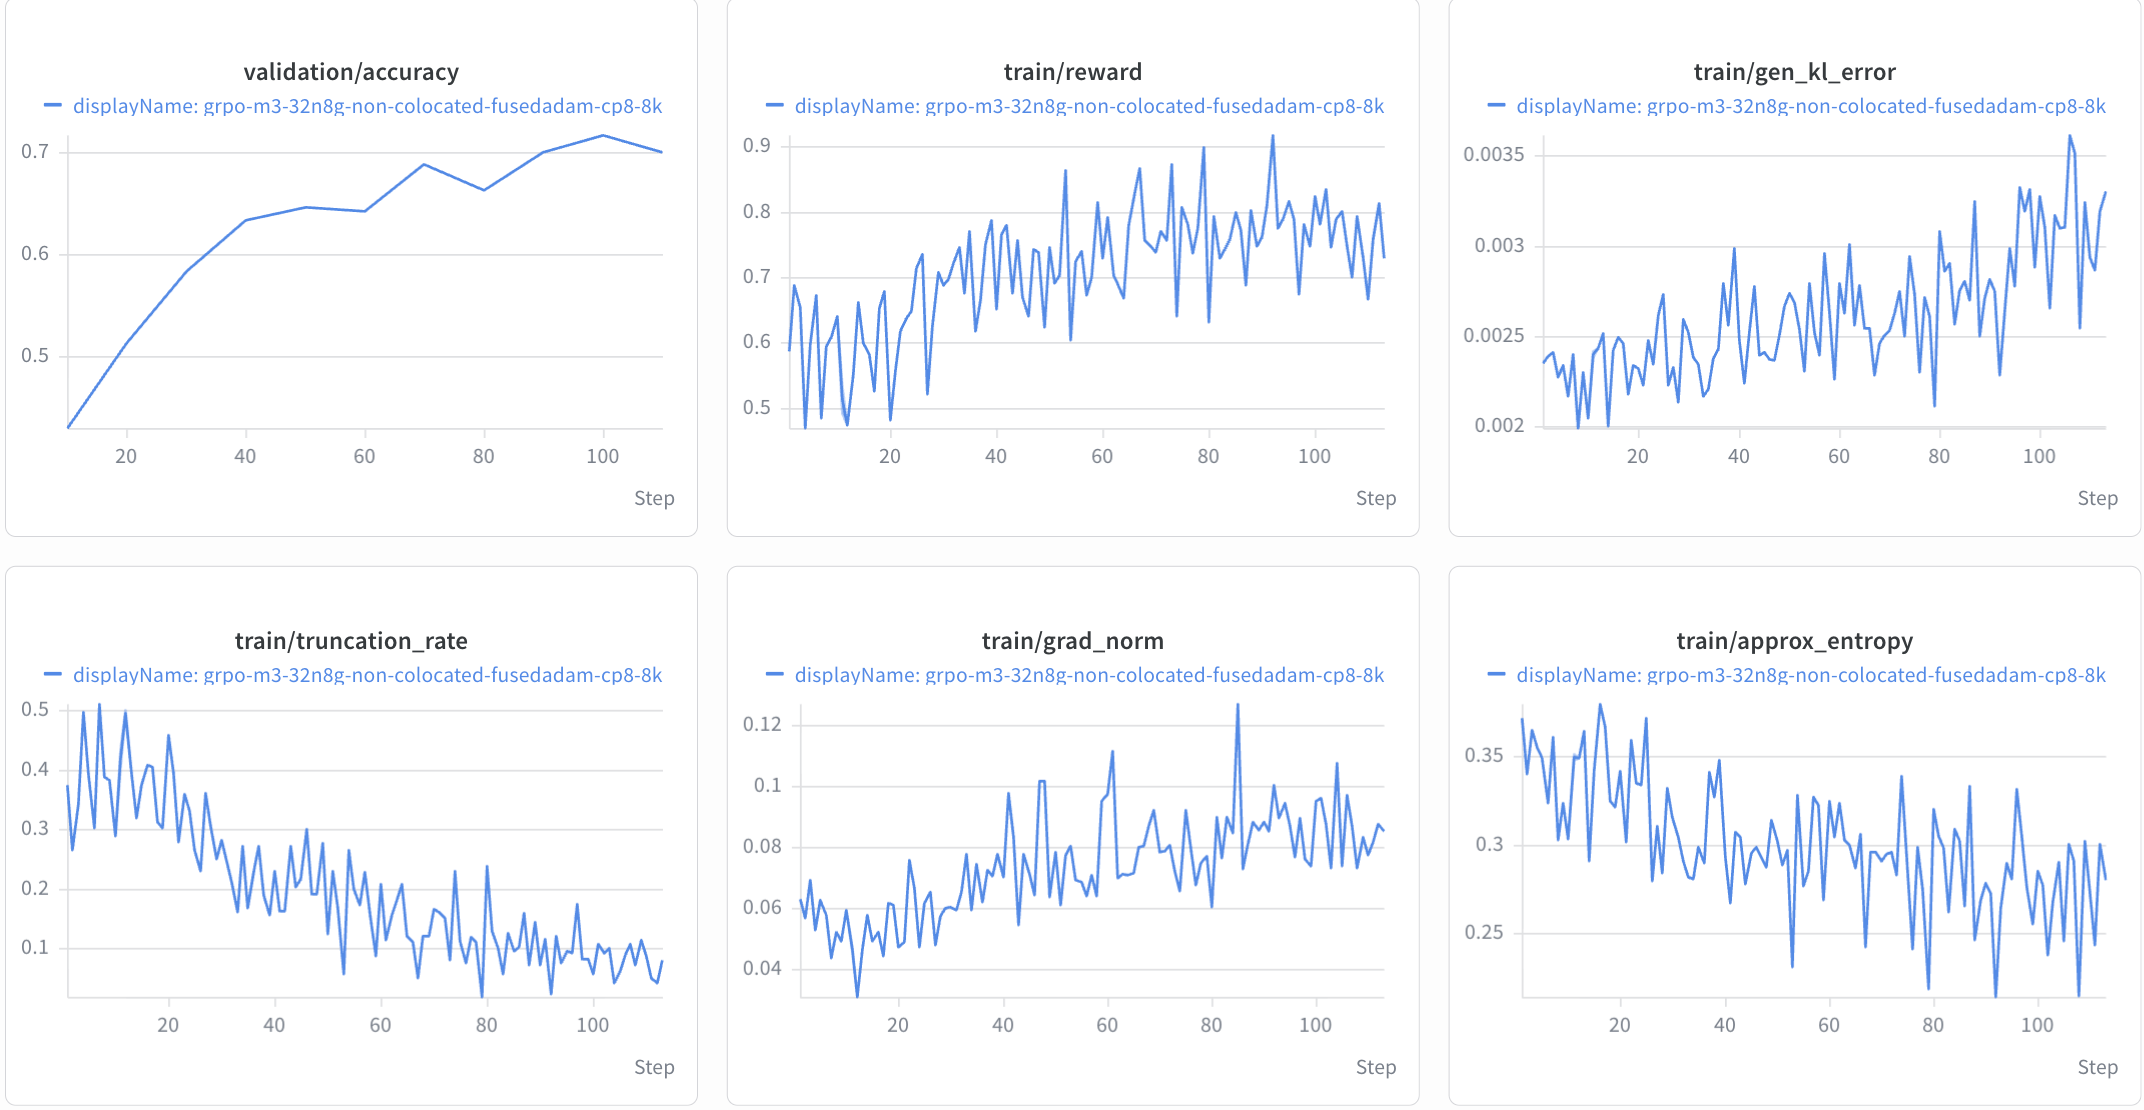 |
For the full list, see the model support page and the per-family model guides (#2900).
⚡ Performance Optimizations
- HybridEP for MoE on H100, B200, and GB200: MoE performance recipes now use HybridEP for expert-parallel communication, and the container builds it with multi-node support (#3436, #3438, #4118, #4037, #4038). On H100, the Nemotron 3 Super policy training step got 30% faster and the Qwen3-30B-A3B one 9% faster. On GB200, Qwen3-30B-A3B end-to-end steps got 11–13% faster. Automodel recipes use
backend.dispatcher: hybridep. - vLLM CUDA graphs in release and nightly recipes: 10 recipes that ran vLLM in eager mode now use CUDA graphs, making generation 48–85% faster (#4568, #4569).
- Single-forward sequence-logprob filtering:
loss_fn.seq_logprob_error_in_loss: trueapplies the sequence-logprob filter inside the training forward pass, removing a separate forward pass. This cut mean step time by 17.8% on Qwen2.5-Math-1.5B (#4171). - FlashInfer TRT-LLM MoE for BF16 on Blackwell: BF16 MoE performance recipes on GB200 use
moe_backend: flashinfer_trtllm, making Qwen3-235B steps 9–10% faster (#3461). H100 recipes stay on Triton (#4850). - Chunked linear fusion for GRPO: computes token logprobs from hidden states chunk by chunk, without building the full logits tensor, for GRPO and the other policy-gradient losses (#2833).
- Lower logprob memory: no full-vocab softmax on the inference-only path (#3484), selected-token logprobs computed directly (#3930, #3124), and an option to run packed microbatches largest first (
sequence_packing.microbatch_order: largest_first), which cut peak reserved memory from 158.5 GiB to 71.2 GiB on a Nemotron Nano run (#3476). - Megatron memory options: fine-grained activation offloading (#2279), offloading part of the optimizer state to CPU (#3628), and training CUDA graphs (#3483).
- Async checkpointing for Megatron: checkpoint writes run in the background (#2828). This is now on in the base Megatron configs.
- Faster startup and less per-step overhead at scale: Ray GCS tuning (#3089, #3158), batched worker port discovery (#2920), NeMo Gym startup that overlaps the generation model load (#3499, #3569), a GPU-free Ray head node option (
DEDICATED_RAY_HEAD=1) (#3388), and less NeMo Gym logging and payload overhead (#3106, #3292, #3390, #3918). - Cross-tokenizer distillation: lower memory and faster loss for top-k KD and x-token P-KL (#3314, #3564).
- Data plane: sync GRPO on the TransferQueue data plane with
mooncake_cpuwent from 21.5 s to 17.8 s per step, close to the 16.8 s without a data plane (#4580).
View the performance numbers from our published recipes in the performance summary.
🚫 Breaking Changes
DTensor v1 removed, and the DTensor backend is renamed to Automodel
In v0.4 we marked DTensorPolicy (v1) for deprecation. NeMo RL v0.8 removes it, and renames the remaining DTensor v2 backend to Automodel, after the NeMo Automodel library it is built on (#4198, #4270, #4273, #4276, #4282, #4283, #4277, #4701).
# v0.7                         # v0.8
policy:                        policy:
  dtensor_cfg:                   automodel_cfg:
    _v2: true    # delete          enabled: true
enabled: true- Rename
dtensor_cfgtoautomodel_cfginpolicy,value,teacher,teachers[i], andenv.reward_model, and delete_v2. The contents are unchanged. Old configs fail at startup with a message that names the fix. - DPO and RM users: check your backend. In v0.7,
_v2defaulted tofalse, anddpo.yamlandrm.yamldid not set it, so DPO and RM runs used DTensor v1 by default. In v0.8 they run on Automodel, which can change memory use, speed, numerics, and the checkpoint layout. - DTensor v1 checkpoints cannot be resumed in v0.8. Convert them to Hugging Face format with
examples/converters/convert_dcp_to_hf.pyfrom NeMo RL v0.7.x, then start from the HF weights. - Worker classes and modules are renamed (for example
DTensorPolicyWorkerV2→AutomodelPolicyWorker), thefsdpuv extra is removed, and recipe files withfsdp2ordtensorin their names now useautomodel(78 recipes; W&B run names change with them).
Other changes that need action
- Automodel checkpoint keys moved (#3935):
checkpointing.model_save_formatandcheckpointing.save_consolidatednow live underpolicy.automodel_cfg.checkpoint.save_consolidatedis now a string:"false","final", or"every"(oldtrue→"every"). Old keys raise an error at setup. - Fused-logprob keys renamed (#2833):
policy.megatron_cfg.use_linear_ce_fusion_loss→use_fused_linear_logprobs, andlinear_ce_fusion_chunk_size→fused_linear_logprobs_chunk_size. There is no startup check for the old names: a config that inheritssft.yamlordpo.yamlsilently runs with fusion off. - Megatron Inference (#3611, #3739, #3609):
mcore_generation_config.async_engineis removed; Megatron Inference always uses the async engine, and setup fails if the key is set. Non-colocated Megatron Inference now refits through NeMo RL's packed collective by default. To use Megatron-Core's own refit, setrefit_transport: mcore; thenvshmemrefit backend is broken and warns. - AIME eval dataset names (#2928):
aime2024,aime2025,aime2026are nowAIME2024,AIME2025,AIME2026. The old names fail with an unrelated file error. - Custom multi-reward environments (#2597) must return a dict of named rewards (
{"reward/<name>": Tensor}) instead of a[B, K]tensor. - Multimodal prompt fields (#3803):
vllm_images,vllm_audios, andvllm_videosare replaced by onevllm_multi_modal_datadict. This affects custom data processors and environments. - Data plane config (#2935):
data_plane.storage_capacityandnum_storage_unitsmoved underdata_plane.simple, andglobal_segment_sizeandlocal_buffer_sizemoved underdata_plane.mooncake_cpu. Old flat keys are silently ignored.mooncake_cpuis now RDMA-only (no TCP mode), and its default memory sizes are smaller. - SGLang (#3612): the HTTP weight-transfer path is removed, and non-colocated Automodel + SGLang is rejected at setup.
disable_outlines_disk_cachenow defaults totruebecause of a CVE (#4797). - Python config objects (#2518, #2526, #2527): inner algorithm configs are now pydantic models. Custom code that reads
master_config.grpo["key"]must use attribute access (master_config.grpo.key). YAML configs are unaffected. - Container: PyAV is no longer in the shipped image (#4184), joining
opencv-python-headless, which was removed in v0.7. Runbash tools/install_audio_deps.shif you need them.
Default changes
- Megatron async checkpointing (
megatron_cfg.checkpoint.async_save: true) anduse_gloo_process_groups: falseare now set in the base Megatron configs (#2828, #2746). policy.offload_policy_before_refitdefaults tofalse(#3300). Set it totrueif you run out of memory at refit.- Async GRPO fails on the first generation-worker error (
grpo.async_grpo.max_generation_failures: 0) instead of hanging (#2368). logger.wandb.log_nemo_gym_full_result_tablesdefaults tofalse; v0.7 logged these tables by default (#3000).- Router Replay now skips MTP-layer routers; set
NRL_ROUTER_REPLAY_EXCLUDE_MTP=0for the old behavior (#3903). - PPO advantages now leave out overlong-filtered samples from GAE, matching GRPO (#3262).
- Service ports moved below 9000, out of the kernel's ephemeral port range (#3103). Check firewall rules if your cluster restricts ports.
Notable Additions
- Full-vocabulary on-policy distillation:
on_policy_distillation.fulluses the exact full-vocabulary reverse KL instead of the sampled-token gap, with multiple teachers, on the Single Controller (#3978, #4045). See the MOPD algorithm page. - Managed Dynamo generation backend (
backend: dynamo) on Slurm (#3391). See the Dynamo guide. - SGLang: Megatron refit over NCCL for non-colocated SGLang rollouts, and opt-in engine fault tolerance (#3612, #3613).
- External vLLM service pools in the same Slurm allocation, for NeMo Gym judges (#3386, #3587).
- GDPO: per-reward weights (
grpo.adv_estimator.reward_weights) and multi-reward NeMo Gym environments (#2680, #2597). - Validation controls for GRPO:
grpo.val_start_at, validation-only sampling settings, grouped pass@k (grpo.val_num_generations_per_prompt), and early stop at a validation threshold (grpo.stop_at_validation_metric) (#3400, #3401, #3404). - Reward and advantage penalties for malformed NeMo Gym outputs (
reward_penalties.*), and an option to stop masking environment-flagged samples (env.should_mask_flagged_samples) (#2885, #3734, #3402). - EAGLE-3 draft training: sequence packing (about 2× policy training throughput on Qwen3-30B-A3B), a separate draft optimizer and grad clipping, and a streaming soft-CE loss (#3463, #3323, #3701, #3703, #3707). See the EAGLE-3 guide.
- LoRA: warm-start from a LoRA checkpoint (
lora_cfg.restore_from,peft.restore_from) and per-expert adapters (peft.share_expert_adapters) (#3874, #4234). See the LoRA guide. - More low-precision options: simulated KV-cache quantization in QARL (#3012), a TE precision config file for per-module quant recipes (#3654), custom FP8 quantizer factories (#3998), and an FP32 LM head (
fp32_lm_head) (#4096). - OpenTelemetry tracing through nemo-lens, off by default (#3655, #4052). See the observability docs.
- Mooncake on the data plane: RDMA backend, GPUDirect RDMA (
data_plane.mooncake_cpu.use_gdr), and data-plane checkpoints (#2935, #3501, #3898). VLM GRPO can also use the data plane (#2957). - vLLM refit options: refit through vLLM's
reload_weightsAPI (#3651, #4063), pausing generation during in-flight refit (#3839), and dropping colocated weights while asleep (discard_weights_on_sleep) to avoid host OOM (#4433). - Megatron config hooks:
megatron_cfg.model_overrides(#3535), custom worker extensions (worker_extension_cls_fqn) (#3809), andtokenizer_kwargs(#3798). - Container can run as a non-root user:
nemo-runtime(UID/GID 65532), with uv and its Python moved out of/root. The image still runs as root by default (#4260). - Fault-tolerance checkpoint retention:
ft_save_period/ft_keep_latest_k(#3157). - New datasets: NuminaMath-1.5 (#3417) and OpenR1-Math-220k (#3131).
- NeMo Gym is now the main evaluation path (#4687). See evaluation.
examples/run_eval.pystill works for quick checks. - Automodel context parallelism: refactored to use model-specific sequence sharding, with aligned loss inputs, automatic padding, and corrected gradient scaling (#3498). See the CP integration guide.
- First shipped in v0.8: the v0.7.0 release notes listed these PRs, but they merged after the v0.7 branch was cut, so v0.8.0 is the first release that contains them: MXFP8 rollouts (#1887), the Qwen2.5-Omni audio + video recipe (#2823), Megatron async checkpointing (#2828), chunked linear fusion for GRPO (#2833), behavior penalties (#2885), batched port discovery (#2920), Ray GCS tuning (#3089, #3158), port-range fixes (#3103), lower Automodel logprob memory (#3124), the OpenR1-Math-220k dataset (#3131), and fault-tolerance checkpoint retention (#3157).
- Major dependency upgrades: vLLM 0.20.0 → 0.29.0, PyTorch 2.13.0, Transformers 5.12.1, Ray 2.58.0, NeMo-Gym 0.4 → 0.7, NeMo-Automodel 0.6.1, Megatron-Bridge 0.7.0, NCCL 2.30.7, and Python 3.13.14 (#3280, #4080, #4415, #4828, #3498, #4852, #3453, #3183).
Notable Fixes
- Fixed GRPO advantage spikes (near −2075) when
use_leave_one_out_baselineandnormalize_rewardsare both on, which is the default ingrpo_math_1B.yaml. This mostly showed up on easy data where all but one sample in a group were correct (#4158). - Fixed token positions filtered out by top-k/top-p still counting in the loss and KL (#4154).
- Fixed refit sending stale weights: for Automodel non-colocated refit with large MoE experts (reward 0.1–0.2 before, 0.81 after on Nemotron 3 Nano Omni) (#4720), for Megatron with
overlap_param_gather(#4086), and for vLLM'sflashinfer_trtllmBF16 MoE backend (#3545, #3659). - Fixed the Automodel KL reference model moving to the resumed weights on every resume, instead of staying at the base weights (#3722).
- Fixed the Automodel MoE router correction bias being cast to BF16 during refit, which could change expert routing in vLLM (#3540).
- Fixed calibrated FP8 KV-cache scales being dropped on colocated refit (#3226), and GLM-5.2 FP8 sparse-attention scoring that made training and generation disagree (#4667).
- Fixed async GRPO skipping about 30% of prompts across checkpoint save and restore (#3599), ignoring
max_num_epochs(#3248), ignoringrecompute_kv_cache_after_weight_updateswithout in-flight updates (#3152), and deadlocking on resume (#3066). - Fixed
run_vlm_grpo.pyalways running sync GRPO even with async enabled (#3740). - Fixed EAGLE-3 draft gradients shrinking the policy update;
train/grad_normis now policy-only (#3323). - Fixed the Megatron optimizer updating random weights with CPU offload and the distributed optimizer (#2372), and gradient finalize being skipped for Nemotron Omni (#3789).
- Fixed wrong eval pass@k when an answer could not be parsed (#3635).
- Fixed a pipeline-parallel hang in MoE aux-loss metrics (#3419), a GPU memory leak after async checkpointing with colocated generation (#3322), and Mooncake port collisions with the kernel's ephemeral range (#4103).
- Fixed DeepSeek-V3 with Transformers 5 (#4408).
- Addressed security vulnerabilities and CVEs (#4343, #4415, #4736, #4766, #4885, #4924, #4970, #4988).
🛠️ Known Issues
- LoRA with activation checkpointing on Automodel: with
activation_checkpointing: true, the LoRA weights never reach vLLM, so rollouts come from the base model (#4470). Turn off activation checkpointing when using LoRA on Automodel. - vLLM async scheduling can hang large MoE runs with data parallelism (vllm-project/vllm#43547). The GLM-5.1 and Qwen3.5-397B recipes set
policy.generation.vllm_kwargs.async_scheduling: falseto avoid it (#4354, #4794). Use the same setting if a large MoE run with vLLM DP > 1 hangs in generation. - Qwen3.5 MoE with the Megatron backend and expert parallelism can still hang in vLLM's
sample_tokens(vllm-project/vllm#36237). The Automodel path no longer hangs after the vLLM upgrade. - Quantized Nemotron 3 Super NVFP4 (W4A16/W4A4) recipes currently fail (#4585).
- Automodel cannot load Nemotron-H checkpoints because of an embedding key name mismatch (#4211). This waits on an Automodel update.
What's Changed
- chore: bump Gym workspace to 610a08ab by @kajalj22 in #2970
- fix: bump prometheus-fastapi-instrumentator>=8.0.2 for fastapi>=0.137 compat by @kajalj22 in #2960
- refactor(rm): migrate RMConfig, RMSaveState, RMValMetrics to BaseModel by @NolenLiang in #2526
- fix: avoid nvidia-cutlass-dsl install race + fix dsv3 gb200 perf test by @yuki-97 in #2982
- feat: add Mistral Medium 3.5 (128B) text-only DAPO support by @sharonyu-115 in #2875
- fix: Add missing variables in mopd nightly by @yfw in #2966
- refactor: handle GDPO multi-reward by dict instead of positional list by @NolenLiang in #2597
- fix: allow router replay trace fallback composition by @zyzhou5 in #2963
- ci: Add super nightly tests by @ashors1 in #2855
- fix: reduce NUM_MINUTES to match 04:00:00 CI walltime in 2 test scripts by @kajalj22 in #2993
- fix: tune small scale super configs for h100 by @macandro96 in #2965
- fix(deepscaler): disable vLLM rotary_embedding custom op in DeepScaler recipes by @NolenLiang in #2981
- fix(grpo_sync): skip refit for colocated MegatronGeneration by @ZhiyuLi-Nvidia in #2967
- fix: WAR for Perf test failing with NCCL error by @RayenTian in #2986
- chore: make ppo default to dtensor to keep consistent with other algos by @yuki-97 in #2974
- feat(xtoken): multi-teacher support for cross-tokenizer off-policy distillation by @avenkateshha in #2797
- docs(mopd): fix dataset override key data.val -> data.validation by @qiaochuz-nv in #2991
- feat: R3 gym notq router replay by @zyzhou5 in #2915
- test: disable flaky grpo-qwen3.5-35ba3b-2n8g-automodel-ep16 nightly by @zpqiu in #3020
- chore: loosen metric in cispo nightly by @yuki-97 in #3026
- ci: use NVIDIA inference for Claude review by @chtruong814 in #3033
- ci: fix grpo-nanov3-30BA3B-2n8g-megatron_generation.yaml config by @ashors1 in #3017
- fix: fix grpo-gspo-deepscaler-1.5b-8K and tighten thresholds by @yuki-97 in #3029
- feat: video + audio understanding GRPO training recipe by @yuekaizhang in #2823
- fix: (qwen3-omni) disable vLLM sequence_parallel_chunk custom op by @yuekaizhang in #3021
- fix: Keep QARL nightlies schedulable on H100 nodes by @mxinO in #3018
- ci: use PAT for code-freeze branch push by @kajalj22 in #3031
- ci: bump NUM_MINUTES +20% for 3 nightly tests hitting Slurm timeout by @kajalj22 in #3049
- docs: X-Token multiteacher example by @sharathts in #3035
- ci: NVFP4 W4A16 nightly tests by @HollowMan6 in #3032
- fix: fix grpo-gemma3-27b-it-8n4g-fsdp2tp4-actckpt-long by @yuki-97 in #3044
- perf: batch worker port discovery by @macandro96 in #2920
- refactor(ppo): reuse LossPostProcessor in value worker + add offload_to_cpu by @bg51717 in #2980
- fix: WAR for grpo-qwen3-235b-16n4g crush by @RayenTian in #3030
- feat: add multiple penalties for model behaviour by @macandro96 in #2885
- fix(megatron): prefer nvrx strategy for HF import saves by @jinglinglingling in #2989
- feat: Support Chunked Linear Fusion for GRPO by @pengdurice in #2833
- fix: fix segment_size in gb200 tests by @yuki-97 in #3069
- ci: fix super environment tests by @ashors1 in #3046
- fix: fix sft-llama3.1-70b-8n8g-tp4pp2-long-megatron by @yuki-97 in #3073
- ci: reduce number of steps for glm5.1 test case by @slikhite-1 in #3077
- fix: cap dapo-deepseek-v3-64n8g perf test NUM_MINUTES at 240 (cluster limit) by @kajalj22 in #3052
- perf: reduce srun overhead in ray.sub and gate driver on sandbox readiness by @ananthsub in #2827
- chore: bump Gym submodule to v0.4.0 by @kajalj22 in #3076
- perf: reduce Qwen3 logprob batch size by @NolenLiang in #3093
- ci: Add nightly GB200 super test by @ashors1 in #3016
- fix: update super recipes for gym bump by @yfw in #2996
- feat: expose
use_gloo_process_groupstoggle for megatron policy workers by @ananthsub in #2746 - feat: auto-detect CPUS_PER_WORKER from Slurm in ray.sub by @terrykong in #2943
- test: add vLLM HTTP logprobs contract test for NeMo-Gym capture by @ananthsub in #2845
- perf: tune Ray GCS server configs for burst tolerance at scale by @ananthsub in #3089
- docs: update CUDA 12 references to CUDA 13 as primary supported version by @kajalj22 in #3086
- feat: MXFP8 rollout support by @guyueh1 in #1887
- fix: fix grpo-deepscaler-1.5b-24K by @yuki-97 in #3097
- chore: update deepscaler nightly metric to avoid flaky by @yuki-97 in #3114
- feat(megatron): split-API train-step state machine on MegatronPolicyWorker by @mehraakash in #2683
- chore: fix CVEs in opencv, av, wandb; tighten setuptools build floor by @kajalj22 in #3085
- fix: fix grpo-qwen2.5-1.5B-4n8g-megatron-yarn-256k by @yuki-97 in #3098
- fix(checkpoint): break metric ties by recency in get_best_checkpoint_path by @tianyi-zhang-02 in #3071
- feat: Add script to re-initialize near-zero HF embeddings by @ashors1 in #2671
- fix: [NemoRL] Disable expensive Gym logging to reduce inter-step inefficiency by @saumishr in #3106
- feat: ThreadSafeTimer, container init timing, and Ray telemetry by @saumishr in #2916
- feat: Numa aware binding by @youngeunkwon0405 in #2613
- fix: un-blocklist deepseek_v3 in transformers tokenizer class set by @ZhiyuLi-Nvidia in #3116
- fix: stop scaling scontrol RPCs with node count in ray.sub CPU detection by @terrykong in #3132
- fix: Update Super SWE test config by @ashors1 in #3126
- fix: fix fp8 hf_config_overrides bug by @ashors1 in #2904
- perf: perf recipe changes to enable force on policy ratio by @seonjinn in #3135
- docs: fix stale references and typos for NVBug 6436630 by @qiaochuz-nv in #3147
- feat: async checkpointing for Megatron policy workers by @ananthsub in #2828
- feat(megatron): add MFU reporting for Megatron training workers by @achartier in #2790
- fix(async-grpo): starvation diagnostics, gym logging, and dataloader exhaustion by @saumishr in #2917
- fix: Port contention issues between Ray/vLLM/Gym and sandbox workers by @saumishr in #3103
- refactor(eval): route AIME eval through the response dataset registry by @NolenLiang in #2928
- fix: fix dapo-deepseek-v3-64n8g.v2 and dsv3 tokenizer by @yuki-97 in #3154
- perf: reduce selected-token logprob memory by @mohamed-alansary in #3124
- fix(grpo): pin inference_optimized config for newer Megatron-Core images by @shanmugamr1992 in #3150
- fix: zero router aux loss in Qwen3.5 automodel recipes by @zpqiu in #3169
- feat(grpo): mask env-flagged samples from policy loss by @macandro96 in #3163
- fix(ppo): restore optimizer state on checkpoint resume by @bg51717 in #3171
- fix: ensure unique TOPO_RANK per node by @yuki-97 in #3178
- fix: skip RayVirtualCluster.shutdown when Ray already torn down by @ZhiyuLi-Nvidia in #3148
- fix: use staged SWE1 data in nightly recipe by @zyzhou5 in #3145
- feat(algorithms): SingleController streaming train_pump (split-API consumer) by @mehraakash in #2700
- feat: add OpenR1-Math-220k response dataset by @tianyi-zhang-02 in #3131
- feat: fault-tolerance checkpoint retention (ft_save_period / ft_keep_latest_k) by @ananthsub in #3157
- refactor(sglang): allocate ports from reserved ranges by @xiuhu17 in #2997
- fix: add vLLM config context during collective refit by @snowmanwwg in #3168
- fix: Fix mtp metrics scale and mtp grad norm logging by @yfw in #3194
- test: increase NUM_MINUTES to 85 for grpo-nanov3-30BA3B-2n8g-fsdp2-lora by @kajalj22 in #3202
- docs: add Docker Quickstart to installation guide and README by @kajalj22 in #3084
- fix: fix rollout metrics fail in unit test by @yuki-97 in #3173
- feat: add phase timing markers to ray.sub for diagnosing startup stalls by @terrykong in #3209
- fix: fix OpenR1-Math-220k unit test by @yuki-97 in #3212
- fix: handle inflated packed sequence lengths in input-id packing by @macandro96 in #3182
- ci: add JOB_REAPER_COMMENT support to tools/launch and super-rlvr recipe by @kajalj22 in #3184
- build: pin Apptainer installer to 1.4.5 by @yfw in #3221
- fix: Fix gym vllm version in super doc by @yfw in #3228
- fix: revert max_concurrency and label fast by @yuki-97 in #3218
- ci: increase sft-nanov3-30BA3B-2n8g-fsdp2-lora timeout to 45min by @kajalj22 in #3234
- perf(ray.sub): tune GCS for large-scale multi-node init bursts by @ananthsub in #3158
- ci: Nemotron3-Super Perf Recipe by @parthmannan in #3207
- fix(vllm): assign node-local VLLM_PORT for cross-node model parallelism by @ananthsub in #3159
- test: unset CI env var in audiomcq VLM GRPO test by @kajalj22 in #3232
- fix: improve error message when NeMo Gym returns no generation data by @yfw in #2918
- feat(megatron): add nccl refit backend for non-colocated generation by @shanmugamr1992 in #3166
- ci: fix super rlvr test by @ashors1 in #3246
- ci: bump async-gym megatron test wall-clock budget to 120 min by @shanmugamr1992 in #3258
- feat: size routed_experts carry dtype from the model's expert count by @zyzhou5 in #3113
- fix: preserve runtime tools after arm64 Apptainer build by @kajalj22 in #3253
- chore: replace decord2 with torchvision/torchaudio for media loading by @kajalj22 in #3107
- chore: bump cryptography, pillow, and mooncake to address CVEs by @kajalj22 in #3230
- feat: add delta-compressed collective refit by @HollowMan6 in #2444
- feat(modelopt): support real NVFP4 QAT rollout for MoE and Mamba by @HollowMan6 in #2983
- fix(vllm): record logprob for the sampled token by @HollowMan6 in #3297
- feat: add checkpoint-engine refit interface and integrate NIXL by @HollowMan6 in #2608
- fix: fix optimizer step working on random initialized model weights by @pengdurice in #2372
- feat: configurable GDPO per-reward weights and multi-reward NeMo Gym bridge by @anjalibshah in #2680
- ci: AUT-895 gate GB200 tests on DISABLE_GB200_TESTS variable by @svcnemo-autobot in #3269
- perf: increase Qwen3-235B async rollout GPU memory utilization on H100 by @humairafirdowse18 in #3278
- feat(grpo): stream rollout batches by prompt group by @yfw in #3000
- feat: GDPO vs GRPO multi-reward example and collapse demo by @anjalibshah in #2681
- feat(vllm): MTP spec dec inference for nemotron super/ultra with refit drafter by @yfw in #2999
- feat(sc): rollout path — TQReplayBuffer, rollout_manager, _rollout_pump by @yuki-97 in #3219
- fix: forward calibrated KV cache scales on colocated ZMQ IPC refit path by @babyplutokurt in #3226
- fix(async-grpo): add startup barrier to prevent checkpoint-resume deadlock by @snowmanwwg in #3066
- fix(test): pass required NeMo Gym rollout arguments by @joyang-nv in #3317
- feat(generation): add TensorRT-LLM rollout backend by @shuyixiong in #2420
- feat(sc): train path — StalenessSampler + _train_pump rewrite by @yuki-97 in #3220
- feat: Adding fast token by @arnavk-nvidia in #3181
- chore: Bump Gym by @yfw in #3326
- perf: speed up TransformerEngine source builds by @joyang-nv in #3333
- feat(sc): setup + entrypoint by @yuki-97 in #3266
- feat(sc): NeMo-Gym path by @yuki-97 in #3267
- test(functional): relax grpo_topp_topk gen_kl_error bound 0.03 -> 0.032 by @terrykong in #3341
- build: exclude opencv-python-headless from shipped container by @kajalj22 in #3339
- feat(trtllm): support agentic training for SWE rollout by @hchings in #3130
- chore: Bump Gym by @yfw in #3343
- docs: add Qwen3.5 model guide and model-family hub by @sharonyu-115 in #2900
- chore: unify setup nemogym by @yuki-97 in #3360
- fix(data): warn when behavioral dataset config keys are silently ignored by @tianyi-zhang-02 in #3271
- fix(grpo_sync): honor force_on_policy_ratio in TQ trainer by @ZhiyuLi-Nvidia in #3087
- fix: backward compatibility in mcore by @shanmugamr1992 in #3377
- feat: NCCL-Reshard refit merge PR (final) by @youngeunkwon0405 in #2971
- fix(async): Always honor recompute_kv_cache_after_weight_updates by @jepio in #3152
- build: install megatron-bridge from submodule; auto-flow its deps on bump by @terrykong in #3235
- fix(megatron): request processed logprobs by @tdene in #3392
- fix: reserve MOPD teacher clusters before Gym startup by @yfw in #3340
- feat: ultra recipes for gb200 by @macandro96 in #3276
- chore(ci): AUT-1178 pin GitHub Actions to commit SHAs by @svcnemo-autobot in #3420
- fix: eliminate JSON serialization bottleneck in r3 + NeMo-Gym rollouts by @zyzhou5 in #3292
- perf: avoid CPU round trip during NVFP4 refit by @seonjinn in #3308
- fix: Megatron async checkpoint CUDA memory retention by @NolenLiang in #3322
- refactor(distillation): migrate DistillationConfig, DistillationSaveS… by @NolenLiang in #2527
- fix(eagle3): isolate draft grad clipping by @yuekaizhang in #3323
- feat(grpo): add val_start_at to delay periodic validation by @michal2409 in #3400
- docs: warn about ray.sub dependency drift and container-rebuild fix by @achartier in #3247
- build: bump vllm 0.20.0 → 0.25.1 by @terrykong in #3280
- docs(ultra): remove obsolete v5->v4 checkpoint conversion section by @macandro96 in #3433
- chore: update NCCL to 2.30.4 via uv override by @yfw in #3352
- feat(grpo): make env-flagged sample masking optional by @michal2409 in #3402
- feat(sc): support router replay with TQ by @zyzhou5 in #3378
- feat(gym): add Ultra environment prefetch config by @yfw in #3452
- chore(ci): AUT-1231 bump preflight workflow template by @svcnemo-autobot in #3460
- feat(grpo): optional early stop at a validation metric threshold by @michal2409 in #3404
- fix(trtllm): Add TRTLLM SWE training example, update refit APIs by @hchings in #3418
- fix(sc): log config parameters to W&B by @RayenTian in #3465
- perf(loss): avoid full-vocab student log-softmax in same-vocab top-k KD by @tianyi-zhang-02 in #3314
- fix(data): honor subset on GSM8KDataset and correct the val-split docs by @tianyi-zhang-02 in #3389
- fix: Fix trtllm CI test, enable TRTLLM in LFast by @hchings in #3479
- feat(ray): support a dedicated gpu-free head node by @macandro96 in #3388
- refactor(grpo): migrate TypedDict configs to pydantic BaseModel by @NolenLiang in #2518
- ci: Debug the MBridge bump by @tdene in #3385
- chore(ci): AUT-1298 bump community workflow to v1.8.7 by @svcnemo-autobot in #3475
- perf(logprob): skip the softmax materialization on the inference path by @tianyi-zhang-02 in #3484
- chore: loosen L1 eval upper bound to avoid flaky in CI by @yuki-97 in #3491
- chore: upgrade Python to 3.13.14 by @kajalj22 in #3183
- test(nightly): fix mcore async-gym test by @tdene in #3398
- fix(megatron): enable mcore colocated to use Gym by @tdene in #3406
- feat: add NuminaMath-1.5 response dataset by @tianyi-zhang-02 in #3417
- feat: Order packed microbatches largest-first per DP rank by @wdykas in #3476
- feat(nemotron-omni): add Megatron Nano image GRPO support by @aroshanghias-nvd in #3290
- feat: nccl v2.30.7 bump by @youngeunkwon0405 in #3453
- perf(megatron): skip redundant weight load by @tdene in #3397
- fix(nemo-gym): refresh final-token route across turns by @zpqiu in #3485
- feat(slurm): support external vLLM services in one allocation by @yfw in #3386
- feat(ppo): support non-colocated generation by @bg51717 in #3262
- feat(grpo): validation-only sampling params and grouped pass@k validation by @michal2409 in #3401
- feat: Multimodal nemo gym compatible grpo pipeline by @rohitrango in #3414
- fix: Reconcile #2315 and #2612 by @tdene in #2902
- chore: bump TQ to v0.19 by @macandro96 in #3423
- feat(sc): overlap NeMo-Gym spinup with deferred vLLM load by @yuki-97 in #3499
- perf(vllm): return token metadata with chat completions by @jthomson04 in #3390
- feat(ultra): serve GenRM and NL2Bash as external vLLM pools by @macandro96 in #3529
- fix(async-grpo): fail fast on generation worker errors by @jthomson04 in #2368
- feat: Add recipes by @yfw in #3549
- feat(gym): bump Gym and add Omni venv prefetch by @yfw in #3541
- feat: add single controller doc and gb200 nightly tests by @yuki-97 in #3427
- feat: upstream wandb script by @youngeunkwon0405 in #3222
- fix(trtllm): Align HTTP server sampling params, use generate_async by @shuyixiong in #3537
- feat: Simulated KV cache QARL by @mxinO in #3012
- feat(grpo): deduplicate multimodal payloads by @aroshanghias-nvd in #3527
- feat(megatron): support model config overrides by @CarlosGomes98 in #3535
- perf(vllm): batch MXFP8 MoE refit shuffles by @seonjinn in #3478
- ci: bump Megatron-Bridge to 0c565c9a0 by @tdene in #3568
- feat(sc): abort stale in-flight rollouts early in non Gym path by @RayenTian in #3263
- feat: add nano-v3.5 dapo recipe using automodel backend by @yuekaizhang in #3383
- docs: add review-pr-team contributor skill for multi-agent PR review by @terrykong in #3133
- perf(external-vllm): remove startup preflights by @yfw in #3587
- feat(sc): add checkpoint save/restore to SingleController by @haitian-nvidia in #3429
- ci: AUT-1501 bump SSO preflight to v1.8.10 by @svcnemo-autobot in #3621
- fix: make nccl_reshard_refit_info wire-safe for the generation-worker. by @youngeunkwon0405 in #3618
- feat(vlm): Nemotron Super Omni GRPO with MTP under context parallelism by @DanialTaheri in #3494
- fix: gate MTP layers from the nccl-reshard bulk refit path by @youngeunkwon0405 in #3619
- fix: model save directly after validation by @tdene in #3605
- fix: skip the HF refit-info handshake for MInf by @tdene in #3607
- docs: copy nemotron model guides into guides/ with deprecation notice by @yuekaizhang in #3637
- feat(sc): contain rollout failures in the SingleController path by @terrykong in #3589
- ci: AUT-1111 support arbitrary Megatron-LM commits by @chtruong814 in #3640
- feat(megatron): expose training CUDA Graph config by @seonjinn in #3483
- perf: support fine-grained activation offloading by @seonjinn in #2279
- fix: remove the mcore async_engine flag by @tdene in #3611
- fix: Add torch-memory-saver to the mcore extra deps by @tdene in #3602
- chore: gitignore unit test result artifacts by @VishnuR23 in #3679
- fix: ensure base configs don't use nvshmem refit by @tdene in #3609
- feat(mopd): add Super Omni multimodal distillation by @nvilia in #3430
- ci(tests): add nightly_mlm test suite by @kajalj22 in #3657
- docs: document token_level_loss in the GRPO guide by @terrykong in #3656
- ci: Bump Megatron-Bridge to 8c46dc42 by @yfw in #3658
- feat: colocated Megatron reshard by @tdene in #3490
- feat(megatron): support fractional optimizer CPU offload by @seonjinn in #3628
- feat(sc): track generation fleet health and route NeMo-Gym through NeMo-RL by @terrykong in #3590
- feat(vlm): carry a media-token validity mask through sequence packing by @DanialTaheri in #3631
- feat(sc): add ready-first staleness sampler by @haitian-nvidia in #3582
- fix(sc): reduce and finalize gradients once per step, not per chunk by @saumishr in #3660
- fix(gym): hold the tokenizer in NemoGym instead of passing it per rollout by @saumishr in #3668
- feat(dynamo): add managed Slurm generation with W&B telemetry by @jthomson04 in #3391
- fix: fix missing tokenizer in unit test by @yuki-97 in https://github.com/NVIDIA-NeMo/RL/pull/3717
- feat(sc): tolerate and replace dropped rollouts in the SingleController by @saumishr in #3665
- docs: add recent news updates to README by @snowmanwwg in https://github.com/NVIDIA-NeMo/RL/pull/3688
- feat(refit): support BF16 to MXFP8 NCCL reshard by @seonjinn in #3477
- feat(ppo): support async ppo by @bg51717 in #3410
- perf(xtoken): project only the top-k teacher columns in P-KL by @tianyi-zhang-02 in #3564
- fix(vlm): dispatch async GRPO from VLM entrypoint by @youngeunkwon0405 in #3740
- feat(video): add Gym support for sync and async GRPO - v2 by @ehosseiniasl in #3648
- docs: nest model guides under their family hubs in the nav tree by @sharonyu-115 in https://github.com/NVIDIA-NeMo/RL/pull/3645
- fix(nemo-gym): honour pad_dynamic_image_shapes on the dedup prompt path by @DanialTaheri in https://github.com/NVIDIA-NeMo/RL/pull/3702
- fix(math-env): one score per sample when answer extraction fails by @tianyi-zhang-02 in #3635
- feat: async colocated GRPO with Megatron inference by @tdene in #2884
- fix(sc): mask sequence logprob outliers by @mehraakash in https://github.com/NVIDIA-NeMo/RL/pull/3671
- fix(fp8): support Qwen3.5 blockwise FP8 rollout and training by @MarkXCloud in #2744
- fix: prevent PP hang in MoE aux-loss metric reduction by @dafu-wu in #3419
- fix: guard tokenizer save with rank 0 to avoid NFS deadlock by @dafu-wu in https://github.com/NVIDIA-NeMo/RL/pull/3504
- fix(grpo): correct sequence importance ratio metric by @CarlosGomes98 in https://github.com/NVIDIA-NeMo/RL/pull/3753
- feat(data_plane): mooncake cpu rdma backend by @ZhiyuLi-Nvidia in #2935
- fix(sc): skip reference logprobs when KL is disabled by @RayenTian in https://github.com/NVIDIA-NeMo/RL/pull/3771
- perf(data): parallelize NeMo Gym image encoding by @youngeunkwon0405 in https://github.com/NVIDIA-NeMo/RL/pull/3721
- fix(logging): aggregate rollout histograms before logging by @yfw in https://github.com/NVIDIA-NeMo/RL/pull/3748
- fix(gym): make the gym venv prefetch dry run pass again by @yfw in https://github.com/NVIDIA-NeMo/RL/pull/3785
- feat: Pass tokenizer_kwargs to AutoTokenizer.from_pretrained by @pstjohn in #3798
- fix(async-grpo): eliminate prompt skips across checkpoint save/restore by @yfw in #3599
- feat(gym): apply effort-level reward shaping in the SingleController by @RayenTian in https://github.com/NVIDIA-NeMo/RL/pull/3770
- fix(dtensor-v2): keep the KL reference anchored to base weights across resumes by @yuekaizhang in #3722
- feat: overlap NeMo-Gym spinup with MInf load by @tdene in #3569
- fix: Megatron Inference colocated CUDA graphs by @tdene in #3718
- fix(megatron): install finalizer on runtime model config by @rohitrango in #3789
- feat(sc): support PPO in single controller by @yuki-97 in #3773
- fix(vllm): support native BF16 FlashInfer TRTLLM refit by @seonjinn in #3545
- feat(sglang): megatron backend weight refit for sglang rollouts by @Kh4L in #3612
- feat(megatron): support MXFP8 inference and BF16-to-MXFP8 refit by @wdykas in #3731
- fix: preserve fp32 router correction bias during refit by @fujial-code in #3540
- fix(vllm): correct MXFP8 rollout quantization scope by @seonjinn in #3652
- perf(recipes): add optimized Super Omni GRPO recipe by @youngeunkwon0405 in https://github.com/NVIDIA-NeMo/RL/pull/3805
- feat: add MOPD to single-controller text path by @yfw in #3768
- fix: non-contiguous top-p logits and null keep_top_k by @mferrato in https://github.com/NVIDIA-NeMo/RL/pull/3709
- ci: move Megatron-Bridge to d352aced by @tdene in https://github.com/NVIDIA-NeMo/RL/pull/3824
- fix(sc): set step_finished=True in async GRPO logging by @RayenTian in https://github.com/NVIDIA-NeMo/RL/pull/3816
- fix(megatron): hotfix disable offending tests by @tdene in https://github.com/NVIDIA-NeMo/RL/pull/3871
- ci: AUT-2165 trigger approval queue when CICD completes by @svcnemo-autobot in https://github.com/NVIDIA-NeMo/RL/pull/3877
- fix(grpo): apply effort shaping to async Gym rollouts by @yfw in https://github.com/NVIDIA-NeMo/RL/pull/3885
- ci: AUT-2161 route external jobs through ephemeral v2 by @svcnemo-autobot in https://github.com/NVIDIA-NeMo/RL/pull/3863
- fix(ci): set CUDA major for torch-memory-saver lock generation by @balasaajay in https://github.com/NVIDIA-NeMo/RL/pull/3862
- feat(glm): add GLM 5.1 and 5.2 support by @slikhite-1 in #3502
- feat(vllm): pause generation during in-flight refit by @youngeunkwon0405 in #3839
- perf: overlap non-colocated MInf + polict init by @tdene in https://github.com/NVIDIA-NeMo/RL/pull/3864
- feat(sc): keep training when a generation shard dies by @terrykong in #3591
- feat(ppo): warm-start the value model from a critic-pretrain checkpoint by @yuki-97 in #3821
- docs: Update performance numbers for v0.7 release by @parthmannan in https://github.com/NVIDIA-NeMo/RL/pull/3779
- feat(telemetry): add nemo-lens instrumentation and efficiency buckets by @rrs45 in #3655
- feat(sc): support non-colocated MInf by @tdene in #3727
- feat: log toolcall and thinktag violation rate into single controller by @arnavk-nvidia in https://github.com/NVIDIA-NeMo/RL/pull/3765
- build(automodel): bump Automodel to r0.6.0 by @jQizhang in #3498
- fix(ci): set TMS_CUDA_MAJOR via uv extra-build-variables by @kajalj22 in https://github.com/NVIDIA-NeMo/RL/pull/3905
- feat(sc): recover replay buffer from native TQ checkpoints by @macandro96 in #3480
- fix: plumb fp8_recipe into OptimizerConfig for fp8_param runs by @seonjinn in https://github.com/NVIDIA-NeMo/RL/pull/3281
- feat(megatron): support te precision config recipes by @guyueh1 in #3654
- fix(async): preserve rollout lookahead on resume by @yfw in https://github.com/NVIDIA-NeMo/RL/pull/3435
- feat(sc): apply reward penalties to Gym rollouts by @macandro96 in https://github.com/NVIDIA-NeMo/RL/pull/3741
- fix(vllm): apply FP8 patches with RayExecutorV2 by @zpqiu in https://github.com/NVIDIA-NeMo/RL/pull/3754
- feat(models): add Qwen3.8-27B Megatron support by @zpqiu in #3678
- fix(vllm): replace fastokens-b10 with fastokens by @guyueh1 in https://github.com/NVIDIA-NeMo/RL/pull/3799
- feat(grpo): support message penalties in single controller by @macandro96 in #3734
- feat(ppo): decouple actor and critic training epochs by @bg51717 in #3829
- fix(sc): gate reference logprobs on KL penalty by @jinglinglingling in https://github.com/NVIDIA-NeMo/RL/pull/3742
- fix(ci): Fix L1 on main by @tdene in https://github.com/NVIDIA-NeMo/RL/pull/3949
- feat(draft): support sequence packing with online eagle3 draft training by @yuekaizhang in #3463
- ci: Bump Megatron-Bridge to b11414c7 by @kajalj22 in https://github.com/NVIDIA-NeMo/RL/pull/3906
- feat(sc): log rollout and speculative decoding metrics by @yfw in https://github.com/NVIDIA-NeMo/RL/pull/3883
- fix: isolate SingleController service port ranges by @yfw in https://github.com/NVIDIA-NeMo/RL/pull/3884
- fix(grpo): support environment sample masking in single controller by @macandro96 in https://github.com/NVIDIA-NeMo/RL/pull/3766
- perf: enable HybridEP on H100/B200 x86 systems by @seonjinn in #3436
- build: mount token secret for apptainer dependency download by @kajalj22 in https://github.com/NVIDIA-NeMo/RL/pull/3860
- fix(ci): Fix #3589's test broken by #3883 by @tdene in https://github.com/NVIDIA-NeMo/RL/pull/3967
- feat(mcore-inference-multimodal): Support multimodal Megatron inference. by @cspades in #3920
- fix(sc): apply advantage clipping and overlong filtering by @yfw in https://github.com/NVIDIA-NeMo/RL/pull/3927
- fix(grpo): honor max_num_epochs in async training by @abhinav-bellapu in #3248
- fix: consolidate Megatron Inference tests by @tdene in https://github.com/NVIDIA-NeMo/RL/pull/3570
- perf: compute selected token logprobs directly by @CarlosGomes98 in #3930
- fix(sc): retain rollout metrics through training by @yfw in https://github.com/NVIDIA-NeMo/RL/pull/3880
- feat(megatron): support MTP in split training by @yfw in https://github.com/NVIDIA-NeMo/RL/pull/3881
- fix(vllm): make threaded HTTP generation async-safe by @jepio in https://github.com/NVIDIA-NeMo/RL/pull/3968
- refactor(nemo-gym): centralize actor construction by @ananthsub in https://github.com/NVIDIA-NeMo/RL/pull/3367
- feat(vlm): route VLM GRPO through TQ trainer when data_plane.enabled by @ZhiyuLi-Nvidia in #2957
- fix(megatron): disable router replay in MTP layers by @guyueh1 in #3903
- fix: handle symlinked Transformers module cache by @jQizhang in https://github.com/NVIDIA-NeMo/RL/pull/3914
- feat(sc): gate-authoritative token capture via an external TransferQueue sink by @pthombre in #3837
- feat: Refit with vLLM reload_weights API by @guyueh1 in #3651
- ci: Bump Megatron-Bridge to 5ed9799 by @cspades in https://github.com/NVIDIA-NeMo/RL/pull/4022
- feat(sft): add SFT v2 stage 1 with the Energon multimodal data path by @rohitrango in #3917
- fix(dtensor): keep v1 model loading on Transformers classes by @jepio in https://github.com/NVIDIA-NeMo/RL/pull/3997
- feat(fp8): pass custom quantizer factory to MCore by @jepio in #3998
- fix(vllm): return HTTP 400 for chat completion context overflow by @jepio in https://github.com/NVIDIA-NeMo/RL/pull/3844
- feat(mllm-v2): Support single-controller for Megatron-Inference. by @cspades in #4009
- fix: resolve HybridEP sequence packing padding by @seonjinn in https://github.com/NVIDIA-NeMo/RL/pull/2964
- fix(tq): install the scalar schema patch at import, not per client by @ZhiyuLi-Nvidia in https://github.com/NVIDIA-NeMo/RL/pull/4024
- fix: honor NEMO_RL_PY_EXECUTABLES_SYSTEM for all actor environments by @yuki-97 in https://github.com/NVIDIA-NeMo/RL/pull/4020
- fix: prevent OOM in Automodel recipes by @jQizhang in https://github.com/NVIDIA-NeMo/RL/pull/4034
- feat(mpo): add Nemotron Omni Nano and Super training by @jinglinglingling in #3345
- feat(gemma4): add CP recipes and 12B support by @sharonyu-115 in #3911
- feat(sc): sibling level rollout checkpointing at train boundary by @macandro96 in #3923
- fix: AUT-2228 route partial reruns to the current attempt by @svcnemo-autobot in https://github.com/NVIDIA-NeMo/RL/pull/4048
- feat(sc): periodic rollout checkpointing by @macandro96 in #3924
- refactor(docker): read the actor venv list from a Python leaf module by @terrykong in https://github.com/NVIDIA-NeMo/RL/pull/4002
- test: [2/3] add L2 Gym-to-RL rollout acceptance by @yaoyu-33 in https://github.com/NVIDIA-NeMo/RL/pull/4014
- feat(sc): support colocated MInf by @tdene in #3730
- build: enable multi-node HybridEP in container images by @seonjinn in #4038
- perf(grpo): make non-colocated refit offload optional by @wdykas in #3300
- feat(workers): Add config-driven worker extension FQNs by @pstjohn in #3809
- feat: add lora warm-start by @pstjohn in #3874
- fix(vllm): support BF16 TRTLLM NCCL reshard refit by @seonjinn in #3659
- feat(data_plane): add Mooncake GDR support by @zyzhou5 in #3501
- fix(docker): Gym venv reconciliation by @tdene in https://github.com/NVIDIA-NeMo/RL/pull/4050
- perf: enable HybridEP in H100/B200 performance recipes by @seonjinn in #3438
- feat(mopd): add full-vocabulary on-policy distillation to SingleController by @RayenTian in #3978
- feat(megatron): expose mcore inference async_sched_mode and cover it by @shanmugamr1992 in #3762
- feat(mllm): Changes to properly support latest Megatron Inference Features by @ArEsKay3 in #3912
- feat(megatron): add nccl_reshard M-to-N refit for Megatron generation by @wdykas in #3739
- fix(nemo-gym): define actor failure and teardown ownership by @ananthsub in https://github.com/NVIDIA-NeMo/RL/pull/3368
- perf(gym): keep health checks off rollout event loop by @ananthsub in #3918
- feat(sc): telemetry for rollout checkpointing by @macandro96 in #3925
- fix(data-plane): move mooncake's ports out of the ephemeral range by @saumishr in #4103
- feat(nemo-gym): expose resolved config entries by @ananthsub in https://github.com/NVIDIA-NeMo/RL/pull/3633
- feat(sc): wire refit_with_reload_api into v2 entrypoint by @guyueh1 in #4063
- ci: AUT-2286 add approve-test-queue concurrency group by @svcnemo-autobot in https://github.com/NVIDIA-NeMo/RL/pull/4121
- fix(megatron): Handle MTP position_ids correctly by @tdene in https://github.com/NVIDIA-NeMo/RL/pull/4098
- feat: add DeepSeek V4 Flash GRPO support - Automodel path by @zpqiu in #3595
- feat(sc): restart dead generation shards and re-admit them at the next refit by @terrykong in #3592
- fix: select Gym environment for rollout reassembler actors by @pthombre in https://github.com/NVIDIA-NeMo/RL/pull/4112
- ci: AUT-2320 cancel stale approval queue runs by @svcnemo-autobot in https://github.com/NVIDIA-NeMo/RL/pull/4132
- fix(megatron): synchronize parameters before inference refit by @wdykas in #4086
- fix(genrm): propagate prompt cohort retry identity by @macandro96 in https://github.com/NVIDIA-NeMo/RL/pull/3861
- feat(vllm): generalize multimodal prompt data by @pstjohn in #3803
- fix(vlm): forward image payloads in async rollouts by @jinglinglingling in https://github.com/NVIDIA-NeMo/RL/pull/4113
- feat(nemo-gym): define shard configuration by @ananthsub in https://github.com/NVIDIA-NeMo/RL/pull/3369
- refactor(draft): add typed speculator contract by @seonjinn in #3701
- fix(vlm): use the vLLM prompt keys in async rollouts by @yfw in https://github.com/NVIDIA-NeMo/RL/pull/4151
- perf: enable HybridEP in remaining GB200 MoE performance recipes by @seonjinn in #4118
- feat(data-plane): track data-plane time, latency percentiles and byte volume by @ZhiyuLi-Nvidia in https://github.com/NVIDIA-NeMo/RL/pull/3616
- feat(draft): stream vocab-parallel soft CE by @seonjinn in #3703
- fix(vllm): support misaligned MXFP8 MoE dimensions by @seonjinn in #3630
- perf(ppo): skip duplicate GAE for equal lambdas by @alanliu-nvidia in https://github.com/NVIDIA-NeMo/RL/pull/4137
- fix(docker): persist the TRT-LLM wheel by @tdene in https://github.com/NVIDIA-NeMo/RL/pull/4153
- feat: add Energon-owned SFT sequence packing by @rohitrango in #4105
- feat(nemo-gym): create actors for configured shards by @ananthsub in https://github.com/NVIDIA-NeMo/RL/pull/3371
- feat: add fp32 LM head toggle by @guyueh1 in #4096
- feat(nemo-gym): route rollouts across shard actors by @ananthsub in https://github.com/NVIDIA-NeMo/RL/pull/3372
- feat(data-plane): add Mooncake storage checkpoints by @zyzhou5 in #3898
- fix(automodel): align checkpoint lifecycle with consolidated save modes by @jQizhang in #3935
- perf(ppo): vectorize GAE when gamma and lambda are one by @youngeunkwon0405 in #4156
- test(automodel): AUT-2382 add checkpoint config to v2 worker fixture by @svcnemo-autobot in https://github.com/NVIDIA-NeMo/RL/pull/4197
- feat(draft): support optimizer schedule overrides by @seonjinn in #3707
- build: exclude PyAV from shipped container by @rohitrango in #4184
- feat(data): add PackedTensor preprocessing modes by @rohitrango in https://github.com/NVIDIA-NeMo/RL/pull/4106
- chore(deps): bump mooncake and wandb by @kajalj22 in https://github.com/NVIDIA-NeMo/RL/pull/4179
- fix(automodel): unbreak L1 by adding the missing dpo model_save_format by @yuki-97 in https://github.com/NVIDIA-NeMo/RL/pull/4209
- feat: add end-to-end TE NVFP4 training with per-token vLLM rollout by @zhangyimi in #3566
- perf(data-plane): avoid local batch copies by @rohitrango in https://github.com/NVIDIA-NeMo/RL/pull/4107
- fix(megatron): preserve patchified vision tensors by @rohitrango in https://github.com/NVIDIA-NeMo/RL/pull/4212
- fix(vllm): strip staged token arrays from capture responses by @pthombre in https://github.com/NVIDIA-NeMo/RL/pull/4206
- fix(ppo): rebuild the critic optimizer on a warm start by @bg51717 in #4213
- fix(LOO-Norm-Advantage): Fix spike in LOO normed advantage. by @cspades in #4158
- feat(mopd): support multiple teacher checkpoints in full-vocabulary o… by @RayenTian in #4045
- feat(nemo-gym): wire sharded stacks into training by @ananthsub in https://github.com/NVIDIA-NeMo/RL/pull/3373
- fix(nemo-gym): preserve replica identity during routing by @ananthsub in https://github.com/NVIDIA-NeMo/RL/pull/3374
- ci: install research folder dependencies & discover research test suites by @sajadn in https://github.com/NVIDIA-NeMo/RL/pull/4216
- test: re-enable nemotron omni clevr megatron single-controller L1 test by @yuki-97 in https://github.com/NVIDIA-NeMo/RL/pull/4231
- feat(draft): preserve split-step normalization parity by @seonjinn in https://github.com/NVIDIA-NeMo/RL/pull/3706
- refactor(loss): move loss-input preparation into loss_input.py by @yuki-97 in https://github.com/NVIDIA-NeMo/RL/pull/4232
- chore(dtensor): move remaining DTensor v1 configs to v2 by @yuki-97 in https://github.com/NVIDIA-NeMo/RL/pull/4196
- feat(dtensor): reject dtensor_cfg._v2=false by @yuki-97 in https://github.com/NVIDIA-NeMo/RL/pull/4207
- fix(sc): pass refit_payload_mode when recovery regenerates refit info by @asolergi-nv in https://github.com/NVIDIA-NeMo/RL/pull/4233
- feat(Automodel): add MiniMax-M3 GRPO training support by @jQizhang in #4143
- feat(research): add flow_grpo, Flow-GRPO for Qwen-Image by @triple-mu in #3408
- refactor(dtensor): remove the DTensor v1 policy worker by @yuki-97 in #4198
- feat(grpo): evaluate sequence-logprob filtering in the training forward by @CarlosGomes98 in #4171
- chore: drop all CODEOWNERS entries except the file itself by @yuki-97 in https://github.com/NVIDIA-NeMo/RL/pull/4254
- test: update reward model expected score by @yuki-97 in https://github.com/NVIDIA-NeMo/RL/pull/4252
- fix: expose grouped expert LoRA adapter sharing by @romitjain-sarvam in #4234
- fix(ci): Increase TP and offload for MInf reshard-async-gym Nano Lfast. by @cspades in https://github.com/NVIDIA-NeMo/RL/pull/4248
- feat(telemetry)!: instrument the single-controller path and propagate traces by @rrs45 in #4052
- ci: Bump Megatron-Bridge to 1f8873bb... (manual) by @kajalj22 in https://github.com/NVIDIA-NeMo/RL/pull/4139
- ci: split the longest jobs to speed up L1 and Lfast by @yuki-97 in https://github.com/NVIDIA-NeMo/RL/pull/4253
- feat(rollout): integrate MInf ledger capture with checkpointing by @lauradang in #4129
- build: bump vllm to 0.29.0 by @yfw in #4080
- build(docker): install uv and its managed Python outside /root by @ko3n1g in #4260
- feat: add advisory CODEOWNERS reviewer suggestions + membership check by @kajalj22 in https://github.com/NVIDIA-NeMo/RL/pull/4181
- chore(deps): bump git-lfs 3.7.0 -> 3.8.0 by @kajalj22 in https://github.com/NVIDIA-NeMo/RL/pull/4204
- refactor(dtensor): drop the mesh-derived CP fallback from the x-token path by @yuki-97 in https://github.com/NVIDIA-NeMo/RL/pull/4318
- feat(sglang): engine fault tolerance for rollouts by @Kh4L in #3613
- chore(deps): build apptainer from source with updated vendored deps by @kajalj22 in https://github.com/NVIDIA-NeMo/RL/pull/4186
- feat(megatron): Pass VL related config fields to MCore by @guyueh1 in https://github.com/NVIDIA-NeMo/RL/pull/4288
- fix(megatron): allow flash attention for expanded Omni by @rohitrango in https://github.com/NVIDIA-NeMo/RL/pull/4284
- feat(capture): capture vLLM VLM media alongside token deltas by @pthombre in #4191
- fix: pin Nsight Systems to a version with patched CVEs by @kajalj22 in #4343
- ci: flip cherry-pick automation to release-branch -> main direction by @kajalj22 in https://github.com/NVIDIA-NeMo/RL/pull/4334
- chore: bump main version to 0.8.0 by @kajalj22 in https://github.com/NVIDIA-NeMo/RL/pull/4385
- refactor(dtensor): delete the DTensor v1 dead code by @yuki-97 in #4276
- chore(dtensor): delete the dtensor_cfg._v2 key by @yuki-97 in #4270
- ci: fix /ok to test not triggering CI on cherry-pick PRs by @kajalj22 in https://github.com/NVIDIA-NeMo/RL/pull/4396
- cp: cherry-pick #4182 - fix: restore unexpanded Nemotron prompts for vLLM by @yuki-97 in https://github.com/NVIDIA-NeMo/RL/pull/4412
- ci: pin to FW-CI-templates v1.12.2 (PR-author identity fix) by @kajalj22 in https://github.com/NVIDIA-NeMo/RL/pull/4413
- fix(ci): megatron_generation-colocated-reshard-gym by @tdene in https://github.com/NVIDIA-NeMo/RL/pull/4402
- fix: bump ray to 2.58.0 and purge bundled ray_dist.jar for CVE remediation by @kajalj22 in #4415
- fix(recipes): disable vLLM async scheduling for GLM-5.1 by @sharonyu-115 in #4354
- fix: Fix vlm_grpo-nemotron-omni-30ba3b nightly by @tdene in https://github.com/NVIDIA-NeMo/RL/pull/4134
- refactor(config): centralize the outdated-config checks in one module by @yuki-97 in https://github.com/NVIDIA-NeMo/RL/pull/4271
- fix(megatron): stream generate_async without .options() so Ray 2.58 accepts it by @terrykong in https://github.com/NVIDIA-NeMo/RL/pull/4468
- fix(nemo-gym): restore Dynamo generation setup by @jthomson04 in https://github.com/NVIDIA-NeMo/RL/pull/4368
- fix(recipes): use SDPA for Mistral Medium 3.5 DAPO by @sharonyu-115 in https://github.com/NVIDIA-NeMo/RL/pull/4454
- ci: nightly Slack reminder for open cherry-pick PRs to main by @kajalj22 in https://github.com/NVIDIA-NeMo/RL/pull/4505
- refactor(dtensor): delete the DTensor v1 native checkpoint implementation by @yuki-97 in #4273
- perf: use HybridEP in AutoModel MoE recipes by @seonjinn in #4037
- fix(recipes): enable save_data_plane for PPO async single-controller nightly by @yuki-97 in https://github.com/NVIDIA-NeMo/RL/pull/4532
- fix: unblock DSV3, Nemotron 3 Super, and Gemma3 nightly/release tests by @yfw in https://github.com/NVIDIA-NeMo/RL/pull/4417
- fix(value): switch the Megatron critic to eval before offloading it by @bg51717 in https://github.com/NVIDIA-NeMo/RL/pull/4538
- refactor(automodel): rename the dtensor_cfg config block to automodel_cfg by @yuki-97 in #4283
- refactor(automodel): rename the DTensor v2 workers to Automodel by @yuki-97 in #4282
- fix(recipes): enable save_data_plane for GRPO token-capture SC nightly by @yuki-97 in https://github.com/NVIDIA-NeMo/RL/pull/4587
- cp: cherry-pick #4372 - fix(token-capture): size the nightly rollout buffer... by @yuki-97 in https://github.com/NVIDIA-NeMo/RL/pull/4586
- fix(nightly): remove flaky step-20 logprob check on r0.8.0 by @fujial-code in https://github.com/NVIDIA-NeMo/RL/pull/4592
- ci: bump FW-CI-templates cherry-pick to v1.13.0 to ping author and merger by @kajalj22 in https://github.com/NVIDIA-NeMo/RL/pull/4601
- perf(data-plane): cut sync TQ overhead and count the rollout actor metrics by @ZhiyuLi-Nvidia in #4580
- ci(recipes): extend SGLang Megatron nightly wall time by @Kh4L in https://github.com/NVIDIA-NeMo/RL/pull/4582
- fix: cap Nemotron-3 Super KV cache by @humairafirdowse18 in https://github.com/NVIDIA-NeMo/RL/pull/4409
- fix(recipes): increase DeepSeek V3 MXFP8 rollout memory budget by @humairafirdowse18 in https://github.com/NVIDIA-NeMo/RL/pull/4424
- fix(megatron): forward the FlashInfer MXFP8 decode token capacity by @wdykas in https://github.com/NVIDIA-NeMo/RL/pull/4570
- ci: scope TRT-LLM caches and Lfast image to release branches by @kajalj22 in https://github.com/NVIDIA-NeMo/RL/pull/4616
- fix: restore Transformers 5 compatibility for DeepSeek-V3 by @humairafirdowse18 in #4408
- fix: correct QARL nightly quantization and HybridEP topology by @mxinO in https://github.com/NVIDIA-NeMo/RL/pull/4548
- fix(checkpoint): use synchronous saves for DeepSeek V3 32-node recipe by @humairafirdowse18 in https://github.com/NVIDIA-NeMo/RL/pull/4432
- fix(ci): load xtoken default dataset by HF id so it works offline by @kajalj22 in https://github.com/NVIDIA-NeMo/RL/pull/4657
- build: bump nixl to 1.4.1 and nvidia-cudnn-frontend to >=1.26.0,<1.29.0 by @yuki-97 in https://github.com/NVIDIA-NeMo/RL/pull/4658
- fix(ci): keep HybridEP nightly in one NVLink domain by @sharonyu-115 in https://github.com/NVIDIA-NeMo/RL/pull/4665
- fix(ci): fix consistently failing and flaky nightly test gates by @yuki-97 in https://github.com/NVIDIA-NeMo/RL/pull/4689
- fix(ci): relax grpo-llama3.2-1b-instruct-1n4g-fsdp2tp1.v3 step-time gate to 16s by @yuki-97 in https://github.com/NVIDIA-NeMo/RL/pull/4692
- feat(megatron): enable GLM-5.2 native SM90 FP8 DSA scoring by @RayenTian in #4667
- fix: pad audio to hop length for Qwen3-Omni prompt match (cp of #4363) by @yuekaizhang in https://github.com/NVIDIA-NeMo/RL/pull/4695
- fix(ci): raise xtoken multiteacher nightly time limit to 60 min by @yuki-97 in https://github.com/NVIDIA-NeMo/RL/pull/4697
- fix: restore Moonlight FP8 nightly compatibility by @fujial-code in https://github.com/NVIDIA-NeMo/RL/pull/4595
- ci: reuse the release-branch container for CI:docs on release PRs by @yuki-97 in https://github.com/NVIDIA-NeMo/RL/pull/4698
- fix(ci): raise nightly GPU-hour cap to 4790 by @yuki-97 in https://github.com/NVIDIA-NeMo/RL/pull/4704
- cp: cherry-pick #4154 - fix(grpo): drop top-k/top-p -inf from token_mask by @tdene in https://github.com/NVIDIA-NeMo/RL/pull/4722
- test(suites): rename the backend token in recipe filenames to automodel by @yuki-97 in #4701
- test(automodel): rename the dtensor-named tests and merge the two worker files by @yuki-97 in https://github.com/NVIDIA-NeMo/RL/pull/4703
- fix(nightly): make dpo-nanov3-30B3AB-1n8g-automodel-ep8.v2 deterministic by @joyang-nv in https://github.com/NVIDIA-NeMo/RL/pull/4619
- docs: make NeMo Gym the primary evaluation path by @cwing-nvidia in #4687
- fix(flow-grpo): install cv2 system libs, cut OCR nightly to 240 min by @yuki-97 in https://github.com/NVIDIA-NeMo/RL/pull/4696
- docs(automodel): rename the DTensor backend to Automodel by @yuki-97 in #4277
- chore: Bump dependencies to address CVES for r0.8.0 by @chtruong814 in #4736
- fix(refit): reduce oversized IPC buffer memory by @sharonyu-115 in https://github.com/NVIDIA-NeMo/RL/pull/4643
- fix: Super QARL MTP compatibility and masked-loss safety by @mxinO in https://github.com/NVIDIA-NeMo/RL/pull/4615
- fix(automodel): release MoE dispatcher state before colocated offload by @joyang-nv in https://github.com/NVIDIA-NeMo/RL/pull/4756
- fix: prevent MiniMax-M2.7 recipe OOM by @jQizhang in https://github.com/NVIDIA-NeMo/RL/pull/4759
- perf(tests): enable vLLM PIECEWISE CUDA graphs in two eager release recipes by @joyang-nv in #4568
- fix(vllm): stabilize Qwen3 30B and 32B MXFP8 rollouts by @humairafirdowse18 in https://github.com/NVIDIA-NeMo/RL/pull/4479
- fix: Address CVEs for mooncake, apptainer, setuptools, and nsys by @chtruong814 in #4766
- perf(tests): enable vLLM CUDA graphs in eight eager nightly recipes by @joyang-nv in #4569
- fix(nightly): fix flow-grpo and sft-gpt-oss nightlies by @yuki-97 in https://github.com/NVIDIA-NeMo/RL/pull/4788
- fix(recipes): disable vLLM async scheduling for Qwen3.5-397B GRPO by @sharonyu-115 in #4794
- test(nightly): retire nanov3 MXFP8 flashinfer test by @tdene in https://github.com/NVIDIA-NeMo/RL/pull/4813
- docs(automodel): call the backend Automodel in the nanov3.5 recipe header by @yuki-97 in https://github.com/NVIDIA-NeMo/RL/pull/4816
- cp: cherry-pick #3984 - fix: release trainer memory before collective export by @seonjinn in https://github.com/NVIDIA-NeMo/RL/pull/4806
- cp: cherry-pick #3461 - perf(recipes): use FlashInfer TRT-LLM MoE for BF16 by @seonjinn in https://github.com/NVIDIA-NeMo/RL/pull/4805
- cp: cherry-pick #3865 - perf: use NCCL Reshard for all async MXFP8 recipes by @seonjinn in https://github.com/NVIDIA-NeMo/RL/pull/4807
- fix: restore Triton for DeepSeek V3 Hopper performance recipes by @youngeunkwon0405 in https://github.com/NVIDIA-NeMo/RL/pull/4847
- cp: cherry-pick #4850 - fix(recipes): use Triton BF16 MoE on H100 by @seonjinn in https://github.com/NVIDIA-NeMo/RL/pull/4851
- fix(vllm): discard colocated weights at safe sleeps by @humairafirdowse18 in #4433
- fix(sglang): disable legacy Outlines disk cache by default by @chtruong814 in #4797
- chore: bump Megatron-Bridge to e0b56303 (Megatron-LM a69434877) by @RayenTian in #4852
- fix(r0.8.0): backport packed refit stream ordering fix (#4720) by @youngeunkwon0405 in https://github.com/NVIDIA-NeMo/RL/pull/4866
- fix(recipe): stabilize Qwen3 235B MXFP8 rollouts by @humairafirdowse18 in https://github.com/NVIDIA-NeMo/RL/pull/4480
- perf: change async dsv3 perf recipe to use nccl reshard refit by @youngeunkwon0405 in #4870
- build: add STRIP_UV_CACHE to drop uv cache from the r0.8.0 release image by @kajalj22 in https://github.com/NVIDIA-NeMo/RL/pull/4889
- test: Increase timeout of grpo-qwen2.5-math-megatrontp1-sglang by 5 minutes by @kajalj22 in https://github.com/NVIDIA-NeMo/RL/pull/4930
- perf(r0.8): use NCCL reshard for non-DeepSeek async recipes by @seonjinn in #4869
- chore: Bump filelock for security fix (r0.8.0) by @kajalj22 in #4924
- fix(qarl): require Triton for fake-quant MoE by @mxinO in https://github.com/NVIDIA-NeMo/RL/pull/4927
- fix(r0.8.0): use default refit for DeepSeek-V3 FP8 async recipe by @youngeunkwon0405 in https://github.com/NVIDIA-NeMo/RL/pull/4926
- chore: Bump virtualenv, gitpython, pillow for security fixes (r0.8.0) by @kajalj22 in #4885
- build: bump Gym submodule to v0.7.0 by @kajalj22 in #4828
- chore: Bump mlflow and aiohttp for security fixes (r0.8.0) by @kajalj22 in #4970
- fix(ci): drop redundant distributed_timeout_seconds by @kajalj22 in https://github.com/NVIDIA-NeMo/RL/pull/4977
- docs: bump version to 0.8.0 by @kajalj22 in https://github.com/NVIDIA-NeMo/RL/pull/4990
- fix(docker): remove Windows launcher stubs from uv-managed Python by @kajalj22 in https://github.com/NVIDIA-NeMo/RL/pull/4987
- fix(recipes): use EP4 for Qwen3-235B async MXFP8 refit by @seonjinn in https://github.com/NVIDIA-NeMo/RL/pull/4982
- docs: fix broken commands, stale claims and version refs in r0.8.0 docs by @terrykong in https://github.com/NVIDIA-NeMo/RL/pull/4991
- build: bump python packages, Go toolchain and image deps for security fixes by @kajalj22 in #4988
- cp: use median-only probability-error checks for Qwen3 perf recipes (#5055) by @kajalj22 in https://github.com/NVIDIA-NeMo/RL/pull/5066
- fix(recipes): use synchronous saves for DAPO DeepSeek V3 by @yuki-97 in https://github.com/NVIDIA-NeMo/RL/pull/5033
- cp: cherry-pick #5073 - test: calibrate noisy metric checks by @yuki-97 in https://github.com/NVIDIA-NeMo/RL/pull/5078
- build(docker): keep ccache out of the release image by @kajalj22 in https://github.com/NVIDIA-NeMo/RL/pull/5052
- docs: Update performance numbers for v0.8 release by @parthmannan in https://github.com/NVIDIA-NeMo/RL/pull/5082
New Contributors
- @tianyi-zhang-02 made their first contribution in #3071
- @mohamed-alansary made their first contribution in #3124
- @anjalibshah made their first contribution in #2680
- @humairafirdowse18 made their first contribution in #3278
- @babyplutokurt made their first contribution in #3226
- @jepio made their first contribution in #3152
- @VishnuR23 made their first contribution in #3679
- @nvilia made their first contribution in #3430
- @MarkXCloud made their first contribution in #2744
- @dafu-wu made their first contribution in #3419
- @Kh4L made their first contribution in #3612
- @mferrato made their first contribution in https://github.com/NVIDIA-NeMo/RL/pull/3709
- @balasaajay made their first contribution in https://github.com/NVIDIA-NeMo/RL/pull/3862
- @abhinav-bellapu made their first contribution in #3248
- @ArEsKay3 made their first contribution in #3912
- @zhangyimi made their first contribution in #3566
- @sajadn made their first contribution in https://github.com/NVIDIA-NeMo/RL/pull/4216
- @asolergi-nv made their first contribution in https://github.com/NVIDIA-NeMo/RL/pull/4233
- @triple-mu made their first contribution in #3408
- @romitjain-sarvam made their first contribution in #4234
- @cwing-nvidia made their first contribution in #4687
Full Changelog: v0.7.0...v0.8.0


