Repository navigation
AWQ
Documentation home · Quickstart · Lifecycle
On this page
AWQ is GPT-QModel's activation-aware weight-quantization method. It uses calibration activations to search for channel scales that reduce the reconstruction error of low-bit weights, folds those scales into adjacent operations, optionally clips weight groups, and packs the resulting weights for inference. Activations are not converted to INT4 by this procedure: a 4-bit AWQ checkpoint is a weight-only quantized model whose computation dtype depends on the selected inference kernel.
Three choices must be kept separate:
| Choice | API/configuration | Meaning |
|---|---|---|
| Quantization method |
AWQConfig, METHOD.AWQ ("awq") |
How calibration and weight quantization are performed. |
| Checkpoint format |
FORMAT.GEMM, FORMAT.GEMV, FORMAT.GEMV_FAST, FORMAT.LLM_AWQ
|
How integer weights, scales, and zero points are stored. |
| Inference backend | For example, BACKEND.AWQ_MARLIN, BACKEND.AWQ_GEMM_TRITON, BACKEND.AWQ_TORCH
|
Which implementation consumes a compatible packed checkpoint. Selecting Marlin inference does not require quantizing into a Marlin checkpoint. |
Here, weight-only describes inference storage: activations remain floating point. It does not mean calibration-free quantization. AWQConfig requires calibration; an RTN configuration exporting an AWQ layout instead uses the separate weight-only lifecycle and does not run AWQ's activation-aware scale/clip search.
The normal starting point is AWQConfig(bits=4, group_size=128, format=FORMAT.GEMM) with BACKEND.AUTO when loading the saved model. Use an explicit backend when a deployment requires a particular implementation, and check its bit width, group size, device, dtype, and shape requirements below.
This page describes the implementation at source revision c1976918cfe3703fbcf6d1ce2440a82b26394375. Requirements and kernel dispatch are version-dependent; use the source and installation requirements matching your installed GPT-QModel version.
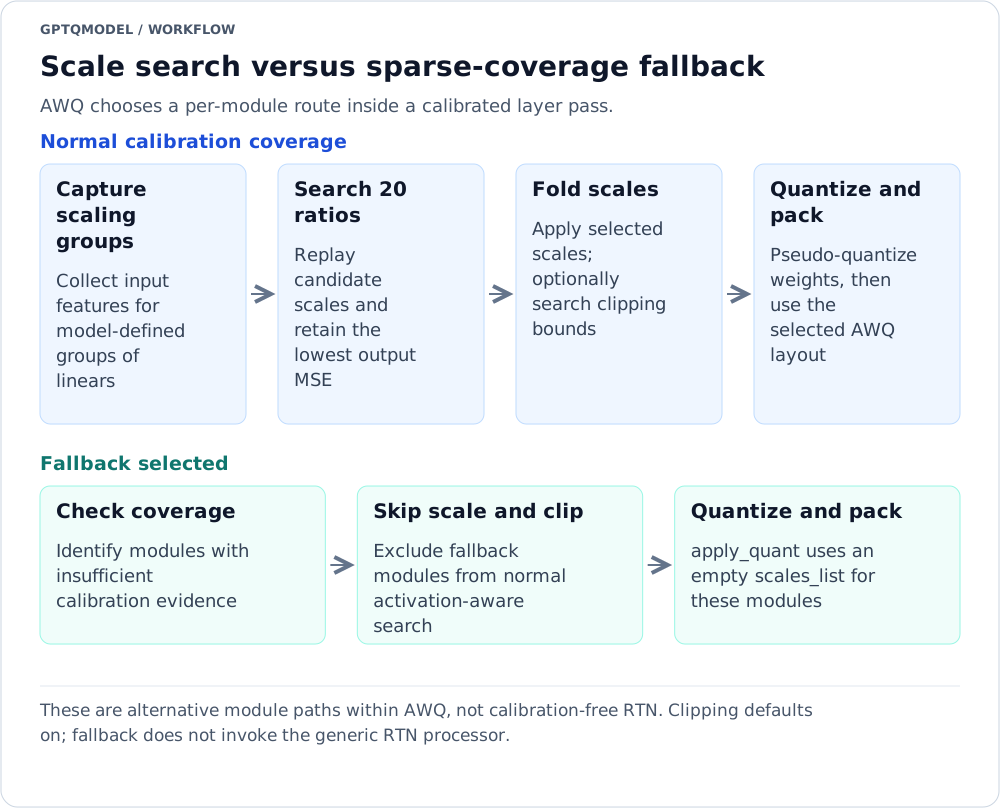
Reading the diagram: These are alternative module paths within AWQ, not calibration-free RTN. Clipping defaults on; fallback does not invoke the generic RTN processor.
Text version of the workflow
- Normal calibration coverage: Capture scaling groups → Search 20 ratios → Fold scales → Quantize and pack.
- Fallback selected: Check coverage → Skip scale and clip → Quantize and pack.
For a linear operation, let X contain calibration activations and W contain weights. Applying an invertible diagonal channel scale s gives the same full-precision operation when weights are multiplied by s and their inputs are divided by s. Quantizing the scaled weights, however, changes the rounding error. AWQ searches for a scale that makes this error less damaging to the layer's output.
The scale-search docstring expresses the objective as:
L(s) = || Q(W * s) (s^-1 * X) - W * X ||
Q here is pseudo-quantization: round and clamp to integer codes, then reconstruct floating-point weights. The implementation measures mean-squared output reconstruction error. It does not keep selected channels permanently in full precision, nor does it choose scales from weight magnitudes alone.
For each model-defined scaling group, the processor computes:
-
x_mean: mean absolute calibration activation per input channel, using FP32 accumulation. -
w_mean: mean normalized absolute weight magnitude per input channel across the group's linears. Weight groups are normalized by their maximum magnitude plus1e-6before accumulation; the implementation streams the linears instead of concatenating all their weights.
With the default processor setting duo_scaling=True, a candidate is:
s = x_mean^r / (w_mean^(1-r) + 1e-4)
With duo_scaling=False, it is s = x_mean^r. Both branches clamp the candidate scales to at least 1e-4. The current search tries 20 ratios, r = i / 20 for i = 0..19, thus 0.00, 0.05, ..., 0.95. Each candidate is normalized by sqrt(s.max() * s.min()) and sanitized for non-finite values. The candidate weights are pseudo-quantized, the inspected module is replayed, and the lowest reconstruction loss wins. Original weights are restored between candidates and after the search.
When a previous-subset weight-scale hint is available, _compute_best_scale() first multiplies w_mean by that hint. Candidate products are rebuilt from pristine master weights rather than repeatedly multiplying and dividing the previous candidate. Selection uses strict <, so equal finite losses retain the first minimum.
group_size partitions the input-feature dimension of each weight row. Positive values require compatible dimensions; -1 denotes one group across the row. The quantizer's basic arithmetic is:
| Mode | Scale and integer range | Reconstruction |
|---|---|---|
Asymmetric, sym=False
|
scale = clamp(max-min, min=1e-5) / (2^bits-1); zero = clamp(-round(min/scale), 0, 2^bits-1)
|
(clamp(round(w/scale)+zero, 0, 2^bits-1)-zero)*scale |
Symmetric, sym=True
|
scale = clamp(max(abs(w)), min=1e-5) / (2^(bits-1)-1); signed codes in [-2^(bits-1), 2^(bits-1)-1]
|
Signed code times scale. Packing shifts codes to unsigned and supplies zero = 2^(bits-1) without changing the reconstructed value. |
Consequently, a symmetric AWQ checkpoint still has affine zero-point data. sym=True does not mean that its packed zero-point tensor can be discarded. In the GEMM representation, dequantization is (integer_weight - integer_zero) * scale, not GPTQ's legacy on-disk zero-minus-one convention.
After scales have been applied, AWQ can narrow a group's weight range before the final pseudo-quantization. _compute_best_clip() evaluates calibration-weighted group outputs, not just the distance between original and quantized weights. It computes an original group product, evaluates clipped and quantized group products, averages squared error over sampled tokens, and selects a bound for each output-channel/group pair.
The current defaults and boundaries are important:
| Item | Implementation |
|---|---|
| Clipping enabled |
AWQProcessor.apply_clip = True. |
| Search signature defaults |
n_grid=20, max_shrink=0.5, n_sample_token=512. |
| Candidate count |
int(max_shrink * n_grid), which is 10 by default. |
| Actual default range multipliers |
1 - i/20 for i=0..9: 1.00, 0.95, ..., 0.55. The endpoint 0.50 is not evaluated. |
| Initial bound | Maximum absolute weight within each group; clipping is symmetric about zero, including when the quantizer uses asymmetric zero points. |
| Token sampling | Flatten activations, then take every max(1, token_count // n_sample_token)th row. This is a stride target, not a strict cap of exactly 512 rows. |
| Output-channel batching | 256 when the output-channel count is divisible by 256; otherwise 64. The output-channel count must be divisible by the chosen batch size. |
| Excluded names | Any linear name containing q_, k_, query, key, or Wqkv; the code avoids these because q/k attention products make precise clipping difficult. This is substring matching, not a semantic attention classifier. |
| Ties and invalid candidates | First minimum wins; NaN errors are mapped to infinity for selection. |
Candidate, token, and product work is chunked. For FP16/BF16 weights, shrink factors are FP32 and their multiplication order is preserved before casting products back to weight dtype. These details are part of the numerical behavior, not merely performance tuning.
from datasets import load_dataset

from gptqmodel import GPTQModel
from gptqmodel.quantization import AWQConfig, FORMAT, MSEConfig

model_id = "meta-llama/Llama-3.2-1B-Instruct"

# Choose representative, nonempty text for the model and task.
dataset = load_dataset("wikitext", "wikitext-2-raw-v1", split="train")
calibration = [text for text in dataset["text"] if len(text.strip()) > 100][:128]

qcfg = AWQConfig(
    bits=4,
    group_size=128,
    sym=False,  # Explicit choice; the inherited default is True.
    format=FORMAT.GEMM,
    scale_search_chunked_activations=True,
    mse=MSEConfig(clip_grid_budget="256M"),
)

model = GPTQModel.load(model_id, quantize_config=qcfg)
model.quantize(calibration, batch_size=1)
model.save("./llama-awq")
The model ID is illustrative and requires access to that model. The 128 examples and character filter are example dataset choices, not AWQ API defaults or a guarantee of calibration quality. GPTQModel.load() defaults to trust_remote_code=False; enable remote code only when you have reviewed and trust it. See Installation and quickstart and Quantization lifecycle for dataset preparation and the general workflow.
from gptqmodel import GPTQModel
from gptqmodel.utils.backend import BACKEND

model = GPTQModel.load("./llama-awq", backend=BACKEND.AUTO)
output = model.generate("Explain weight-only quantization.", max_new_tokens=64)
print(output)
For an explicit compatible GEMM-format implementation:
# NVIDIA Ampere or newer, subject to all Marlin validation checks.
model = GPTQModel.load("./llama-awq", backend=BACKEND.AWQ_MARLIN)

# Portable GEMM-format fallback; this can temporarily dequantize weights.
model = GPTQModel.load("./llama-awq", backend=BACKEND.AWQ_TORCH)
An explicit backend is a compatibility request, not a request to convert an arbitrary checkpoint into that backend's input format. For example, the portable Torch AWQ kernel consumes GEMM format, not GEMV_FAST format. Use Loading and inference for device placement and generation details.
from gptqmodel.quantization import AWQConfig, FORMAT

gemm_config = AWQConfig(format=FORMAT.GEMM)
gemv_config = AWQConfig(format=FORMAT.GEMV)
fast_config = AWQConfig(format=FORMAT.GEMV_FAST)
llm_awq_config = AWQConfig(format=FORMAT.LLM_AWQ)
Choose before quantization. In BaseQModel.quantize(), GEMV_FAST and LLM_AWQ automatically set pack_dtype=torch.int16; the default for GEMM/GEMV is torch.int32. Native fast inference is FP16, and the loader enforces the fast formats' dtype requirements. Do not select a fast layout solely because of its name: format compatibility can be more restrictive than GEMM's range of inference backends.
AWQConfig is a dataclass derived from PreProcessorConfig, which derives from BaseQuantizeConfig. Its AWQ-specific declarations are:
@dataclass
class AWQConfig(PreProcessorConfig):
    method: METHOD = field(default=METHOD.AWQ)
    format: FORMAT = field(default=FORMAT.GEMM)
    scale_search_chunked_activations: bool = field(
        default=True,
        metadata={
            "help": "Stream and chunk AWQ scale-search activations to reduce peak memory during reference and reconstruction forwards."
        },
)| AWQ-specific contract | Value/behavior |
|---|---|
method |
METHOD.AWQ; allowed_quant_methods() returns (METHOD.AWQ,). |
format |
Defaults to FORMAT.GEMM. |
scale_search_chunked_activations |
True; generate reference outputs in replay chunks, initially stage them on CPU, and score candidate outputs chunk by chunk. The scorer then retains all reference chunks on the inspected module's device; this is not a GPU-residency cap. False restores the legacy eager reference/candidate path. Serialized into quantization metadata. |
default_desc_act() |
False. The inherited constructor field starts as None and resolves to AWQ's method default. |
supported_export_formats() |
AWQ_EXPORT_FORMATS: GEMM, GEMV, GEMV_FAST, MARLIN, BITBLAS, LLM_AWQ. Membership does not imply that fresh quantization supports every format. |
| Output compatibility fields | Writes zero_point = not sym, version = format, and format = format, in addition to common method/quantization serialization. |
The complete inherited public field surface is listed below. Defaults are constructor declarations unless a resolved default is explicitly stated. Not every shared option changes AWQ's search algorithm; in particular, GPTQ Hessian/damping controls are not AWQ controls.
| Field | Default | AWQ/shared behavior |
|---|---|---|
bits |
4 |
Common integer choices are 2–8. Actual support depends on the packing and inference kernel; most native AWQ kernels are INT4-only. |
dynamic |
None |
Shared per-module override/exclusion map. AWQ preprocessing honors exclusions, and packing passes the dynamic map to module creation. Do not infer unrestricted mixed-bit search support from the common config type: AWQ's pseudo-quantizer reads the processor's qcfg.bits, qcfg.group_size, and qcfg.sym. |
group_size |
128 |
Input-feature grouping; -1 means row-wide grouping. Check the selected kernel and actual layer widths. |
desc_act |
None, resolved to False for AWQ |
AWQ does not perform GPTQ activation-order permutations. Some kernels accept True as compatibility metadata; this does not add GPTQ's g_idx ordering to AWQ. |
sym |
True |
Symmetric versus asymmetric quantization. Set False explicitly when asymmetric AWQ is desired. |
true_sequential |
True |
Shared sequential module/layer lifecycle control. |
lm_head |
False |
Whether to include the output head in quantization. |
activation |
None |
Shared GPTQ W4A configuration, not an AWQ option. Non-None activation policies are rejected with METHOD.AWQ in this revision. |
meta |
None |
Quantization metadata. |
device |
None |
Quantization device selection; normalized by the common lifecycle. |
telemetry |
TelemetryConfig() |
Diagnostics; its device flag defaults to False. Not an AWQ numerical parameter. |
mse |
MSEConfig() |
Typed configuration for shrink-grid/clip scratch budgets. Details below. |
pack_dtype |
torch.int32 |
Packed word dtype; fast AWQ formats override it to torch.int16 during quantization. |
pack_impl |
"auto" |
Shared packing implementation choice. |
adapter |
None |
Adapter configuration; kernel adapter support must also match. |
offload_to_disk |
True |
Offload completed modules during quantization. |
offload_to_disk_path |
None |
Optional directory for disk offload. |
rotation |
None |
Shared rotation option; declared choices are "hadamard", "random". Separate from AWQ's diagonal scaling. |
fallback |
Fallback() |
Default object uses strategy=FallbackStrategy.RTN, threshold="0.5%", smooth=None. AWQ uses coverage/fallback decisions and directly pseudo-quantizes fallback modules without its normal scale search. |
compute_device_filter |
None |
Optional fn(devices: List) -> List filter for compute-intensive work. |
calibration_data_device |
None |
Calibration-storage device; supports explicit devices and "balanced" round-robin storage. |
auto_forward_data_parallel |
True |
May clone forwarding work across GPUs; can increase VRAM use and setup cost. |
dense_vram_strategy |
VramStrategy.EXCLUSIVE ("exclusive") |
Dense-pool placement; alternative enum value is BALANCED ("balanced"). |
dense_vram_strategy_devices |
None |
Optional device pool for dense modules. |
moe_vram_strategy |
VramStrategy.EXCLUSIVE |
Expert-pool placement; expert families stay co-located. |
moe_vram_strategy_devices |
None |
Optional expert device pool. |
gc_mode |
GcMode.INTERVAL ("interval") |
Shared GC policy; alternative ON_STAGE_END ("on_stage_end"). |
wait_for_submodule_finalizers |
False |
Wait for packing/offload finalizers before the next layer, potentially reducing VRAM pressure. |
moe |
None |
Optional MoEConfig for routing/batching. See Multimodal and MoE models. |
preprocessors |
New empty list per instance | Ordered shared preprocessing configs. |
smoother |
None |
Accepts SmootherConfig, a smooth-method object, dictionary, or string; normalized into the preprocessor list. |
smooth |
None |
Backward-compatible smoother input alias, hidden from repr; the resolved smooth method is also exposed here after normalization. Prefer smoother. |
The internal _offload_temp_dir field is not an initializer argument. method and format are inherited fields overridden by the AWQ declarations above. See QuantizeConfig reference for common normalization, dynamic rules, placement, and preprocessing APIs.
These similarly named mechanisms are not interchangeable:
| Mechanism | Configuration/default | Relationship to AWQ |
|---|---|---|
| AWQ activation-aware scale search | Processor duo_scaling=True; fixed 20-ratio search |
Native AWQ algorithm, implemented by _search_best_scale() and _compute_best_scale(). Does not read SmoothMSE.steps or SmoothMSE.maxshrink. |
| Generic MSE shrink-grid objective | MSEConfig.norm=0.0 |
Zero disables the general quantizer's shrink-grid search. It does not disable AWQ's scale search or clip search; those compute their own reconstruction MSE. |
| Generic shrink-grid workspace | MSEConfig.grid_budget=None |
Used for the GPTQ/QQQ shrink-grid workspace; not the AWQ clip-grid budget. |
| AWQ clip-grid workspace | MSEConfig.clip_grid_budget=None |
Read by _compute_best_clip() to size independent scratch buffers/chunks. Does not set clip strength or turn clipping on/off. |
| Generic smoother shrink search | SmoothMSE(steps=32, maxshrink=0.8, group_size_threshold=128) |
A typed shared smoothing method. AWQConfig can normalize/serialize it through its parent config, but AWQ's scale, clip, and pseudo-quantization routines do not consume it as their search policy. |
| AWQ clipping policy | Processor apply_clip=True, clip method defaults n_grid=20, max_shrink=0.5
|
Independent of the generic SmoothMSE and mse.norm controls. |
| AWQ chunk budget | Processor max_chunk_memory=1024 * 1024 * 1024
|
Used by activation statistics, reconstruction loss, and replay chunking. Not the same setting as clip_grid_budget. |
PreProcessorConfig normalizes smoother (or, when absent, the legacy smooth alias), keeps a single smoother entry after other preprocessors, and exposes its method through resolve_smooth_method(). ModulePreProcessor records an ordered per-module preprocessor plan. This configuration plumbing must not be mistaken for an AWQ implementation of every generic smoother: the SmoothMSE branches that perform generic shrink optimization are in the GPTQ, QQQ, and RTN quantizers, not AWQ's scale/clip search.
There are no AWQConfig(apply_clip=...), AWQConfig(duo_scaling=...), AWQConfig(max_shrink=...), or AWQConfig(n_grid=...) fields in this implementation. Those are processor attributes or internal method parameters. Do not copy similarly named options from another AWQ library into this dataclass. Changing them requires processor-level integration, not an undocumented keyword to GPTQModel.quantize().
The source's smoother constructor is:
def __init__(self, steps: int = 32, maxshrink: float = 0.8, group_size_threshold: int = 128):The memory-budget config fields are:
norm: float = 0.0
grid_budget: Optional[Union[int, str]] = None
clip_grid_budget: Optional[Union[int, str]] = None
Budgets accept integer byte counts and binary-unit strings such as "256M" and "1G". A None budget resolves to 16 MiB on CPU and 256 MiB on other devices. These are chunk-sizing targets for individual scratch workspaces, not limits on total model, activation, process, or device memory. Several scratch buffers can coexist, and minimum chunk sizes can exceed a very small requested target.
A zero clip_grid_budget selects single-candidate chunks and one-token product tiles; it does not turn clipping off. Negative byte budgets are rejected.
from gptqmodel.quantization import AWQConfig, MSEConfig

qcfg = AWQConfig(
    scale_search_chunked_activations=True,
    mse=MSEConfig(clip_grid_budget="64M"),
)
This changes AWQ clip workspace sizing. It does not disable clipping, change the 20-ratio scale search, or set a different clipping grid.
The public lifecycle is GPTQModel.load(..., quantize_config=AWQConfig(...)), model.quantize(calibration, ...), then model.save(...). The loader entry point is defined in gptqmodel/models/auto.py:
@classmethod
def load(
    cls,
    model_id_or_path: Optional[str],
    quantize_config: Optional[QuantizeConfig | Dict] = None,
    device_map: Optional[Union[str, Dict[str, Union[str, int]]]] = None,
    device: Optional[Union[str, torch.device]] = None,
    backend: Union[str, BACKEND] = BACKEND.AUTO,
    profile: Union[str, int, PROFILE] = PROFILE.AUTO,
    trust_remote_code: bool = False,
    allow_remote_adapter: bool = False,
    adapter_revision: Optional[str] = None,
    adapter_sha256: Optional[str] = None,
    **kwargs,
):
The quantization entry point is defined in gptqmodel/models/base.py:
def quantize(
    self,
    calibration: Optional[Union[List[Dict[str, Union[List[int], torch.LongTensor]]], List[str], List[int]]] = None,
    calibration_concat_size: Optional[int] = None,
    calibration_sort: Optional[str] = "desc",
    batch_size: int = 1,
    tokenizer: Optional[PreTrainedTokenizerBase] = None,
    backend: Optional[BACKEND] = BACKEND.AUTO,
    adapter: Adapter = None,
    adapter_calibration_dataset: Union[List[Dict[str, Union[List[int], torch.LongTensor]]], List[str], List[int]] = None,
    calibration_data_min_length: int = 10,
    calibration_concat_separator: Optional[str] = None,
    embed_quant_config: Optional[Union[QuantizeEmbedConfig, QuantizeEmbed]] = None,
    embed_quant_mode: Optional[QuantizeEmbed] = None,
    checkpoint: Optional["CheckpointConfig"] = None,
) -> Dict[str, List[Dict[str, str]]]:
The AWQ-specific processor signature in gptqmodel/looper/awq_processor.py is:
def __init__(
    self,
    tokenizer,
    qcfg: QuantizeConfig,
    calibration,
    prepare_dataset_func,
    calibration_concat_size: Optional[int],
    calibration_sort: Optional[str],
    batch_size: int,
    gptq_model,
    model,
    require_fwd: bool = True,
    calculate_w_wq_diff: bool = False,
    calibration_concat_separator: Optional[str] = None,
):
The model sets AWQ_BATCH_SIZE from the requested quantization batch size and schedules shared preprocessors before AWQProcessor. Its execution configuration requires forwards by default, enables activation capture, requests replay after processing, and permits early stopping of subset forwards:
ExecutionConfig(
    require_fwd=require_fwd,
    fwd_replay_after_process=True,
    subset_forward_early_stop=True,
    enable_activation_capture=True,
)| Stage | Implementation and state |
|---|---|
| Register modules |
preprocess() honors dynamic exclusions, records modules in _AWQLayerState, normalizes fallback preferences, and initializes capture buckets. Locks guard shared layer state and finalization. |
| Capture inputs | Forward hooks collect input activations. Padding is removed when the active keep mask can be aligned to input rows. Model-specific MoE policies can capture a shared root feature rather than only routed expert inputs. |
| Aggregate calibration | Model policies can bound retained token rows deterministically, preserve batch coverage, and allocate retention proportionally. Logs distinguish raw tokens, retained tokens, batches, aggregation mode, and the feature actually used for scaling. |
| Wait for scheduled work |
process() tracks processed subsets and pending modules. _quantize_layer() runs after all scheduled subsets for the layer are ready, avoiding partially collected features. |
| Resolve scaling groups |
gptq_model.awq_get_modules_for_scaling() uses model module-tree information to identify the preceding operation, linears sharing a scale, captured inputs, module to inspect, and forward kwargs. |
| Search and apply scales |
_search_best_scale() gathers statistics/reference outputs; _compute_best_scale() tests candidates. apply_scale() folds the winning scale into the graph and adjusts captured downstream features. |
| Search and apply clips | Unless apply_clip is false, eligible non-fallback linears are passed to _search_best_clip() and apply_clip(). |
| Pseudo-quantize |
apply_quant() writes reconstructed weights, saves q_scales and q_zeros, optionally records the original-minus-quantized difference for adapter work, and stages packing state. |
| Pack |
submodule_finalize() calls pack_module(), which resolves the selected kernel, creates the quantized module, packs its weights/scales/zeros, and removes temporary state. |
| Finalize |
finalize() marks the model quantized and sets the method to METHOD.AWQ. |
AWQProcessor can use the model's already selected qlinear_kernel; otherwise its internal format selector maps GEMM to AwqGEMMLinear (or AwqTorchLinear on NPU), GEMV to AwqGEMVLinear, GEMV_FAST to AwqGEMVFastLinear, and LLM_AWQ to LLMAwqLinear. The normal public lifecycle chooses a compatible packing backend first, including portable GEMM packing on non-CUDA hosts. The processor's internal fallback selector alone is not the entire public backend-selection policy.
Calibration is established at processor construction. set_calibration_dataset() deliberately raises NotImplementedError, and verify_calibration_dataset() rejects missing calibration. Continuation methods save/restore AWQ loss, sample-count, and batch-size state; this does not make an ordinary inference checkpoint equivalent to a complete resumable quantization checkpoint. See Looper processors and Quantization lifecycle.
Chunked scale search is enabled by default. It prepares the inspected module's device placement and rotary scaffolding once, generates reference outputs in replay batches, and initially moves each reference chunk to CPU. However, _compute_best_scale() subsequently constructs a list containing all reference chunks moved to the inspected module's device before evaluating the grid. _prepare_module_forward() also moves the full replay input to that device. Candidate outputs and their loss comparisons are processed chunk by chunk, but the current implementation does not keep the full reference exclusively on CPU or stream replay inputs from CPU one chunk at a time.
Weight statistics stream across linears, and activation sums use chunked FP32 reductions; computing inp.abs() still materializes an activation-sized tensor. Large original-weight master copies may be staged on the host when their combined size exceeds max_chunk_memory. The replay-size estimate uses input width and dtype, not an exact account of the inspected module's intermediate activations or output width, and its minimum can be the capture batch size. Treat max_chunk_memory as a heuristic for individual work, not a cap on total scale-search memory. Disabling scale_search_chunked_activations restores the eager path that assembles full reference/candidate outputs.
The replay machinery sanitizes kwargs against each module's actual forward signature, removes use_cache, aligns masks and positional metadata to the replay input, and handles rotary-device placement. Packed activation rows cannot automatically reuse an arbitrary original attention mask or position-ID tensor; incompatible metadata is repacked or dropped. Variable-length capture can fall back to the latest batch for aligned replay. Models can opt into preserving explicit position embeddings through their AWQ policy.
This is why new architectures need model-specific grouping and capture policies, not just a list of all nn.Linear modules. See Model definitions and module tree.
The search methods are internal AWQProcessor APIs; their source signatures expose the difference between the fixed scale-ratio grid and the clip method's parameterized grid:
def _compute_best_scale(
    self,
    x: torch.Tensor,
    w_mean: torch.Tensor,
    x_mean: torch.Tensor,
    module2inspect: torch.nn.Module,
    linears2scale: List[nn.Linear],
    fp16_output: torch.Tensor,
    kwargs: Dict={},
    replay_batch_size: Optional[int] = None,
    prepared_forward: Optional[Tuple[torch.Tensor, Dict]] = None,
):
def _compute_best_clip(
self,
w: torch.Tensor,
input_feat: torch.Tensor,
n_grid=20,
max_shrink=0.5,
n_sample_token=512,
):_compute_loss() flattens reference and candidate outputs, compares them in chunks, subtracts in the output dtype, casts the differences to FP32, and sums their squares in FP32 with an FP64 running total. It divides by the number of output elements. The chunked replay path uses the same reconstruction objective and avoids assembling one contiguous reference tensor, but retains its complete reference as a list of device-resident chunks. These paths need not have identical floating-point reduction order for different chunk boundaries.
When a group lacks sufficient calibration coverage, configured fallback decisions can exclude it from normal AWQ scaling/clipping. AWQ's fallback implementation calls apply_quant(..., scales_list=[]): direct pseudo-quantization rather than a call to the separate generic RTN processor. Do not assume that Fallback.smooth or a generic RTN SmoothMSE policy will be applied by this AWQ fallback path. For token-row aggregation, fallback coverage uses raw routed token counts rather than the deliberately bounded retained sample; other aggregation modes use retained rows when available.
With fallback disabled, empty tensors present in the input-feature map trigger a RuntimeError. This is not a universal guarantee that every invalid scaling group raises: missing feature-map entries and predecessor/linear dimension mismatches can be filtered out. If the model supplies no scaling configuration, or filtering leaves no valid groups and no fallback work, the layer is finalized without normal AWQ search. Inspect warnings and actual quantized modules when adding an architecture or diagnosing incomplete quantization.
The displayed per-module loss is the associated scale-search reconstruction loss. Modules without an applicable scale-search result are logged as "not applicable"; it is not a perplexity, model accuracy score, or universal GPTQ-comparable loss. Retained-token logging also must not be confused with the number of original calibration examples. Evaluate the saved model separately; see Evaluation.
Scale and clip searches live in AWQProcessor; the AWQ package provides transformations, packing, calibration utilities, and Triton execution components.
Path under gptqmodel/quantization/awq/
|
Main symbols | Role |
|---|---|---|
quantize/scale.py |
apply_scale, apply_clip, scale_ln_fcs, scale_fc_fc, scale_fc_fcs, scale_gelu_fc
|
Fold searched scales into supported predecessor/linear patterns; clamp weights using searched clip bounds. |
modules/act.py |
ScaledActivation |
Wrap an activation and divide its output by channel scales. |
modules/triton/gemm.py |
awq_dequantize_triton, awq_gemm_triton, JIT kernels |
GEMM-format INT4 unpack/dequantization and fused matrix multiplication. |
modules/triton/scheduler.py |
AwqTritonPlan, select_awq_triton_plan, candidate_plans, rule/cache helpers |
Deterministic, device/dtype/exact-shape-aware dispatch policy; no benchmark or kernel compilation during plan selection. |
utils/packing_utils.py |
pack_awq, pack_awq_columns, unpack_awq, reverse_awq_order, pack_exllama, unpack_reorder_pack, dequantize_gemm
|
Integer layout conversions and Torch reconstruction. |
utils/calib_data.py |
get_calib_dataset |
Standalone AWQ calibration-block helper, distinct from the public model's dataset-preparation lifecycle. |
utils/module.py |
get_named_linears, get_op_by_name, set_op_by_name, get_op_name, append_str_prefix, exclude_layers_to_not_quantize
|
Resolve modules and names, enumerate linears, and filter exclusions. |
utils/utils.py |
get_module_by_name_suffix, simple_dispatch_model, set_module_name, compute_memory_used_pct, get_lowest_memory_device_index
|
Module lookup/replacement, Accelerate hooks/device-map dispatch, CUDA memory helpers. |
Package __init__.py files |
Package boundaries | These do not replace AWQProcessor with a separate public quantization engine. |
apply_scale(module, scales_list, input_feat_dict=None) dispatches according to predecessor type. Norm-to-linear folding divides norm parameters and multiplies downstream linear weights; Gemma/Gemma2 norm semantics have explicit handling. Linear-to-linear folding divides the appropriate trailing predecessor weights/bias and multiplies one or several downstream linears. Activation-to-linear folding uses a scaled activation wrapper. When features are supplied, the same input-channel scale is divided out of captured downstream inputs. apply_clip(module, clip_list) reshapes weights into clip groups, clamps, and restores the module's prior device placement after working on its execution device.
The standalone calibration helper has this source signature:
def get_calib_dataset(
    data: Union[str, List[str], List[List[int]]] = "pileval",
    tokenizer=None,
    n_samples=128,
    max_seq_len=512,
    split="train",
    text_column="text",
):
"pileval" resolves to mit-han-lab/pile-val-backup, validation split; other dataset strings use the requested split. String datasets are shuffled with seed 42. It accepts lists of text or token-ID lists, skips empty or overlong examples, concatenates accepted tokens, and returns only full max_seq_len blocks, dropping the final partial block. n_samples counts accepted input examples, not returned blocks. Supply nonempty data with enough accepted tokens: the helper is not an empty-dataset recovery mechanism. Its defaults are not defaults for model.quantize().
Let K = in_features, N = out_features, G be the resolved group size, and Z = calculate_zeros_width(K, G). Shapes below describe the usual 4-bit stored layouts before backend-specific runtime repacking. These layouts are not interchangeable.
| Format enum/value | Weights | Scale/zero storage | Key differences |
|---|---|---|---|
FORMAT.GEMM, "gemm"
|
qweight: INT32 [K, N/8]
|
scales: floating [K/G, N]; qzeros: INT32 [K/G, N/8]
|
Weights and zero points pack output columns using classic AWQ INT4 interleaving. Broadest AWQ runtime compatibility. |
FORMAT.GEMV, "gemv"
|
qweight: INT32 [N, K/8]
|
scales: FP16 [N, Z*8]; qzeros: INT32 [N, Z]
|
Input-axis packing and padded group storage; not GEMM with a different dispatch flag. |
FORMAT.GEMV_FAST, "gemv_fast"
|
qweight: INT16 [N/4, K] for the fast packer |
scales and qzeros: FP16 [Z*8, N]
|
Permuted/interleaved fast layout. Despite its name, qzeros holds the floating additive offset -scale * integer_zero, not packed integer zero codes. |
FORMAT.LLM_AWQ, "llm-awq"
|
Same fast INT16 layout | FP16 scales and scaled_zeros
|
LLMAwqLinear subclasses the fast implementation and changes the zero-buffer name/format identity. |
FORMAT.MARLIN, "marlin"
|
Backend/legacy compatibility format | Loader/runtime-specific handling | Advertised by the AWQ format registry, but fresh BaseQModel.quantize() rejects FORMAT.MARLIN as deprecated. Use GEMM plus Marlin inference instead. |
FORMAT.BITBLAS, "bitblas"
|
BitBLAS representation | BitBLAS quantization state | Supported format/backend route; do not treat it as a synonym for raw GEMM tensors. The public quantization lifecycle can select the BitBLAS packer. |
For INT4 GEMM, packing uses:
AWQ_ORDER = [0, 2, 4, 6, 1, 3, 5, 7]
AWQ_REVERSE_ORDER = [0, 4, 1, 5, 2, 6, 3, 7]
pack_awq() preserves this established INT4 layout and rejects INT4 dimensions not divisible by eight. For other 2–8-bit widths it uses a continuous little-endian bit stream, including codes crossing 32-bit word boundaries; reverse_awq_order() is a no-op outside INT4. Support for these helper layouts does not make every optimized inference kernel support those widths.
The lower-level pack_awq_columns() packs complete words and ignores an incomplete trailing group. Callers must enforce shape compatibility; it is not an automatic-padding API. GEMV_FAST's pack_intweight() uses interleave=4, kstride=64, and additional input/output permutations, imposing reshape constraints even though its class's generic divisibility metadata is permissive.
calculate_zeros_width() pads the group axis in blocks of eight, with additional multipliers for group sizes 64, 32, and 16. The fast formats' padded scales/offsets must be preserved. Do not infer scale shapes from K/G alone or change only version in JSON to convert formats.
AWQConfig writes both version and format for AWQ compatibility and derives zero_point from not sym. Config loading also recognizes LLM-AWQ metadata conventions. For serialized fields, model shards, and external checkpoint compatibility, see packing formats and compatibility.
select_quant_linear() in gptqmodel/utils/importer.py normalizes backend aliases using the quantization method, validates the method/format pair, and filters candidate classes by their declared contracts and runtime availability. AUTO uses the registry's per-format priorities and validation; it is not a startup benchmark. Multi-device selection validates candidates on each exact device ordinal. Trainable auto-selection additionally filters for training support.
Use the canonical method-specific backend names below. Compatibility aliases such as gemm, gemm_triton, gemv, gemv_fast, torch, torch_awq, torch_fused_awq, torch_int8_awq, bitblas_awq, marlin, and machete are normalized for AWQ; the filename spelling is not necessarily the canonical backend string. In particular, torch_aten_kernel_awq.py corresponds to AWQ_TORCH_ATEN / "awq_torch_aten".
The following table lists AWQ kernel modules' declared contracts. -1 means one group across the input dimension, subject to backend validation of the resolved width. Dtype entries are class validation dtypes; runtime casting and native-extension caveats follow the table. All rows refer to AWQ, not similarly named GPTQ kernels.
| Module / class | Canonical backend/string | Input formats | Bits; group sizes | Device/platform and declared dtype |
|---|---|---|---|---|
gemm_awq.py / AwqGEMMLinear
|
AWQ_GEMM / awq_gemm
|
GEMM | 4; -1,16,32,64,128
|
CUDA; all platforms; FP16/BF16. Native CUDA extension required. |
gemm_awq_triton.py / AwqGEMMTritonLinear
|
AWQ_GEMM_TRITON / awq_gemm_triton
|
GEMM | 4; -1,32,64,128
|
CUDA/ROCm; Linux/Windows; FP16. Requires K % 32 == 0, N % 8 == 0. |
gemv_awq.py / AwqGEMVLinear
|
AWQ_GEMV / awq_gemv
|
GEMV | 4; -1,64,128
|
Declares CUDA/ROCm, all platforms; FP16. Requires N % 64 == 0; native runtime caveat below. |
gemv_fast_awq.py / AwqGEMVFastLinear, LLMAwqLinear
|
AWQ_GEMV_FAST / awq_gemv_fast
|
GEMV_FAST; LLM_AWQ through subclass | 4; -1,16,32,64,128
|
Declares CUDA/ROCm, all platforms; FP16; INT16 qweight. Native runtime and packer-shape caveats below. |
marlin_awq.py / AwqMarlinLinear
|
AWQ_MARLIN / awq_marlin
|
GEMM, MARLIN | 4 or 8; -1,32,64,128
|
NVIDIA CUDA, Linux, compute capability >= 8.0; FP16/BF16. Not ROCm. |
machete_awq.py / AwqMacheteLinear
|
AWQ_MACHETE / awq_machete
|
GEMM, MARLIN at class level | 4 or 8; -1,32,64,128
|
CUDA, Linux, Hopper SM90 only; FP16/BF16; K % 64 == 0, N % 128 == 0; desc_act=False. |
bitblas_awq.py / AWQBitBlasKernel (AwqBitBLASLinear alias) |
AWQ_BITBLAS / awq_bitblas
|
GEMM, BITBLAS | 4; -1,32,64,128
|
CUDA, Linux/Windows; FP16/BF16; K and N divisible by 16. |
torch_awq.py / AwqTorchLinear
|
AWQ_TORCH / awq_torch
|
GEMM | 2–8; -1,16,32,64,128
|
All device/platform families; FP16/BF16; N % 8 == 0. Torch operation support on the device still matters. |
torch_fused_awq.py / TorchFusedAwqLinear
|
AWQ_TORCH_FUSED / awq_torch_fused
|
GEMM | 4; -1,16,32,64,128
|
CPU/XPU, all platforms; FP32/FP16/BF16 inherited contract, with fused-op dtype/device restrictions. |
torch_aten_kernel_awq.py / TorchAtenAwqLinear
|
AWQ_TORCH_ATEN / awq_torch_aten
|
GEMM | 4; 32,64,128,256
|
CPU, all platforms; FP16/BF16; local ATen CPU int4pack ops required. |
torch_cpu_avx512_awq.py / TorchCpuAvx512AwqLinear
|
AWQ_TORCH_CPU_AVX512 / awq_torch_cpu_avx512
|
GEMM | 4; 16,32,64,128,256,512
|
CPU, Linux, AVX512-BF16; BF16 only; K % 2 == 0, N % 32 == 0, complete groups. |
torch_int8_awq.py / TorchInt8AwqLinear
|
AWQ_TORCH_INT8 / awq_torch_int8
|
Retired | No usable runtime | Validation fails and construction raises NotImplementedError; persistent INT4-to-INT8 expansion is disabled. |
mlx_awq.py / MlxAWQLinear, MlxAWQGroup16Linear
|
MLX / mlx
|
Packed-transfer holders for GEMM, GEMV, GEMV_FAST, LLM_AWQ, MARLIN, BITBLAS | Depends on source holder/transfer path | Apple Silicon, macOS arm64, Metal; mlx and mlx_lm required. These are MLX runtime modules, not interchangeable Torch qlinear classes. |
The file list is not the entire registry: exllamav2_awq.py also supplies AwqExllamaV2Linear (AWQ_EXLLAMA_V2 / awq_exllama_v2) for 4-bit GEMM with groups -1,32,64,128, CUDA on Linux/Windows, K/N divisible by 32, and FP16/BF16 interface dtypes. It unpacks/reorders/re-packs AWQ codes, converts scales/computation to FP16, and restores the input dtype at output. Group 16 is deliberately disabled; ROCm is not declared supported. It requires ExLlamaV2 runtime initialization and scratch space.
swordfish.py additionally defines AwqSwordfishLinear under AWQ_SWORDFISH / awq_swordfish, with its own validation/repacking policy. Consult Kernel backends reference for that implementation and the complete registry, rather than assuming all AWQ backend names are aliases for native GEMM.
AwqGEMMLinear packs the GEMM layout using the shared AWQ column packer. Its autograd function saves packed weights/zeros/scales and input metadata, not a full activation tensor. Empty input returns an appropriately shaped output without launching the native kernel.
For up to 1024 flattened input rows it calls the native GEMM wrapper with split_k_iters=8. For more than 1024 rows it temporarily dequantizes the weight and uses torch.matmul, then releases the operation-local dense tensor. The threshold is based on all leading input dimensions flattened into rows, not on one sequence-length field alone. Input-gradient backward also temporarily dequantizes; packed integer weights themselves do not become trainable floating-point parameters.
GPTQMODEL_FP32_ACCUM defaults to enabled and controls the native GEMM accumulation choice. Disabling it is a numerical/performance choice, not a different checkpoint format.
Triton requires version >= 2.0.0; when Python's GIL is disabled, validation requires >= 3.4.0. The qlinear's declared dtype is FP16, although its forward wrapper can cast other input tensors to FP16 and restore output dtype. Low-level Triton GEMM requires contiguous rank-2 FP16 input/scales, INT32 weights/zeros, matching devices, and consistent packed shapes. Group 16 is not supported.
AwqTritonPlan records path, tile sizes, split-K, and optional warps/stages. Defaults are tiles (32,32,32), split-K 8, and implicit launch warps/stages. Historical dispatch uses fused execution for M <= 128 and temporary dequantization plus dense matmul for M > 128.
GPTQMODEL_AWQ_TRITON_SCHEDULE selects "auto" (default) or "legacy". Auto can use exact measured device/shape/dtype rules; the built-in table is gated on the source's precise RTX 4090 device profile and FP16 input/compute/output with FP32 accumulation. Unlisted cases retain legacy behavior; there is no general promise that one GPU family's threshold applies to another. Runtime measured rules can be registered with register_awq_triton_rule(), and explicit plans are validated before launch. Training deliberately keeps legacy scheduling.
The scheduler has bounded plan/warmup caches (256 entries) and separate helpers to clear plans, warmup state, or registered rules. CUDA Graph capture performs cache lookup only and requires a successful eager prewarm for the exact plan/request; discovery, compilation, and benchmarking do not occur during capture. candidate_plans() describes an offline search space rather than performing online autotuning.
The low-level execution entry point is:
def awq_gemm_triton(
    input: torch.Tensor,
    qweight: torch.Tensor,
    scales: torch.Tensor,
    qzeros: torch.Tensor,
    split_k_iters: int,
    block_size_m: int = 32,
    block_size_n: int = 32,
    block_size_k: int = 32,
    fp32_accum: bool = FP32_ACCUM,
    output_dtype: torch.dtype | None = None,
    num_warps: int | None = None,
    num_stages: int | None = None,
) -> torch.Tensor:
FP32 accumulation defaults to enabled here too. Split-K 1 overwrites an uninitialized output buffer; multi-split execution starts with a zeroed accumulation buffer and uses atomic additions. output_dtype controls the final cast, not an alternative packed representation.
Native GEMV flattens leading input dimensions and chooses awq_gemv_forward() for up to eight rows or awq_gemmv2_forward() for more than eight. Computation/scales are FP16; the wrapper restores the original input dtype where it casts inputs.
Its validator resolves group_size=-1 to K and then accepts only normalized groups 64 or 128. Thus -1 is not general row-wide support for arbitrary input widths in this native backend. The class-wide N % 64 == 0 requirement protects the GEMMV2 path even for requests currently using at most eight rows.
GEMV_FAST uses the decode kernel only for rank-3 input with batch_size < 8 and n_tokens == 1. Other shapes, including flattened rank-2 input, use the prefill entry point. Its fast packer requires K % 64 == 0 and N % 4 == 0 for its reshapes; these constraints are additional to the generic class metadata. Runtime preparation makes weights, scales, offsets, and bias contiguous and resident on the execution device. LLMAwqLinear uses that same execution logic with the scaled_zeros buffer.
ROCm caveat: GEMV and GEMV_FAST class metadata lists ROCm, but these forwards call the shared AWQ native extension, whose sources contain CUDA-specific headers and inline PTX. The loader's requires_cuda=True checks Torch's CUDA-facing device API, which ROCm also uses; that flag alone does not establish NVIDIA-only support or HIP compatibility. For ROCm deployments, GEMM-format checkpoints with validated Triton or portable Torch execution avoid relying on these native kernels. Do not advertise native GEMV/fast support solely from SUPPORTS_DEVICES.
Marlin loads AWQ affine integer codes and repacks/permutates weights, scales, zero points, and bias into its runtime layout. AWQ uses empty activation-order indices. Workspace and indexing buffers are runtime-only and must be initialized before forward. NVIDIA compute capability >= 8.0 is checked on the target device, and ROCm is rejected.
Explicit AWQ_MARLIN can enable runtime tile padding for supported 4-bit tail shapes. Auto selection deliberately leaves tile-misaligned shapes to another backend. Output width must still be divisible by 32 // bits; padding cannot repair a partially packed integer word. Non-4-bit tile-misaligned shapes are rejected. Thus permissive generic divisibility metadata does not remove these checks.
Machete removes AWQ interleaving, packs/prepacks integer weights for its matrix product, and converts zero points to additive -scale * zero values. Its static runtime validator is Hopper-only, exactly compute capability (9,0), not “Hopper or newer.” It also checks opt-in shared memory. Blackwell is not accepted by this validator. Machete and Marlin classes may advertise MARLIN compatibility, but the high-level loader restricts legacy MARLIN checkpoints to their matching Marlin route (or supported MLX transfer); class metadata alone does not override loader policy.
AWQBitBlasKernel builds an unsigned affine BitBLAS quantization config even for symmetric AWQ, because stored AWQ codes retain zero points. It can pack from pseudo-quantized weights/scales/zeros or repack a raw AWQ GEMM module by unpacking codes and reversing AWQ interleaving.
The optional dependency in this revision is bitblas==0.1.0.post1; the runtime minimum is 0.1.0.post1. BF16 is an interface dtype, but the shared implementation computes low-bit BF16 modules in FP16 and casts at the module boundary because that BitBLAS version's bundled CUTLASS cannot compile its generated BF16 dequantization path. Target detection also normalizes unsupported targets; do not infer native coverage of every newer NVIDIA architecture from a CUDA device declaration. See Inference backends for installation and backend selection.
AwqTorchLinear uses dequantize_gemm() followed by torch.matmul, keeping packed weights as persistent state and constructing dense weights only for the current computation. It accepts 2–8-bit GEMM packing and preserves input dtype at output. FP16/BF16 inputs use that compute dtype; other input dtypes are cast to FP16 internally and restored at output. Its current forward() deliberately remains the dense reference path and does not invoke its CPU-AVX512 helper methods. Select AWQ_TORCH_CPU_AVX512 explicitly, or use AUTO to choose a compatible packed kernel, for that optimized BF16 path. The portable implementation does not promise the latency or peak workspace of a fused packed kernel.
TorchFusedAwqLinear reverses AWQ packing into the CPU/XPU fused representation. CPU uses ATen int4 packing, and XPU uses _weight_int4pack_mm_with_scales_and_zeros. When fused execution is unavailable, it falls back to temporary weight reconstruction and matrix multiplication. AWQ has no GPTQ g_idx activation reorder to apply.
TorchAtenAwqLinear requires local aten::_convert_weight_to_int4pack_for_cpu and aten::_weight_int4pack_mm_for_cpu availability. On its first eligible inference call it transforms packed weights and affine parameters, matching scales/zero metadata to the FP16/BF16 activation dtype. Once transformed, it requires one consistent activation dtype per layer. A non-fused/training path uses temporary dequantization. Availability of a symbol in one PyTorch version does not guarantee it exists in another build.
TorchCpuAvx512AwqLinear is inference-only and requires AVX512-BF16 plus the shared CPU extension's packing/GEMM ops. It keeps scales and bias in FP32, consumes BF16 activations, and uses FP32 accumulation. For FP16 execution, use a compatible ATen path instead of forcing this BF16-only backend. Calling train(True) raises. Its transformed representation stays quantized; it does not retain an expanded INT8 or floating weight cache.
TorchInt8AwqLinear is retired: validation returns failure and construction raises because persistent INT4-to-INT8 expansion is disabled. Select AUTO or a compatible packed backend; use AWQ_TORCH for GEMM-format portable fallback. Changing backend aliases cannot reactivate the retired implementation.
MLX inference is selected with BACKEND.MLX, not an AWQ_MLX enum. Validation requires macOS (Darwin), arm64, importable mlx.core/mlx_lm, and available Metal. The optional dependency group in this revision declares mlx>=0.32.4, with mlx_lm>=0.31.3 for Python < 3.11 and mlx_lm>=0.32.2 for Python >= 3.11. Install the extras matching the release:
pip install 'gptqmodel[mlx]'The checkpoint-holder classes in qlinear/mlx.py validate source tensor layouts before conversion. AwqMlxQuantLinear accepts GEMM, bits 2–8, groups -1,16,32,64,128, FP16 checkpoint scales, and no activation ordering; separate holders cover GEMV, GEMV_FAST, LLM_AWQ, MARLIN, and BITBLAS. Fast holders use INT16 qweights and require K % 64 == 0, N % 8 == 0; GEMV holders require K % 32 == 0, N % 64 == 0. Holder forward() is not a Torch inference implementation: conversion must replace holders with MLX modules.
utils/mlx.py first attempts packed transfer without requantization. GEMV, fast, LLM_AWQ, MARLIN, and BITBLAS routes require transferable packed state instead of silently falling back to generic conversion. A generic GEMM conversion fallback can dequantize/requantize when exact packed transfer is unavailable; this should not be described as a universally lossless conversion.
At runtime, MlxAWQLinear wraps an affine quantized linear and casts its output to the input activation dtype. MlxAWQGroup16Linear has exact group-16 metadata handling and packed Metal execution: one-row decode uses its packed kernel; small BF16 prefill (1 < rows <= 16, N <= 2048) uses a tiled packed path; other prefill uses the parent group-16 implementation. It supports storage widths 2,3,4,5,6,8 in its direct constructor; source 7-bit storage is mapped to 8-bit MLX codes by transfer policy. Group-16 transfer requires input width divisible by 32. FP16 and BF16 are separate runtime paths; checkpoint-holder FP16 validation does not imply BF16 activations should be downcast permanently. See MLX and Apple Silicon.
gptqmodel/utils/awq.py exposes the shared native runtime through the central extension API. Its extension is named gptqmodel_awq_ops, uses the gptqmodel_awq namespace, and declares python_abi_dependent=False. Required registered operations include GEMM, FP32-reduction GEMM, GEMMV2, GEMV, fast prefill/decode, and dequantization.
| Helper | Purpose |
|---|---|
awq_runtime_available() -> bool |
Ask the central extension API whether the AWQ runtime is available. |
awq_runtime_error() -> str |
Empty string when available; otherwise the extension error or "CUDA AWQ runtime unavailable.". |
prewarm_awq_extension() -> bool |
Explicitly request AWQ extension loading/building before a latency-sensitive operation. |
clear_awq_extension_cache() -> None |
Clear the loader's AWQ cache through the shared singleton; not an instruction to delete all on-disk build artifacts. |
The operation wrappers have these source signatures:
def awq_gemm_forward(input, qweight, scales, qzeros, split_k_iters, fp32_accum: bool):
def awq_dequantize_weights(qweight, scales, qzeros, split_k_iters, thx, thy, dbg):
def awq_gemmv2_forward(input, qweight, scales, qzeros, group_size, split_k_iters):
def awq_gemv_forward(input, qweight, scales, qzeros, group_size):
def awq_fast_gemm_forward_prefill(input, qweight, scales, qzeros):
def awq_fast_gemv_forward_decode(input, qweight, scales, qzeros, m, n, k, group_size):
These are internal packed-tensor interfaces, not a calibration API. Their argument order is significant: qlinear callers arrange their stored buffers to match these wrappers.
The JIT sources are gptqmodel_ext/awq/torch_bind.cpp, quantization/gemm_cuda_gen.cu, quantization/gemv_cuda.cu, gemm_fast_cuda_entry.cu, and gemv_fast_cuda_entry.cu under that extension directory. Include-path discovery checks for cusparse.h. The loader sets requires_cuda=True; on NVIDIA, building these kernels requires CUDA-enabled Torch and a suitable CUDA development toolchain, not just runtime libraries. The shared loader has ROCm-aware build handling, but that does not make this extension's CUDA-specific kernels portable. See the ROCm caveat above.
| Environment variable | Role |
|---|---|
GPTQMODEL_AWQ_BUILD_ROOT |
Override the AWQ JIT build directory. |
GPTQMODEL_AWQ_FORCE_REBUILD |
Force-rebuild control passed to the shared loader. |
GPTQMODEL_EXT_VERBOSE |
Verbose extension build output. |
GPTQMODEL_FP32_ACCUM |
Native/Triton GEMM numerical accumulation policy; defaults enabled. |
GPTQMODEL_AWQ_TRITON_SCHEDULE |
Triton schedule mode, default auto; alternative legacy. |
awq_gemm_pack_backend(device_type, is_rocm, weight_only), defined in utils/backend.py, returns AWQ_TORCH for weight-only lifecycle exports, ROCm, or any non-CUDA device; otherwise it returns AWQ_GEMM. Both pack the same AWQ GEMM layout. The public model lifecycle uses this to avoid requiring CUDA headers just to write a GEMM checkpoint on another device. NPU AWQ quantization explicitly requires GEMM format.
The source revision declares Python >= 3.10, torch>=2.14.1, and transformers>=5.20.2. These are revision-specific package requirements, not minimum versions for the AWQ algorithm itself. Optional kernel requirements remain additional constraints; follow Installation and quickstart for the installed release.
AWQConfig.gsq refines scalar AWQ export after the ordinary solve on 4-bit GEMM, GEMV, GEMV_FAST, or LLM_AWQ formats; non-GEMM formats additionally require group_size of -1, 32, 64, or 128. AWQConfig.gsq_training selects the staged dense-Llama block-training recipe with the AWQ initializer, exporting 4-bit GEMM with AWQ's scaled weights, integer zero points, and packer. gsq and gsq_training are mutually exclusive on one config. See GSQ.
| Symptom or assumption | What to check |
|---|---|
| “AWQ defaults to asymmetric quantization.” | This implementation inherits sym=True. Choose sym=False explicitly if needed; serialized zero_point is its inverse. |
“mse.norm=0 disables AWQ clipping.” |
It does not. AWQ clipping is controlled by the processor's apply_clip, and the clip scratch budget is mse.clip_grid_budget. |
“SmoothMSE(steps=...) changes AWQ's 20-ratio search.” |
It does not; generic smoother normalization is separate from AWQ's native scale/clip searches. |
| Unexpected quantization memory use | Distinguish processor chunk estimates, clip scratch budgets, the full replay input and all reference chunks moved to the scoring device, model weights, and multi-GPU cloning/offload memory. Chunked search reduces some intermediate allocations but none of these settings is a total-memory cap. |
| Clip assertion on a narrow projection |
_compute_best_clip() batches output channels in 256/64 and asserts divisibility. Generic kernel metadata does not remove calibration-time shape requirements. |
| Bad or missing MoE calibration coverage | Inspect raw/retained token counts, selected scale feature, routing/capture policy, and fallback logs. A successful direct fallback is not evidence that normal AWQ scale search ran. |
| Native extension missing or build fails | Inspect awq_runtime_error(), CUDA/toolchain/header availability, build root, and verbose output. GEMM-format portable Torch packing/inference does not require that native extension. |
| ROCm is listed but native GEMV fails | Runtime extension support is stricter than GEMV class metadata. Prefer a validated GEMM-format ROCm path rather than assuming CUDA native sources work on HIP. |
| Triton rejects group 16 | Supported groups are -1,32,64,128; select another compatible backend or quantize with a compatible group size. |
| CUDA Graph capture requests eager prewarm | Run the exact shape/device/dtype/request eagerly before capture; a different shape or plan's warmup is not sufficient. |
| Explicit Marlin tails fail | Check packed output-word alignment, bit width, tile-padding policy, and target capability. Auto intentionally does not enable the explicit 4-bit padding route. |
| Machete fails on Blackwell | This revision accepts exact SM90 and has no Blackwell image in its Machete validator. Use another backend. |
| CPU ATen dtype error after initial inference | The transformed layer's scales/zeros match the first fused activation dtype. Keep that dtype consistent. |
| AVX512 path rejects FP16 | It requires BF16 activations and AVX512-BF16, not merely an arbitrary AVX512-capable CPU. |
AWQ_TORCH_INT8 fails immediately |
It is retired; use a packed implementation or portable GEMM fallback. |
| Renaming JSON format fields breaks load | GEMM, GEMV, and fast layouts differ in axes, permutations, word dtype, padding, and zero representation. Metadata editing is not conversion. |
| A GEMM checkpoint is called “Marlin AWQ.” | Usually this describes the inference backend. Inspect actual format/version and the loaded kernel, not the model repository name. |
| Comparing logged loss to perplexity | Scale reconstruction MSE is a local search metric, not a task-level quality measure. Evaluate full-model behavior separately. |
Paths below are relative to the verified source tree.
| Area | Key paths |
|---|---|
| Configuration and serialization |
gptqmodel/quantization/config.py, gptqmodel/quantization/__init__.py
|
| AWQ lifecycle, scale/clip search, MSE | gptqmodel/looper/awq_processor.py |
| Shared preprocessor planning | gptqmodel/looper/module_preprocessor.py |
| AWQ graph transforms |
gptqmodel/quantization/awq/quantize/scale.py, gptqmodel/quantization/awq/modules/act.py
|
| Packing and calibration helpers |
gptqmodel/quantization/awq/utils/packing_utils.py, calib_data.py, module.py, utils.py in that directory |
| Triton implementation/policy |
gptqmodel/quantization/awq/modules/triton/gemm.py, gptqmodel/quantization/awq/modules/triton/scheduler.py
|
| Public model integration |
gptqmodel/models/auto.py, gptqmodel/models/base.py, gptqmodel/models/loader.py, gptqmodel/models/writer.py
|
| Backend registry/validation |
gptqmodel/utils/backend.py, gptqmodel/utils/importer.py, gptqmodel/nn_modules/qlinear/__init__.py
|
| Native AWQ runtime |
gptqmodel/utils/awq.py, gptqmodel/utils/cpp.py, gptqmodel/extension.py, gptqmodel_ext/awq/
|
| Native GEMM/GEMV/fast |
gptqmodel/nn_modules/qlinear/gemm_awq.py, gemv_awq.py, gemv_fast_awq.py in that directory; gptqmodel/utils/gemv.py
|
| Triton qlinear | gptqmodel/nn_modules/qlinear/gemm_awq_triton.py |
| Marlin |
gptqmodel/nn_modules/qlinear/marlin_awq.py, gptqmodel/utils/marlin.py
|
| Machete |
gptqmodel/nn_modules/qlinear/machete_awq.py, gptqmodel/utils/machete.py
|
| BitBLAS |
gptqmodel/nn_modules/qlinear/bitblas_awq.py, gptqmodel/nn_modules/qlinear/bitblas.py
|
| Portable/fused Torch |
gptqmodel/nn_modules/qlinear/torch_awq.py, torch_fused_awq.py, torch_fused.py in that directory |
| CPU ATen/AVX512 |
gptqmodel/nn_modules/qlinear/torch_aten_kernel_awq.py, torch_aten_kernel.py, torch_cpu_avx512_awq.py, torch_cpu_avx512.py in that directory; gptqmodel/utils/cpu_features.py
|
| Retired INT8 backend | gptqmodel/nn_modules/qlinear/torch_int8_awq.py |
| Additional AWQ runtimes |
gptqmodel/nn_modules/qlinear/exllamav2_awq.py, gptqmodel/nn_modules/qlinear/swordfish.py
|
| MLX runtime/transfer |
gptqmodel/nn_modules/qlinear/mlx_awq.py, mlx.py, mlx_group16.py in that directory; gptqmodel/utils/mlx.py, gptqmodel/utils/mlx_packing.py
|
| Generic SmoothMSE consumers |
gptqmodel/quantization/gptq.py, gptqmodel/quantization/qqq.py, gptqmodel/quantization/rtn.py
|
| Dependency requirements |
pyproject.toml, requirements.txt
|
- What is quantization?
- Installation and quickstart
- Quantization lifecycle
- QuantizeConfig reference
- GSQ
- Rotation, smoothing, and norm tuning
- packing formats and compatibility
- Loading and inference
- Inference backends
- Kernel backends reference
- Looper processors
- Model definitions and module tree
- Multimodal and MoE models
- Memory offload and multi-GPU
- MLX and Apple Silicon
- Evaluation
- Troubleshooting and FAQ
- Developer guide