Repository navigation
HuggingFace Integration
Documentation home · Quickstart · Lifecycle
On this page
- Overview
- Workflow at a glance
- Integration layers and ownership
- Loading through GPT-QModel and Transformers
- Config, dtype, tokenizer, and remote-code compatibility
- GGUF artifacts hosted on the Hub
- Hub download and ModelScope integration
- Stable
hf_kernel packing API - Local Hugging Face kernel ports
- Bundled MiniMax M2 Hugging Face implementation
- PEFT LoRA training and adapter interchange
- Saving and uploading to the Hub
- Pitfalls and edge cases
- Source files
- See also
GPT-QModel integrates with the Hugging Face ecosystem at several distinct levels: model/configuration/tokenizer loading, Transformers and Optimum quantized-layer selection and packing, checkpoint serialization, PEFT adapter interoperability, and local replacements for optional Hub kernels. These layers should not be confused: a checkpoint being hosted on the Hub does not imply that every Transformers backend can execute its packing format.
This page describes source revision c1976918, including compatibility code for Transformers 5.x. Dependency minimums in this tree are transformers>=5.20.2 (requirements.txt) and optimum>=2.3.0 (the hf extra in pyproject.toml). Install the integration extra and PEFT separately when fine-tuning:
pip install 'gptqmodel[hf]' peftBackend availability still depends on hardware and optional dependencies. Selecting a CUDA kernel in Transformers does not make it usable on CPU, ROCm, or Apple silicon. See Loading and Inference, Inference Backends, and Packing Formats and Compatibility.
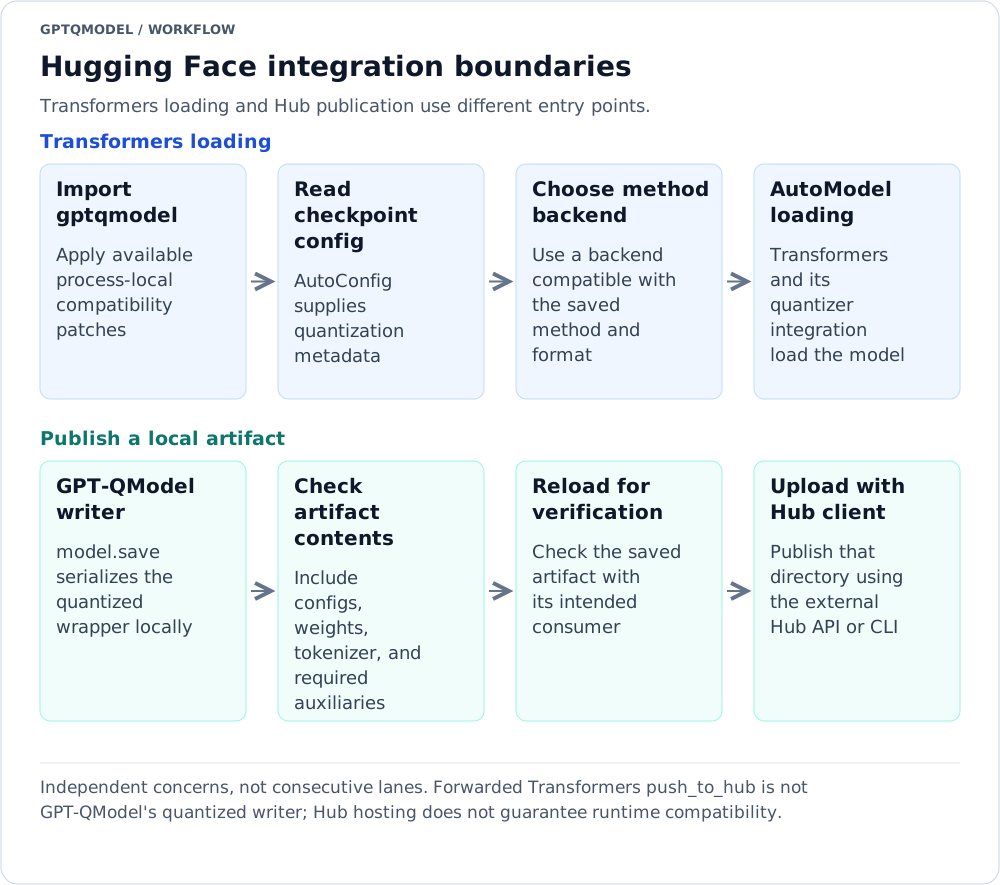
Reading the diagram: Independent concerns, not consecutive lanes. Forwarded Transformers push_to_hub is not GPT-QModel's quantized writer; Hub hosting does not guarantee runtime compatibility.
Text version of the workflow
- Transformers loading: Import gptqmodel → Read checkpoint config → Choose method backend → AutoModel loading.
- Publish a local artifact: GPT-QModel writer → Check artifact contents → Reload for verification → Upload with Hub client.
| Layer | Source | Responsibility |
|---|---|---|
| Public factory | gptqmodel/models/auto.py |
GPTQModel.load, from_pretrained, from_quantized, method/backend dispatch, GGUF input normalization |
| HF compatibility | gptqmodel/utils/hf.py |
Config dtype migration, native-vs-remote-code decisions, remote model compatibility, tokenizer loading, generation config sanitation, meta-device shells |
| Hub facade | gptqmodel/utils/hub.py |
Shared download, discovery, and repository helpers |
| Alternative model host |
gptqmodel/utils/modelscope.py, models/loader.py, __init__.py
|
Explicitly enabled ModelScope download and HF Hub patching |
| Transformers GPTQ quantizer | gptqmodel/__init__.py |
Compatibility around GptqHfQuantizer and registration of ParoQuant |
| Stable packing API |
gptqmodel/utils/packing.py, utils/importer.py, nn_modules/qlinear/__init__.py
|
External kernel selection, feasibility, packing, repacking, and initialization |
| Local Hub kernels | gptqmodel/hf_kernels/ |
Causal convolution and Mamba-compatible Torch ports |
| MiniMax implementation | gptqmodel/hf_minimax_m2/ |
HF config/model classes and historical class-name aliases |
| Adapter interchange |
gptqmodel/adapter/peft.py, adapter/remote.py, models/writer.py
|
PEFT-compatible LoRA config and EoRA serialization; explicit remote adapter resolution |
| Checkpoint writer | gptqmodel/models/writer.py |
Local packed safetensors, model/quantization config, tokenizer, processor, and remote-code files |
For a supported quantized checkpoint, GPT-QModel owns backend selection:
from gptqmodel import GPTQModel

model = GPTQModel.load("organization/quantized-model")
Transformers can instead load supported quantized checkpoints through its quantizer integration:
import gptqmodel  # Install GPTQModel's process-local compatibility patches.
from transformers import AutoConfig, AutoModelForCausalLM

model_id = "organization/quantized-model"
config = AutoConfig.from_pretrained(model_id)
config.quantization_config["backend"] = "gptq_torch"  # GPTQ example.
model = AutoModelForCausalLM.from_pretrained(
    model_id,
    config=config,
    device_map="auto",
)
The explicit backend above is a GPTQ example, not a backend valid for all methods. For AWQ LoRA training, use torch_awq, the Transformers-facing alias for AWQ_TORCH. The available method/format/backend combinations are described in Kernel Backends Reference.
GPT-QModel calls both patch functions below during package initialization. They use _MONKEY_PATCH_LOCK, detect repeat application, and return without patching if the required Transformers imports are unavailable.
def _patch_transformers_gptq_device_map_compat():
    ...

def _patch_transformers_paroquant_quantizer_compat():
...| Patch | Exact behavior | Why it matters |
|---|---|---|
| GPTQ device map | Wraps GptqHfQuantizer._process_model_before_weight_loading. If device_map is a nonempty dict with exactly one unique value, and the model has no hf_device_map, assigns a copy of the map before invoking the original method. |
Preserves a single-device map for Optimum's later packing step. It does not invent a map for "auto", an empty dict, or a multi-value dict, and does not overwrite an existing attribute. The wrapper itself does not validate that shared value as a supported device. |
| ParoQuant | Uses setdefault("paroquant", GPTQConfig) in AUTO_QUANTIZATION_CONFIG_MAPPING and setdefault("paroquant", GptqHfQuantizer) in AUTO_QUANTIZER_MAPPING. |
Allows checkpoints with quant_method="paroquant" to enter GPT-QModel/Optimum loading semantics instead of being rejected as unknown before loading. Existing upstream registrations win. |
ParoQuant registration does not convert a ParoQuant checkpoint into ordinary GPTQ weights or remove its rotations. Its runtime still needs a compatible ParoQuant backend. See ParoQuant.
Another optional import-time patch broadens OpenVINO's GPTQ layer-type recognition by replacing its supported_quant_types membership container. This compatibility change alone is not a guarantee that every GPT-QModel kernel or checkpoint can be exported to OpenVINO.
These signatures are from gptqmodel/utils/hf.py:
def get_hf_config_dtype(config: Any) -> Optional[torch.dtype]:
    ...

def set_hf_config_dtype(config: Any, dtype: torch.dtype) -> None:
    ...

def normalize_torch_dtype_kwarg(
    kwargs: dict[str, Any],
    *,
    api_name: str,
    explicit_dtype: Any = _MISSING,
) -> Any:
    ...

def normalize_hf_config_compat(config: Any, *, trust_remote_code: bool = False) -> None:
    ...
get_hf_config_dtype prefers modern config.dtype; if absent it reads legacy torch_dtype. When modern dtype is None, it checks genuinely stored legacy metadata in __dict__ rather than reading a deprecated property. A resulting None is returned unchanged. It accepts torch.dtype values and resolves strings by literal getattr(torch, value); a missing attribute or an unsupported non-string value raises ValueError. This helper does not strip a "torch." prefix or check that a resolved attribute is itself a dtype. Use a real dtype such as torch.float16 or an unprefixed dtype name such as "float16".
normalize_torch_dtype_kwarg consumes deprecated torch_dtype, warns once, and normalizes to dtype. A missing, None, or "auto" modern dtype can be replaced by the legacy argument. Otherwise any unequal legacy value raises ValueError, including legacy None or "auto"; the function compares values directly rather than resolving dtype names first. With explicit_dtype supplied it returns the chosen value instead of inserting kwargs["dtype"]. Use dtype= in new code.
def resolve_trust_remote_code(model_id_or_path: Optional[str], *, trust_remote_code: bool) -> bool:
    ...

def has_native_transformers_causallm_support(model_id_or_path: Optional[str]) -> bool:
    ...

def ensure_qwen_drive_registered(model_id_or_path: Optional[str] = None) -> bool:
    ...
The native-support probe loads AutoConfig with trust_remote_code=False and checks AutoModelForCausalLM._model_mapping[type(config)]. If a caller requested remote code but the installed Transformers supplies a native causal-LM class, GPT-QModel changes the effective setting to False and emits a warning once per model/type/class tuple. If native support cannot be established, it preserves the remote-code request. Thus a different Transformers installation can change which class is used.
Qwen-Drive is deliberately not bundled. A local config with model_type="qwen_drive" triggers import of the official qwen_drive package before AutoConfig; missing support produces an installation hint pointing to https://github.com/QwenLM/Qwen-Drive-1.0. Unrelated model loads do not eagerly import that optional stack.
def load_hf_tokenizer(
        tokenizer_or_path,
        *,
        model_config: Any = None,
        trust_remote_code: bool = False,
        **kwargs,
):
    ...

def load_tokenizer(tokenizer_or_path, *, model_config: Any = None, **kwargs):
    ...
Both delegate construction and compatibility normalization to Tokenicer.load. load_hf_tokenizer returns the underlying native tokenizer (tokenicer.tokenizer), while deprecated load_tokenizer returns the Tokenicer object and emits DeprecationWarning. The runtime wrapper is applied by BaseQModel; these return types are not interchangeable.
These are implementation compatibility shims, not new public configuration knobs. They are applied conditionally according to installed APIs and model config.
| Area | Compatibility behavior in utils/hf.py
|
|---|---|
| Imports | Restores removed FX availability probe, legacy tokenizer enum/type imports, Flash Attention version probe, and check_model_inputs when missing. |
| RoPE | Restores an unscaled "default" RoPE initializer; normalizes old rope_scaling/rope_theta into rope_parameters, including partial rotary factors and original position limits for applicable scaling types. |
| RoPE exceptions | HunYuan-VL normalizes only its text config; unscaled Nanbeige retains None legacy RoPE; GLM5-Next zero-rotary NoPE configs avoid synthetic RoPE when no genuine parameters exist. |
| Cache API | Aliases removed SlidingWindowCache/HybridCache to StaticCache when available, restores legacy max/usable-length access and tuple conversion on DynamicCache, and bridges custom generation-cache registry entries. |
| Tied weights | Converts list/tuple/set _tied_weights_keys into target-to-input-embedding mappings where embeddings really are tied; handles remote models missing all_tied_weights_keys; adapts old tie_weights(self) overrides to new keyword arguments. |
| Model helpers | Supplies missing is_parallelizable and get_head_mask defaults and bridges historical Flash Attention support flags. |
| Local code cache | Backfills missing top-level Python files from a local checkpoint into existing dynamic-module cache directories without overwriting existing files. |
| DeepSeek-VL2 | Before local config loading, restores old Llama attention/import interfaces, including old cache arguments and attention-output behavior. |
| ChatGLM | Bridges max_length to seq_length when needed and restores missing use_cache; removes the temporary max-length alias when saving. |
| Other remote configs | Restores missing Unlimited-OCR fields, LocateAnything text RoPE metadata, Ouro padding config, Brumby config compatibility, Instella legacy RoPE keys, and Hymba attention selection. |
| Vision-language init | Registers runtime Ovis visual config/model classes; adapts InternVL drop-path construction for meta init; bridges MiniCPM/Ovis Flash Attention flags and Ovis tokenizer backend recognition. |
| OpenVLA/Prismatic | Bridges removed AutoModelForVision2Seq mappings to AutoModelForImageTextToText, restores GenerationMixin where missing, and adapts remote-local timm version checks and single-layer list outputs. It does not alter timm's global version metadata. |
| LocateAnything attention | Strips unsupported allow_all_kernels from legacy overrides and keeps supported SDPA/magi paths; nested vision/text configs are kept on SDPA. |
| Hymba init | Avoids a hard-coded CUDA device during remote RoPE construction under meta initialization. |
| Phi-4 multimodal | Handles specific scalar/positional-buffer meta-init cases, infers missing language/vision/speech input mode, supplies an inner generation-input hook for PEFT, and narrows AutoAWQ availability checks to awq.modules.linear. |
| Deci | Bridges mismatched remote config/model classes during AutoModel registration. |
normalize_hf_config_compat always normalizes RoPE. Remote-code shims and legacy config aliases are used when remote code is trusted or a causal-LM remote auto_map exists. prepare_remote_code_compat(config) invokes that normalization with remote-code compatibility enabled. prepare_remote_model_init_compat pre-imports and patches the actual remote class before construction.
These shims do not make arbitrary remote code safe. Only enable it for code you trust. They are narrow compatibility paths, not a substitute for a supported model definition or for checking the installed Transformers version.
build_shell_model(loader, config, trust_remote_code=True, **model_init_kwargs) creates the architecture under accelerate.init_empty_weights(include_buffers=True). Its caller must provide device_map and _fast_init in model_init_kwargs, because the helper deletes these keys before from_config. Meta parameters preserve topology but do not contain usable weights. A narrow stale dynamic-code-cache failure can trigger one refresh/retry, including a known configuration-Llama shim.
suspend_hf_weight_init() temporarily disables selected Torch initializers and HF initialization, restoring global state in finally. It is an internal loading context, not a context to leave active during unrelated model creation.
Generation sanitation in this source sets generic GenerationConfig.do_sample=True when it is not already true, including saved generation_config.json. Specialized GenerationConfig subclasses are preserved by autofix_hf_model_config; rebuilding those as generic configs would lose model-specific fields. If deterministic decoding is required, explicitly pass do_sample=False to generation rather than assuming that a stored greedy-decoding flag survives packaging unchanged.
GGUF-over-HF loading is input normalization plus Transformers GGUF compatibility, not a claim that a GGUF file is GPTQ-packed safetensors.
from gptqmodel import GPTQModel

# An explicit local artifact disambiguates a directory with several GGUF files.
model = GPTQModel.load("/models/example/model-q4_0.gguf")

# Also accepted: a directory or Hub repo with one unambiguous GGUF artifact.
model = GPTQModel.load("organization/single-gguf-model")
def normalize_model_id_or_path_for_hf_gguf(
model_id_or_path: Optional[str],
kwargs: dict[str, Any],
*,
api_name: str,
) -> Optional[str]:
...
def get_hf_gguf_load_kwargs(kwargs: dict[str, Any]) -> dict[str, str]:
...| Input or condition | Behavior |
|---|---|
Local .gguf file |
Normalizes to its absolute parent directory plus internal GGUF filename. |
| Local directory | Recursively inventories files; infers GGUF only if exactly one exists and no dense model files exist. |
| Hub repo ID | Uses list_repo_files(repo_id=...) and the same uniqueness rule. Discovery errors fall back to the original input. |
| Dense model files | Any .safetensors, .bin, .pt, .pth, or .ckpt prevents automatic single-GGUF inference, even alongside one GGUF file. |
| Multiple GGUF files | No automatic selection; use a local explicit file rather than expecting a quantization variant to be chosen. |
Public gguf_file=
|
A non-None value raises TypeError in GPT-QModel's normalizer. Put the artifact in model_id_or_path instead. |
| Internal handoff |
_gptqmodel_hf_gguf_file is translated to Transformers' gguf_file only at the internal HF boundary. Do not use this private key in application code. |
Artifact discovery is lru_cache-cached. A repository's contents changing within one process is not guaranteed to trigger rediscovery.
The compatibility path installs GPT-QModel's internal GGUF runtime and, if missing upstream, supplies the local Prism Q1_0_g128 symbols/dequantizer to Transformers. A separate optional direct-to-Torch GGUF loading path avoids a NumPy tensor staging path only when all of its guards hold: tensor loading requested, a target model supplied, the internal loader enabled, model_type Qwen3, and the ordinary TensorProcessor rather than an architecture-specific processor. Other cases delegate to the original loader; exceptions also fall back.
| Internal GGUF environment variable | Effect |
|---|---|
GPTQMODEL_INTERNAL_GGUF_TORCH_LOADER |
Explicit enable/disable; stripped lower-case "", 0, false, off, no disable it. |
GPTQMODEL_INTERNAL_GGUF_DEQUANT_DEVICE |
If the first variable is unset, a nonempty value enables the direct Torch path and is consumed by the internal GGUF device resolver. |
These controls concern the compatibility loader, not native MLX GGUF packing or GGUF inference-kernel selection. See GGUF and MLX (Apple Silicon).
gptqmodel/utils/hub.py exposes aliases rather than maintaining a separate cache or authentication implementation:
| Name | Provider |
|---|---|
cached_file, has_file
|
transformers.utils.hub |
create_repo, hf_hub_download, list_repo_tree, snapshot_download
|
huggingface_hub |
disable_progress_bar |
Transformers logging |
list_repo_files(*args, **kwargs), model_info(*args, **kwargs), repo_info(*args, **kwargs)
|
The existing bound Hub API client obtained from list_repo_tree.__self__
|
Use the Hub library's supported credentials, access controls, revisions, and cache options at its API boundary. The facade does not add an upload_folder wrapper or a GPT-QModel-specific authentication flow.
ModelScope is opt-in through GPTQMODEL_USE_MODELSCOPE; default is disabled. The shared environment parser accepts 1, true, yes, on, or y, case-insensitively and with surrounding whitespace removed.
pip install modelscope
GPTQMODEL_USE_MODELSCOPE=1 python quantize.py
ensure_modelscope_available() returns False when not requested, returns True after a successful import when requested, and raises an actionable ModuleNotFoundError otherwise. models/loader.py chooses ModelScope's snapshot_download when enabled. Package initialization also calls modelscope.utils.hf_util.patcher.patch_hub(). Set the environment before importing GPT-QModel: this changes process-wide Hub integration, not just one model-call parameter. Failure while importing or patching ModelScope is surfaced as an installation error, so check the underlying exception if the package is already present.
External integrators should use the hf_ entry points documented in docs/hf_packing_api.md and tested in tests/test_hf_packing_api.py, not internal pack_module or select_quant_linear contracts.
def hf_check_packing_feasibility(
    bits: int,
    group_size: int = -1,
    desc_act: bool = False,
    sym: bool = True,
    *,
    format: Union[str, FORMAT] = FORMAT.GPTQ,
    quant_method: Union[str, METHOD] = METHOD.GPTQ,
    backend: Optional[Union[str, BACKEND]] = BACKEND.AUTO,
    device=None,
    dtype: Optional[torch.dtype] = None,
    pack_dtype: Optional[torch.dtype] = None,
    dynamic: Optional[Dict[str, Dict[str, Any]]] = None,
    in_features: Optional[int] = None,
    out_features: Optional[int] = None,
    allow_marlin: bool = True,
    is_sharded: bool = False,
    repack: bool = False,
) -> bool:
    ...

def hf_check_best_packing_format(
    bits: int,
    group_size: int = -1,
    desc_act: bool = False,
    sym: bool = True,
    *,
    quant_method: Union[str, METHOD] = METHOD.GPTQ,
    device=None,
    dtype: Optional[torch.dtype] = None,
    pack_dtype: Optional[torch.dtype] = None,
    dynamic: Optional[Dict[str, Dict[str, Any]]] = None,
    in_features: Optional[int] = None,
    out_features: Optional[int] = None,
    formats: Optional[Sequence[Union[str, FORMAT]]] = None,
    allow_marlin: bool = True,
) -> FORMAT:
    ...
Feasibility returns False for unsupported contracts, but argument normalization happens before that probe: unknown format/method/backend names raise ValueError, and a backend argument with an unsupported type raises TypeError. Supply shape arguments to check actual layer divisibility. Use repack=True for kernels that accept an already-packed checkpoint and convert in post_init() rather than implementing raw-weight packing; Marlin and ExllamaV2 are examples. Best-format selection ranks available kernels by declared priority and deterministically breaks format-name ties; it is not a runtime microbenchmark of your model.
The Transformers-facing selector also has an explicit stable signature:
def hf_select_quant_linear_v2(
        bits: int,
        group_size: int,
        desc_act: bool,
        sym: bool,
        format: Union[str, FORMAT],
        quant_method: Union[str, METHOD],
        zero_point: Optional[bool] = None,
        dtype: Optional[Union[str, torch.dtype]] = None,
        meta: Optional[Dict[str, any]] = None,
        pack: Optional[bool] = True,
        device_map: Optional[Union[str, dict]] = None,
        backend: Optional[Union[str, BACKEND]] = None,
) -> Type[BaseQuantLinear]:
    ...
It normalizes backend aliases and method/format strings, accepts dtype strings with or without torch., and uses meta["pack_dtype"] when supplied. Packing storage otherwise defaults to int32, except AWQ GEMV_FAST defaults to int16. LLM_AWQ additionally forces int16 after this default/override resolution. zero_point expresses AWQ asymmetry and overrides sym as not bool(zero_point). With no device_map, selection starts from CPU. AWQ version names must already be mapped to GPT-QModel's format/quant_method concepts by the caller.
The LLM_AWQ override specifically tests the original argument with format == FORMAT.LLM_AWQ, not the normalized local fmt. Pass the enum or its canonical string value "llm-awq"; an uppercase spelling can normalize for selection without triggering this int16 override.
def hf_pack_layer(
    module: BaseQuantLinear,
    linear: nn.Module,
    scales: torch.Tensor,
    zeros: Optional[torch.Tensor] = None,
    g_idx: Optional[torch.Tensor] = None,
    *,
    pack_impl: Optional[str] = None,
    device=None,
    block_in: int = 8192,
    workers: int = 1,
    scales_extra: Optional[torch.Tensor] = None,
    post_init: bool = False,
    post_init_kwargs: Optional[Dict[str, Any]] = None,
    checkpoint_format: Optional[Union[str, FORMAT]] = None,
) -> BaseQuantLinear:
    ...

def hf_post_init(module: nn.Module, **post_init_kwargs) -> nn.Module:
    ...

def hf_repack_layer(
    module: BaseQuantLinear,
    backend: Optional[Union[str, BACKEND]] = None,
    *,
    device=None,
    dtype: Optional[torch.dtype] = None,
    post_init: bool = True,
    post_init_kwargs: Optional[Dict[str, Any]] = None,
) -> BaseQuantLinear:
...| Contract | Details |
|---|---|
| Quantizer scale/zero layout |
[out_features, num_groups], not the transposed runtime-kernel layout |
| Missing zero points | Symmetric modules synthesize 2 ** (bits - 1); asymmetric modules require explicit zeros
|
| Activation ordering |
g_idx has length in_features
|
| Packing implementation |
None resolves to original packing; explicit values include original, auto, block/cpu, and gpu. Unavailable accelerated/block paths fall back to original packing; a selected GPU/block packer raising ValueError or NotImplementedError also falls back. Other exceptions are not caught by this fallback. Unknown implementation names warn and select original packing. |
| QQQ/AWQ | Their single pack() paths ignore GPTQ pack_impl; QQQ consumes scales_extra
|
| Storage device | Packed buffers are registered on CPU even when GPU accelerates the packing math; move to the runtime device afterward |
| Return | Packing modifies and returns the same module; module.hf_pack(...) delegates to this function |
| GPTQ zero-point versions | Raw packing starts in v1 zero-point layout, then converts to requested gptq/gptq_v2; repeated packing resets metadata before conversion |
| Post-initialization |
hf_post_init handles a single layer or quantized children of an nn.Module; it is not a replacement for all model-level scratch/activation-order initialization |
| Repacking | Uses native repack_from_gptq/repack_from_awq hooks where present, otherwise copies compatible checkpoint tensors and calls target post_init()
|
| Same target | Returns source unchanged when the requested backend is already in use |
| Private runtime ABI | Marlin/Machete/Swordfish/BitBLAS-style ABI-transforming sources are rejected for copy repacking; repack from a checkpoint-layout kernel instead |
| Errors | Invalid source type raises TypeError; unsupported layout conversion raises NotImplementedError; unresolved target/backend raises ValueError
|
Example with an existing dense linear, quantizer-native scales, and optional g_idx:
from gptqmodel.utils.importer import hf_select_quant_linear_v2
from gptqmodel.utils.packing import hf_pack_layer

kernel_cls = hf_select_quant_linear_v2(
    bits=4, group_size=128, desc_act=False, sym=True,
    format="gptq_v2", quant_method="gptq", backend="auto", device_map="cpu",
)
module = kernel_cls(
    bits=4, group_size=128, desc_act=False, sym=True,
    in_features=linear.in_features, out_features=linear.out_features,
    bias=linear.bias is not None,
)
hf_pack_layer(
    module, linear, scales, zeros=None, g_idx=g_idx,
    pack_impl="original", checkpoint_format="gptq_v2",
)
For ExllamaV2 repacking, defer initialization until scratch is available:
from gptqmodel.utils.exllamav2 import ScratchSpace
from gptqmodel.utils.packing import hf_post_init, hf_repack_layer

target = hf_repack_layer(source, backend="gptq_exllama_v2", device="cuda:1", post_init=False)
hf_post_init(target, scratch_space=ScratchSpace(target.temp_dq_size(), dev="cuda:1"))_patch_transformers_causal_conv1d_hub_kernel_compat wraps Transformers' hub_kernels.lazy_load_kernel and exported transformers.integrations.lazy_load_kernel if available. Hyphens in kernel names become underscores. Resolution checks gptqmodel.hf_kernels.<name> first, then a project-root module, and falls back to Transformers' original loader if neither exists. The resolved module is stored in Transformers' kernel mapping; causal-conv1d additionally gets a legacy sys.modules["causal_conv1d"] alias without overwriting an existing one.
These are local Torch implementations. The ops/triton/ directory name in the Mamba port does not mean these files contain Triton JIT kernels.
| Package/API | Behavior and limitations |
|---|---|
causal_conv1d (__version__="0.0.local") |
Exports causal_conv1d_fn, causal_conv1d_update, causal_conv1d_varlen_states; supports activation None, silu, swish only. |
causal_conv1d_fn |
Input [batch, dim, seqlen], weights [dim, width]; casts compute input to weight dtype and returns input dtype. Supports initial/final states; sequence-index masking cannot be combined with initial states or returning final states. |
causal_conv1d_update |
Accepts a token or sequence, mutates the supplied convolution state, supports selected state rows and circular-buffer cache_seqlens. |
causal_conv1d_varlen_states |
Extracts right-aligned sequence tails from [total_tokens, dim] and cumulative lengths into [batch, dim, state_len]; documented forward-only. |
mamba_ssm (__version__="2.2.4-local") |
Exports selective scan, inner function, falcon_mamba_inner_fn alias, state update, chunk scan, and split convolution/scan interfaces. Uses Torch and einops. |
selective_scan_fn |
Delegates to a reference recurrence; supports variable/grouped B/C, optional D, gate z, delta bias/softplus, complex A, and optional last state. |
selective_state_update |
Mutates selected state rows; checks grouped-head and tensor-shape contracts and returns activation dtype. |
mamba_chunk_scan_combined |
Reference per-token recurrence, optional sequence-index state resets, FP32 state for FP16/BF16 activations, optional final state. Accepts but discards chunk_size, cu_seqlens, and return_varlen_states; do not assume optimized chunking or a returned varlen-state structure. |
mamba_split_conv1d_scan_combined |
Splits projection payloads, runs local convolution and scan, optional gated/grouped RMS normalization and output projection. |
These ports prioritize compatible interfaces. Their sequential Torch loops do not promise the throughput or full specialized-kernel behavior of external fused packages.
gptqmodel/hf_minimax_m2/ exports MiniMaxM2Config, MiniMaxM2PreTrainedModel, MiniMaxM2Model, and MiniMaxM2ForCausalLM, plus legacy MiniMax* aliases/classes. The config's model_type is "minimax", not inferred from the package directory name. Importing the package exposes classes; its __init__.py does not itself register them with AutoConfig or AutoModelForCausalLM.
Selected constructor defaults:
| Parameter | Default |
|---|---|
vocab_size, hidden_size
|
200064, 3072
|
intermediate_size, mlp_intermediate_size
|
1536, 8192
|
num_hidden_layers |
62 |
num_attention_heads, num_key_value_heads, head_dim
|
48, 8, 128
|
num_local_experts, num_experts_per_tok
|
256, 8
|
max_position_embeddings, rope_theta, rotary_dim
|
196608, 5000000.0, 64
|
use_qk_norm, qk_norm_type
|
True, "per_layer"
|
scoring_func, use_routing_bias, use_grouped_topk
|
"sigmoid", True, True
|
router_aux_loss_coef, router_jitter_noise, output_router_logits
|
0.001, 0.0, False
|
attn_window_size, sliding_window, swa_rope_theta
|
None, None, -1.0
|
use_mtp, num_mtp_modules, mtp_transformer_layers
|
True, 3, 1 (serialized config fields, not an implemented MTP generation promise) |
rms_norm_eps, attention_dropout, tie_word_embeddings, use_cache
|
1e-6, 0.0, False, True
|
The model implements partial rotary attention, optional Q/K normalization, grouped-query heads, sparse expert routing, optional router-logit/auxiliary-loss outputs, and HF Cache/DynamicCache generation. Attention is explicitly chunked per head in 1024-token query chunks, and expert execution is chunked at 1024 routed tokens. The model declares Flash Attention, SDPA, and attention-backend support flags false; it is not a Flash Attention implementation merely because it follows HF interfaces.
load_state_dict(self, state_dict, strict=True) filters FP8-related scale metadata (weight_scale_inv, weight_scale, input_scale, scales, amax, and keys containing fp8) and splits fused qkv_proj.weight into Q/K/V projection weights. Filtering scale metadata is not FP8 dequantization: use a correctly converted dense checkpoint for this implementation rather than expecting the filter to reconstruct FP8 payloads.
The bundled test_minimax_m2_hf.py is a manual streaming checkpoint smoke script using a chat template and BF16 auto placement. Its structural assertions are commented out; it is not proof that all MiniMax config features execute or that quantized loading is numerically validated.
The quantized base stays frozen; train only the LoRA parameters. Inference-only kernels do not provide the gradient propagation needed through the quantized layers.
| Checkpoint method | Transformers training backend |
|---|---|
| GPTQ | gptq_torch |
| AWQ | torch_awq |
import gptqmodel  # Apply process-local Transformers compatibility patches.
from peft import LoraConfig, get_peft_model
from transformers import AutoConfig, AutoModelForCausalLM

quant_path = "organization/quantized-model"
config = AutoConfig.from_pretrained(quant_path)
config.quantization_config["backend"] = {
    "gptq": "gptq_torch", "awq": "torch_awq",
}[config.quantization_config["quant_method"]]
base = AutoModelForCausalLM.from_pretrained(quant_path, config=config, device_map="auto")
model = get_peft_model(base, LoraConfig(
    r=16, lora_alpha=32, target_modules=["q_proj", "v_proj"], task_type="CAUSAL_LM",
))
# Train with Trainer or a training loop, then save only adapter files.
model.save_pretrained("./adapter")
At inference, keep the adapter separate:
from peft import PeftModel
from transformers import AutoModelForCausalLM

base = AutoModelForCausalLM.from_pretrained(quant_path, device_map="auto")
model = PeftModel.from_pretrained(base, "./adapter")
This peft.LoraConfig is the external training configuration. It is not the similarly named serialization dataclass in gptqmodel.adapter.peft.
gptqmodel.adapter.peft.LoraConfig serializes adapter config for GPT-QModel/EoRA interchange. It does not create or train a PEFT model.
| Field | Default |
|---|---|
base_model_name_or_path |
"" |
r, lora_alpha, lora_dropout
|
8, 8, 0.0
|
target_modules, exclude_modules, modules_to_save
|
None |
fan_in_fan_out, use_rslora
|
False |
bias |
"none"; annotation allows "none", "all", "lora_only"
|
init_lora_weights |
True; annotated strings gaussian, eva, olora, pissa, pissa_niter_[number of iters], loftq are subject to validation below |
layers_to_transform, layers_pattern
|
None |
rank_pattern, alpha_pattern
|
New empty dict per instance |
megatron_config, eva_config
|
None |
megatron_core |
"megatron.core" |
loftq_config |
New empty dict per instance |
use_dora, lora_bias
|
False |
layer_replication, auto_mapping
|
None |
task_type, peft_type
|
"CAUSAL_LM", "LORA" (peft_type forced to "LORA" after init) |
__post_init__ converts target/exclude lists to sets. Regex target_modules cannot be combined with layers_to_transform or layers_pattern; a truthy layers_pattern requires truthy layers_to_transform. It rejects LoftQ selection/config, LoRA bias, DoRA combined with Megatron config, EVA selection without an EVA config, or an EVA config when not selecting EVA. It also rejects the combination of RSLoRA, rank/alpha patterns, and PiSSA/OLoRA initialization. These checks are narrower than blanket claims that every annotated PEFT feature is implemented or always rejected.
to_dict() removes None, empty dict, and empty list values, converts sets to lists, and retains false/zero values. save_pretrained(self, save_dir: str) writes adapter_config.json. The loader signature is:
@classmethod
def from_pretrained(
    cls,
    path: str,
    filename: str,
    *,
    allow_remote: bool = False,
    revision: Optional[str] = None,
):
    ...
It resolves the file through adapter.remote.resolve_path, discards unknown/empty fields, and constructs the dataclass. Remote config resolution is explicitly opt-in and requires an immutable 40-character Hub commit revision. This config-only loader has no weights-digest parameter; it is not the complete adapter-loading security boundary.
Full adapter loading through GPT-QModel distinguishes a caller's explicit adapter= from an adapter path embedded in a checkpoint:
| Input/control | Contract in adapter/remote.py and models/auto.py
|
|---|---|
allow_remote_adapter |
Defaults to False; remote loading requires explicit opt-in and an explicitly selected remote adapter. |
adapter_revision |
Requires exactly 40 hexadecimal characters identifying an immutable Hub commit, not a branch or tag. |
adapter_sha256 |
Requires exactly 64 hexadecimal characters for adapter_model.safetensors; downloaded weights are checked against this digest. |
| Explicit local adapter directory | Resolved locally; remote opt-in/revision/hash options are rejected for this input. A nonexistent absolute or explicitly relative local path is not reinterpreted as a remote repository. |
| Explicit remote reference | Supports Hub repository IDs, nested adapter subfolders, and supported HTTPS Hugging Face blob URLs. A URL's revision must match the caller's pinned commit. |
| Checkpoint-manifest adapter path | Must resolve to an existing directory inside the checkpoint. Absolute paths, Windows drive paths, .., backslashes, and symlinked directory components are rejected. Adapter-file symlinks are checked separately, with a narrow exception for the checkpoint's Hub-cache blob storage. |
These controls apply to GPT-QModel's adapter resolver, not to the separate external peft.PeftModel.from_pretrained API. Do not treat a checkpoint's embedded adapter path as authorization to fetch arbitrary external files. See EoRA for GPT-QModel adapter use.
The writer's EoRA path saves adapter_model.safetensors using PEFT-style lora_A.weight/lora_B.weight keys and writes a matching config (lora_alpha equals adapter rank). Dynamic adapter ranks become rank_pattern. See EoRA.
docs/peft.md records a recipe validated with PEFT 0.21.3.dev0, Optimum 2.3.0, Transformers 5.20.2, and PyTorch 2.14, using an 8B Llama 3.1 GPTQ checkpoint on four RTX 4090 GPUs. This is a recorded recipe, not a universal compatibility matrix.
Use PEFT's maintained examples/sft training script and set gptq_torch before constructing the model. The repository's docs/peft/fsdp_config.yaml specifies:
| Setting | Value |
|---|---|
distributed_type, num_machines, num_processes
|
FSDP, 1, 4
|
mixed_precision, downcast_bf16
|
bf16, no
|
| Sharding, state dict |
FULL_SHARD, SHARDED_STATE_DICT
|
| Auto-wrap, backward prefetch |
TRANSFORMER_BASED_WRAP, BACKWARD_PRE
|
fsdp_cpu_ram_efficient_loading, fsdp_sync_module_states
|
true, true
|
fsdp_use_orig_params, fsdp_offload_params, fsdp_forward_prefetch
|
false, false, false
|
Before training, install PEFT's FSDP wrapping policy:
from peft.utils.other import fsdp_auto_wrap_policy

if model_args.use_peft_lora and trainer.is_fsdp_enabled:
    trainer.accelerator.state.fsdp_plugin.auto_wrap_policy = fsdp_auto_wrap_policy(trainer.model)
With the versions recorded in the recipe, trainer.save_model() produced an empty adapter weights file. The documented workaround gathers a full state dict and writes normalized LoRA keys on the main process:
import os
from safetensors.torch import save_file

if trainer.is_fsdp_enabled:
    trainer.accelerator.state.fsdp_plugin.set_state_dict_type("FULL_STATE_DICT")
    state_dict = trainer.accelerator.get_state_dict(trainer.model)
    trainer.save_model()
    if trainer.is_world_process_zero():
        adapter_state_dict = {
            key.replace(".default.weight", ".weight"): value.cpu().contiguous()
            for key, value in state_dict.items()
            if key.endswith((".lora_A.default.weight", ".lora_B.default.weight"))
        }
        if not adapter_state_dict:
            raise RuntimeError("FSDP full state dict contains no GPTQ LoRA tensors")
        save_file(adapter_state_dict, os.path.join(training_args.output_dir, "adapter_model.safetensors"))
else:
    trainer.save_model()
The launch recipe uses BF16, max length 2048, batch size 1 per GPU, gradient accumulation 4, gradient checkpointing, and LoRA rank 8/alpha 16/dropout 0.1. Keep --use_4bit_quantization False for the already-GPTQ checkpoint: that option would enable a separate bitsandbytes QLoRA path. Reduce sequence length if memory is insufficient. Consult the source recipe for all SFT script arguments; they belong to that external example script, not GPT-QModel's quantization API.
PEFT cannot add dense LoRA deltas directly into packed GPTQ/AWQ weights. The project guide documents ValueError: Cannot merge LORA layers when the model is gptq quantized for GPTQ and NotImplementedError for AWQ. Keep adapters separate, or load the original dense base, merge there, save it, and quantize the merged model again. Do not relabel the original packed checkpoint as merged.
# `model` is a quantized GPTQModel wrapper.
model.save("./quantized-output")
BaseQModel.save dispatches quantized models to the quantized writer (or the specialized embedding-only writer). save_pretrained on the GPT-QModel wrapper is a warning-emitting alias that redirects to save_quantized; it is not the generic Transformers writer. save_quantized requires self.quantized and writes packed safetensors with optional sharding/index, model config containing quantization_config, standalone quantize_config.json, and generation config. It preserves first-match ordering of dynamic rules after Transformers config serialization.
The writer also saves tokenizer files, then the multimodal processor so a processor-aware chat template is not overwritten by a text-only tokenizer template. For trusted remote-code checkpoints it copies Python source files. It restores a source-compatible tokenizer class name instead of leaving an incompatible modern backend name in saved metadata. EoRA adapter output may be in a separate directory selected by adapter path or eora_path; include it intentionally when publishing.
There is no dedicated GPTQModel.push_to_hub implementation or upload-folder pipeline in this tree. BaseQModel.__getattr__ forwards unknown attributes to the underlying HF model, so an apparent model.push_to_hub(...) may be the Transformers method. It must not be assumed to run GPT-QModel's quantized writer, preserve all auxiliary artifacts, or serialize the intended checkpoint ABI.
For reliable publication, save with GPT-QModel first, inspect/reload that directory with the intended runtime, and upload the directory using the supported Hugging Face Hub client/CLI. utils/hub.py exposes create_repo for repository creation, but does not expose upload_folder or upload_file. Those are Hub-library operations, not extra model.save parameters. Upload the quantization configs, safetensors and index, tokenizer/processor files, required trusted code, and intended adapter artifacts together. Avoid uploading unrelated local calibration data or credentials.
The same separation applies to an MLX-native output: save the MLX-LM checkpoint with GPTQModel.quantize_mlx, then publish that artifact as MLX-LM output rather than advertising it as a GPTQ safetensors checkpoint.
- Import GPT-QModel before relying on its process-local Transformers monkeypatches. Availability checks are defensive and may skip patches for missing/incompatible imports.
- Do not equate method (
gptq,awq,paroquant), checkpoint format, and execution backend. These are separate contracts. - A single concrete device map is not the same as
device_map="auto"; the compatibility patch only backfills the former. - Prefer modern
dtype=and avoid conflicting legacytorch_dtype=arguments. - Tokenicer wrappers and native HF tokenizers have different return contracts.
- GGUF auto-discovery will not choose among quantization variants or mixed dense/GGUF artifacts.
- A local Mamba compatibility port may intentionally ignore optimized-kernel options. Check its implementation before depending on varlen-state return behavior or throughput.
- Do not train through inference-only quantized kernels or merge LoRA directly into packed weights.
- Check nonempty adapter weights after FSDP saving, and record the actual library versions used.
- Do not use forwarded HF
push_to_hubas a substitute for GPT-QModel's checkpoint writer.
gptqmodel/utils/hf.pygptqmodel/utils/hub.py-
gptqmodel/utils/modelscope.py,gptqmodel/utils/env.py gptqmodel/__init__.py-
gptqmodel/models/auto.py,gptqmodel/models/loader.py,gptqmodel/models/base.py,gptqmodel/models/writer.py -
gptqmodel/utils/importer.py,gptqmodel/utils/packing.py,gptqmodel/nn_modules/qlinear/__init__.py -
gptqmodel/hf_kernels/causal_conv1d/__init__.py,causal_conv1d_interface.py,causal_conv1d_varlen.py -
gptqmodel/hf_kernels/mamba_ssm/__init__.py,ops/selective_scan_interface.py,ops/triton/selective_state_update.py,ops/triton/ssd_combined.py -
gptqmodel/hf_minimax_m2/__init__.py,configuration_minimax_m2.py,modeling_minimax_m2.py,test_minimax_m2_hf.py -
gptqmodel/adapter/peft.py,gptqmodel/adapter/remote.py docs/hf_packing_api.md-
docs/peft.md,docs/peft/fsdp_config.yaml tests/test_hf_packing_api.py-
pyproject.toml,requirements.txt