Repository navigation
Home
A fully local, production-grade Retrieval-Augmented Generation system. Upload documents, ask questions in plain English, and receive accurate answers with source citations — all running on your machine with no cloud dependencies.
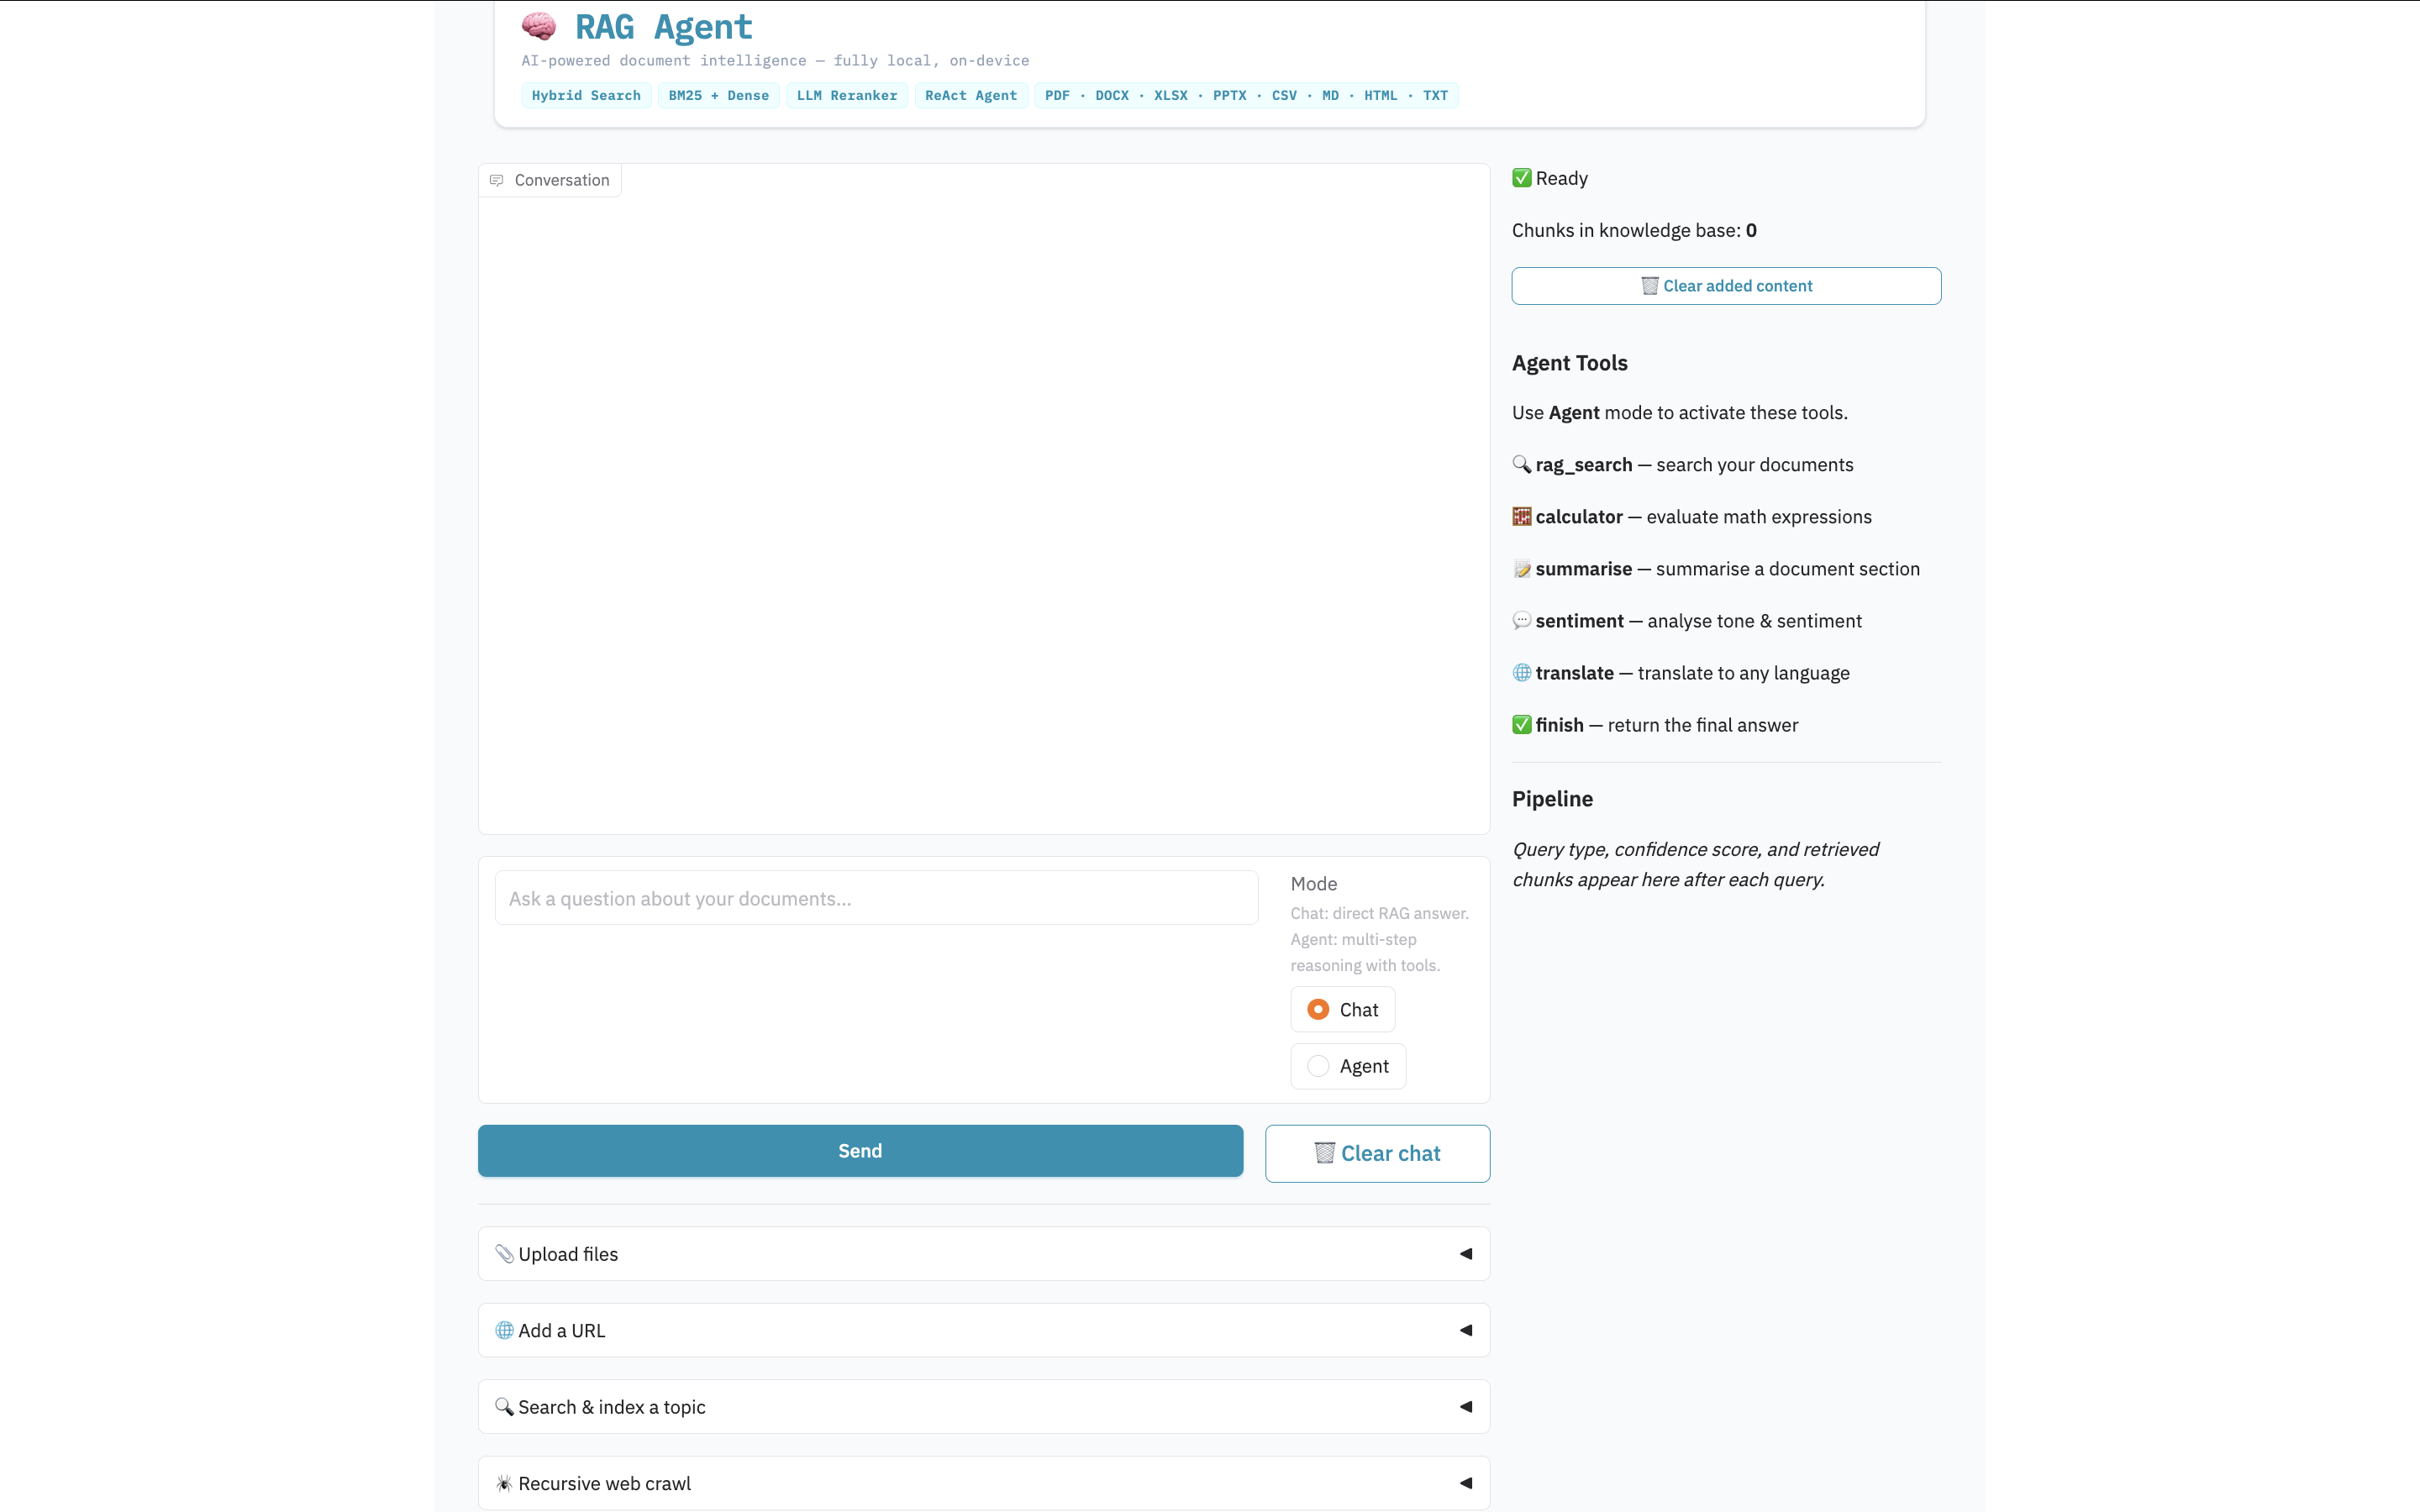
Click the image to try the live demo on Hugging Face.
| Page | Description |
|---|---|
| Installation | Prerequisites, setup steps, and model downloads |
| Quick Start | Get running in under 5 minutes |
| Usage Guide | Chat mode, agent mode, URL ingestion, topic search |
| Supported File Types | All 9 formats with chunking details |
| Agent Mode | ReAct loop, all 6 tools, and example queries |
| Architecture | 4-class design, pipeline flow, and key decisions |
| Benchmarking | Running evaluations and interpreting results |
| Troubleshooting | Common problems and fixes |
| FAQ | Frequently asked questions |
| Contributing | Development setup, test strategy, and PR guidelines |
- Chat with your documents — PDF, Word, Excel, Legacy Excel (XLS), PowerPoint, CSV, Markdown, HTML, and plain text — 9 formats
- Fully local — LLaMA 3.2 and BGE embeddings run via Ollama; no data leaves your machine
-
Docker support — run the full stack with
docker compose up; no Python setup required - Hybrid search — BM25 + dense vector fusion with LLM query expansion (3 rewrites per query) for higher recall
- Type-aware reranking — 7 document-type-specific LLM reranker prompts optimised for structured data
- Hallucination filter — confidence gate + pivot-phrase filter prevents unsupported claims
- Agent mode — autonomous ReAct loop with 6 tools: search, calculator, summarise, sentiment, translate, finish
- Multiple ingestion methods — drop files into a folder, upload via UI, paste any public URL, recursive URL crawl (depth 3), or topic search via DuckDuckGo
- Multi-turn conversation — follow-up questions resolve pronouns and references from prior turns
- Streaming responses — tokens appear word by word as they generate; no waiting for the full answer
-
RAGAS evaluation —
python main.py --ragasruns industry-standard LLM-as-judge metrics (Faithfulness, ResponseRelevancy, ContextPrecision, ContextRecall) - Benchmark score — Faithfulness 0.967 · Answer Relevancy 0.867 · MRR 1.000 · Overall 0.808
- Test suite — 859 local · 385 HF Space · 1,244 total — unit, integration, functional, contract, regression, boundary, negative, parametrized, UI — all passing
- GitHub Repository
- Installation — Docker & Local
- Live Demo — Hugging Face
- Blog Post — Medium
- Release Notes
- Changelog
- Issue Tracker
- Security Policy
- Architecture Deep-Dive
This project extends the Make Your Own RAG tutorial by ngxson (Hugging Face). The original provided a minimal ChromaDB + Ollama retrieval loop; hybrid search, type-aware reranking, agent mode, benchmarking, multi-format ingestion, and the production architecture were built on top of that foundation.