Repository navigation
Retention and Archives
There are three different retentions in DAD, and they fail in different ways.
| what | where | controlled by |
|---|---|---|
| ingested log files | Logs/ProcessedLogs |
RETENTION_DAYS = 7 in import_syslog.rb
|
| event rows | Postgres partitions |
DAD_EVENT_RETENTION_DAYS (default 365) |
| event archives | DAD_OFFLINE_STORAGE_DIR |
the Preferences free-space floor |
events and events_words are range-partitioned by month, and retention drops a
month by DROP TABLE-ing its partition — metadata-only, so it costs the same
whether the month holds 10k rows or 100M, where DELETE would rewrite every
index. The maintain_event_partitions job (seeded daily) creates coming months and
drops expired ones.
Retention keeps DAD_EVENT_RETENTION_DAYS days of history, default 365. It is
a floor, not an exact age — a partition is dropped only once its whole month is
past the cutoff, so rows can survive up to a month longer. Set it to 0 to keep
everything.
Every entry point checks the schema shape before acting. On a database where the
partitioned shape was never built — one prepared with plain db:migrate, which
loads the committed db/schema.rb dump rather than replaying db/migrate — the job
reports event partitioning is Postgres-only; nothing to do instead of raising, so
a stray Job row cannot crash the scheduler.
Before any drop, EventPartitionBackup writes the partition to a CSV under
DAD_OFFLINE_STORAGE_DIR (default offline_storage under the app root, which
under systemd resolves to /var/DAD/offline_storage because the units set
WorkingDirectory=/var/DAD — no unit sets the variable itself; owned by the
service user, mode from the umask). If the archive does not complete, the partition
is kept and the next run retries. That is the whole safety property: retention
cannot destroy the only copy of a month's rows.
Archives are plain CSV with a header row. To put a month back:
bin/restore_event_partition --list                    # what is archived
bin/restore_event_partition events_p202509            # recreate + load
The restore recreates the partition with the same FOR VALUES range the
maintenance job would have used, then loads the CSV by COPY. It refuses to run if
the partition already exists.
bin/export_logs is a different thing: it streams every stored event back out as
its original log line, one per stdout line, for replaying the corpus into another
system. It pages by primary key, so it is safe on a table too large to hold in
memory.
Archives are never pruned unless an admin says they may be. Set a required free
space percentage for the partition holding them under Preferences →
"Archive partition: required free space (%)" (Admin-only). Blank or 0 leaves
pruning off.
With a floor set, the maintain_event_partitions job deletes whole months of
archives — oldest first — whenever the archives on disk, plus what the next
archives are expected to need, would breach it. Pruning happens before any new
archive is written, so the disk never fills mid-dump. The size of the incoming
archives is measured from the partitions themselves (pg_relation_size, rows only
— indexes are not in the CSV), falling back to the size of the largest recent
archive when it cannot be.
Pruning is unrecoverable. An archive is usually the only copy of a month the database has already dropped; deleting it destroys that history for good.
bin/prune_event_archives --check      # floor, usage, and what is stored
bin/prune_event_archives --dry-run    # exactly what would be deleted
bin/prune_event_archives              # delete it
Three deliberate behaviours:
- It fails closed. If the filesystem cannot be measured, nothing is deleted — a bogus reading must not delete history. The job logs and reports it instead.
-
It never prunes an archive it is about to rewrite. The scheduled job skips
archives whose partition is still in the database and due to be archived this
run: deleting one would free space that the very next step spends writing it
again, so the run would report success and still breach the floor. The manual
bin/prune_event_archiveshas no such pending write, so it treats every archive as prunable. - It alerts when the floor cannot be met. If every archive has been deleted and the floor still fails, a Critical alert is raised (once, not per run). That is the state where retention is about to stop working for lack of space.
-
Disk. If the archive directory fills, archiving fails and partitions stop
being dropped — the database grows instead of the disk filling. Set a floor, or
check the job output: it reports
N expired partition(s) kept pending archivewhen this is happening. - Secrets. Archives are raw log lines. Anything that ever reached a log line is in them, so restrict the directory yourself: nothing in the app sets a mode on it, so it gets the umask default.
The disk_utilization job reports the partition holding the archives, not the root
filesystem, and names the directory it measured. If that partition cannot be
measured it says disk utilization unknown rather than 0% — a missing reading
must not look like an empty disk.
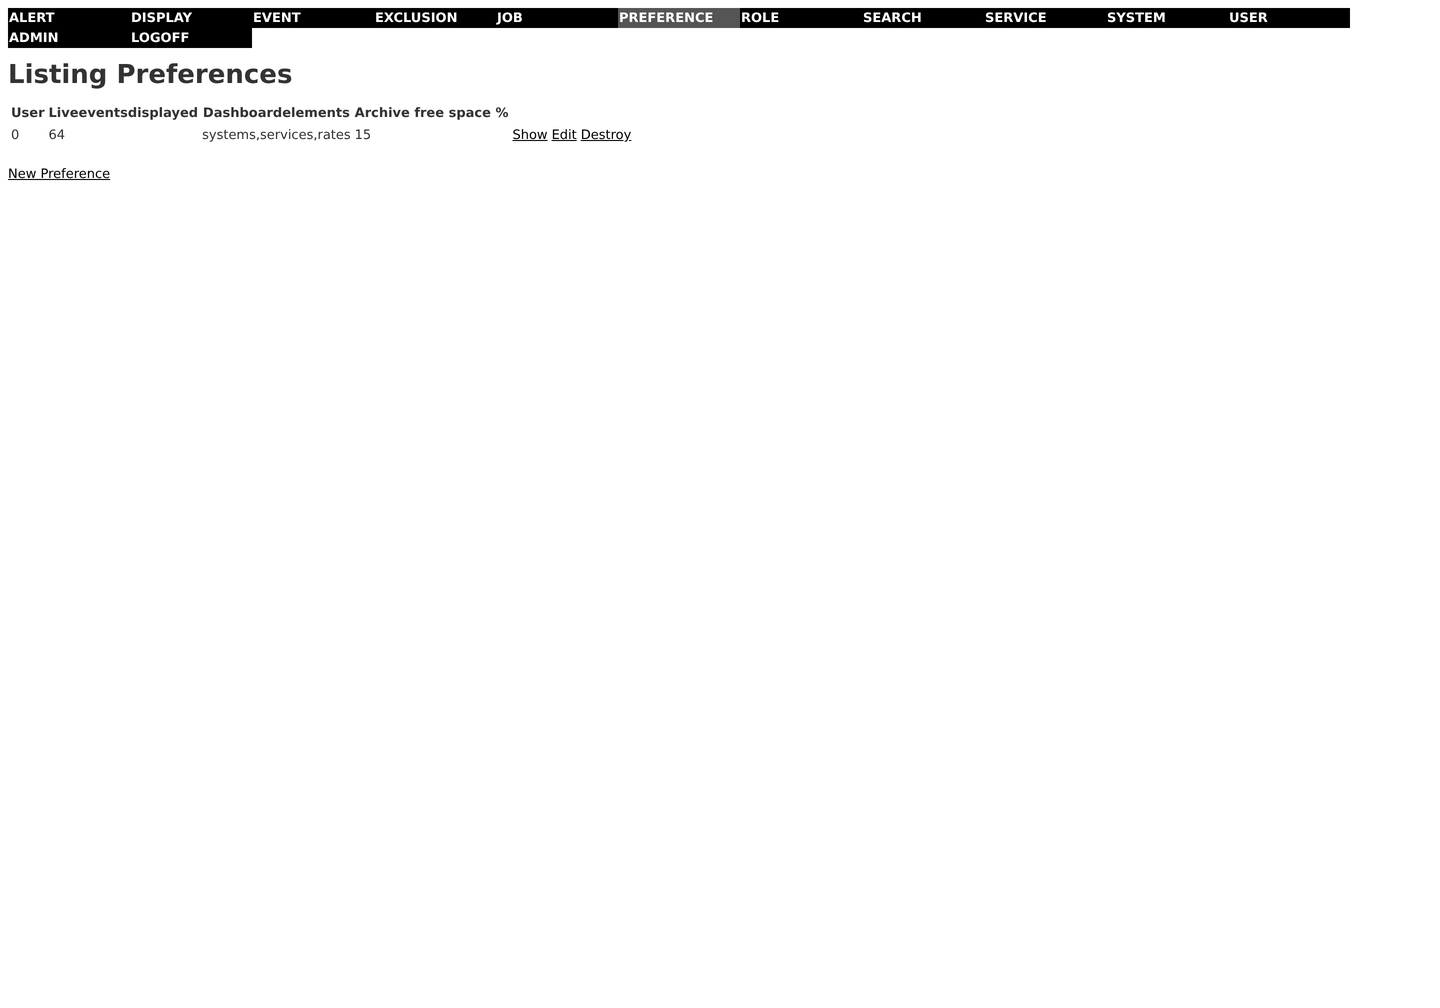
The floor itself is preferences.archiveFreeSpacePercent (Admin-only, clamped to
0..100 on write; nil or 0 means pruning is off). There is no disk utilization
chart on the dashboard: the author commented it out in bec738c ("Hiding disk
gauge", 2015-02-28), noting "Removed for now. There is a configured alert for
this." The job output and the floor are the live surfaces. See Interface.