Repository navigation
Highest probability of topic not equal to topic selected by model? #916


|
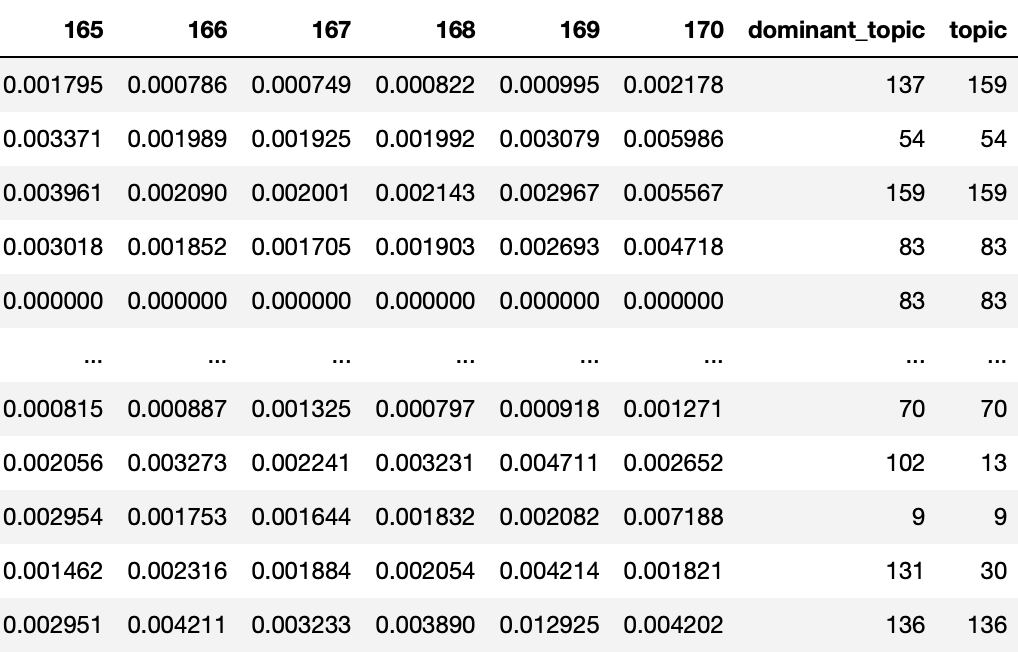
I followed your example to reduce outliers. ... topics, probs = model.fit_transform(df.text) % Reduce outliers new_topics = model.reduce_outliers(df.text, topics, strategy="c-tf-idf") %Update topic frequency model.topics_ = new_topics %Create a topics probabilities DataFrame names = model.get_topic_info()['Topic'] %Get a dominant topic for each document prob_df['dominant_topic'] = prob_df.columns[np.argmax(prob_df.values, axis=1)] Here, I realized that the np.argmax value of the row is not always equal to the _topic value assigned by the model. In other words, the column with the highest probability is not always the assigned topic.
Is that because the probs were not updated with reduce_outliers, or is there an alternative explanation? Thank you in advance! |
Replies: 1 comment 2 replies

|
The probabilities that are generated within BERTopic are a result of the soft clustering capabilities of HDBSCAN. More specifically, these probabilities are generated after finding the clusters and are exactly an approximation of the probabilities, not the process by which the clusters are created. In other words, the probabilities that are calculated by HDBSCAN are an approximation of its fitting process and will not exactly match the actual clusters that are created. Lastly, the output of |

|
Thank you, @MaartenGr! This is very helpful. Just asking, as the reproducibility of research papers might depend on this: Is there any workaround you'd recommend? Or: Would you rather recommend to work with the |

|
Working with the topics themselves is, in the case of using HDBSCAN, often preferred. The reason for this is that the probabilities that you extract using HDBSCAN are an approximation, and as such are less accurate than the actual clustering itself since it tries to imitate the clustering in a sense. You can find more about that here. However, the soft probabilities are especially helpful if you have a bunch of outliers that you want to assign to topics or if you want to know more about the potential topic distributions. |


The probabilities that are generated within BERTopic are a result of the soft clustering capabilities of HDBSCAN. More specifically, these probabilities are generated after finding the clusters and are exactly an approximation of the probabilities, not the process by which the clusters are created. In other words, the probabilities that are calculated by HDBSCAN are an approximation of its fitting process and will not exactly match the actual clusters that are created.
Lastly, the output of
.reduce_outliersis done with a different process than how the probabilities are calculated, so updating the probabilities with the output of.reduce_outliersis not possible since they are created fro…