Repository navigation
Releases: PixelML/club-170hx
Release list
Qwen3.8-27B no-train Jev endpoint — benchmark video (1× CMP 170HX, 180 W)

Claim. A stock, no-train Qwen3.8-27B (W4A16 GPTQ) serves LLM-as-judge reads on one CMP 170HX at a 180 W cap: 141.7 ms per read idle (one prompt evaluation, logprob read — no answer generated); first production workload 2026-09-21: 19,045 annotations in 4.53 h, 0 failures, 5 permutation reads per annotation, 16 clients; engine prefill 1,952 tok/s at a 178 W mean (vs ~1,955 tok/s synthetic at the same cap); answer under load 12.0 s mean, 99.8% within 15 s (queue-bound); prefix-cache hit rate 0.0% on this traffic.
Limitation. Loaded answers are queue-bound; n=42 calibration is descriptive, not certified. Classification reads only — generation throughput is a separate notebook.
Artifacts. benchmark-video.mp4 (1080×1080, 30 fps, 8 s, silent by design), benchmark-video-poster.png, benchmark-video.json (claims source), benchmark-video-source.zip (editable HyperFrames 0.8.22 project).
SHA-256
- benchmark-video.mp4
7ca44554a0a946224f1419f5496994ff9544e1704b3dcefffceeefda57ec9d64 - benchmark-video-poster.png
1b4c96ce2c9b4e9a67987228f8baf6cdc453aca7e7cd33259d63e797f646dbae - benchmark-video.json
ccf5336bede5ae8903f33d42e588afd5c2d0b4bbd608625178afea312211667f - benchmark-video-source.zip
eb237e7055ba7248a97a545c4b09ddfd2945cd4f19ec5cf1a0150a7c88d25084
Independent exact-file review: 5/5 checks pass (hashes, numeric reconciliation, public-boundary scan, ffprobe runtime, frame inspection). Receipts: results/2026-09-20-qwen3.8-27b-w4a16-jev-1card-vllm/ on main.
GLM-5.3-Flash — PP4 + MTP k=3 on vLLM sm80 (87.6 tok/s c=1)
GLM-5.3-Flash — 4x CMP 170HX (SM80) — PP4 + MTP k=3, vLLM sm80
Pipeline parallelism, not tensor parallelism, is the right topology for this model on a
four-card node with no NVLink and no P2P. PP4 with the model native MTP drafter at depth 3
is the recipe of record and replaces the 2026-09-03 TP4 result.
TL;DR
| Metric | Value | Protocol / label |
|---|---|---|
| Decode, c=1 | 87.55 tok/s | P1 math workload, temperature 0, 512 output tokens, median of 3, clean completion — measured |
| Decode, c=1 | 67.91 tok/s | P2, temperature 0.7 + ignore_eos, 512 output tokens, median of 5 — measured |
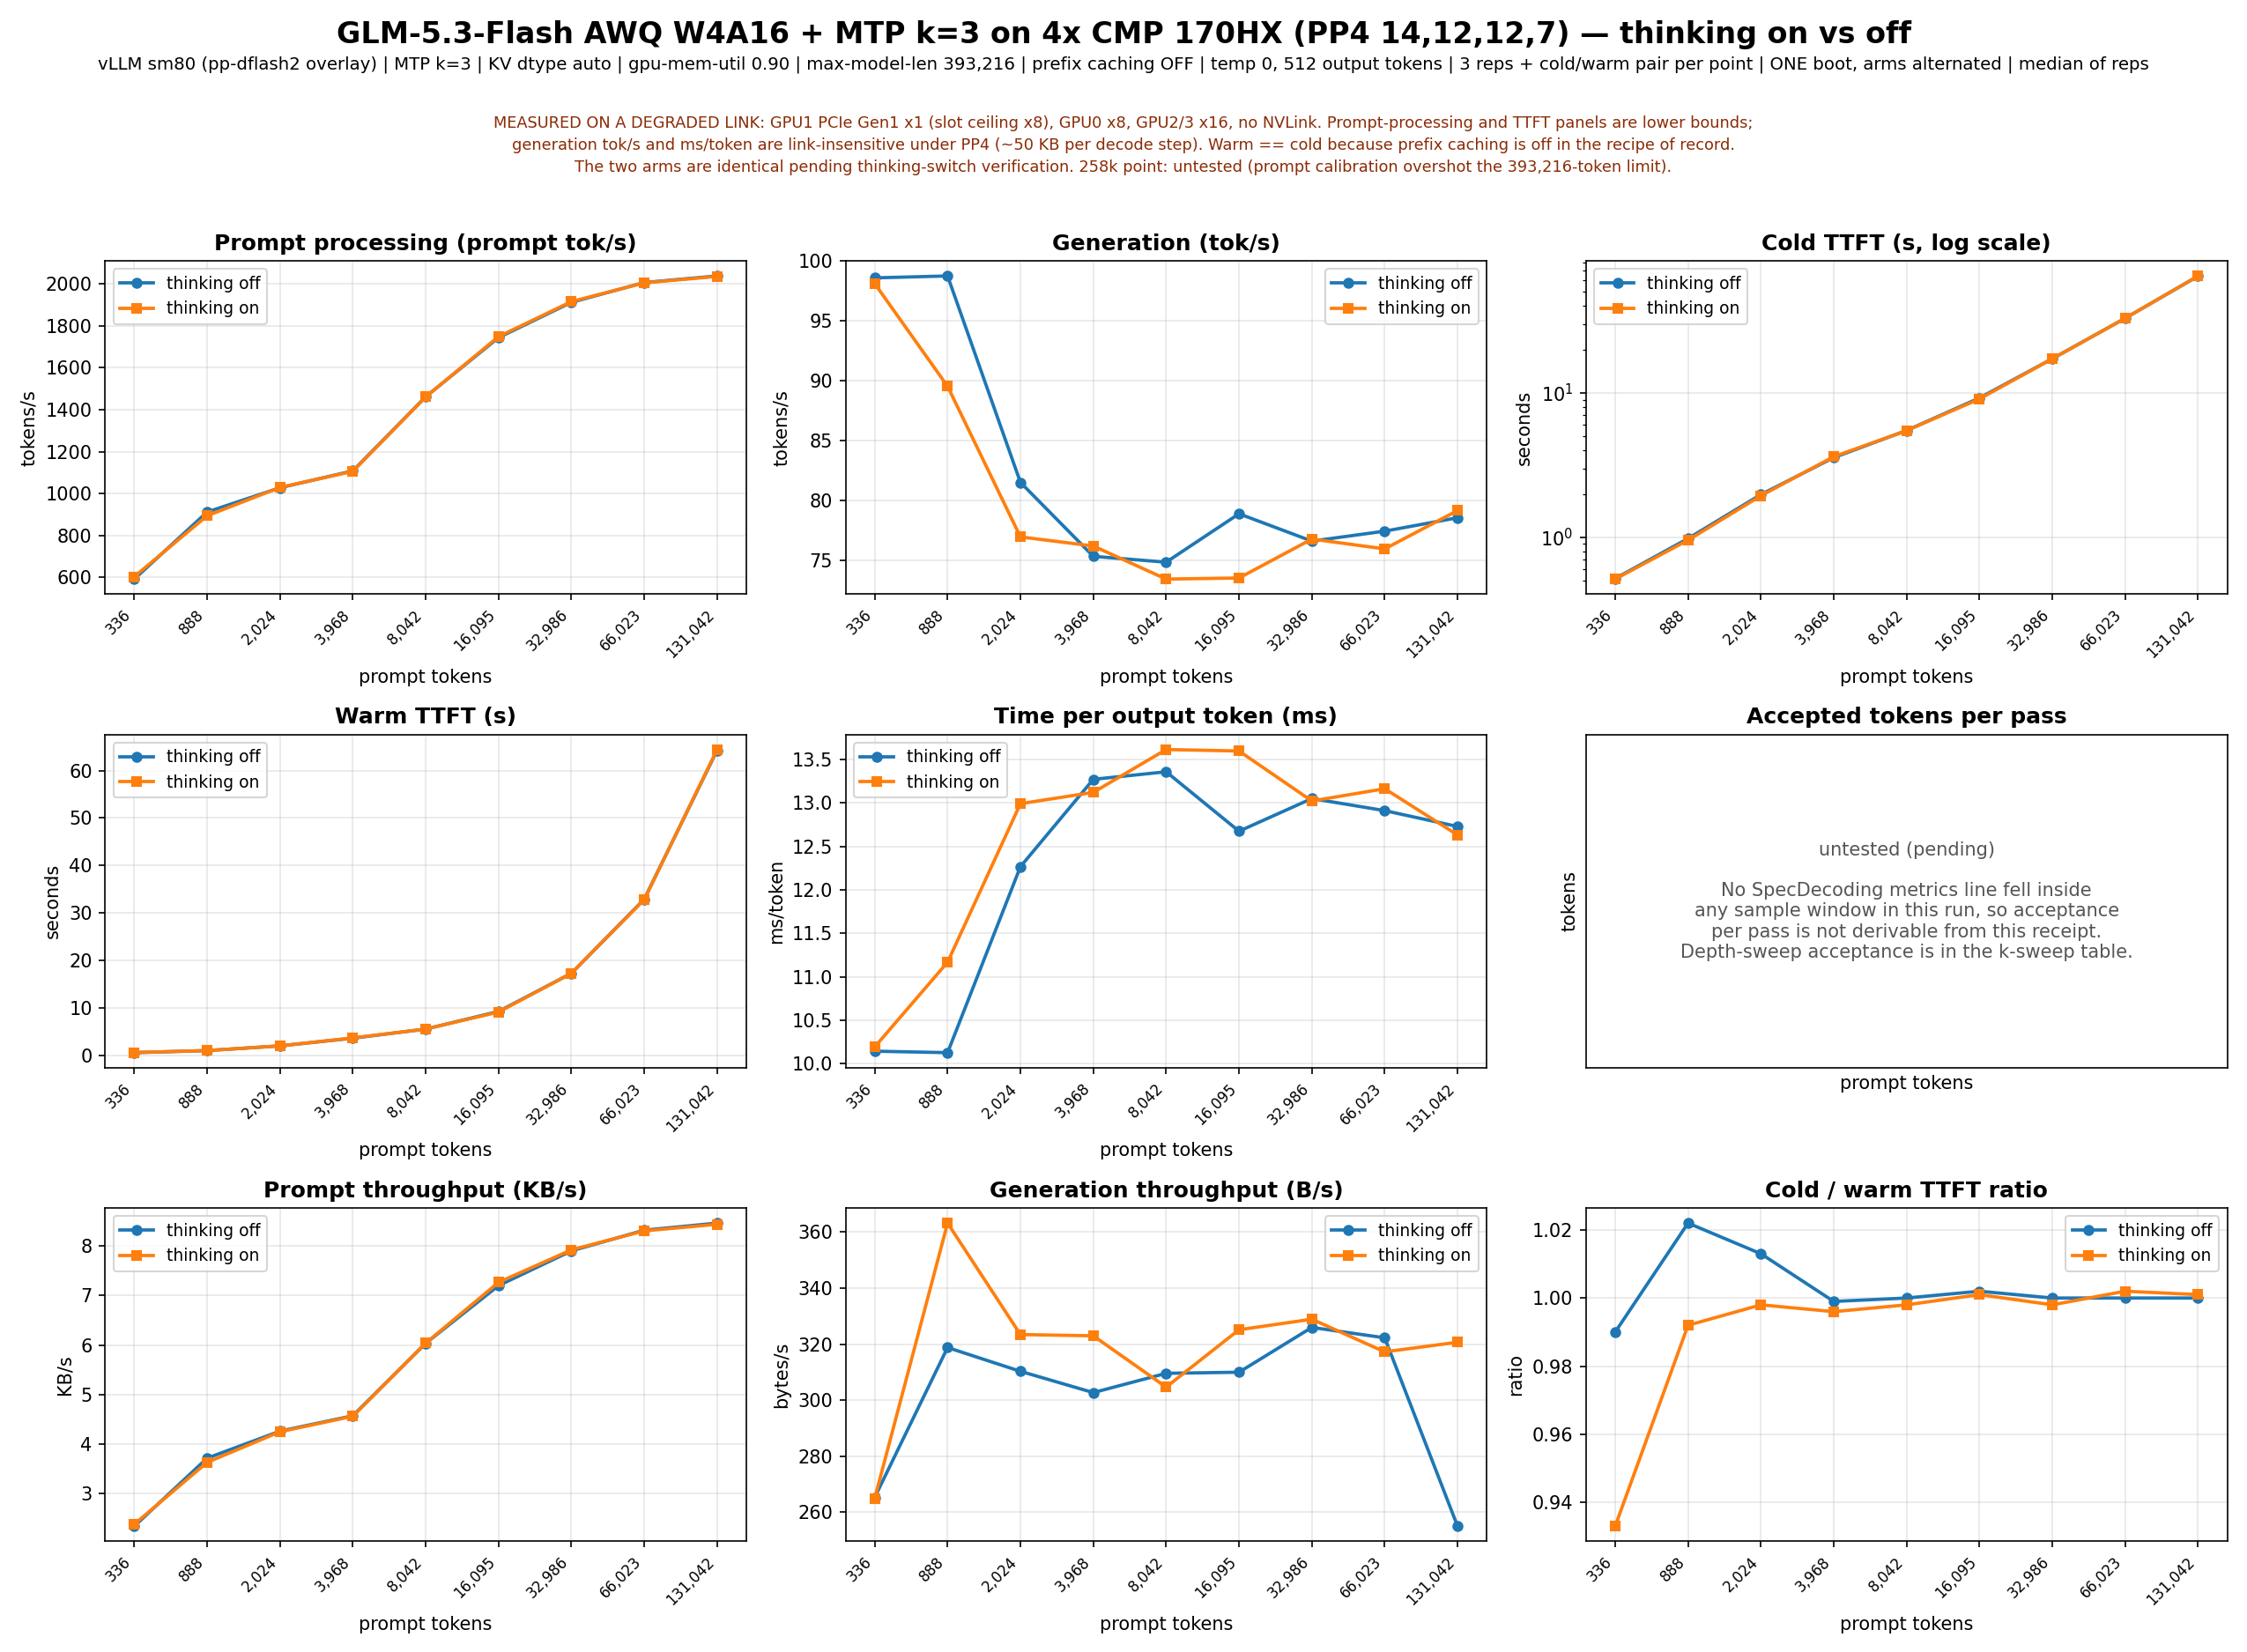
| Decode vs context | flat 74-79 tok/s from 8,192 to 131,042 prompt tokens | c=1 — measured |
| Drafter value | 1.62x over speculation off | native MTP k=3 vs k=0, same protocol — measured |
| Best aggregate | 78.4 tok/s at c=16 | 4,096-token prompt, 256 output tokens — measured on a degraded link |
| Prefill | 1,752 tok/s at 16,384 prompt tokens | median of 3 — measured on a degraded link |
| TTFT | 9.44 s at 16,384 / 3.67 s at 4,096 prompt tokens | warm, streaming, prefix caching off — measured on a degraded link |
| Quality | GSM8K 49/50, HumanEval 19/20 pass@1, structured output 10/10 | checkpoint sampling defaults — measured |
| Stability | 3/3 rounds of c=8, 24/24 requests, zero Xid, 48-53 C | sustained — measured |
| Boots | 8/8, 795-1,263 s | measured |
| NVFP4 on this pool | not viable | 2 attempts, out-of-memory in the MoE conversion; SM80 has no native FP4 — measured |
| Lossless parity | not measurable on this stack | greedy output is not reproducible with speculation on or off — measured |
| 258k context | untested |
server configured to 393,216; 131,042 is the largest prompt run |
| Vision path | untested |
multimodal profiling disabled as a node workaround |
| Upstream author throughput figures | community-reported |
never mixed into the tables above |
Pre-release. The vision path is unmeasured, the block-drafter lane is still in
progress, and the aggregate / prefill / TTFT cells were measured while one card PCIe
link had retrained to Gen1 x1. This release is updated in place as those close.
Pins
| Pin | Value |
|---|---|
| Checkpoint | wtdcode/GLM-5.3-Flash-AWQ-W4A16 @ abd7b07719111f137e1de8a0c1b7e01c11b74d1a (24 files, 190,843,146,533 bytes, byte-verified) |
| Quantization | AWQ W4A16 (compressed-tensors) |
| Fork | PixelML/sm80vllm, branch pp-dflash2/glm53-flash-487ecf187-20260905 — orphan overlay over vllm/vllm-openai:glm53-flash @ 487ecf187 plus 24 ported patches |
| Recipe script | recipes/glm53-flash-4x170hx-pp4.sh on that branch |
| Image | ghcr.io/pixelml/club-170hx:vllm-glm53-sm80-pp-20260905 |
| Image index digest | sha256:62f612b49614523e6a46e1493d35d3efd1f363917129d38cc923a31053693bfb |
| Topology | PP4, VLLM_PP_LAYER_PARTITION=14,12,12,7 (45 hidden layers) |
| Speculation | native MTP, num_speculative_tokens=3 |
| Context | --max-model-len 393216; largest prompt measured 131,042 tokens |
| KV dtype | auto; prefix caching off |
| Hardware | 4x CMP 170HX (SM80, 64 GiB each), 180 W per-card cap, no NVLink |
| Link state during the run | degraded — one card at PCIe Gen1 x1, one at x8, two at x16 |
| Measured | 2026-09-05 |
Pull and run
# 1. Pull the image by digest
docker pull ghcr.io/pixelml/club-170hx@sha256:62f612b49614523e6a46e1493d35d3efd1f363917129d38cc923a31053693bfb

# 2. Download and verify the weights: expect 24 files, 190,843,146,533 bytes,
#    0 missing or mismatched. Stage on local NVMe, not a network mount.
pip install -U huggingface_hub
hf download wtdcode/GLM-5.3-Flash-AWQ-W4A16 \
  --revision abd7b07719111f137e1de8a0c1b7e01c11b74d1a \
  --local-dir <weights>

# 3. Launch (recipe of record: recipes/glm53-flash-4x170hx-pp4.sh on the fork branch)
docker run -d --name <container> --gpus '"device=0,1,2,3"' \
  --shm-size 16g --ipc=host -p 127.0.0.1:<port>:8000 \
  -e HF_HUB_OFFLINE=1 \
  -e VLLM_PP_LAYER_PARTITION=14,12,12,7 \
  -e VLLM_WORKER_MULTIPROC_METHOD=spawn \
  -e TORCH_CUDA_ARCH_LIST=8.0 \
  -e VLLM_PP_MAX_DECODE_REQS_PER_BATCH=2 \
  -e VLLM_GLM5N_SIDECAR_BLOCK_SIZE=256 \
  -v <weights>:/weights:ro \
  ghcr.io/pixelml/club-170hx:vllm-glm53-sm80-pp-20260905 \
  --model /weights --served-model-name GLM-5.3-Flash \
  --pipeline-parallel-size 4 \
  --max-model-len 393216 \
  --gpu-memory-utilization 0.90 \
  --no-enable-prefix-caching \
  --max-num-seqs 8 --max-num-batched-tokens 4096 \
  --speculative-config '{"method":"mtp","num_speculative_tokens":3}' \
  --limit-mm-per-prompt '{"image":0,"video":0}'

# 4. First request
curl http://127.0.0.1:<port>/v1/chat/completions \
  -H 'Content-Type: application/json' \
  -d '{"model":"GLM-5.3-Flash",
       "messages":[{"role":"user","content":"What is the capital of France? Answer with just the city name."}],
       "temperature":0,"max_tokens":128}'
Expected boot: about 17 minutes (1,029 s measured) from locally staged weights, 320 s of
which is engine init. Short factual answers need max_tokens >= 128; this model reasons
before it answers.
Links
- Notebook (executed proof): notebooks/2026-09-05-glm-5.3-flash-4card-pp4-vllm.ipynb
- Model guide (durable how-to): docs/models/glm-5.3-flash.md
- Chart source: assets/charts/2026-09-05-glm-5.3-flash-pp4-context-sweep.py
- Evidence repository: PixelML/GLM-5.3-Flash-CMP-170HX — raw receipts release
pp4-2026-09-05 - Fork branch: PixelML/sm80vllm @ pp-dflash2/glm53-flash-487ecf187-20260905
- HF Collection: club-170hx: verified on CMP 170HX (SM80)
Supersedes
glm-5.3-flash-4card-tp4-20260903 — TP4 + MTP k=3, 60.4 tok/s c=1 median under the same P2 protocol. TP is link-bound on this fabric: the identical TP4 recipe measured 70.5 tok/s before one card PCIe link retrained narrow and 14.4 tok/s after, while PP4 held 60.8 tok/s on the same degraded box. The TP4 release is kept for history.
Attribution
| Source | License | What was taken |
|---|---|---|
| promisezackr/glm53-flash-170hx-pp8 | Apache-2.0 | The pipeline-parallel patch set, 24 patches, applied over vllm/vllm-openai:glm53-flash @ 487ecf187 with per-patch attribution trailers. The KV-balancing rule behind the layer partition is his; the four-stage split is our adaptation. His scripts/bench.py is the P1 protocol and its repeat guard, used unmodified. His published throughput figures are community-reported and are not mixed into the measured tables. |
| wtdcode/vllm-backport, wtdcode/GLM-5.3-Flash-AWQ-W4A16 | Apache-2.0 (backport); per the model card (checkpoint) | The SM80 vLLM enablement these images descend from, and the AWQ W4A16 checkpoint used as published at the pinned revision. Third-party verified, not re-quantized and not mirrored. |
| incoai/GLM-5.3-Flash-DFlash2 | cc-by-nc-nd-4.0 | The block drafter, downloaded for measurement only. It is a net loss on our AWQ checkpoint and is recorded as a negative cell. Not redistributed. |
Assets
Chart PNG and SVG, both video cuts (1080x1920 and 1920x1080) with the poster, and the raw
receipts tarball from the evidence repository.
GLM-5.3-Flash — TP4 + MTP-3 on vLLM sm80 (56.4 tok/s c=1)
Superseded by glm-5.3-flash-4card-pp4-20260905 (2026-09-05). Kept for history.
GLM-5.3-Flash — 4x CMP 170HX (SM80) — TP4 + MTP-3, vLLM sm80
TL;DR
| Metric | Value |
|---|---|
| Decode, c=1 (median of 5 reps) | 56.4 tok/s (peak 56.9) — 2.1x the EXL3 lane |
| Best aggregate | 37.0 tok/s at c=8 (below EXL3's 44.8; TP4 all-reduce bound — PP4+MTP port pending) |
| Prefill / TTFT | untested |
| Context | 524,288 tokens (KV cache 650,916 tokens) |
Pre-release: GLM-5.3-Flash has vision capability (Glm5NextForConditionalGeneration); this run measured text-only. Will be updated in place when the vision path is measured.
Pins
| Pin | Value |
|---|---|
| Checkpoint | wtdcode/GLM-5.3-Flash-AWQ-W4A16 @ abd7b07719111f137e1de8a0c1b7e01c11b74d1a (190,843,146,533 bytes, byte-verified) |
| Fork | PixelML/sm80vllm, branch glm53-sm80 @ f6fbf3b854 |
| Image | ghcr.io/pixelml/club-170hx:vllm-glm53-sm80-20260903 (sha256:f7fe5d02c2951500448553f1783ff781470f7d3fdff943ff1492659cf775bb64) |
| Driver | 610.43.03 |
| Topology | TP4, 4x CMP 170HX, 180 W per card, forced airflow |
| Speculative | native MTP k=3 (swept k=2: 51.1 / k=3: 56.4 / k=5: 47.1 median) |
Run
docker pull ghcr.io/pixelml/club-170hx:vllm-glm53-sm80-20260903Launch command, weights verification, and bench protocol:
notebooks/2026-09-03-glm-5.3-flash-4card-tp4-vllm.ipynb
Links
- Notebook (executed proof): notebooks/2026-09-03-glm-5.3-flash-4card-tp4-vllm.ipynb
- Model guide (durable how-to): docs/models/glm-5.3-flash.md
- Raw receipts: results/2026-09-03-glm-5.3-flash-vllm-sm80-4gpu/README.md (+ tarball attached)
- Fork branch: https://github.com/PixelML/sm80vllm/tree/glm53-sm80
- HF Collection: club-170hx: verified on CMP 170HX (SM80) — wtdcode/GLM-5.3-Flash-AWQ-W4A16 @ abd7b0771 added as third-party-verified
DeepSeek-V4-Flash-Vision-Exp on 4x CMP 170HX: vision measured, 119 tok/s median text c=1 (peak 162)
DeepSeek-V4-Flash-Vision-Exp on 4x CMP 170HX: vision measured
Real image input now runs on vLLM (SM80 fork, PP4, DSpark k=6) on four $1,600 mining cards. Measured 2026-09-02.

| Measurement | Value |
|---|---|
| Image gates (golden corpus) | 10/10 keyword match |
| Decode c=1, text only | 119 tok/s median of 5 reps (peak 162) |
| Decode c=1, text + image | 45.3 tok/s |
| Power cap 250 W vs. 180 W | no gain (latency-bound); 180 W kept |
| Decode c=2, text + image | 78.2 tok/s |
| Uncached prefill, 2,941 tokens | 2,352 tok/s warm |
| Warm streaming TTFT | 0.386 s |
| Concurrency limit | engine crashed at c=4 (text ladder, rep 3); recorded, not hidden |
| Boot from NVMe | about 6 min |
Text-only reference run on the same cards earlier the same day (text-path image): c=1 97.4, c=8 220.2 tok/s aggregate.
Pins: model deepseek-ai/DeepSeek-V4-Flash-Vision-Exp revision 86f746b36186f0e567729a5c06a8c918caba82a9; SM80 vLLM fork plus the PixelML vision port (five boot fixes, patch series in the evidence repository); partition 11,11,11,10; fp8 KV; max-model-len 16384.
Run it:
docker pull ghcr.io/pixelml/club-170hx:vllm-deepseek-v4-vision-sm80-20260902
Vision image digest sha256:b26232f8f041c988d3285e2278c9f5001cc49f96131bb0b22a9d38b5e5e061cd. Text-path image: ghcr.io/pixelml/club-170hx:vllm-deepseek-v4-sm80-20260902.
Links: vision notebook, text notebook, evidence repository, Hugging Face collection.
Known limits: text exact-match against the DGX Spark reference is 10/20 (finish_reason drift); the engine is not stable above c=2 on this build. Both are tracked as follow-ups.