Repository navigation
Releases: ahmadhammoud56/MOAA
Release list
MOAA 0.12.1: council vs single-agent benchmark, prismantis 0.34.0

Added
- Council vs single-agent benchmark (
benchmarks/council-vs-solo): Sonnet alone, Opus alone and the council
on 5 tasks with fixed answer keys (three code reviews with 25 planted bugs and 10 decoys, 10 statistics claims, 10
trap questions), 3 runs each, in clean headless sessions with no shell or file writes.bench.pyruns, resumes and
scores it on a normal Claude Code login, andverify_keys.pyre-proves every answer key by execution. Raw results
for all 45 runs are included.- Result: both single models scored 100% in every run. The council never did better, cost 2.5–6× as much and
took 3.5–7× as long. One council run lost its answer to a late worker report.
- Result: both single models scored 100% in every run. The council never did better, cost 2.5–6× as much and
- Replay tool, arena runs:
tools/council-replaynow recognises an Agent Arena transcript and labels it as one:
contestants, the judge, the verdict and the winner.
Changed
- Specialist Council 1.6.1:
- It now sizes the job first. Short tasks with a checkable answer get one worker or a direct answer, unless the
user explicitly asks for several workers. Teams are for ambiguous, long or high-stakes work. - It waits for every worker, and after a late report it restates the full answer instead of pointing back to it.
Headless use keeps only the last message.
- It now sizes the job first. Short tasks with a checkable answer get one worker or a direct answer, unless the
- Specialist Council README rewritten: marketplace install, use, roles, cost ledger and commands. The old one still
described the pre-plugin standalone install. - README: the cost section states the benchmark result.
- prismantis 0.11.0 → 0.34.0 (23 upstream releases).
- The vendored copy is upstream v0.34.0 without its Codex plugin files and the 14 MB of screenshots in
docs/
(1.5 MB instead of 4.3 MB). - MOAA's PNG button is re-applied on top. It is now opt-in through
PRISMANTIS_PNG_BUTTON, which the installer's
default env sets to 1, so upstream's own test suite passes unchanged: 844 of 844 including the button's 2 tests. MODIFICATIONS.mdandpng-button.patchdescribe the change against clean v0.34.0.
- The vendored copy is upstream v0.34.0 without its Codex plugin files and the 14 MB of screenshots in
MOAA 0.12.0: cost ledger, council evals, one-line install
The first milestone of the October roadmap: measure what the council costs,
start proving what it adds, make the first install one line, and trim per-prompt overhead.
Added
- moaa-core 0.1.0 (new plugin):
/plugin install moaa-core@moaainstalls the Specialist Council, the Agent Arena
and moaa-catalog as plugin dependencies, with no clone and no installer. It has no components of its own. - Specialist Council 1.6.0, cost ledger: a
SubagentStophook records every finished subagent's input, output
and cache tokens (each message counted once) in~/.claude/specialist-council/ledger.jsonl.
council.py cost [--session ID | --days N]sums them per agent type, and the council skill ends each answer with
one cost line. Tokens only: no price table is guessed. - Specialist Council eval suite in
plugins/specialist-council/evals/forclaude plugin eval: 4 cases
(factoring, a digit count, an off-by-one review and a Simpson's-paradox claim), each run with and without the
council so the report shows what the council adds. It needs an API key, so it runs by hand or through the new
manual Council evals workflow (ANTHROPIC_API_KEYsecret, cost ceiling as an input). install.py --reportnames enabled plugins that only repeat another enabled plugin's skills.- docs/GUIDE.md (the detailed reference) and docs/PLUGINS.md (the generated plugin list);
docs/media/social-preview.png(1280×640) and its HTML source for the repository's social preview.
Changed
--mode all-onleaves duplicate plugins off: a plugin whose every skill another plugin of the same
marketplace already lists (the 34agentic-bundle-*subsets of agentic-awesome-skills) is no longer enabled, and
is disabled if it was. On the maintainer machine that drops 283 skills, about 1.8k tokens from every request (23,490 to 21,676 under the all-on listing caps), with
nothing lost.--restorere-enables them.strict: falsemarketplace entries count only their listed skill
folders.- Faster hooks (moaa-catalog 0.3.1, strata 0.1.1): hook commands no longer start Python once just to check its
version. The scripts exit 3 on Python older than 3.10 and the command tries the next interpreter, skipping the
Windows Store alias (exit 49). The catalog prompt hook went from 108–184 ms to 81–117 ms per prompt here. - README rewritten around one first screen: a one-line hook, a two-line
/plugininstall, the council GIF, the
arena-to-council loop and a feature table (49 KB to about 7 KB). Everything else moved to docs/GUIDE.md. scripts/sync_catalog.pywrites the plugin list to docs/PLUGINS.md instead of the README.- Marketplace description now describes MOAA instead of "agent arena and UI mods".
Fixed
- CI now runs moaa-catalog's tests (its prompt hook runs on every prompt but had no CI step).
- CITATION.cff: earlier releases bumped
cff-version(the format version, back to 1.2.0) instead ofversion
(now 0.12.0).
MOAA 0.11.1: forged members get every tool
Agent Arena 0.6.1: forged council members get every tool except Agent again (disallowedTools: [Agent]), MCP servers included. The 60 council role agents keep their core tool list. See CHANGELOG.md.
MOAA 0.11.0: every plugin on, fewer tokens
Every plugin on, fewer tokens.
install.py --mode all-on: enables every catalog plugin (opt-in ones such as claude-mem excepted), so every hook, agent, MCP server and command is live, and trims the skill listing to names plus short descriptions (skillListingMaxDescChars200,skillListingBudgetFraction0.003).--mode leandisables the big packs and restores the earlier limits. Settings are backed up first, and--uninstallalso restores them.- moaa-catalog 0.3.0: in all-on mode, the index and the prompt hook also cover enabled skills whose descriptions the listing trims, pointing to the Skill tool for them.
- Fixed:
--reportnow follows Claude Code's own listing caps instead of counting full descriptions, which overstated the cost several times over. Reinstalling now keepspruned,modeand the report history.
See CHANGELOG.md for details.
MOAA 0.10.0: work profiles, usage report, effort trial
Easier to start with, cheaper to run.
- Work profiles:
install.py --profile web|data|devops|research|science(comma-separated for several) adds that kind of work's packs, installed and enabled;sciencealso sets up the ansys MCP server. install.py --report: a local summary of the skills listed in every request and their rough token cost, what disabled plugins keep out of the prompt, the most used plugins, catalog hits and pruned plugins, with a trend line. Nothing leaves the machine.- Agent Arena 0.6.0, effort trial:
/agent-arena-mode:effort-trialmeasures, with blind judging, whether a council role finds more at a higher effort, and suggests a preset only when the dearer effort earns it. It never edits presets. - moaa-catalog 0.2.0: short-form synonyms (k8s, tf, py and more), project-file hints and
/moaa-catalog:moaa-help. - Getting started:
docs/GETTING_STARTED.md, a 5-minute walkthrough. - Fix:
--prunenow counts a slash command only when a user typed it.
See CHANGELOG.md for details.
MOAA 0.9.0: skills on demand, lower context cost
Context cost, after Cloudflare's write-up of their AI code reviewer: most of their savings came from sending fewer tokens and making fewer calls.
- moaa-catalog 0.1.0 (new, core): skills on demand. Big skill packs stay installed but disabled; a cached index, a prompt hook for strong matches and one-call
usebring in a single skill when a task needs it. - Installer:
--fullinstalls agentic-awesome-skills and the ruflo extras disabled;--leandoes the same for older installs;--prune [--yes]/--restore; a context-budget check in--statusand--doctor. - Specialist Council 1.5.0 / Agent Arena 0.5.1: explicit core tool lists for workers (no MCP tool definitions per call) and cache-friendly brief ordering.
- War Room 0.7.0 / Allies 0.2.0: a timed-out ally task is retried with double the limit, a task taken away stops its process, runs record why they failed, and workers end without a closing summary turn.
On the author's machine, --lean cut the skills listed in every request from 3,630 to 1,148. See CHANGELOG.md for details.
MOAA 0.8.1: War Room hub starts fast on macOS
Fixed
- War Room 0.6.1: the hub no longer does a reverse DNS lookup of the machine when it starts.
- Python's HTTP server does this by default (
socket.getfqdn()). - On macOS the lookup can stall for 30 seconds or more, so the War Room app could be slow to open or not open at all.
- The new hub tests in 0.8.0 caught this on macOS CI.
- The hub tests now wait up to 30 seconds and report a crash clearly.
- Python's HTTP server does this by default (
CI passes on Windows, Linux and macOS, including the clean-install jobs.
Everything else is as in 0.8.0: the War Room app redesigned around allies, and fuller Allies and Strata sections in the README.
MOAA 0.8.0: War Room redesigned for allies
War Room 0.6.0: the app redesigned around allies
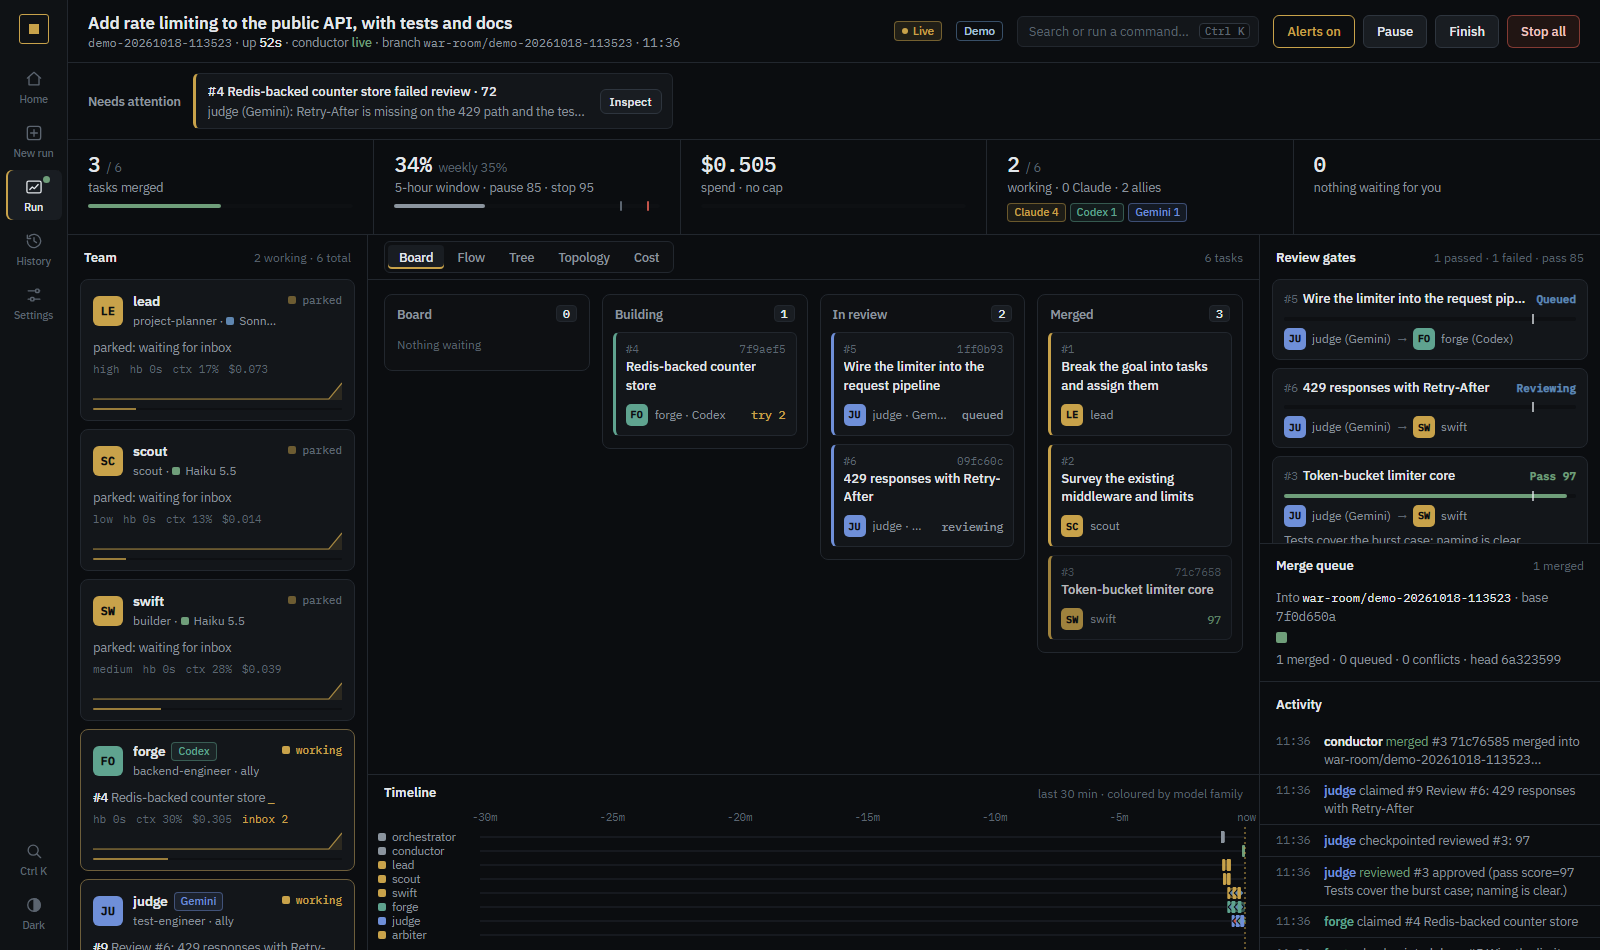
- One shell for every page: an icon sidebar (Home, New run, Run, History, Settings) and a Ctrl+K command palette.
- Model families everywhere: Claude, Codex, Gemini, Kimi, DeepSeek and OmniRoute workers each have their own colour and badge. Claude tiers stay visible as a small swatch.
- Run view:
- A needs-attention strip. Human gates can be approved or rejected right there.
- A KPI strip (tasks merged, the 5-hour window, spend, Claude versus allies working, gates waiting).
- Team cards.
- A kanban Board, the new default view.
- A task inspector: reviews and notes, the commit with its diff stat, the people involved and the history.
- A family-coloured timeline. Flow, Tree, Topology, Cost, replay and the worker drill-down are kept.
- Home, New run and Settings are now separate pages. The plan editor picks an engine per worker (a Claude tier or an ally).
/?template=mixed-allies#newopens a team directly. - History gains a filter and shows each run's team.
- Typography: IBM Plex Sans for text and Plex Mono only for data. The style stays flat, with no gradients or glow; dark, light and system themes; reduced motion is respected.
- New hub routes:
POST /api/run/<run>/decide(human gates, blocked tasks only, token-protected).GET /api/run/<run>/task/<id>/diff.- Shared
/ui.cssand/ui.js.
- The demo team now includes a Codex builder and a Gemini reviewer.
README
The Allies and Strata sections now explain:
- what each plugin is for;
- how each one keeps your code and credentials safe;
- how to use them, with examples.
Checks
All suites pass, along with the public-release scan and plugin validation. The UI was tested only with demo runs in an isolated profile, so no tokens were spent. An independent code review found no serious issues; its three low-severity findings are fixed.
MOAA 0.7.1
Fixed
- Allies 0.1.1: the npm shim parser now splits the script path the shim gives (written with backslashes) into
folders, so it is correct on every OS. 0.7.0's CI failed on Linux and macOS because of this; Windows, where shims
are used, was not affected. All suites were also run on Linux (WSL) before this release.
See 0.7.0 for Allies, Strata and the rest of this line.
MOAA 0.7.0: Allies and Strata
Added
- Allies 0.1.0 (new plugin): other agent CLIs on call.
- Claude Code hands a bounded brief to OpenAI Codex, Google Gemini, Moonshot Kimi Code, DeepSeek (Claude Code with
--bareon DeepSeek's Anthropic-format API) or a local OmniRoute gateway. It then reads and checks the answer. - Each member uses its own account, so the work spends that service's quota rather than Claude usage.
allies.py doctorshows what is installed and signed in.rungives one member a read-only task, andasksends
the same brief to several members in parallel.run --writeworks in a separate git worktree. Allies commits the result on branchally/<member>-<id>and never
touches your checkout.- Every run is kept under
~/.claude/allies/runs/. Keys can live in~/.claude/allies/keys.env, outside any
repository; each member gets only its own key. - In read-only work Gemini runs under a shipped policy that denies shell and file-write tools; headless Gemini
otherwise waits forever for an approval no one can give. - Windows short (8.3) paths are expanded before a member runs, because Codex's sandbox denies them. Its
sandbox also cannot enter the user Temp folder, so keep projects in normal folders. - Gemini uses an API key: Google sign-in no longer serves the CLI's free tier. Gemini runs in its own home, set to
API-key sign-in, so your~/.geminiis left alone. doctorreportsblockedwhen a member's service cannot be reached from the current network.- The Claude-format members never read your Claude login.
- An
alliesskill covers briefing, verification, stretching Claude limits, and what never to send. - Verified live with Gemini (API key) on a read-only question, and with Codex: a read-only question (correct answer, no files changed) and a write task (bug fixed
with a test, committed on its own branch).
- Claude Code hands a bounded brief to OpenAI Codex, Google Gemini, Moonshot Kimi Code, DeepSeek (Claude Code with
- Strata 0.1.0 (new plugin): layered long-term memory across sessions.
- Four layers, after the design of TencentDB Agent Memory: raw sessions, extracted notes with supersession,
per-project scenes and a user profile. - Stored in local SQLite with FTS5, using standard-library Python.
- The SessionStart hook injects the profile, scenes and recent notes, labelled as data.
- The SessionEnd hook stores the session and starts one background Haiku extraction. That call has all tools
denied and saves no session, so it cannot recurse. - Secrets are redacted on the way in, and model output is validated before it is stored.
- The
strataskill searches, shows, remembers, corrects and forgets. - Verified on a real transcript: one Haiku call (71 s) produced 11 accurate notes, a project scene and a profile
entry.
- Four layers, after the design of TencentDB Agent Memory: raw sessions, extracted notes with supersession,
- War Room 0.5.0: ally workers.
- A plan worker can set
"engine": "codex"(or gemini, kimi, deepseek, omniroute). - The conductor claims that worker's tasks, runs them through allies in the worker's own worktree and completes them
with the commit. As a reviewer, the worker returns a parsed verdict. - Review gates and the merge queue are unchanged, so model families can review each other.
- A reviewer without a verdict is retried once, then blocked for the human.
- Ally workers have no console, and stop and resume skip them.
- The plan editor offers the engines in its model list.
- New template:
mixed-allies(Claude plans, Codex builds, Gemini reviews). - Verified live through the War Room bus. Codex fixed a function and added four tests in its worktree (58 s).
Gemini reviewed the commit and passed it at 100 (41 s). The bus then approved the task and queued the merge.
- A plan worker can set
- OmniRoute checked live: pinned 3.8.51 started through allies.
- It listens only on 127.0.0.1 (all three ports).
- The API and management endpoints refuse requests without a key (401).
- The traffic inspector, TLS interception and cloud sync are off, and allies forces them off at every start.
- The
omniroutemember reaches the gateway with your key. With no provider connected it fails at once with a
clear message.
install.py --with-omniroute: installs a pinnedomniroutefrom npm and records it, so--uninstall
removes it.allies.py omniroute startruns it on 127.0.0.1 only, with an API key required, conversation tracking,
browser-cookie providers and paid-credit fallback off, and a generated password and JWT secret instead of
CHANGEME.
- Allies and strata join the core profile (13 plugins). Their read-only subcommands run without prompts.
Changed
- superpowers is tested at 7.0.0 (the catalog already pinned it;
tested_versionsaid 6.4.1).
Fixed
-
Allow rules were too broad (security). MOAA's no-prompt rules for
council.pyandwarroom.pyused
wildcards around the script and the subcommand. Three consequences:app*also matchedapprove, so War Room's human gate could run without a prompt.- A subcommand word anywhere in the arguments matched too.
- A crafted command such as
python -c "..." war-room warroom.py listran without a prompt.
Rules are now pinned to each installed script's exact path, the way Claude calls it, with the subcommand right
after the path. After a plugin update outside the installer the rules simply stop matching, and you get prompts
again until you rerun the installer. Reinstalling removes the rules an earlier MOAA install added (recorded in its
manifest); rules you added yourself are kept.
Security
Hardening from an independent review before release:
- Allies:
- npm
.cmdshims are bypassed: allies runs the node script directly, becausecmd.exewould re-parse task text
(BatBadBut). - Model names are validated.
- Each member sees only its own credentials. Claude, cloud and other providers' keys are removed from its
environment. - A timeout kills the member's whole process tree.
omniroute stopchecks the pid's command line before killing it.- The secrets file is created owner-only.
- Allies' commits skip repository hooks.
- npm
- War Room ally workers:
- A stop kills the running member process and does not report its result.
- A task held by a job that no longer runs (for example after the conductor restarts) is reclaimed.
- Finished work is never reopened.
- A writer with no new commit reports its HEAD for review.
- Verdicts are case-insensitive.
- Strata:
- Redaction also catches JSON and quoted secrets, "password is ...", JWTs, credentials in URLs and AWS secret keys.
- Extraction can no longer create global notes or supersede notes of other projects, so a transcript cannot plant
notes in every project. Onlyremember --globalmakes global notes. - The supersede check and the write happen under one lock.
- A resumed session is consolidated again only when it grew.
- Forgetting a note brings back the notes it had superseded.
- On Windows the background extraction breaks away from Claude Code's job object where allowed.
--uninstallno longer removes anomniroutethat was installed before MOAA.
Upgrading: run python scripts/install.py again. It installs allies and strata and replaces the old War Room and council allow rules with path-pinned ones. Check the result with python scripts/install.py --status.