Repository navigation
Kokoro TTS
Kokoro is a tiny (82M-parameter, ~350 MB) text-to-speech model that is very fast on GPU and usable on CPU. It has 54 built-in voices in 9 languages and needs no reference audio: pick a voice and go.
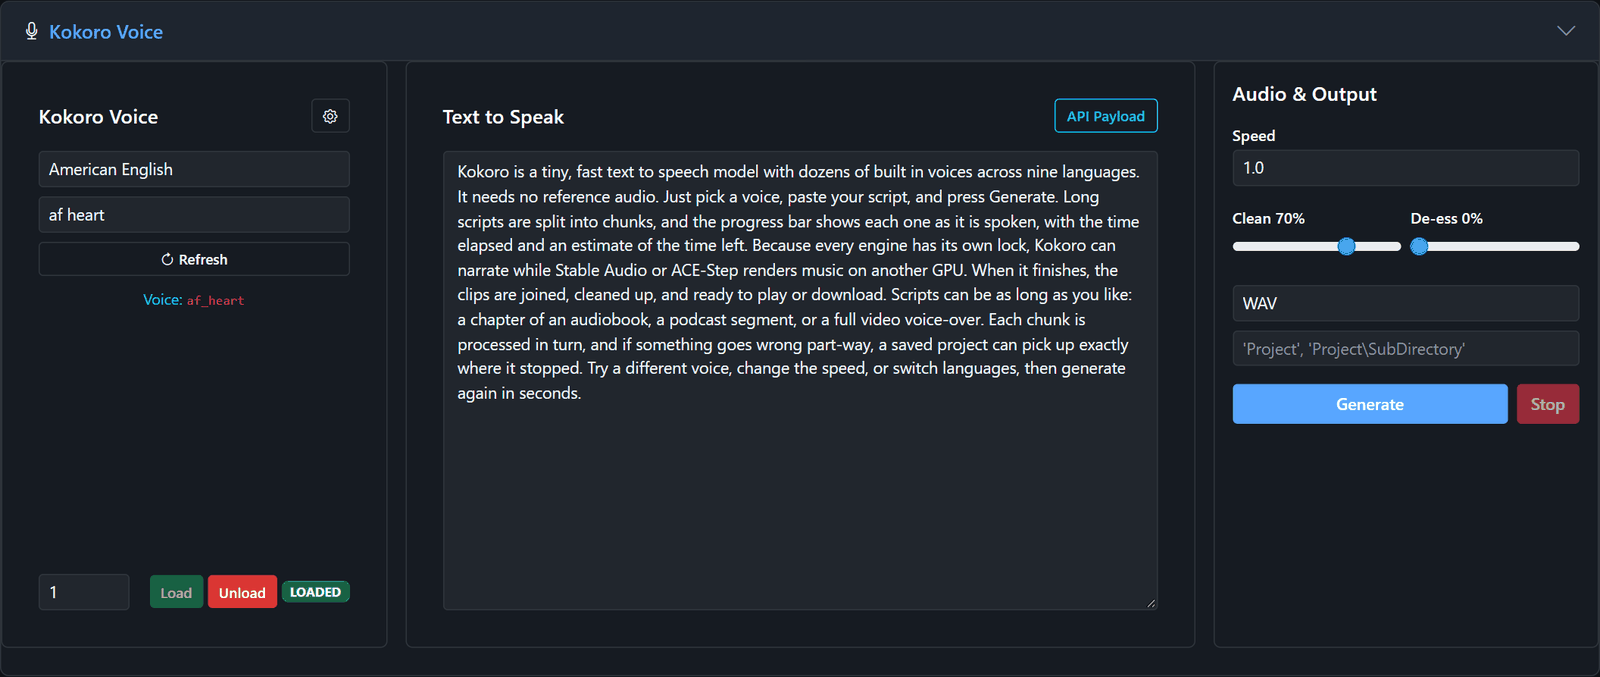
Use Kokoro when you want speed: drafts, long narration, low-VRAM machines, CPU-only setups, or real-time apps. Prefer XTTS or Fish Speech when you need a specific (cloned) voice.
🔊 Listen: Kokoro sample (af_heart)
| Language | Voices |
|---|---|
| American English (20) | af_heart, af_alloy, af_aoede, af_bella, af_jessica, af_kore, af_nicole, af_nova, af_river, af_sarah, af_sky, am_adam, am_echo, am_eric, am_fenrir, am_liam, am_michael, am_onyx, am_puck, am_santa |
| British English (8) | bf_alice, bf_emma, bf_isabella, bf_lily, bm_daniel, bm_fable, bm_george, bm_lewis |
| Spanish (3) | ef_dora, em_alex, em_santa |
| French (1) | ff_siwis |
| Hindi (4) | hf_alpha, hf_beta, hm_omega, hm_psi |
| Italian (2) | if_sara, im_nicola |
| Japanese (5) | jf_alpha, jf_gongitsune, jf_nezumi, jf_tebukuro, jm_kumo |
| Brazilian Portuguese (3) | pf_dora, pm_alex, pm_santa |
| Mandarin Chinese (8) | zf_xiaobei, zf_xiaoni, zf_xiaoxiao, zf_xiaoyi, zm_yunjian, zm_yunxi, zm_yunxia, zm_yunyang |
f = female, m = male. Choose the language first; the voice list follows it. Use the preview player to audition voices.
- Choose a language, then a voice.
-
Pick a device (
cpuworks well; a GPU is faster) and click Load. - Type or paste your text. Long scripts are split into chunks.
- Set speed, Clean, De-ess, format and an optional save path.
- Click Generate.
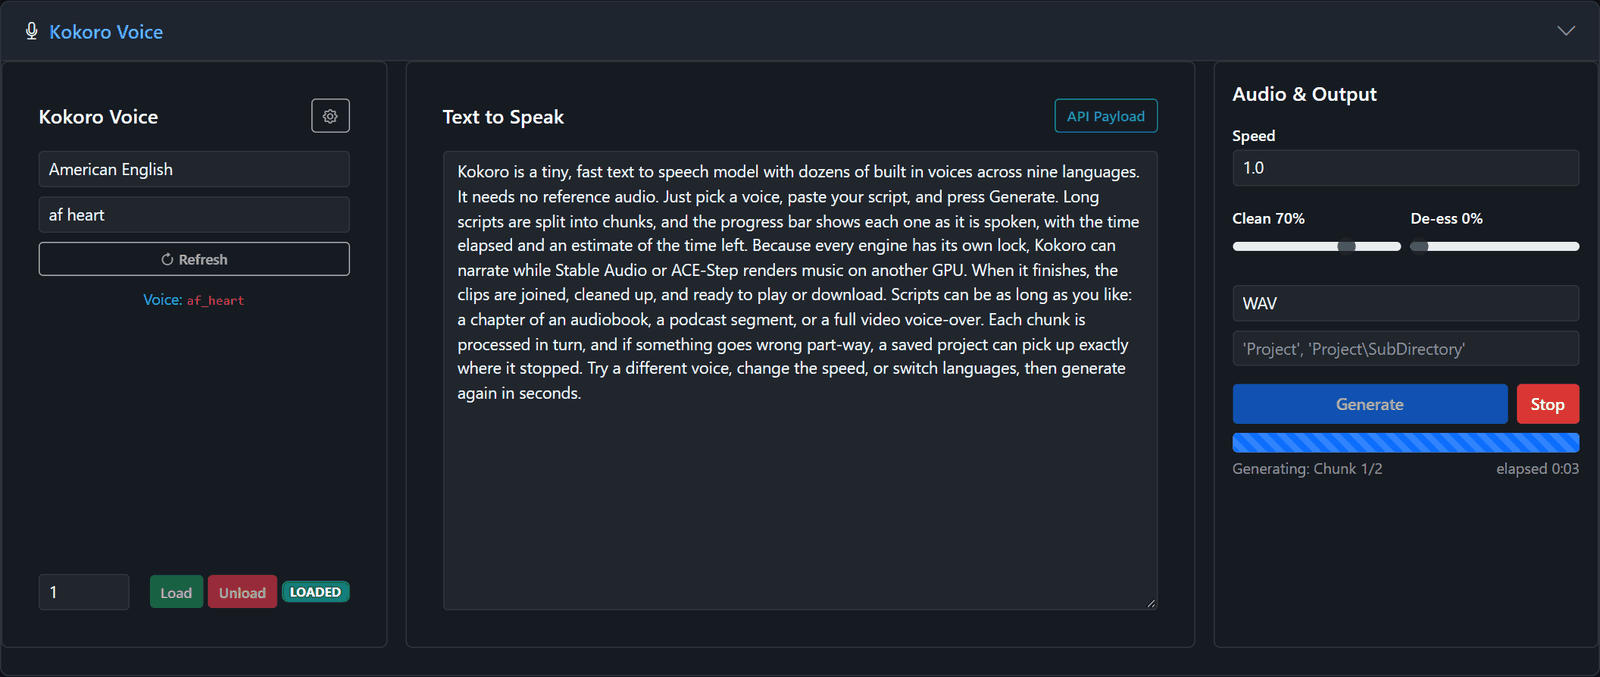
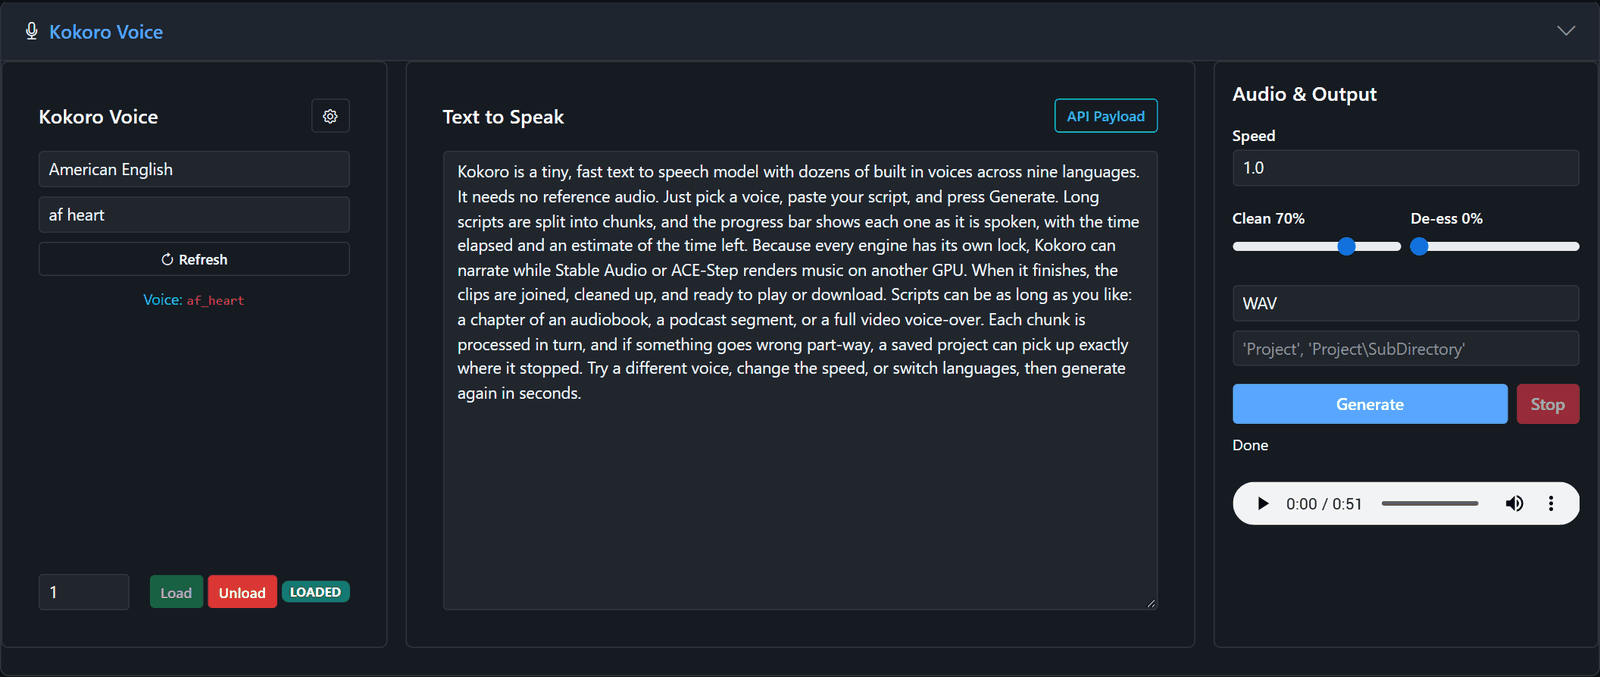
| Setting | Default | Guidance |
|---|---|---|
| Speed | 1.0 (0.5–2.0) | Kokoro handles speed well; 1.1–1.4 suits narration. Above ~1.7 voices get chipmunky. |
| Creativity (temperature) | 0.7 | Variation in delivery. |
| Diversity (top P) | 0.9 | |
| Verify with Whisper | on | Turn off for maximum speed. Kokoro rarely garbles text. |
| Clean / De-ess | 70% / 0% | Post-processing shared with the other engines. |
- Kokoro is ideal for previewing a script before rendering it with a slower cloning engine.
- It can narrate while a music engine renders on another GPU; see Concurrency & Progress.
- Rare words or names may be mispronounced. Spell them phonetically (e.g. "Nguyen" → "Win").
curl -X POST http://127.0.0.1:5006/kokoro_infer -H "Content-Type: application/json" -d "{\"text\": \"Hello from Kokoro.\", \"voice\": \"af_heart\", \"kokoroDeviceSelect\": \"cpu\"}"GET /kokoro_voices lists every voice by language. More in API Reference and chapter 7 of the manual.