Repository navigation
XTTS Voice Cloning
XTTS-v2 (Coqui) clones a voice from a few seconds of reference audio and speaks 17 languages. It also ships 58 built-in speakers if you don't have a reference clip. It's the most versatile speech engine in LocalSoundsAPI: good quality, reasonable speed, about 2 GB of VRAM.
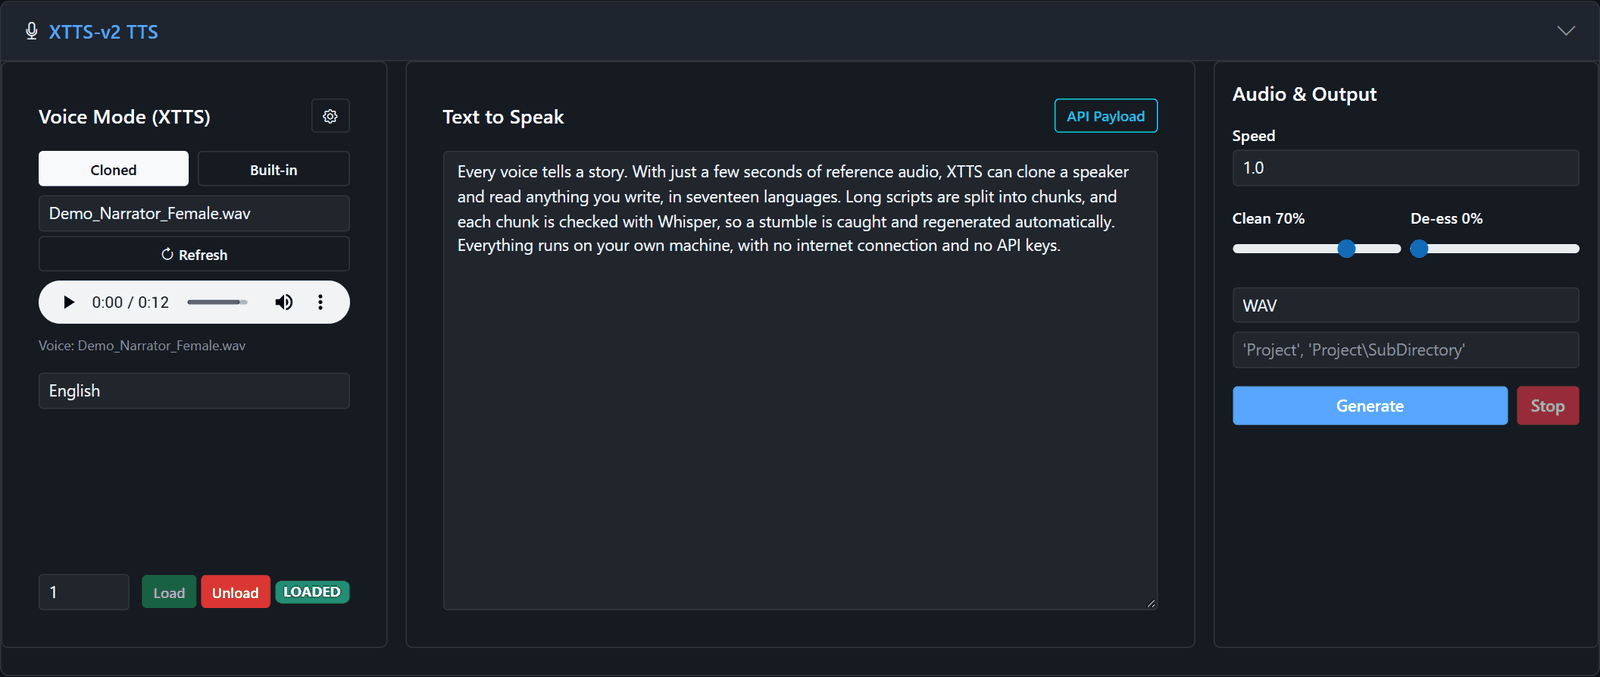
Use XTTS when you want a specific voice (cloned), several languages, or a big library of ready-made speakers. Prefer Fish Speech for maximum cloning quality, or Kokoro for raw speed.
🔊 Listen: XTTS cloned-voice sample
- Load the model. Pick a device at the bottom of the left column (a GPU is recommended) and click Load. Wait for LOADED. The first load downloads the model (~2 GB).
-
Choose a voice mode:
-
Cloned: uses a reference clip from
voices/. Add clips in Upload & Transcribe, then click Refresh. A player lets you preview the reference. - Built-in: pick one of the 58 included speakers.
-
Cloned: uses a reference clip from
- Pick the language of your text.
- Type or paste your text in the center column. Long text is split into chunks automatically.
- (Optional) Open the ⚙ gear for inference settings (below).
- Set the output: speed, Clean, De-ess, format (WAV/FLAC/MP3/OGG/M4A) and an optional save path.
- Click Generate.
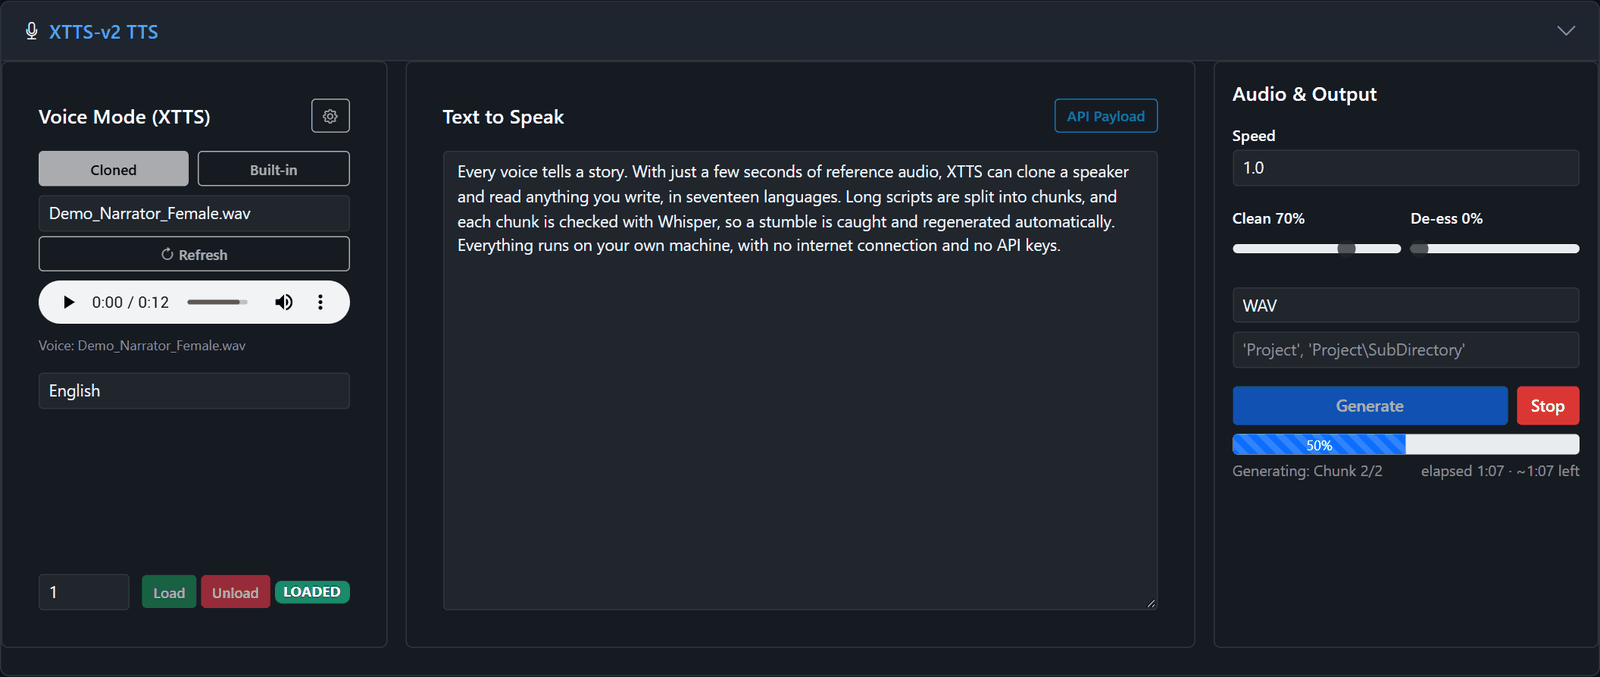
While it runs, the panel locks and shows the chunk being generated, elapsed time and an ETA:
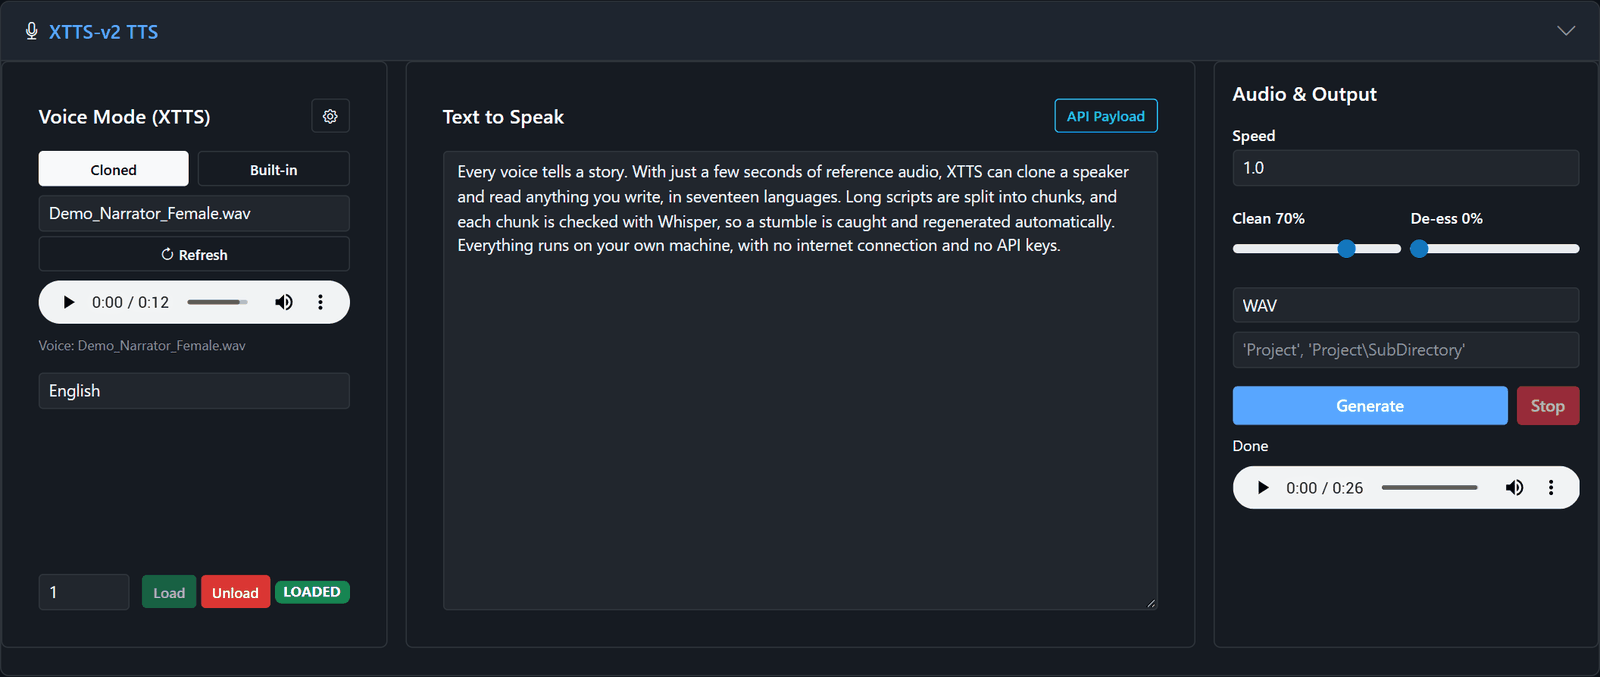
When it's done, play the result or download it:
| Setting | Default | Guidance |
|---|---|---|
| Temperature | 0.65 | 0.65–0.75 sounds natural. Higher is more expressive but may slur. |
| Repetition penalty | 2.1 | Raise it (4–6) if long paragraphs loop or stutter. |
| Verify with Whisper | on | Each chunk is transcribed and compared to your text; failed chunks are regenerated. |
| Accuracy tolerance | 80% | Minimum Whisper similarity (70–98%) to accept a chunk. 80–85% is a good balance. |
| Speed | 1.0 | Pitch-corrected with RubberBand. 0.9–1.2 stays natural. |
| Clean | 70% | Removes room reverb/echo. 50–80% for most voices. |
| De-ess | 0% | Raise only if "s" sounds are harsh. |
- Use 6–15 seconds of clean speech: one speaker, no music, no background noise.
- Avoid heavy reverb; the clone copies the room as well as the voice.
- A natural, mid-paced read clones better than shouting or whispering.
- Keep a few takes of the same voice and try each; results vary between clips.
With a save path set, progress is written to projects_output/<name>/job.json. If a job stops part-way, enter ##recover## as the text, keep the same save path and click Generate. Only the unfinished chunks are generated again.
The API Payload button shows the exact request. A minimal call:
curl -X POST http://127.0.0.1:5006/infer -H "Content-Type: application/json" -d "{\"text\": \"Hello from XTTS.\", \"mode\": \"builtin\", \"voice\": \"Aaron Dreschner\", \"language\": \"en\"}"Load the model first with POST /load and {"device": "0"}. More in API Reference and chapter 5 of the manual.