Repository navigation
Query Retrieval Based Question Answering
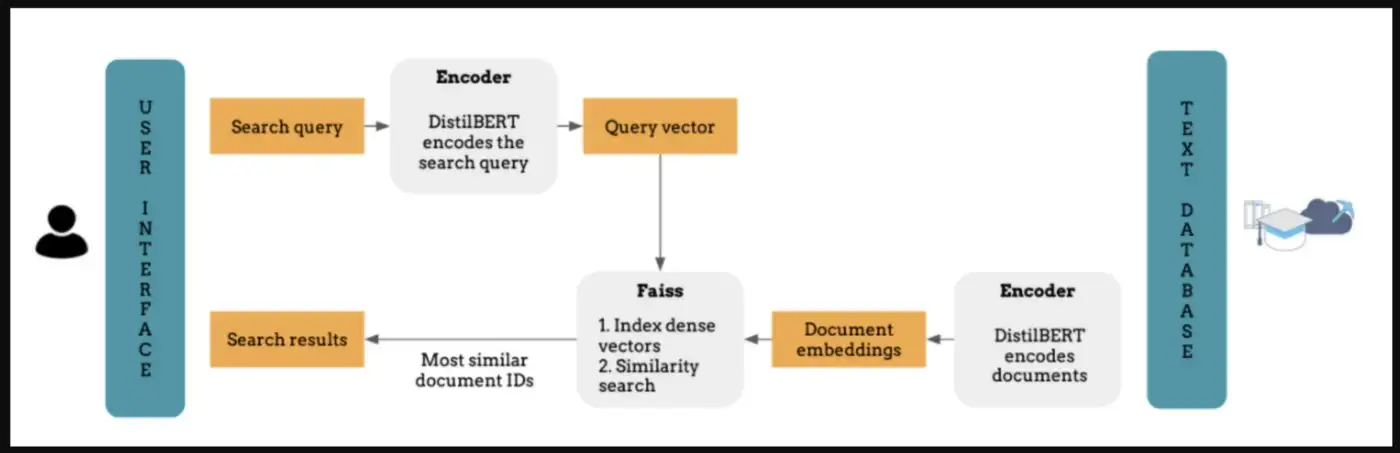
Given a database of frequently asked Question Answers, map the input query with the most relevant Question in the database and fetch the answer.
- Encode all the questions using a Bert Variation Model. (Use msmarco-distilbert-base-dot-prod-v3 for large queries and distilbert-base-nli-stsb-mean-tokens for small queries). This Bert model has been trained to bring similar queries close to each other and dissimilar queries far from each other. There when we encode the query using this model, they are semantically closer to similar queries or documents which are present in the database. Model Details
- Index the encoded documents using Faiss or Elastic Search for getting similarity score b/w query vector and the encoded documents.
- Given an input query, encode the query using model mentioned above, and find the most similar question from faiss indexed database. Map the question with its answer.
To finetune the distilbert model on our own dataset, we need sample generated queries from a given document so that they serve as a pair while training the model. So, first we have to generate synthetic queries for the documents and then use them to finetune the network.
For generating synthetic, a T5 Transformer has been used to generate 5 queries per paragraph or document.
The distilbert model is finetuned using the queries generated above.