Repository navigation
Architecture
📖 loopsmith's documentation lives at bitphill.github.io/loopsmith → This wiki mirrors it so existing links keep working.
← Wiki home · Rendered viewer with search
The design rests on one finding, and the whole structure exists to enforce it:
A model must not be the thing that certifies its own completion.
So goal_satisfied is written by a deterministic Rust gate and by nothing
else. No prompt, no confident summary, and no model that likes its own work can
set it. The gate can also revoke — delete a required artefact and a
previously satisfied goal flips back. A system that can only promote is a
burndown chart with extra steps.
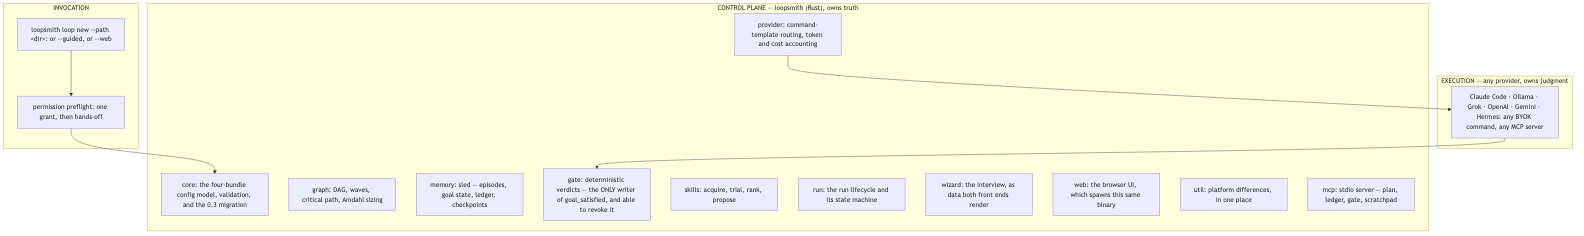
The same thing in text, which is what the rest of the documentation uses —
both are rendered from assets/architecture.mmd:
INVOCATION
  ├─ loopsmith loop new --path <dir>  or --guided, or --web
  └─ permission preflight             one grant, then hands-off
       │
CONTROL PLANE — loopsmith (Rust), owns truth
  ├─ core      the four-bundle config model, validation, and the 0.3 migration
  ├─ graph     DAG, waves, critical path, Amdahl sizing
  ├─ memory    sled — episodes, goal state, ledger, checkpoints
  ├─ gate      deterministic verdicts — the ONLY writer of goal_satisfied, and able to revoke it
  ├─ provider  command-template routing, token and cost accounting
  ├─ skills    acquire, trial, rank, propose
  ├─ run       the run lifecycle and its state machine
  ├─ wizard    the interview, as data both front ends render
  ├─ web       the browser UI, which spawns this same binary
  ├─ util      platform differences, in one place
  └─ mcp       stdio server — plan, ledger, gate, scratchpad
       │
EXECUTION — any provider, owns judgment
     Claude Code · Ollama · Grok · OpenAI · Gemini · Hermes  any BYOK command, any MCP server
The orchestrator is a binary rather than a chat session because a loop has to survive a crash, a schedule boundary, and a budget ceiling. Sessions are ephemeral and have no resume; a sled ledger does. Coordination is also a solved deterministic problem — spending model tokens on scheduling is the same mistake as spending frontier reasoning on entity extraction.
The guided terminal wizard, the browser UI, and the raw subcommands all produce
the same LoopConfig, parsed by one serde model, checked by one
validator, and executed by one runtime. There is no second schema and no
privileged path.
Two things hold that together rather than leaving it to discipline:
-
The wizard is data.
loopsmith-wizardpublishes every question, its wording, its order, its default and its validator. The terminal walks that spec and the browser fetches it from/api/wizard/spec. Neither can ask a question the other does not. -
The browser spawns this binary.
loopsmith-webdoes not link the engine. Every action in the UI is a subprocess running a command from a closed list, so the UI cannot drift from the CLI and cannot do anythingloopsmith --helpdoes not list.
Created → Validating → Planning → [AwaitingApproval] → Running
Running ⇄ Retrying
Running → { Paused | Blocked | Escalated | RolledBack | Failed | Succeeded } → Closed
Validating / AwaitingApproval → { Failed | Paused | Blocked | Escalated }
Closed → Validating                                          (resume)
Retrying is a detour inside an iteration, not an outcome, so it returns to
Running rather than closing. The extra edges out of Validating and
AwaitingApproval are where entry and approval gates halt a run before its
first dispatch. run/state.rs is the only place a transition is legal — every
other module asks it to move — and the current state is persisted in the sled
checkpoint, so loopsmith run status answers after a crash.
Detectors, strongest first:
| Type | Decides by |
|---|---|
script |
Exit code — prefer this |
file_exists |
Path present, optionally non-empty |
regex_match |
Pattern against a named artefact |
threshold |
Reported metric versus a number |
judge |
A model verdict against a named external standard |
judge is the weakest rung and the runtime treats it accordingly: a verdict
produced by the same provider as the work it judges is refused, not
discounted.
[FAIL] prose — judgment refused: judge and builder both ran on `claude`;
       a shared provider shares its blind spots
Every goal needs at least one blocking check, or the config is rejected. A goal you cannot check is a goal the loop can never honestly finish.
Verifier satisfied · iteration cap · budget ceiling (tokens, cost, wall-clock) · no measurable progress. All evaluated every iteration, all hard logic. "Stop when it's good enough" inside a prompt is a suggestion a model will eventually talk itself past.
Every trigger is written to the ledger, not just successes — a node that hits its ceiling constantly is telling you its judge is miscalibrated, and that signal is invisible if you only record completions.
1.0 adds three more kinds of gate beside the stop gates: entry gates checked once before the first dispatch, approval gates checked after planning so the plan is on the table when a person decides, and rollback gates checked every iteration that undo the iteration that tripped them.
loopsmith loop plan derives the parallel fraction from the graph itself and
sizes the fleet by arithmetic instead of optimism:
Waves (3 total):
   1. survey
   2. refactor-a, refactor-b
   3. review

Critical path (5.0 cost): survey -> refactor-a -> review
Parallel fraction p: 0.375
Concurrency chosen:  2
Predicted speedup:   1.23x  (ceiling 1.60x at infinite workers)
Amdahl's law is the cap and the critical path is the floor. At p=0.95, sixteen
workers buy ×9.14 — not ×16. auto mode adds workers only while the next one
still buys a configurable slice of additional speedup, then stops.
The question that builds a graph: on every "and then", does the next step actually read the previous step's output? Yes is a real edge. No was never an edge — run them together, and cut a false edge rather than adding a worker.
Parallel writers need separate file state as well as separate context. Per-node
isolation gives a node the loop directory (none), its own git worktree
(worktree), or a container over that worktree (container). A host with no
Docker degrades to worktree with a warning rather than failing, because a
config is checked out on laptops, CI runners and servers.
Every provider is a command template, which is what makes BYOK free: if you can run it from a shell, loopsmith can route to it. Adding one is a config edit, never a rebuild.
execution:
  providers:
    providers:
      - id: ollama
        kind: ollama
        tiers: [cheap]
        command: ollama
        args: ["run", "{model}"]
        model: llama3
        prompt_on_stdin: true

      - id: openai
        kind: openai
        tiers: [strong]
        command: curl
        args: ["-sS", "https://api.openai.com/v1/chat/completions",
               "-H", "Authorization: Bearer $OPENAI_API_KEY", "-d", "@-"]
        requires_env: [OPENAI_API_KEY]
        prompt_on_stdin: true

    cascade:
      cheap:    [ollama, claude]
      standard: [claude, gemini]
      strong:   [openai, claude]
Supported kinds: claude_code, ollama, grok_cli, grok_build, hermes,
openai, gemini, byok, mcp. Common aliases (claude, grok, open_ai,
google_gemini, custom) are accepted, because a config that rejects openai
in favour of open_ai wastes your afternoon.
Pull an ollama model before the first run. ollama run <model> downloads
the model when it is not present, and from outside the process a 4.7 GB
download is indistinguishable from a slow generation. One real run spent its
entire timeout pulling llama3 and produced nothing. The starter ollama
provider therefore has timeout_seconds: 120 — short enough that the cascade
abandons it and moves on rather than waiting out a download.
Secrets never enter the process. requires_env names keys that must be
present; values are never read, substituted into arguments, or written to the
ledger. Let the command expand them itself, as curl does above.
$ loopsmith providers loop.yaml
claude       available    claude
ollama       available    ollama
openai       unavailable  missing env: OPENAI_API_KEY
gemini       unavailable  command not found on PATH; missing env: GEMINI_API_KEY
Cheap tiers carry mechanical, high-volume work; strong tiers carry judgment. Spending frontier reasoning on extraction is where loop budgets die.
Spend accounting. Set usage_regex to pull a real token count out of a
provider's output and cost_per_1k_tokens to price it. Without a regex, usage
is estimated at roughly four characters per token and every report says so:
spend: 263 tokens (estimated: no provider reported usage), $0.0000
An approximate ceiling that fires beats an exact one that never does, which is what an unaccounted budget gate amounts to.
Five independently written sources on loop engineering converge on the same rule from different directions, and they form an escalation of trust:
- Separate prompt — weakest. Same context, same blind spots.
- Separate context — a verifier that never saw the work being made.
- Separate model family — avoids characteristic blind spots.
- Separate mechanism — deterministic code decides. Strongest.
loopsmith-gate sits at rung 4. The reasoning is in
HOW-TO-USE §14,
which distils all twenty sources and records what was borrowed, what was
rejected, and why.
The MCP server makes the same point by omission: it exposes the plan, the ledger, the gate's verdict, and the scratchpad — and has no tool for marking a goal satisfied. There is a test asserting that absence, so removing the guarantee cannot happen quietly.
run start executes once. run watch is the process that keeps a loop alive:
loopsmith run watch loop.yaml              # until interrupted
loopsmith run watch loop.yaml --check      # show triggers, run nothing
loopsmith run schedule loop.yaml --install # survive a reboot (launchd / cron)
Triggers: cron (five fields, evaluated in UTC), interval
(timezone-independent, preferred for plain cadence), file_change, and
goal_satisfied. File and goal triggers fire on the edge, not the level, so
a satisfied goal does not retrigger forever, and the watcher ignores its own
state/ directory so the ledger's writes cannot retrigger it.
A failed run logs and the watcher continues. That difference — a crash ending one run instead of the whole schedule — is what separates a scheduler from a one-shot.
The loop discovers which sub-agents help rather than being told:
execution:
  skills:
    explore: true                                  # off by default; it spends money
    explore_candidates: [table-formatter, chart-maker]
    min_trials: 3
Each iteration attaches one under-trialled candidate to a builder, records the gate outcome that followed, and ranks by satisfaction rate. What correlates with satisfied goals becomes a proposal:
$ loopsmith skills scores loop.yaml
skill                         trials satisfied   mean pass  source
chart-maker                        3      100%       1.00  generated
table-formatter                    3       33%       0.42  generated

$ loopsmith run proposals loop.yaml run-1786861783335
[AdoptSkill] chart-maker (iteration 3)
  goals were satisfied in 100% of 3 trials using `chart-maker`; it is not in the config
  suggested: skills: [chart-maker]

Apply these by editing the config yourself. The loop cannot.
| The loop does, on its own | The loop only proposes |
|---|---|
| Acquire, install, or generate sub-agents (quarantined) | Goals |
| Trial candidates and score them against gate outcomes | Checks |
| Write scratchpad notes between iterations | Success scenarios |
| Which skills the config uses |
The loop cannot move its own goalposts, and cannot silently adopt a tool. A system that rewrites the criteria it is judged against cannot certify that it met them.
1.0 adds two more bounds. safety.protected names what a proposal may never
touch — the gates, the limits, the recovery policy, the credentials, the audit
trail — and a proposal that would rewrite one of them is refused before it is
evaluated. evolution.baseline records what the loop currently achieves, and a
proposal that regresses any of those numbers by more than
evolution.max_regression is refused by the gate rather than by a reviewer's
patience.
One lucky run is not evidence. Below min_trials, a candidate is recorded
and ignored.
Sub-agents are sourced installed → marketplace → generate, with trust
floors in runtime/crates/loopsmith-cli/templates/marketplaces.json. Names
matching credential-shaped patterns are never auto-installed regardless of star
count — popularity is not trust. Everything acquired lands in
generated-skills/ until a human promotes it, because an acquired sub-agent
runs with whatever your permission grant allowed.
loops/
├── README.md                          the short version
├── README-FOR-DUMMIES.md              the start-here version
├── HOW-TO-USE.md                      section-by-section reference
├── LOOP-TEMPLATE.md                   the fill-in authoring template
├── assets/                            logo and architecture diagram
├── site/                              the gh-pages landing page
├── wiki/                              the hand-written wiki pages, including this one
├── installers/                        one manifest, three install scripts
├── skills/
│   ├── loopsmith/                     user-invoked runner
│   └── loopsmith-reference/           model-invoked design reference
├── config/
│   ├── loop.schema.json               generated from the Rust model, never hand-edited
│   ├── marketplaces.json              acquisition sources + trust floors
│   ├── permissions.template.json      shape of the consolidated grant
│   ├── mcp.template.json              MCP registration
│   └── examples/                      one worked loop per row of the table
└── runtime/
    └── crates/
        ├── loopsmith-core             config model, validation, migration
        ├── loopsmith-memory           Store trait + sled backend
        ├── loopsmith-graph            DAG, waves, critical path, Amdahl
        ├── loopsmith-gate             deterministic verdicts
        ├── loopsmith-provider         command-template routing + usage accounting
        ├── loopsmith-skills           acquisition, marketplace, outcome ranking
        ├── loopsmith-run              the run lifecycle and its state machine
        ├── loopsmith-wizard           the interview, as data
        ├── loopsmith-web              the browser UI (axum; spawns this binary)
        ├── loopsmith-util             platform differences, in one place
        ├── loopsmith-mcp              stdio MCP server
        └── loopsmith-cli              the binary: clap, dispatch, scaffold, doctor
sled is shipped but sits behind a Store trait — it is effectively frozen
upstream, and the trait means a swap to redb never reaches callers.
export PATH="$HOME/.cargo/bin:$PATH"
cd runtime && cargo test --workspace
No warnings, and cargo clippy --workspace --all-targets -- -D warnings is
clean. Tests are named as sentences describing the guarantee they pin. The ones
worth knowing about:
-
the_gate_can_take_done_back— satisfied flips to unsatisfied when the artefact disappears -
judge_on_the_builders_provider_is_refused— self-judgment cannot satisfy the gate -
a_missing_judgment_fails_closed/a_missing_metric_fails_rather_than_passes_by_default -
there_is_no_tool_for_declaring_a_goal_satisfied— guards the MCP surface -
amdahl_matches_the_published_table— the sizing arithmetic -
checkpoint_survives_reopen— resume after a crash an_unsatisfiable_loop_stops_on_no_progress_not_on_success-
a_bare_pass_without_evidence_is_demoted_to_fail— a verdict with no evidence is an assertion -
independent_nodes_in_a_wave_run_concurrently— timed, not asserted by inspection -
two_nodes_get_separate_directories— worktree isolation actually isolates -
one_lucky_run_is_not_evidence— a single trial cannot drive a config change -
a_high_star_credential_grabber_is_still_excluded— popularity is not trust a_cron_trigger_fires_once_per_minute_not_once_per_pollthe_watcher_ignores_its_own_state_directory-
the_browser_never_asks_for_a_spelling_that_moved— the web UI and the CLI grammar, checked against each other -
the_run_log_is_a_format_the_web_can_read— the run's writer and the browser's reader, checked against each other