Repository navigation
Can't obtain excellent voice-cloning results with any TTS model #2105


|
I have tried finetuning different TTS models to voice-clone custom voice following different community guides. But the results are far less impressive than what can be done in the coqui app with only one voice sample. Is there any available information on the methods or models used under the hood? Would be very thankful for any suggestions on how can I achieve the same results. |
Replies: 4 comments 3 replies

|
How long did you train? How much data did you use for finetuning? can you share your config file and tensorboard logs here. |

|
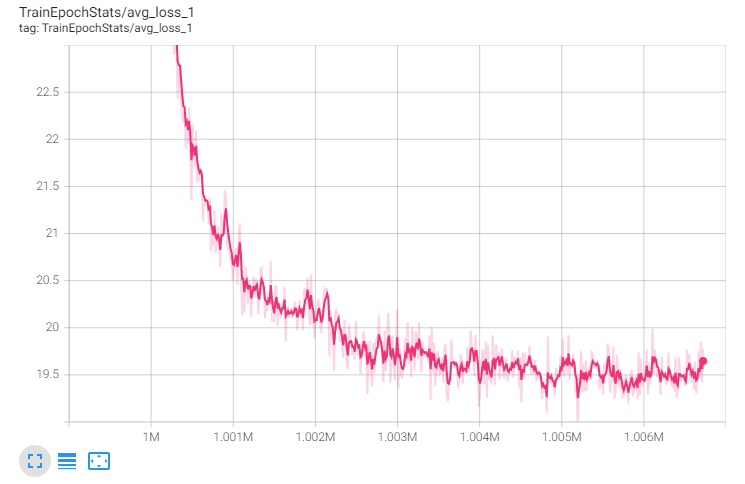
This was my best run probably |

|
I don't know about what the image you posted contains since I'm blind, but in my opinion 7k steps is not good. |
|
The image contains an average loss 1 graph and it looks like it plateaued on value 19.5 after 5k steps. |
|
That's not really so much cloning your voice as trying to replicate it using a speaker embedding with a well trained multi speaker model based on the sample you give it. The final result will not give you a completely similar voice, but if you train a voice based on a really good dataset and for longer times it will sound exactly like that person's voice, since it's not replicating the voice by turning its parameters into numeric values, but learning from it directly. The name of the model you mentioned is called your tts. Experienced people, please correct me if I'm wrong |
|
Thank you so much, Your TTS looks interesting and promising |
|
No prob, bro/sir/fello person/whatever you like calling yourself lol |


That's not really so much cloning your voice as trying to replicate it using a speaker embedding with a well trained multi speaker model based on the sample you give it. The final result will not give you a completely similar voice, but if you train a voice based on a really good dataset and for longer times it will sound exactly like that person's voice, since it's not replicating the voice by turning its parameters into numeric values, but learning from it directly. The name of the model you mentioned is called your tts. Experienced people, please correct me if I'm wrong