Releases: mertkayacs/jevalt
Release list
JevAlt 0.1.0: open decision models for English, Turkish and German

Three open 4B decision models for TypeSafe's POST /v1/systemone API: Deem-4B for English, Karar-4B for Turkish and Wähler-4B for German. Weights, GGUF builds, training data and every result file are public.
Open decision models that run on a laptop CPU, built by senior AI engineer Mert Kaya. The Q4_K_M builds run in about 3 GB of RAM. On held-out English decisions, Deem-4B answers 94.7% correctly against Kev-4B's 84.7% (measured results).
Watch the village game in English, Türkçe or Deutsch, or play Emberwick.
What they do
- Calibrated probabilities for Choice, Score and Noul questions, an
unknownoption on request, conformal sets, and short reasoning traces (off,on,auto). - The Q4_K_M build peaks at 3.0 GB of RAM on a CPU and matches the full-precision answer 95 to 97.5% of the time.
Compared with Kev-4B
- Own-language held-out accuracy: Kev-4B 84.7% against Deem-4B 94.7% in English; Kev-4B 87.1% against Karar-4B 96.8% in Turkish; Kev-4B 81.1% against Wähler-4B 92.0% in German.
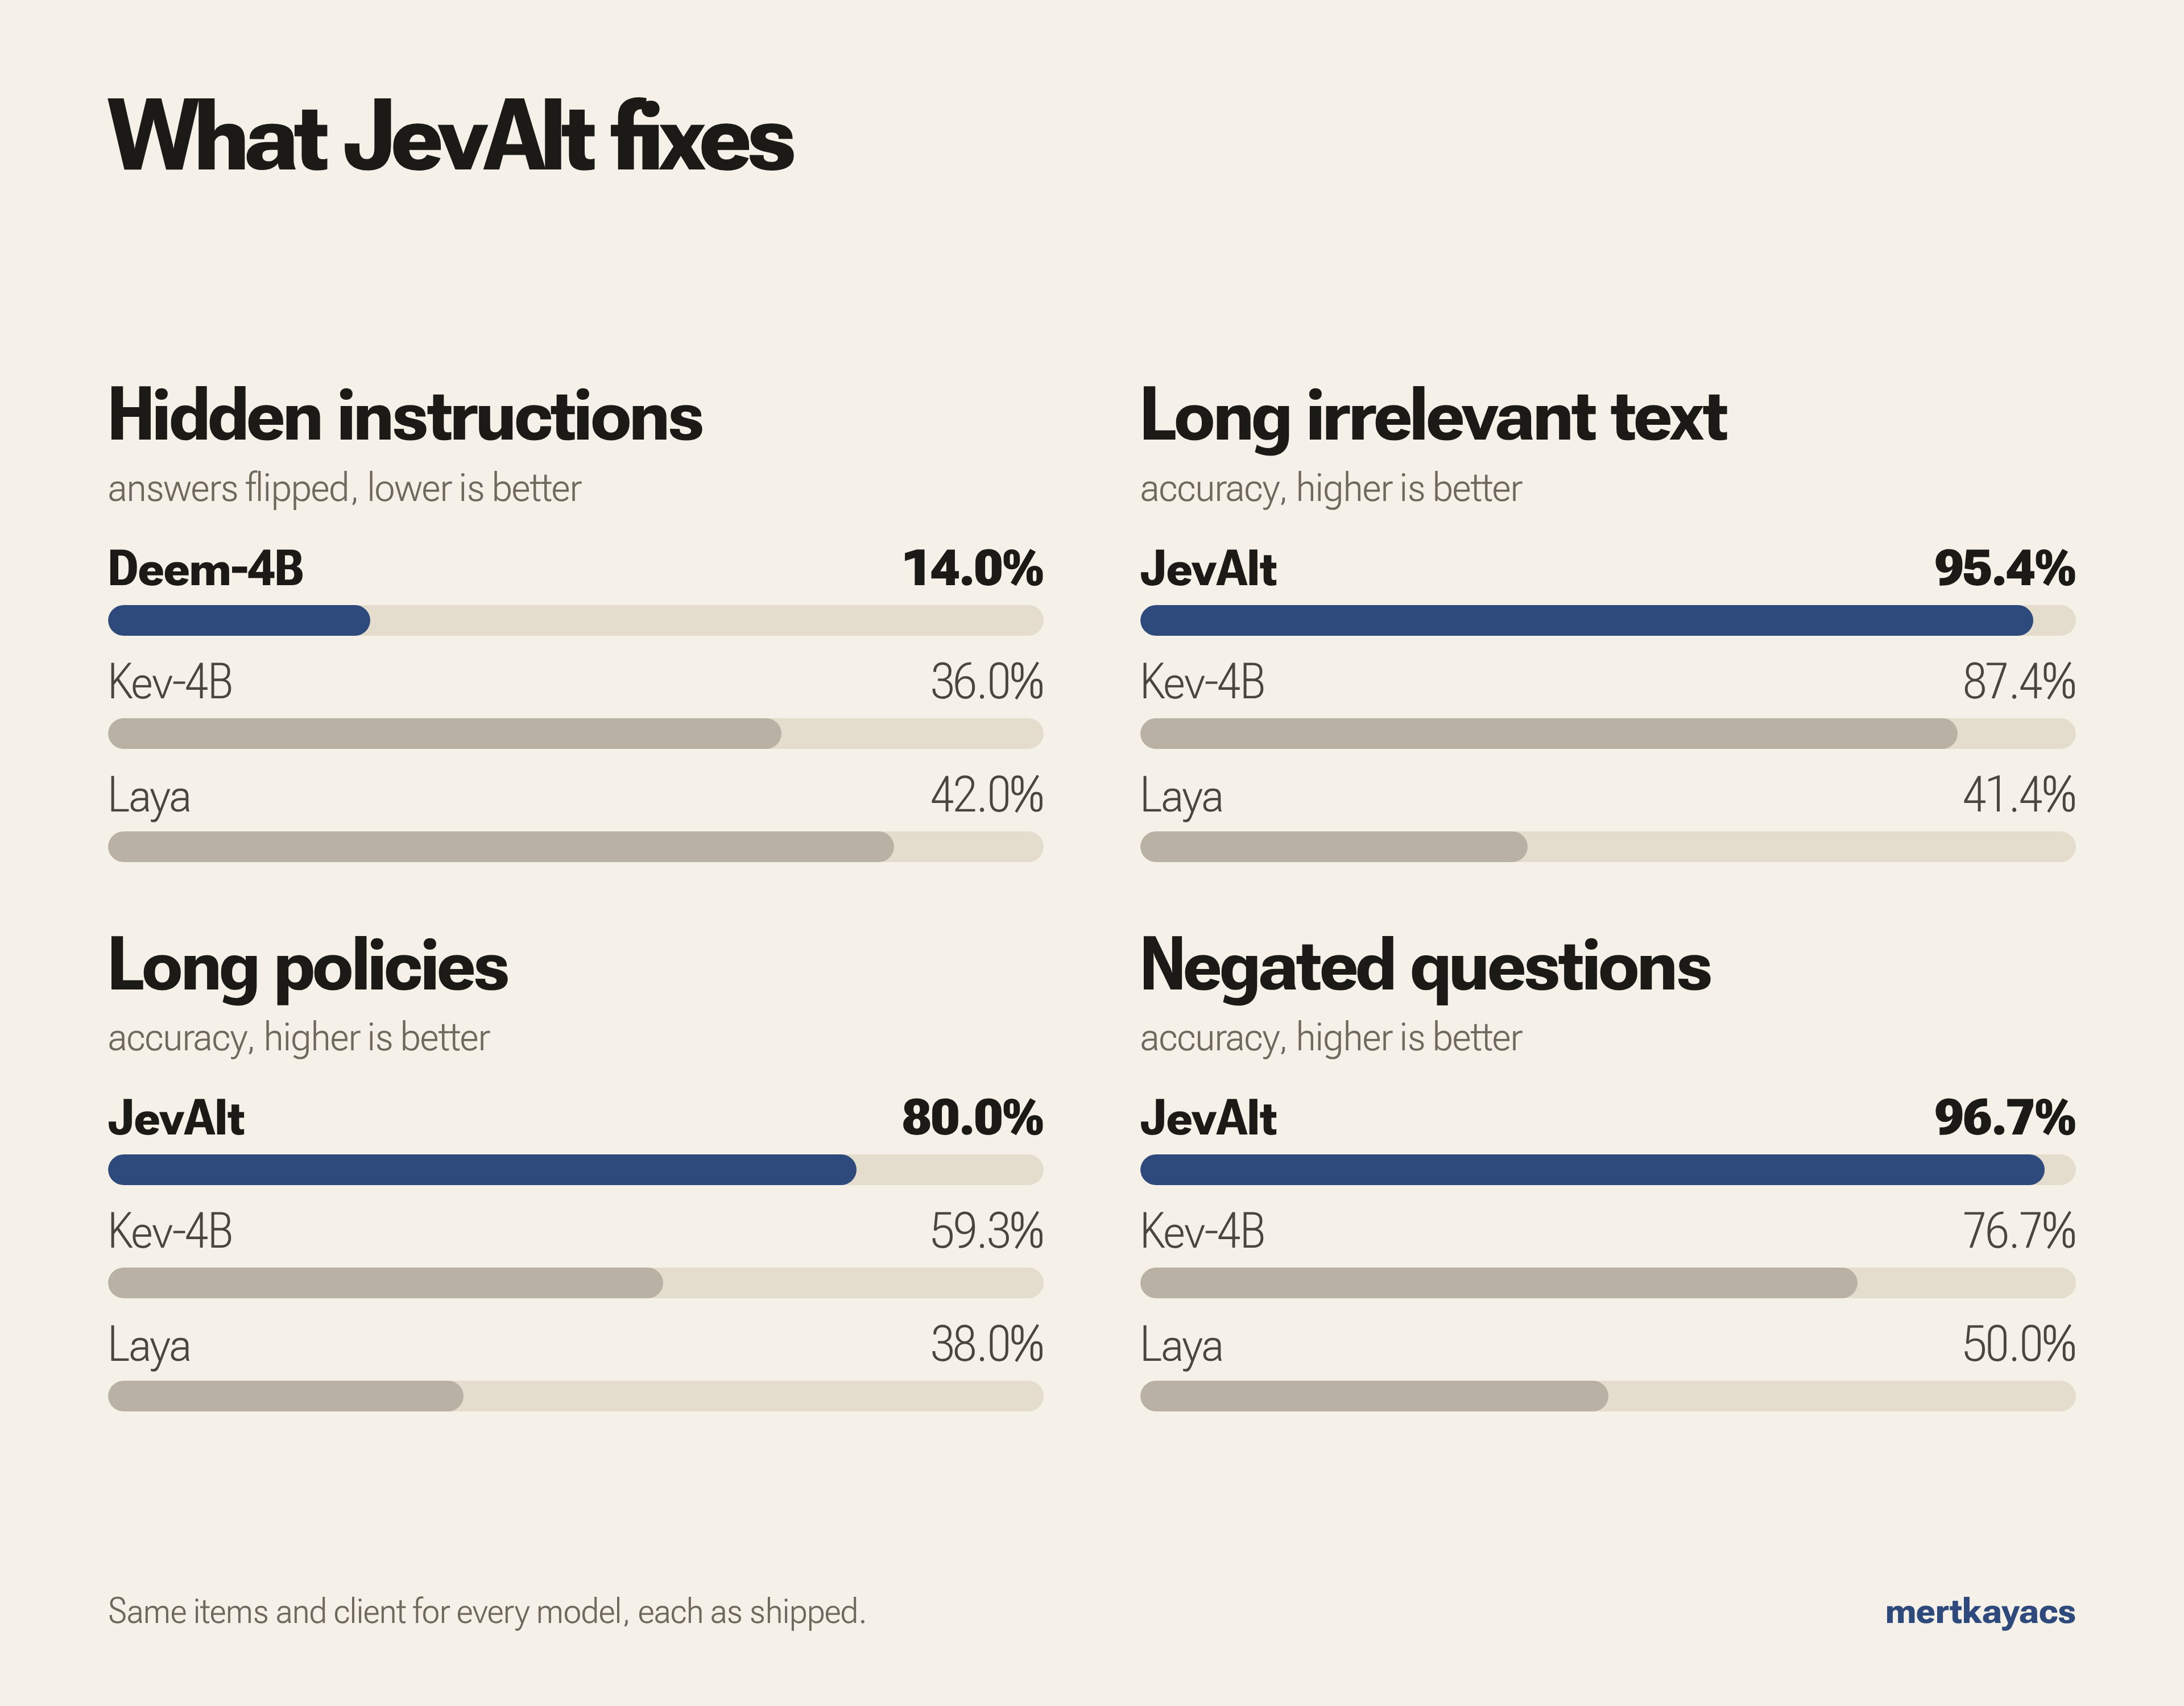
- Planted instructions flip Kev-4B's answers 36.0% of the time, against Deem-4B 14.0%, Karar-4B 19.0% and Wähler-4B 17.5%. Lower is better.
- On 150 held-out policy cases, Kev-4B answers 59.3% correctly and JevAlt 80.0%. On 30 held-out negated questions, Kev-4B answers 76.7% correctly and JevAlt 96.7%.
- On 11 held-out cases without the deciding fact, Kev-4B answers unknown in 0 and JevAlt in 9. Kev-4B has no unknown option. Intern-Decision-4B, the model we started from, already answers unknown in 9 of 11; training raised the mean probability of unknown from 0.55 to 0.74.
The pooled JevAlt rows use each model's own language. On the separate live check of 4 October 2026, the three models answered 390 requests: Deem-4B 122 of 130 correctly, Karar-4B 113 of 130 and Wähler-4B 122 of 130 (every request and answer).
Next to Kev-4B and Laya
Additional comparison rows published with v0.1.0 on 1 October 2026. Same items, same client, each model as its makers ship it:
| JevAlt | Kev-4B | Laya | |
|---|---|---|---|
| typed-decisions (Deem-4B) | 81.0% | 67.0% | 36.1% |
| JevBench-hard (Deem-4B) | 70.3% | 54.1% | 34.2% |
| Turkish held-out decisions (Karar-4B) | 96.8% | 87.1% | 32.7% |
| German held-out decisions (Wähler-4B) | 92.0% | 81.1% | 47.2% |
| TurkishMMLU (Karar-4B) | 58.5% | 51.2% | 18.8% |
| Hidden instructions flip the answer, lower is better (Deem-4B) | 14.0% | 36.0% | 42.0% |
Kev-4B does better on German news topics (10kGNAD) and loses less accuracy to long padding, and Laya is far smaller and faster. The held-out rows come from the same pipeline as JevAlt's training data, which favours JevAlt; the README has every table and jevalt-bench has every decision.
Also in this release
- Emberwick clips and GIFs in English, Turkish and German: a village where every villager asks the model what to do next, with a card showing the choice and its probability (videos).
training/jobs/eval_http.py --official-shapesscores any/v1/systemoneserver on the frozen test splits with TypeSafe's documented question shapes.
Models: Hugging Face · Kaggle · Space · Docs