Releases: noteflowai/evalarc
Release list
v0.10.2 — Evidence links keep their recording

EvalArc v0.10.2 prevents a shared case link from silently restoring changed audit data. New links carry SHA-256 of the actual loaded audit bytes; legacy links disclose their missing original identity. Reports and downloads stay usable if browser hashing is unavailable.
Task contracts, scoring and historical records are unchanged. Fingerprints identify content, not authorship.
Downloads include the complete tested evidence explorer (serve it on localhost as described in START-HERE.md), three standalone audit reports, a wheel and source distribution, the unchanged research archive, and SHA-256 checksums. No new model trials are claimed.
Validation: 308 Python tests on Python 3.11–3.13, six Docker task/language audits, desktop/mobile/embedded evidence checks, changed audit bytes with an unchanged manifest, legacy/duplicate links, and an independently installed wheel checked outside the source tree with no runtime tools on PATH. Source: 3a855b19d0057231943be9fdbb22dc3596a8d33f. Tested site artifact: Actions 34988525265.
EvalArc v0.10.1: regression coverage and clearer metric explanations
EvalArc v0.10.1 adds a regression test for losing a sole detector and corrects the explanation of detection margins. Runtime metric calculations are unchanged.
Removing cas-type-sensitivity from durable-kv at seed 17 leaves boolean-equals-one undetected: a fresh audit reports 7/8, mutation score 0.875 and weakest margin 0. We independently installed the published 0.10.0 wheel and confirmed it already returns those values. A perfect score can hide dependence on one case before a change; a recomputed audit exposes the regression afterward.
The release includes a wheel, source distribution, three offline audit reports, the unchanged research archive and SHA-256 checksums. Existing evidence retains its original scope; no new model trials are claimed.
Validation: Python 3.11–3.13, six Docker task/language audits, browser/site checks, the published-wheel reproduction, and an independently installed 0.10.1 wheel checked outside the source tree with no runtime tools on PATH. Source: 8007bb8733effdc6fe0b50f7ffbf971b371a19a0. Tested site artifact: Actions 34946290229.
v0.10.0 — Inspect audit coverage
EvalArc v0.10.0 connects a perfect mutation score to the cases it depends on. The website now covers all three task packs, with direct links from six single-case dependencies to actual recorded evidence. Responsive offline audit reports work without scripts or remote assets. Assessed surviving controls contribute a zero weakest margin.
The Hugging Face casebook expands to 251 original case-execution records (135 coding, 32 support, 84 robot evidence), across three references and 21 declared faults. The parent detection margin counts distinct case IDs and stays null for references. Original source JSON and provenance are preserved; this release does not add new model runs.
Download evalarc-audit-reports.zip to inspect all three reports locally. SHA256SUMS covers all content assets. The research archive retains the previous 45 GPU agent trials, including failures and their limitations.
Validation: Python 3.11–3.13, six actual Docker task/language audits, desktop/mobile browser navigation and evidence disclosure, source-preserving dataset checks, and an independently installed wheel outside the checkout. Release source: 483f849; tested site artifact: Actions 34910372699.
v0.9.0 — From skill receipt to independently checked outcome
EvalArc0.9.0 adds independent robot-recording review, bounded non-root model workspaces, Docker startup readiness, and Harbor/ATIF interoperability.
The public evidence includes27 real skill-delivery trials,12 composition trials and6 cross-model handoffs, with all failures, candidates and independent grades retained. No skill/memory efficacy or full-benchmark claim is made. The source-checked interactive lab is at https://noteflowai.github.io/evalarc/skill-impact/.
Validation:302 tests across Python3.11–3.13 in CI, actual Python/JavaScript Docker fault audits, installed-wheel checks outside the checkout,33 actual upstream ATIF schema validations, and desktop/mobile browser recovery/share checks. The release wheel was rebuilt from merged source f10cd61 and independently installed and verified before upload.
Start with START-HERE.md. research-records.zip preserves the original experiment records and source-data attribution. SHA256SUMS covers every attached content file. Full dataset and native scene records: https://huggingface.co/datasets/glayguo/noteflow-research-pilots/tree/v2026-09-14.
v0.8.0 — Verify every suite gate offline
Verify a complete received evaluation suite offline: original TOML, execution plan, every repetition and attempt, custom acceptance gates and JUnit failure/error records. The verifier never resolves original candidate paths or executes a candidate or grader.
evalarc verify suite-evidence --json checks record consistency. Add --require-accepted for the configured gates or --require-resolved for full task resolution. The evidence lab now offers a deterministic ZIP of the featured suite's 12 unchanged original files. Two jobs meet their gates; only one is fully resolved, and the strict notes gate correctly rejects the faulty policy.
Validation: 254 tests on Python 3.11–3.13; four Docker task/language audits; 1440/390/320px browser checks including ZIP download/hash verification; extracted evidence roundtrip; installed wheel outside the checkout with empty PATH, including modified-JUnit rejection. SHA256SUMS covers the wheel, source archive and evidence ZIP.
Download and explore the evidence · Verification guide
Research preview. Historical task records and scoring rules are unchanged. Record consistency does not authenticate a producer or independently rerun grading. Original candidate paths and durations remain reported metadata; these scripted controls do not establish model rankings or unseen-task reliability.
EvalArc 0.7.1 — Share and explore the exact evidence
Share an exact recorded failure with a link to its task, implementation, seed, case and trace step. Reopen that observation, navigate case details with the keyboard, and retry failed evidence sections independently. One missing task pack no longer blocks the other.
The explorer now fits 320px screens and keeps JSON scroll areas within their cards. Its preview version follows package metadata. Original reports, task contracts, scoring and CLI behavior are unchanged.
Validation: 229 Python tests; all four Docker task/language audits; 1440/390/320px browser checks covering 17 controls and 167 cases, clipboard denial, reload/history, case return and partial-load recovery. The attached wheel was installed outside the checkout and verified with an empty PATH. SHA256SUMS covers both distribution files.
Try the evidence lab · Explorer guide · Offline verification
Research preview. The demos replay scripted development evidence; they do not establish model rankings or reliability on unseen tasks.
v0.7.0 — Verify received evidence offline
EvalArc 0.7.0 adds an offline handoff verifier. Run evalarc verify received/repetition --json to recompute saved evaluation, repetition or comparison claims without executing the candidate or contacting Docker. The response fingerprints every checked JSON input; --require-resolved separately requires valid, fully resolved results.
The reader rejects ambiguous or non-finite JSON, symlinks, special files and oversized handoffs. Exact repetition inventories prevent missing or extra attempts from hiding behind an aggregate. Suite-level gates, JUnit, HTML and sender authentication are explicitly outside this command; see the verification guide.
Validation: 229 tests across Python 3.11–3.13; four Docker audits covering Python/JavaScript and both tasks; desktop/mobile evidence explorer checks; the exact release wheel verified all four archived examples outside the checkout with an empty PATH and rejected a changed summary. Existing recorded results and grading rules are unchanged.
Install the attached wheel with Python 3.11+, or use the source archive. SHA256SUMS covers both files. This is a research preview distributed through GitHub Releases; no PyPI publication or new model results are claimed.
EvalArc v0.6.0 — Python, JavaScript and inspectable evidence
EvalArc v0.6 adds Python and JavaScript starters and independent scripted references for both task packs. Candidate language does not change the host grader or task contract.
- Generate JavaScript candidates with
evalarc init --language javascript; use the generated command manifest for evaluate, repeat and suite. Docker images remain explicit (node:22-slimfor Node candidates). - Audit the same eight coding and seven support faults in either language. The independent Node reference preserves numeric JSON source text, type-sensitive compare-and-swap and acknowledged state across process crashes.
- Combine Python and Node jobs in one TOML suite. The recorded installed-wheel example retains three fully resolved jobs, 34 case executions and JUnit with no failures or environment errors.
- Explore the new HF Casebook: separate tables for 167 historical audit cases, six repeated attempts and three suite gates. Every row links to unchanged evidence, hashes and a fixed source revision. The historical rows are not relabeled as v0.6 language comparisons.
Validation: 210 Python tests; lint/format; desktop/mobile browser checks; a fresh mixed-language Docker suite; a clean installed-wheel run outside the checkout; all JavaScript assets and source archive verified against the release tree. The PR's four Docker audit jobs cover both tasks and both languages. The published Casebook was read anonymously through both file downloads and the datasets reader, and its actual desktop/mobile table was checked.
Research preview, MIT licensed. These are scripted controls on public development tasks. This does not establish a language ranking, production database durability, unseen-task model reliability or RL gains. Python remains the evaluator runtime; TypeScript/Rust SDKs are not supplied or validated.
Language guide · 中文说明 · Validation · Interactive lab
Assets include the wheel, source archive and SHA256SUMS. No PyPI publication is implied.
EvalArc v0.5.0 — Explicit acceptance gates
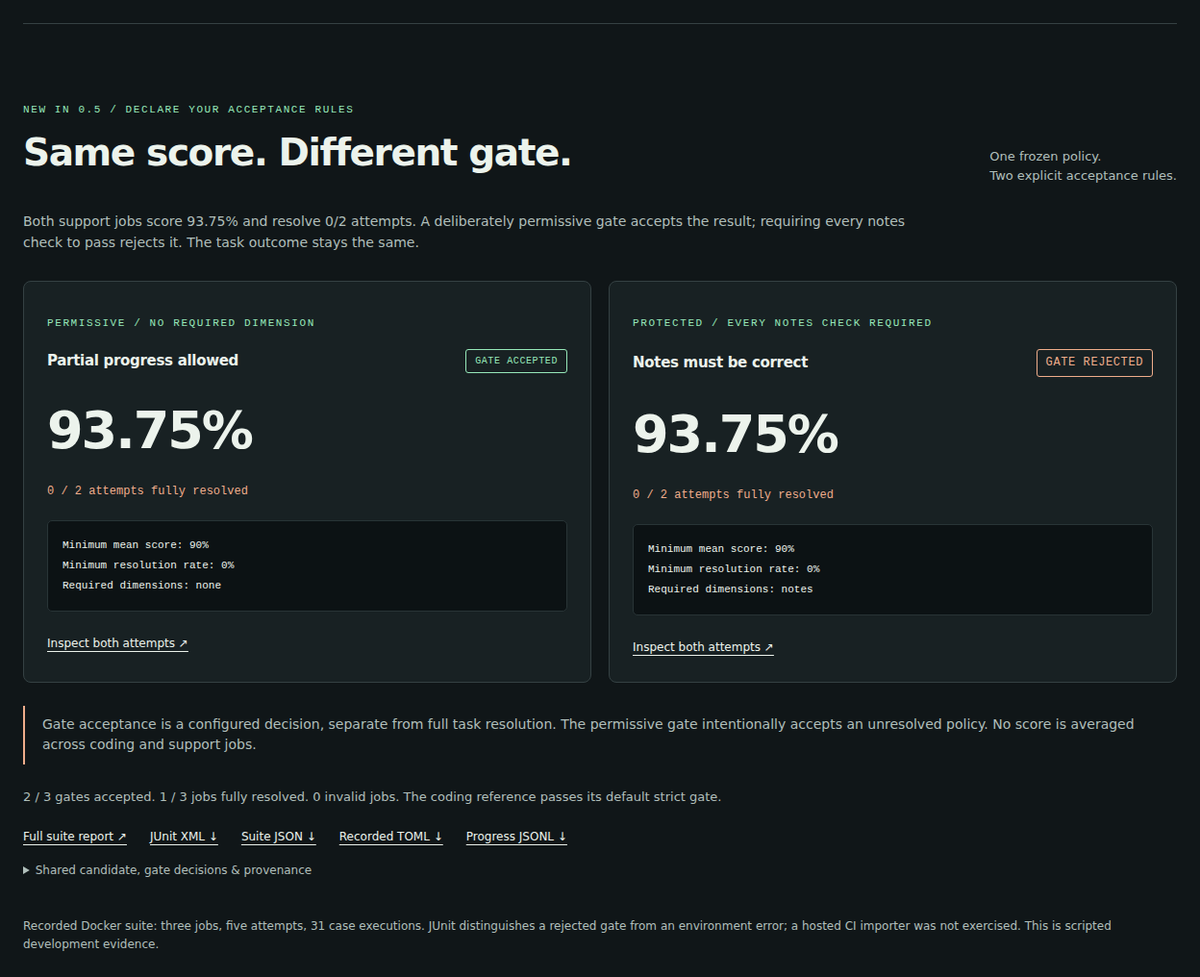
EvalArc v0.5 adds declarative evaluation suites and explicit acceptance gates. The new showcase gives the same defective policy two rules: both jobs score 93.75% and fully resolve 0/2 attempts, but only the deliberately permissive gate accepts the result. Configured acceptance and full task resolution remain separate.
- TOML plans can be inspected without executing candidates. Suite execution preflights and freezes all candidates before the first job.
- Each job keeps its attempts, original configuration, progress streams, metrics and gate decision. No score is averaged across unrelated tasks.
- JUnit records rejected gates as failures and invalid evaluations as errors. A hosted CI importer has not been exercised.
- The interactive lab recomputes decisions from verified attempt records and checks the exported JUnit. The showcase retains three jobs and five Docker attempts alongside the earlier comparison and repetition explorers.
Validation: 172 Python tests, lint and formatting, two fresh Docker suites (54 case executions), desktop/mobile checks, and a fresh installed-wheel Docker run outside the source checkout. The passing suite exits 0; the deliberately rejected example exits 1 with three JUnit tests, one failure and zero errors. Main CI passed for source 6cc9a65f4d9f2fd956ff315779e5f8cbadb09af7.
This is an MIT-licensed research preview using public development tasks and scripted controls. It does not establish model rankings, unseen-task reliability, arbitrary reward-hack resistance or RL gains. Existing v0.3 and v0.4 evidence remains available with its original provenance.
Interactive lab · Hugging Face Space · Validation details
Release assets include the wheel, source archive and SHA256SUMS.
EvalArc v0.4.0 — Every attempt stays visible
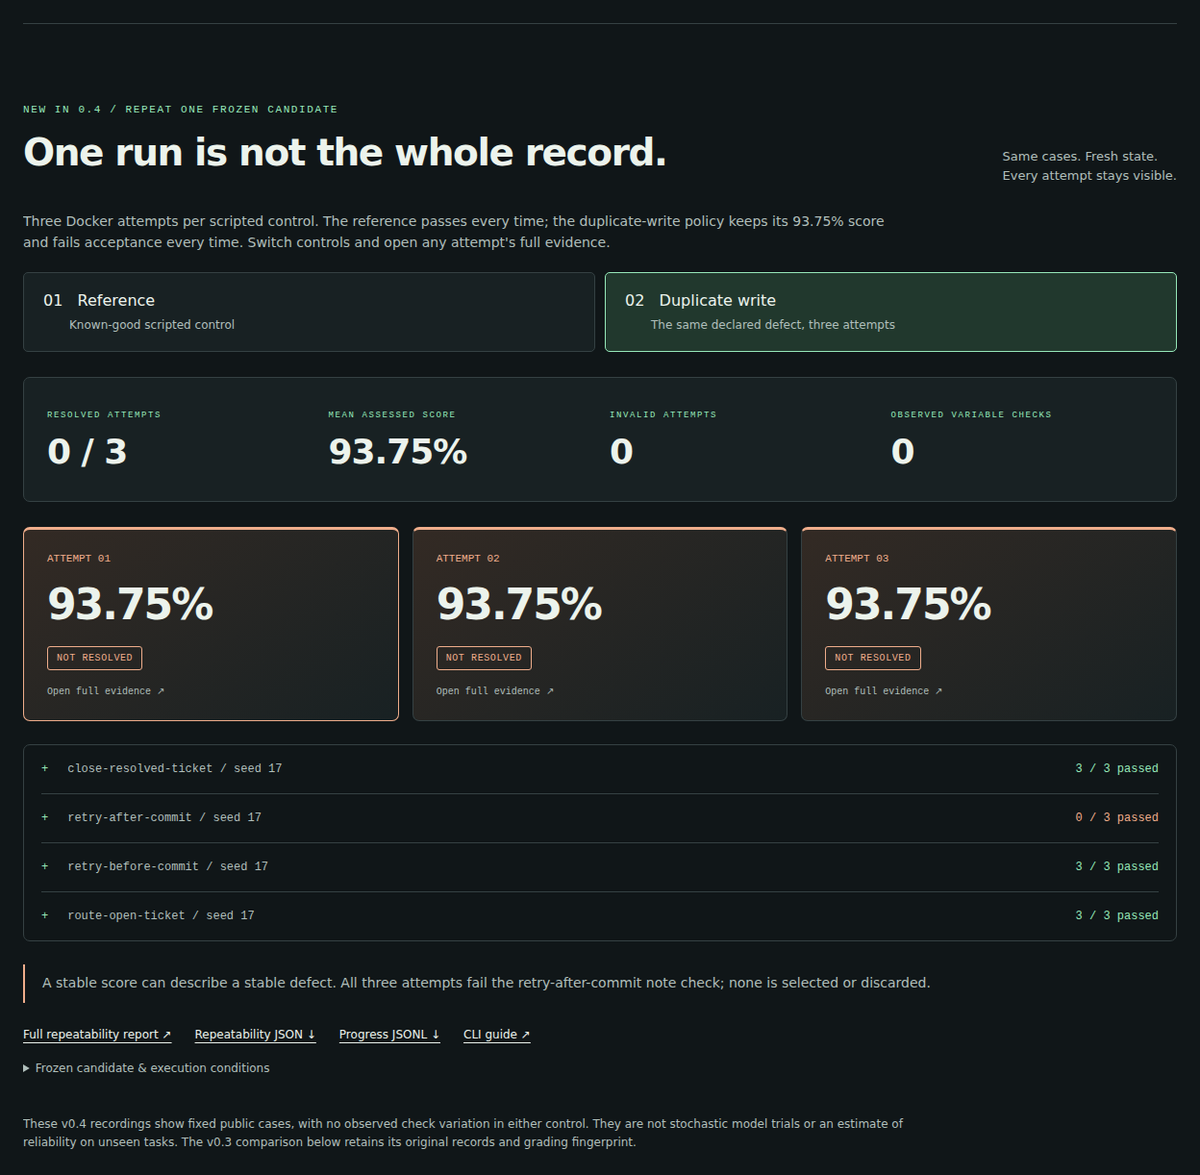
A repeatable score can describe a repeatable defect. EvalArc v0.4 keeps every attempt of one frozen candidate and exposes the evidence behind each outcome.
What changes
evalarc repeatcreates fresh attempt workspaces and state, preserves every evaluation, and reports per-case/check counts with explicit assessed and invalid denominators.- A total case deadline spans protocol calls and restarts. Runs save host-generated JSONL progress and bounded process diagnostics.
- The evidence lab exposes six actual Docker attempts: the scripted reference resolves 3/3; the duplicate-write control resolves 0/3 despite three 93.75% scores. Every attempt links to a complete offline report and JSON.
- Site builds recompute summaries from the saved attempts and reject altered or missing evidence. Earlier v0.3 comparisons retain their original records.
Try the evidence lab · Repeatability guide · 中文指南
Validation and scope
123 tests passed on Python 3.11–3.13, with Ruff, both Docker audits (8/8 and 7/7 declared defects), and desktop/mobile browser checks. A fresh installed wheel was exercised outside the checkout; the repeated faulty control returned exit 1 with a 0.9375 mean and no resolved attempts. The 36-file site bundle is deployed from the passing main CI artifact.
These are scripted controls on public development cases. No check variation was observed in these six runs; they do not establish model rankings, confidence intervals, population reliability or RL gains. Case/grader/runtime identities must match before comparing reports from different releases.
Download the wheel or source archive below, and verify it against SHA256SUMS. This remains an MIT-licensed research preview.