Repository navigation
Remote Models and llm bridge
Explanation. How agents with no network can use the OpenAI API, any OpenAI-compatible server, or the Anthropic API, and what keeps that path from becoming a way out.
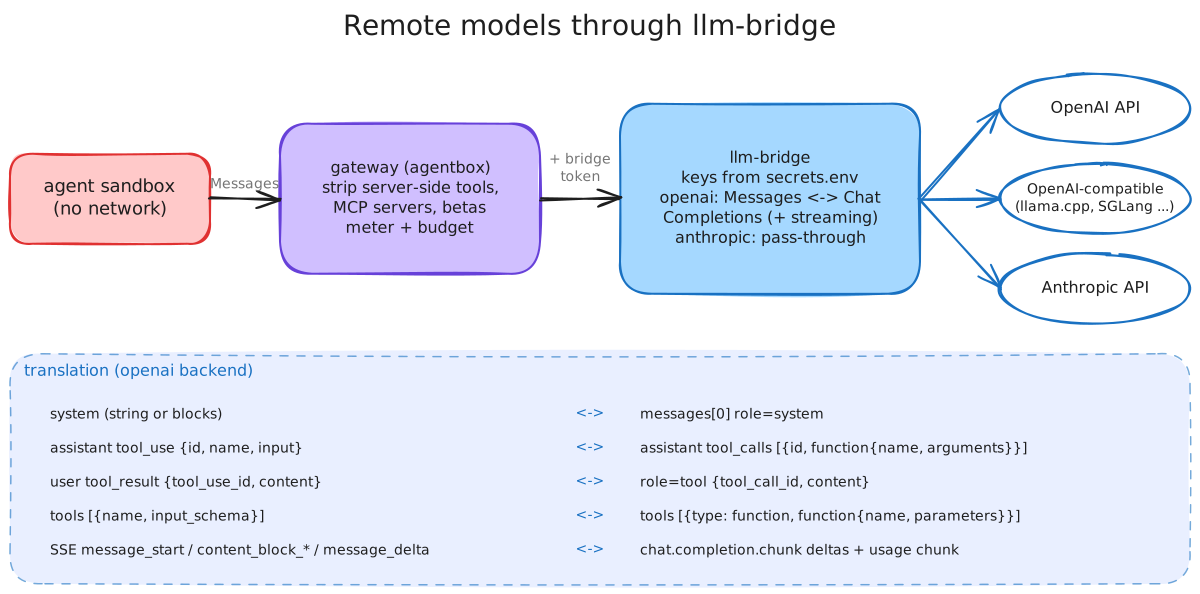
Remote models need two things the rest of agentbox deliberately lacks: API keys and internet access. Both live in exactly one place, the llm-bridge container:
- Keys come from
secrets.env, which only llm-bridge loads. The agentbox container doesn't have them. The agents never see them. - The agent's gateway forwards remote-model requests to llm-bridge with a bridge token. The agent can't reach llm-bridge itself.
-
backend: openaitranslates Anthropic Messages, which Claude Code speaks, into Chat Completions, and translates the response back. Streaming tool calls are re-assembled into Anthropic'scontent_blockevents. This works with the OpenAI API and any OpenAI-compatible server: llama.cpp, LM Studio, SGLang, TGI, a vLLM on another machine, OpenRouter, Groq and others. -
backend: anthropicpasses requests through to the Anthropic API, or any/v1/messagesendpoint.
Per-model options handle real-world differences:
-
token_param: max_completion_tokensfor newer OpenAI models; -
drop_params: [temperature, top_p]for reasoning models; -
max_output_tokensfor servers with small limits; -
extra_bodyfor provider-specific fields.
Thinking blocks are not translated, because Anthropic thinking needs signatures other providers can't produce.
Some model APIs can act on the network themselves: web search, web fetch, code execution, connecting to MCP servers. If an agent could switch those on, the model API would fetch URLs for a network-less agent. So the gateway, and again llm-bridge:
- keeps only client-side tools (a
nameand aninput_schema, executed by Claude Code in the sandbox); - drops server-side tools,
mcp_servers,containerandcontext_management; - never forwards
anthropic-betaheaders.
The model is pinned per task, so an agent can't redirect its traffic to another endpoint.
With a remote model, the agent's prompts, which include your code, go to that provider, and tokens cost
money. token_budget defaults to 3M per task for remote models (20M for local) and can be set per model.