Learned Policy
Experimental and OFF by default. This is a fitted system around JEV, not a renamed fixed threshold, a cache, or fine-tuning of JEV itself.
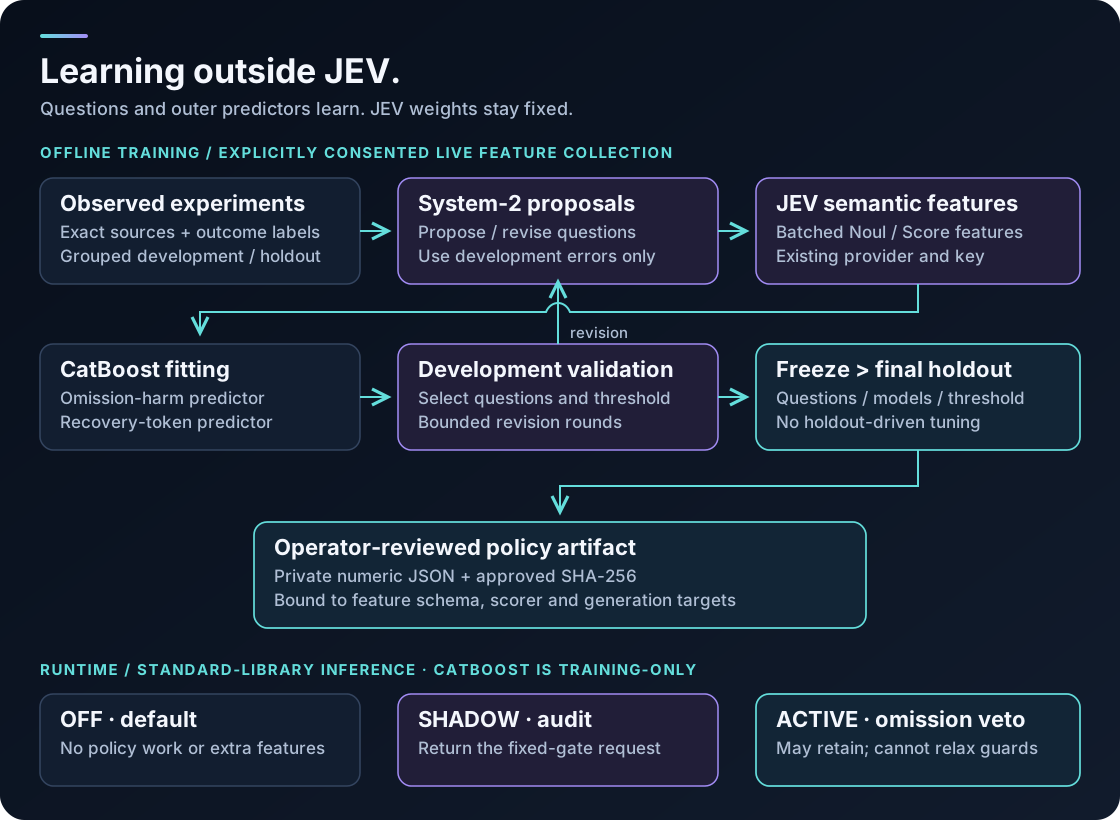
policy-train uses explicit outcome-labelled exact-source experiments. A System-2
model proposes/revises semantic questions based on grouped development-validation
errors. Existing OpenRouter/direct TypeSafe JEV routes produce batched Noul/Score
probabilities, from which CatBoost fits omission-harm and recovery-token predictors.
Questions, models and operating threshold freeze before final holdout assessment.
| Mode | Behavior |
|---|---|
off |
Default; no policy load or additional feature work |
shadow |
Return the fixed-gate request and separately audit the learned plan; up to twice the JEV batches |
active |
Approved predictor may retain otherwise removable evidence; extra questions share the bounded region batches |
The learned policy only adds an omission veto. It cannot weaken protected/uncertain context, call scope, exact evidence/recovery or the final tokenizer gate. Invalid or unapproved artifacts, incompatible scorer/target/schema and missing/out-of-domain features retain evidence. Runtime inference reads bounded numeric JSON, never pickle or executable model content; CatBoost is training-only.
export TOKEN_TERMINATOR_LEARNED_POLICY_PATH=/private/policies/reviewed/policy.json
export TOKEN_TERMINATOR_LEARNED_POLICY_SHA256="REVIEWED_64_HEX_DIGEST"
export TOKEN_TERMINATOR_LEARNED_POLICY_MODE=shadowNo training, vault mining, data export or policy activation happens automatically. Use exact offline replay, or explicitly consented live collection with existing credentials. The built-in System-2 proposer uses an explicitly selected generative OpenRouter model; replay or a callback can supply another integration. Native JEV is not treated as a generative chat model.
Limits bound rows, rounds, extra questions, requests, payload volume and model size;
these are not a hard dollar cap. Related sessions/tasks/exact evidence cannot cross
development/holdout groups. A finite successful holdout is not proof of production
calibration or quality. No production policy ships with the synthetic demonstration.
Rollback is TOKEN_TERMINATOR_LEARNED_POLICY_MODE=off plus restart; retain the vault.
Dataset, training and deployment guide · Real-fitting synthetic benchmark