Repository navigation
Releases: DepressionCenter/extractium
Release list
Extractium v0.4

Extractium™
Description
Extractium™ turns your organization's scattered public documentation into one searchable knowledge base. Point it at your website, knowledge base portal, GitHub repositories, YouTube channel, library repository, or a folder of files, and it gathers the content, prepares it for both keyword and meaning-based search, and writes it out in several formats. You can then use that knowledge base in a website search box, in your own scripts, or with the AI assistant of your choice, without depending on any one AI provider.
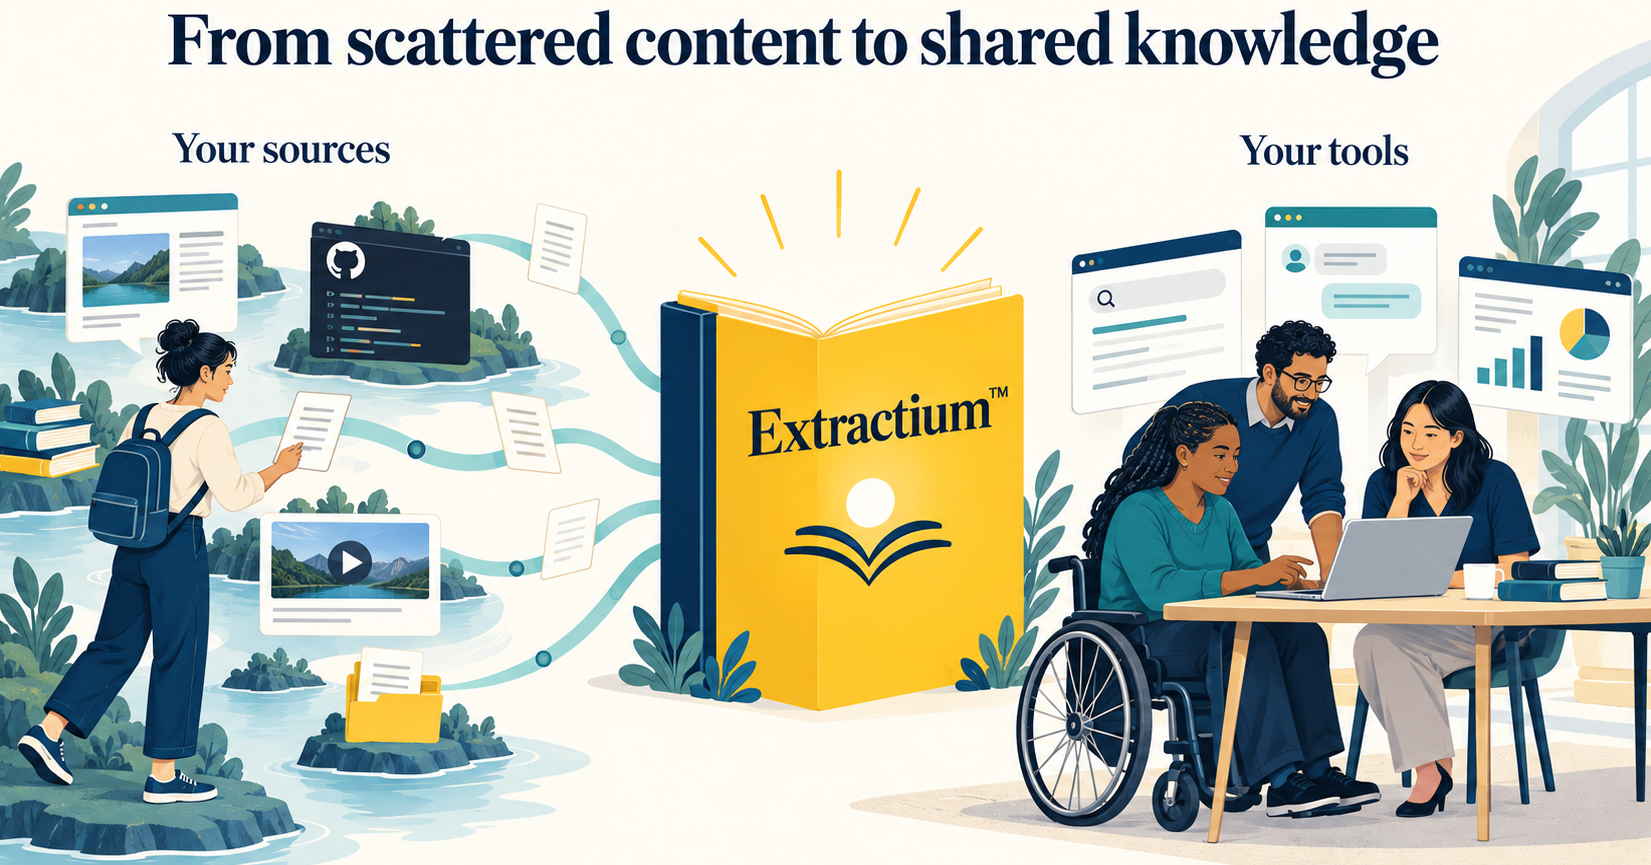
Unlike a vector database, Extractium™ needs no server, no database, and no API to run. Every output is a static file that you can host anywhere, including GitHub Pages, and the same build feeds all of them at once. Sources and outputs are plug-ins, so you can add your own if the built-in ones do not cover your needs.
Learn more at: github.com/DepressionCenter/extractium.
What's Changed
- Read a video's publisher without a key, and use each page's own description and tags by Gabriel Mongefranco (@gabrielmongefranco) in #76
- Transcribe a refused video from its audio, and report embedding progress by Gabriel Mongefranco (@gabrielmongefranco) in #78
- Skip vendored, generated, and housekeeping repository files; cap repositories and files per repository by Gabriel Mongefranco (@gabrielmongefranco) in #79
- Document the variables that choose which copy of Extractium the run scripts download by Gabriel Mongefranco (@gabrielmongefranco) in #80
- Shorten the site's hero line and simplify its header by Gabriel Mongefranco (@gabrielmongefranco) in #81
- Fix the site's stylesheet hash in its Content Security Policy by Gabriel Mongefranco (@gabrielmongefranco) in #84
- Call the thing a build writes a compendium, not a knowledge base by Gabriel Mongefranco (@gabrielmongefranco) in #83
- Stop tracking the coverage data file by Gabriel Mongefranco (@gabrielmongefranco) in #85
- Pin the audio transcription packages in the lock file, and report linked videos by publisher by Gabriel Mongefranco (@gabrielmongefranco) in #86
- Wait between audio downloads, say which path YouTube refused, and raise the sample delay by Gabriel Mongefranco (@gabrielmongefranco) in #87
- Record why the outputs are being made smaller, and plan the three phases that do it by Gabriel Mongefranco (@gabrielmongefranco) in #88
- Write llms.txt as an index of sources with one index file per source by Gabriel Mongefranco (@gabrielmongefranco) in #89
- Store SQLite postings by integer term id, and have the D1 worker read them that way by Gabriel Mongefranco (@gabrielmongefranco) in #90
- Write a light container and a full container, and leave code analysis to the sqlite and okf outputs by Gabriel Mongefranco (@gabrielmongefranco) in #91
- Keep the documentation's examples general, and name the current files in the settings file init writes by Gabriel Mongefranco (@gabrielmongefranco) in #92
- Decide relevance from the raw cosine to the query, not from the calibration figures by Gabriel Mongefranco (@gabrielmongefranco) in #93
- Index each page once, and cut long sections between words by Gabriel Mongefranco (@gabrielmongefranco) in #94
- Measure a relevance floor for each compendium at build time by Gabriel Mongefranco (@gabrielmongefranco) in #95
- Round every search score before ordering, and pass maxsplit by name by Gabriel Mongefranco (@gabrielmongefranco) in #96
- Show the rebuild setting in both sample settings files by Gabriel Mongefranco (@gabrielmongefranco) in #97
- Put local and GitLab builds first, and add a GitLab pipeline to the template by Gabriel Mongefranco (@gabrielmongefranco) in #99
- Add the staged plan for the local page and assistant connections by Gabriel Mongefranco (@gabrielmongefranco) in #100
Full Changelog: v0.3...v0.4
Copyright © 2026 The Regents of the University of Michigan
Contributors

Assets 2
Extractium v0.3
Extractium™
Description
Extractium™ turns your organization's scattered public documentation into one searchable knowledge base. Point it at your website, knowledge base portal, GitHub repositories, YouTube channel, library repository, or a folder of files, and it gathers the content, prepares it for both keyword and meaning-based search, and writes it out in several formats. You can then use that knowledge base in a website search box, in your own scripts, or with the AI assistant of your choice, without depending on any one AI provider.
Unlike a vector database, Extractium™ needs no server, no database, and no API to run. Every output is a static file that you can host anywhere, including GitHub Pages, and the same build feeds all of them at once. Sources and outputs are plug-ins, so you can add your own if the built-in ones do not cover your needs.
Learn more at: github.com/DepressionCenter/extractium.
What's Changed
- Raise the version to 0.2 and read it from one place by Gabriel Mongefranco (@gabrielmongefranco) in #45
- Stop crawling the narrowed views of a portal question listing by Gabriel Mongefranco (@gabrielmongefranco) in #46
- Skip an account's housekeeping repositories and accept their names by Gabriel Mongefranco (@gabrielmongefranco) in #47
- Read UTF-16 repository files and say what max_pages counts by Gabriel Mongefranco (@gabrielmongefranco) in #48
- Let a web source add exclude patterns without replacing the defaults by Gabriel Mongefranco (@gabrielmongefranco) in #49
- Carry the code parsers in the lock file and read Windows batch files by Gabriel Mongefranco (@gabrielmongefranco) in #51
- Index a long file as a compact record, and keep a page's text past the parse ceiling by Gabriel Mongefranco (@gabrielmongefranco) in #52
- Let the automatic transport post, and keep program folders out of a crawl by Gabriel Mongefranco (@gabrielmongefranco) in #53
- Run sources at the same time and keep several page fetches in flight by Gabriel Mongefranco (@gabrielmongefranco) in #60
- Choose a standard Python for the build environment by Gabriel Mongefranco (@gabrielmongefranco) in #61
- Build on a free-threaded Python, and check the Python the script was given by Gabriel Mongefranco (@gabrielmongefranco) in #62
- Read shared Google files and Word, OpenDocument, and RTF documents by Gabriel Mongefranco (@gabrielmongefranco) in #64
- Add leaf patterns for single pages on other hosts by Gabriel Mongefranco (@gabrielmongefranco) in #65
- Carry the caption library in the lock file by Gabriel Mongefranco (@gabrielmongefranco) in #67
- Parse Go and Rust with their published grammars by Gabriel Mongefranco (@gabrielmongefranco) in #68
- Read PDF files with pypdf in a killable child process by Gabriel Mongefranco (@gabrielmongefranco) in #69
- Read portal attachments, carry the enrichment fields, and fix the caption session by Gabriel Mongefranco (@gabrielmongefranco) in #70
- Apply max_pages to every source, in the unit each one reads by Gabriel Mongefranco (@gabrielmongefranco) in #71
- Record a redirected page where it landed, recheck pypdf security advisories, and untrack the lint reports by Gabriel Mongefranco (@gabrielmongefranco) in #72
- Name every section with keywords and every page with tags using YAKE by Gabriel Mongefranco (@gabrielmongefranco) in #73
- Read PowerPoint and OpenDocument presentations one section per slide by Gabriel Mongefranco (@gabrielmongefranco) in #74
Full Changelog: v0.2...v0.3
Copyright © 2026 The Regents of the University of Michigan
Contributors
Assets 2
Extractium v0.2
Extractium™
Description
Extractium™ turns your organization's scattered public documentation into one searchable knowledge base. Point it at your website, knowledge base portal, GitHub repositories, YouTube channel, library repository, or a folder of files, and it gathers the content, prepares it for both keyword and meaning-based search, and writes it out in several formats. You can then use that knowledge base in a website search box, in your own scripts, or with the AI assistant of your choice, without depending on any one AI provider.
Unlike a vector database, Extractium™ needs no server, no database, and no API to run. Every output is a static file that you can host anywhere, including GitHub Pages, and the same build feeds all of them at once. Sources and outputs are plug-ins, so you can add your own if the built-in ones do not cover your needs.
Learn more at: github.com/DepressionCenter/extractium.
What's Changed
- Redirect scope, action pinning, release pin, and full or incremental rebuilds by Gabriel Mongefranco (@gabrielmongefranco) in #40
- Rewrite the documentation to address the reader directly by Gabriel Mongefranco (@gabrielmongefranco) in #41
- Add the init command and let the build scripts download the tool by Gabriel Mongefranco (@gabrielmongefranco) in #43
- Stop the downloaded checkout from shadowing the package by Gabriel Mongefranco (@gabrielmongefranco) in #44
Full Changelog: v0.1.0...v0.2
Copyright © 2026 The Regents of the University of Michigan
Contributors
Assets 2
Extractium™ Initial Release
Extractium™
Description
Extractium™ turns your organization's scattered public documentation into one searchable knowledge base. Point it at your website, knowledge base portal, GitHub repositories, YouTube channel, library repository, or a folder of files, and it gathers the content, prepares it for both keyword and meaning-based search, and writes it out in several formats. You can then use that knowledge base in a website search box, in your own scripts, or with the AI assistant of your choice, without depending on any one AI provider.
Unlike a vector database, Extractium™ needs no server, no database, and no API to run. Every output is a static file that you can host anywhere, including GitHub Pages, and the same build feeds all of them at once. Sources and outputs are plug-ins, so you can add your own if the built-in ones do not cover your needs.
Learn more at: github.com/DepressionCenter/extractium.
Full Changelog: https://github.com/DepressionCenter/extractium/commits/v0.1.0
Copyright © 2026 The Regents of the University of Michigan