Repository navigation

Extractium™
Description
Extractium™ turns your organization's scattered public documentation into one searchable knowledge base. Point it at your website, knowledge base portal, GitHub repositories, YouTube channel, library repository, or a folder of files, and it gathers the content, prepares it for both keyword and meaning-based search, and writes it out in several formats. You can then use that knowledge base in a website search box, in your own scripts, or with the AI assistant of your choice, without depending on any one AI provider.
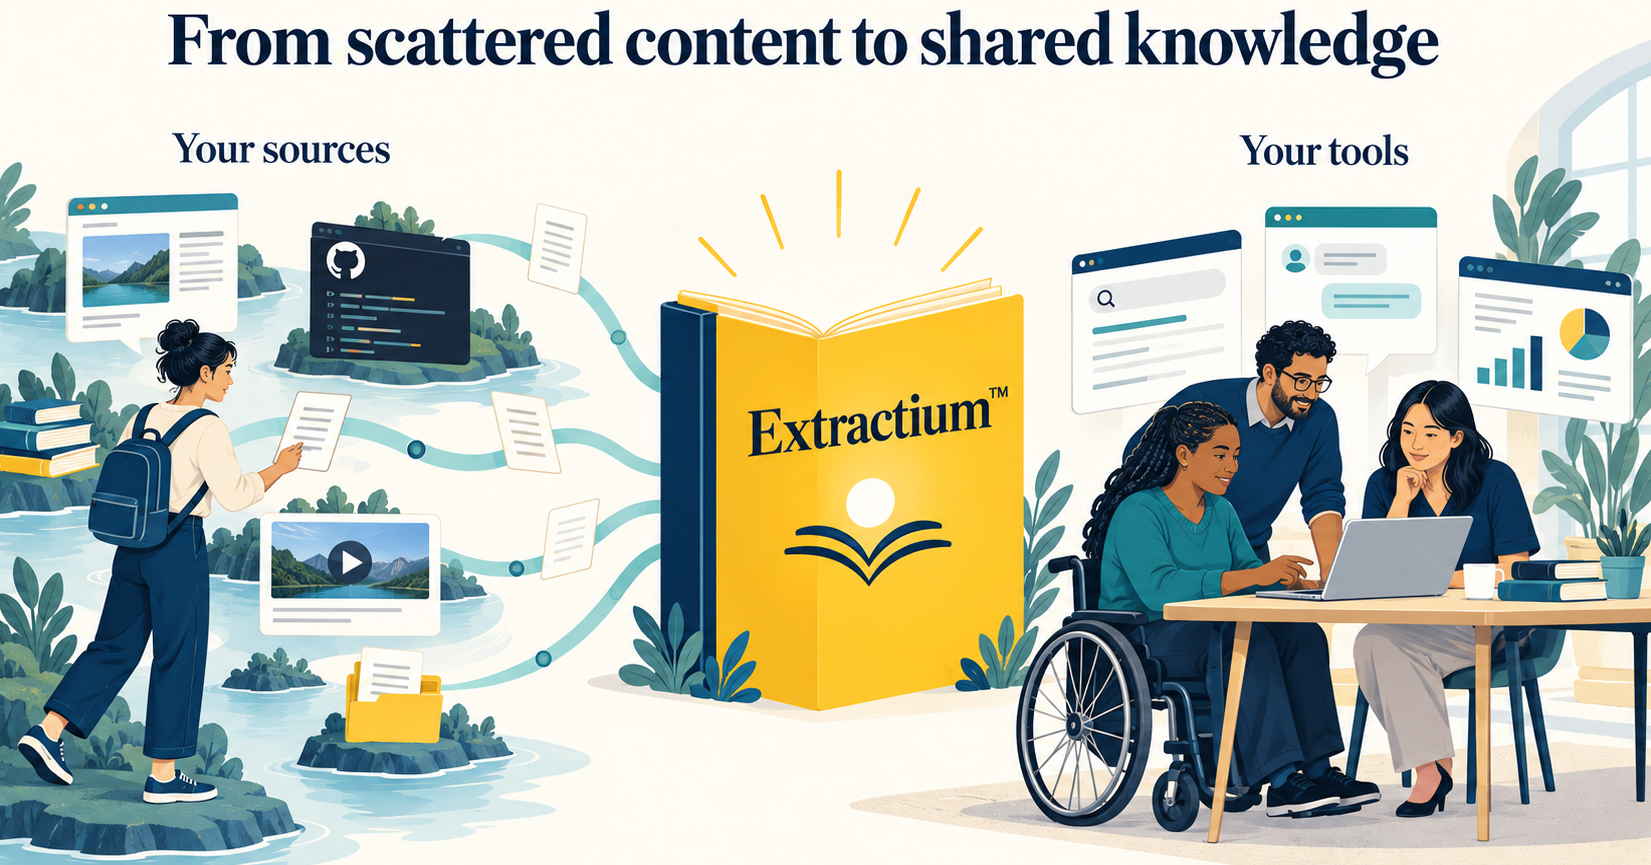
Unlike a vector database, Extractium™ needs no server, no database, and no API to run. Every output is a static file that you can host anywhere, including GitHub Pages, and the same build feeds all of them at once. Sources and outputs are plug-ins, so you can add your own if the built-in ones do not cover your needs.
Learn more at: github.com/DepressionCenter/extractium.
What's Changed
- Read a video's publisher without a key, and use each page's own description and tags by Gabriel Mongefranco (@gabrielmongefranco) in #76
- Transcribe a refused video from its audio, and report embedding progress by Gabriel Mongefranco (@gabrielmongefranco) in #78
- Skip vendored, generated, and housekeeping repository files; cap repositories and files per repository by Gabriel Mongefranco (@gabrielmongefranco) in #79
- Document the variables that choose which copy of Extractium the run scripts download by Gabriel Mongefranco (@gabrielmongefranco) in #80
- Shorten the site's hero line and simplify its header by Gabriel Mongefranco (@gabrielmongefranco) in #81
- Fix the site's stylesheet hash in its Content Security Policy by Gabriel Mongefranco (@gabrielmongefranco) in #84
- Call the thing a build writes a compendium, not a knowledge base by Gabriel Mongefranco (@gabrielmongefranco) in #83
- Stop tracking the coverage data file by Gabriel Mongefranco (@gabrielmongefranco) in #85
- Pin the audio transcription packages in the lock file, and report linked videos by publisher by Gabriel Mongefranco (@gabrielmongefranco) in #86
- Wait between audio downloads, say which path YouTube refused, and raise the sample delay by Gabriel Mongefranco (@gabrielmongefranco) in #87
- Record why the outputs are being made smaller, and plan the three phases that do it by Gabriel Mongefranco (@gabrielmongefranco) in #88
- Write llms.txt as an index of sources with one index file per source by Gabriel Mongefranco (@gabrielmongefranco) in #89
- Store SQLite postings by integer term id, and have the D1 worker read them that way by Gabriel Mongefranco (@gabrielmongefranco) in #90
- Write a light container and a full container, and leave code analysis to the sqlite and okf outputs by Gabriel Mongefranco (@gabrielmongefranco) in #91
- Keep the documentation's examples general, and name the current files in the settings file init writes by Gabriel Mongefranco (@gabrielmongefranco) in #92
- Decide relevance from the raw cosine to the query, not from the calibration figures by Gabriel Mongefranco (@gabrielmongefranco) in #93
- Index each page once, and cut long sections between words by Gabriel Mongefranco (@gabrielmongefranco) in #94
- Measure a relevance floor for each compendium at build time by Gabriel Mongefranco (@gabrielmongefranco) in #95
- Round every search score before ordering, and pass maxsplit by name by Gabriel Mongefranco (@gabrielmongefranco) in #96
- Show the rebuild setting in both sample settings files by Gabriel Mongefranco (@gabrielmongefranco) in #97
- Put local and GitLab builds first, and add a GitLab pipeline to the template by Gabriel Mongefranco (@gabrielmongefranco) in #99
- Add the staged plan for the local page and assistant connections by Gabriel Mongefranco (@gabrielmongefranco) in #100
Full Changelog: v0.3...v0.4
Copyright © 2026 The Regents of the University of Michigan
