Repository navigation
Monolith or Microservices Follow One Lost Answer Software Engineering Full Course Lecture 6
Full tutorial link > https://www.youtube.com/watch?v=r3lQevA-vtY
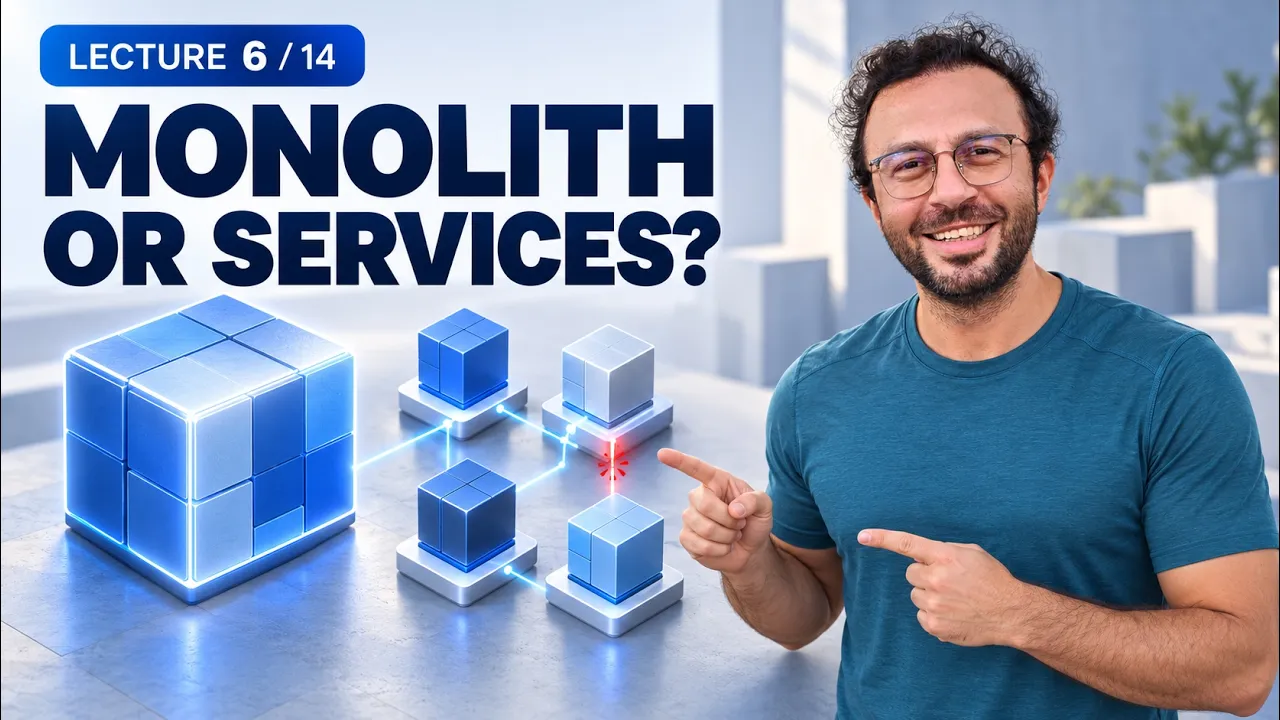





Lecture 6 of the Software Engineering course. Ari presses Book in Campus Rooms, a fictional room-booking service, and the screen says the request timed out, yet the database already holds booking B-001. Eight interactive scenes follow that lost answer through the whole system.
Links:
SECourses Patreon: [ https://www.patreon.com/SECourses ]
SECourses Discord: [ https://discord.com/servers/software-engineering-courses-secourses-772774097734074388 ]
You will see C4 views, a traced request, a modular application against separate services, a check-then-write race with one authoritative decision per room, idempotent retries, the four answers a caller can get, a transactional outbox, API contracts and an architecture decision record.
Topics: software architecture, C4 model, synchronous and asynchronous interactions, timeouts and unknown outcomes, microservices, race conditions, idempotency keys, eventual consistency, transactional outbox, API contracts, architecture decision records.
Jump to any scene, the questions, the principles or the sources.
Chapters:
00:00:00 A booking gets no answer: was the room booked?
00:00:43 Ari presses Book and the request times out
00:01:04 Predict: is room C101 booked for Ari?
00:01:24 Look inside: B-001 was stored, the answer was lost
00:02:06 The week's question and the five steps of this lecture
00:03:11 From week 5 modules to programs that fail separately
00:03:33 The components of Campus Rooms and two outside systems
00:03:56 Rules R-01, R-02 and R-04 under pressure this week
00:04:28 Five learning outcomes for architecture and distributed failure
00:05:07 Scene 1: what does a box labeled Booking stand for?
00:05:49 Level 1, system context: who the system deals with
00:06:21 Level 2, containers: applications and data stores, not Docker
00:07:14 Level 3, components: five modules inside one process
00:07:36 Trace Ari's request: three function calls, four network hops
00:08:51 Separate worker preset: Notification moves into its own process
00:09:56 What changed: how the system runs, not what it does
00:10:40 Scene 2: follow request REQ-17 across real boundaries
00:11:25 Steps 1 to 5: Ari waits 125 illustrative milliseconds
00:12:31 Synchronous calls versus asynchronous work, and what each costs
00:13:24 Mail down, email first: an outage reaches the booking answer
00:14:35 Principle: what you wait for decides which failures reach you
00:14:46 Mail down, pending: Confirmed now, the email waits
00:16:12 Scene 3: what would separate services buy a small team?
00:17:04 Six rows: release, scaling, calls, contracts, data, operations
00:18:22 Steady load: no universal winner, only a fit to conditions
00:18:45 Notifications grow: which split targets the growing workload?
00:20:12 Scene 4: two sensible requests, one broken booking rule
00:20:51 Check then write: both reads say available, both confirm
00:21:50 Invariants and races: the gap between a read and a write
00:22:11 In a transaction at read committed: still two bookings
00:23:21 Unique room plus start: different keys, overlapping times
00:24:12 One atomic decision per room: Bo gets a conflict
00:25:47 Scene 5: does a timeout tell you the write happened?
00:26:37 A plain retry: a conflict with Ari's own booking
00:27:25 Operation key K1: a retry returns the original result
00:29:11 Same key, new request: an explicit conflict, nothing stored
00:30:51 Four answers to one booking: stored, not stored or unknown?
00:32:24 Timeout, failure and unknown outcome: three observations named
00:32:56 Scene 6: a confirmed booking and a pending email
00:33:49 Mail outage: the booking stays confirmed, the email arrives late
00:34:52 Eventual consistency: fine for an email, never for overlaps
00:35:04 Duplicate attempt: a handler that checks before it sends
00:36:14 A crash between two writes: the silently missing email
00:36:58 Transactional outbox: booking and pending email committed together
00:38:26 Scene 7: the booking contract between Booking and its callers
00:39:53 What OpenAPI describes, and what it cannot establish
00:40:16 Three consumers: web app, door display and nightly export
00:40:38 Add a field: the strict nightly export fails
00:41:30 Same field, new meaning: every consumer silently wrong
00:42:29 New status values: an abrupt change versus a transition
00:43:41 Compatibility matrix: each change against each real consumer
00:44:27 Scene 8: which structure protects the promises? Decision record DR-002
00:45:38 Quality scenarios QS-1 to QS-3 and what protects each
00:47:17 Several campuses: a revisit trigger fires and reopens DR-002
00:48:44 Eight principles of this lecture, one from each scene
00:49:28 Six checks, including a batch importer that crashes
00:51:28 What carries forward to week 7, terms and sources
00:52:31 Recap: one lost answer followed through a whole system
Every name, number and booking is a teaching example from the fictional Campus Rooms service.
Questions and updates: the links above and the comments below. Thank you for watching.
-
00:00:08 Greetings everyone. This is week 6 of the Software Engineering course. Today's question
-
00:00:13 starts with a booking that gets no answer: Ari presses Book, and nothing comes back.
-
00:00:19 Here is the setup. Ari, user U-01, books room C101 from 10:00 to 11:00 in Campus Rooms,
-
00:00:26 the fictional booking service we follow throughout this course. On the left is Ari's booking screen,
-
00:00:32 with the room and the time filled in. Below it is the path of the request: Ari's browser, and
-
00:00:38 the inside of Campus Rooms, covered, because Ari cannot see in there. Let's press Book and see what
-
00:00:45 reaches Ari's screen. The request goes out, no answer comes back in time, and the browser reports
-
00:00:51 that the request timed out. Look at the path below. The request arrow went in, and then nothing
-
00:00:58 came back before the browser gave up waiting. From where Ari sits, that is all there is to see.
-
00:01:04 So decide before we look inside. Ari sees no answer. Is room C101 booked for Ari? Option A, no:
-
00:01:11 an error means the booking is not there. Option B, yes: Campus Rooms always saves first. Option C,
-
00:01:17 Ari cannot tell from this screen. Pause the video for a moment and choose your answer.
-
00:01:24 Now let's look inside Campus Rooms, the view Ari never gets. The request did reach Booking,
-
00:01:29 the part of Campus Rooms that decides bookings. Booking checked the rules and stored the booking:
-
00:01:36 B-001, Ari, room C101, 10:00 to 11:00, confirmed. It is in the booking database right now.
-
00:01:45 But the answer was lost on its way back, at the red cross. So Ari's screen says timed out,
-
00:01:50 while the room is in fact booked for Ari. The right answer was C. The whole lesson of today
-
00:01:57 fits in 1 picture. The write happened, the answer was lost, and the timeout told Ari only 1 thing:
-
00:02:04 the waiting was over. And Ari's next move matters. If Ari simply books again, or gives the room up,
-
00:02:11 a lost answer turns into a real problem. You will see both of those cases in this lecture.
-
00:02:17 So here is the question of this week: what changes when a dependency becomes slow,
-
00:02:21 unavailable, or uncertain? This lecture answers it in 5 steps.
-
00:02:26 First, what does a box on an architecture diagram stand for? That is scene one. Second,
-
00:02:31 which dependency does a request wait for, and which failures reach the user? Scenes 2 and 3.
-
00:02:38 Then, how can 2 reasonable bookings break 1 shared rule? That is scene 4. Next,
-
00:02:44 what do you know after a timeout, and how do you retry safely? Those are scenes 5 and 6.
-
00:02:50 And finally, how do contracts and decisions keep these promises over time? That is scenes 7 and
-
00:02:57 8. Check out the tutorial description to see the chapters. To move between pages, I use the arrow
-
00:03:03 buttons at the top right of the deck. The next page connects this week to what you already know.
-
00:03:11 Week 5 drew boundaries inside the code: modules with 1 responsibility each,
-
00:03:15 contracts that include failure behavior, and a decision record, which lists its revisit triggers.
-
00:03:22 This week, those same parts run as programs. They wait for each other over networks,
-
00:03:27 and they can fail separately. That changes what a design has to protect.
-
00:03:33 Here are the components of Campus Rooms. Booking receives a booking request and answers it. Policy
-
00:03:39 owns the booking rules, and Room Catalog knows the rooms. Notification sends confirmations,
-
00:03:45 and Storage reads and writes the booking database. 2 outside systems complete the picture:
-
00:03:50 Identity signs people in, and a mail provider delivers email. 3 rules come back this week. R-01:
-
00:03:58 no overlapping confirmed bookings for the same room. 10:00 to 11:00 and 11 to 12 only touch,
-
00:04:04 so both may exist. R-02: a booking lasts 30 to 120 minutes, both limits included. And R-04:
-
00:04:14 a failed notification never cancels a confirmed booking. R-04 also says that pending email stays
-
00:04:21 visible and recoverable. Keep that rule in mind, because scenes 2 and 6 put it under real pressure.
-
00:04:28 By the end of this lecture you can do 5 things. First, distinguish a module boundary from a
-
00:04:33 process or deployment boundary. Second, read context, component and runtime views at an
-
00:04:40 appropriate level. Third, explain how a concurrent check then write can violate a shared invariant.
-
00:04:47 Next, distinguish timeout, failure and unknown outcome. And finally, compare synchronous and
-
00:04:53 asynchronous interactions, including their costs. Each idea appears first as a mechanism you can
-
00:04:59 watch, and only then gets its formal name. So let's start with a question about a single box.
-
00:05:07 Scene 1 asks a simple question: what does a box labeled Booking stand for? Architecture diagrams
-
00:05:13 are full of boxes like this one, with a single word and no context. Before anything changes,
-
00:05:19 decide what you would point at if someone wants to know about this box. Option A, it depends
-
00:05:25 on the view: each view must say which level it belongs to. Option B, a module of code. Option C,
-
00:05:32 a server. Take a moment and choose, because all 3 answers sound reasonable in a meeting.
-
00:05:39 To find out, I use the Step button at the top right. It moves a scene forward
-
00:05:43 one state at a time, and the tabs above the diagram show which level we are on.
-
00:05:49 Level 1 is the system context. Here Booking means the whole booking system,
-
00:05:54 Campus Rooms, seen from outside, with the people who use it and what it depends on.
-
00:05:59 Ari and Bo book rooms. Campus Rooms asks Identity who is asking, and it sends email through a mail
-
00:06:05 provider. Both are outside systems that someone else runs. Notice what this view leaves out on
-
00:06:12 purpose: nothing about programs, databases or modules. A context view answers 1 question:
-
00:06:17 who and what surrounds this system? Now let's zoom in. Level 2 shows containers: the separately
-
00:06:24 running applications and data stores inside Campus Rooms. This vocabulary comes from the C4 model.
-
00:06:32 There are 3 of them. A browser app runs in the browser, 1 server application decides
-
00:06:37 and records bookings, and a booking database keeps the authoritative record. Here Booking means that
-
00:06:44 running application: 1 process you deploy, start and restart. If it stops, every booking stops,
-
00:06:50 whatever its code looks like inside. 1 warning about the word container. In the C4 model,
-
00:06:57 a container is an application or a data store. It is not necessarily a Docker container.
-
00:07:03 Docker images are a packaging format. This application could run from a Docker image,
-
00:07:07 as a plain process on a server, or on a cloud platform, and the view would not change at all.
-
00:07:14 Now we zoom in once more. Level 3 shows components, the modules inside 1 application.
-
00:07:19 Booking, Policy, Room Catalog, Notification and Storage all run in this one process. So here
-
00:07:26 Booking means 1 module with 1 responsibility: it receives a booking request and answers it.
-
00:07:32 3 views, 3 meanings of the same word. Let's trace Ari's request through this view. The numbers
-
00:07:39 follow the request, the green arrows are function calls inside the process, and the dashed blue
-
00:07:45 arrows are network connections. One, the request arrives from the browser over the network. 2,
-
00:07:51 Booking asks Identity who is asking, also over the network, because Identity is an outside system.
-
00:07:59 3, Booking asks Policy about the rules, and 4, it asks Storage to decide and store. Both are plain
-
00:08:05 function calls inside 1 process. 5, Storage writes to the booking database, across the network again.
-
00:08:12 6, Booking hands the email to Notification, and 7, Notification calls the mail provider.
-
00:08:19 Count them: 3 function calls inside 1 process, and 4 network connections to the outside. Room
-
00:08:25 Catalog plays no part in this request at all. So 5 logical components do not mean 5 servers.
-
00:08:32 Module boundaries are drawn in the code, and network boundaries are drawn by how you deploy it.
-
00:08:39 Here is the principle: architecture views should state their level, and logical separation does
-
00:08:44 not automatically imply network separation. In short, say which level a box lives on.
-
00:08:50 Now let's change 1 condition. The presets on the right select a variant of the scene. This one is
-
00:08:56 called Separate worker: Notification moves into its own process. Today all 5 components still run
-
00:09:04 inside 1 application. Before the change is shown, decide: what changes for Booking and Policy?
-
00:09:10 Option A, each now needs its own server. Option B, their logic stays the same,
-
00:09:15 and only where Notification runs changes. Option C, every booking now waits for the worker.
-
00:09:23 First the container view. A second process appears, the Notification worker. Booking
-
00:09:28 records a pending notification in the booking database, and the worker reads it and delivers it.
-
00:09:34 Now the component view: the same 5 responsibilities, and Notification has simply
-
00:09:40 left the application. Booking and Policy have not changed at all, so the answer is B. Look at hop
-
00:09:47 6. It used to be a function call; now the worker reads the pending email from the database, across
-
00:09:53 a network. That handoff is new. What changed is how the system runs. There are 2 server processes
-
00:09:59 to deploy and watch instead of one, and the worker restarts and scales without touching bookings.
-
00:10:07 A handoff through the database replaces a function call. And there is a new failure: the worker can
-
00:10:12 be down while bookings still confirm, so pending work must stay visible. What stayed the same is
-
00:10:19 what the system does: the same 5 responsibilities, the same rules, and Booking still decides.
-
00:10:26 Ari still gets Confirmed. Operations changed, and the logic did not. That is the same principle,
-
00:10:32 seen from the other side. Next, let's follow 1 request through these parts, step by step.
-
00:10:40 Scene 2 follows 1 request across real boundaries. Ari books C101 from 10:00
-
00:10:45 to 11:00, and the request carries a label, REQ-17, so we can track it.
-
00:10:51 Across the top are the 7 parts it visits: the browser, Booking, Identity, Policy, Storage,
-
00:10:56 Notification and the mail provider. Time runs from top to bottom. Solid arrows are calls that hold
-
00:11:04 up the answer, and dashed arrows are work that continues after it. Now decide: which steps must
-
00:11:10 finish before Ari sees Confirmed? Option A, only Storage, because it keeps the booking. Option B,
-
00:11:17 every step, including the email. Option C, Identity, Policy and Storage, then the answer.
-
00:11:24 Let's follow it. Step one: Ari's browser submits REQ-17 to Booking. From this moment
-
00:11:30 Ari is waiting, and the bar on the browser's line shows that wait. Step 2: Booking asks Identity
-
00:11:37 whether the signed in person is really Ari. In this illustration that is a 40-millisecond step,
-
00:11:43 and Ari waits the whole time. Step 3: Policy checks the duration and the interval rules,
-
00:11:49 a 5-millisecond step. Policy runs inside the same application, so this is a fast function call.
-
00:11:56 Step 4 is the important one. Here Storage makes the authoritative decision: nothing overlaps,
-
00:12:03 so it stores B-001 as confirmed, in a 60-millisecond write to the database.
-
00:12:09 Step 5: the answer, Confirmed, travels back to Ari. Ari's whole wait is a 125-millisecond
-
00:12:16 round trip. Each of those numbers is only an illustration. The dotted green line marks the
-
00:12:22 moment Ari has the answer. Steps 1 to 5 held it up, and Ari waited for each of those parts,
-
00:12:28 one after the other. These 2 kinds of steps have names. A call the caller waits for is synchronous,
-
00:12:35 like steps 1 to 5. Work that is recorded now and finished later is asynchronous.
-
00:12:42 Step 6 happens after the answer. Booking records the email as pending notification N-001,
-
00:12:48 and Ari is not waiting for this step at all. And step 7: Notification hands N-001
-
00:12:55 to the mail provider, which delivers it later. Ari's screen said Confirmed long before that.
-
00:13:02 So steps 1 to 5 hold up the answer, and steps 6 and 7 continue after it. That makes C the right
-
00:13:08 answer: Identity, Policy and Storage, then the answer. Each kind has a cost. Synchronous calls
-
00:13:15 add up: every part you wait for adds its time and its failures. Asynchronous work needs tracking,
-
00:13:21 so nothing pending is forgotten. Why does this matter? Every part Ari waits for is also a
-
00:13:27 part whose failure Ari will feel. So let's make one of them fail: the mail provider.
-
00:13:34 In the preset Mail down, email first, the mail provider is unavailable, and this design sends the
-
00:13:39 email before it answers Ari. Everything else stays the same. Decide what Ari sees now. Option A, no
-
00:13:47 answer: an unknown outcome. Option B, Confirmed, a little later. Option C, a clear Rejected.
-
00:13:54 Steps 1 to 4 still succeed. Identity, Policy and Storage all answer, so B-001 is stored as
-
00:14:02 confirmed, exactly as on a normal day. But now Booking sends the email first and waits
-
00:14:08 for it. The mail provider never answers, so Booking keeps waiting, and so does Ari.
-
00:14:14 At some point Ari's browser stops waiting. The screen says unknown outcome, while the database
-
00:14:20 says B-001 is confirmed. The right answer was A. So an email outage reached the booking answer.
-
00:14:28 Ari cannot tell whether C101 is booked, and may try again, or give the room away. Here is the
-
00:14:35 principle: interaction structure determines which failures affect which user promises. In short,
-
00:14:41 what you wait for decides which failures reach you. Now the same failure with the other design,
-
00:14:48 Mail down, pending. Here Booking answers first and records the email as pending work for later.
-
00:14:54 Decide again. Option A, no answer, an unknown outcome. Option B, Confirmed,
-
00:14:59 with the email still pending. Option C, Rejected until the mail provider returns.
-
00:15:06 Steps 1 to 5 run as usual, so Ari sees Confirmed, B-001, after the same 125 milliseconds. The mail
-
00:15:15 provider had no part in that answer. Step 6 records N-001 as pending notification,
-
00:15:22 after the answer. Ari is not waiting for it, so this step cannot delay the booking.
-
00:15:28 Step 7 tries to deliver it, and the mail provider is unavailable. N-001 stays pending,
-
00:15:35 with its failed attempt, and a retry is scheduled.
-
00:15:39 This design takes on an extra responsibility. Pending delivery must be observable and
-
00:15:44 recoverable, not merely forgotten. Support can see N-001, with its failed attempt on display.
-
00:15:52 So the same failure meets 2 designs. One breaks the booking promise, the other only delays the
-
00:15:58 email, and the right answer this time was B. Keep this picture in mind: a design decides which
-
00:16:04 failures reach the user. Next, let's ask whether those parts should be separate services at all.
-
00:16:12 Scene 3 asks what separate services would buy a small team. 1 team builds and runs Campus Rooms,
-
00:16:18 and the same components can run in 2 ways. On the left, a modular application:
-
00:16:24 1 deployable with 5 modules inside and 1 booking database. It is not an undivided blob;
-
00:16:29 its modules keep their boundaries. On the right, every component a service. Booking, Policy, Room
-
00:16:36 Catalog and Notification each deploy on their own, and Booking and Room Catalog each own their data.
-
00:16:43 Before the comparison appears, decide: for 1 small team under steady load, what would separate
-
00:16:49 services buy? Option A, loose coupling, for free. Option B, independent release and scaling, paid
-
00:16:56 for with network and coordination work. Option C, less to deploy and watch. Pause and choose one.
-
00:17:03 Row one: independent release. With the modular application, every change ships as 1 release
-
00:17:09 of the whole thing. A service can ship on its own, while its contracts stay compatible. Row 2:
-
00:17:16 independent scaling. The modular application scales as 1 unit, while 1 busy service can scale
-
00:17:21 on its own. That is a real benefit, when a need asks for it. Row 3, and this is the price: calls
-
00:17:28 between parts. Inside 1 process they are function calls. Between services they are network calls,
-
00:17:33 which can be slow, fail, or end in an unknown outcome. That last part should sound familiar.
-
00:17:41 Every network call now needs a timeout and a retry rule, which are exactly the problems of Ari's lost
-
00:17:47 answer in the opening. Row 4: contract changes. In 1 application, a changed function and its callers
-
00:17:54 change in 1 commit. Between services, a changed API needs a transition plan across releases.
-
00:18:01 Row 5: data ownership. 1 database holds the one no overlap decision. With services,
-
00:18:06 each owns its data, and a rule that spans services needs coordination. Row 6: operational work.
-
00:18:14 1 deployment to build, run and watch, against 4 deployments, their logs and alerts, and the
-
00:18:19 network between them. So the answer is B. For 1 small team under steady load, the extra boundaries
-
00:18:26 answer no need that has appeared yet. There is no universal winner here, only a fit to conditions.
-
00:18:34 Loose coupling, option A, does not come for free with services. 2 services that
-
00:18:39 must change together are still coupled, now with a network between them. So let's change 1 condition.
-
00:18:46 In Notifications grow, notification volume grows on its own, while booking writes stay the same.
-
00:18:53 The left side now shows a modular application with a separate Notification worker. Which split
-
00:18:59 targets the need? Option A, split every component into a service. Option B, split Policy out. Option
-
00:19:06 C, move only Notification into its own worker. Decide which change answers the growing workload,
-
00:19:12 and nothing more. First, the growing workload. Both alternatives let notification work scale
-
00:19:19 and fail on its own: the worker on the left, and the Notification service on the right.
-
00:19:25 Second, the boundaries added. The worker adds 1 handoff, through pending notifications in
-
00:19:30 the database. Splitting everything adds network calls between all 4 services, and split data.
-
00:19:38 Next, the booking route. With the worker it does not change: 1 process decides and stores.
-
00:19:43 With services, every booking now crosses the network to Policy and Room Catalog.
-
00:19:49 So C is the targeted answer: separate the one workload that grew. The principle:
-
00:19:54 choose deployment boundaries for demonstrated needs. Modularity and
-
00:19:59 distribution are different decisions. In short, split a process only when a real need asks. Now,
-
00:20:05 what happens when 2 people book the same room at the same moment? That is scene 4.
-
00:20:12 Scene 4. 2 reasonable bookings, 1 broken rule. Ari asks for C101 from 10:00 to 11:00. Bo,
-
00:20:18 at almost the same moment, wants 10:30 to 11:30. The calendar shows the clash: the half hour from
-
00:20:25 10:30 to 11 belongs to both requests. R-01, at the top right, allows only one of them.
-
00:20:32 Below is the order of events: Ari's request on the top lane, Bo's on the bottom lane, and time
-
00:20:38 running from left to right. Both requests run the same code, at the bottom left. Read the bookings
-
00:20:44 of the room, decide whether the new booking overlaps one of them, and write it if it does not.
-
00:20:51 Time one: Ari's request reads the bookings of C101. Nothing overlaps 10:00 to 11:00,
-
00:20:56 so the result is available. Time 2: Bo's request reads the same calendar
-
00:21:01 before Ari's write has landed. It also finds nothing in the way, so it reads available too.
-
00:21:08 Both reads said available. Now decide what each request will do. Option A,
-
00:21:12 both confirm. Option B, Ari confirms and Bo is rejected. Option C, both are rejected.
-
00:21:19 Time 3: Ari's request writes Confirmed, and B-001 is stored. R-01 still holds,
-
00:21:26 because there is only 1 booking. Time 4: Bo's request writes too. Its decision came from
-
00:21:32 the old read, so it stores B-002. The half hour from 10:30 to 11 is now booked twice.
-
00:21:41 R-01 is broken, and both people get Confirmed as their answer. So the answer is A. Each
-
00:21:47 decision made sense on its own. This is the heart of the scene. The order of the
-
00:21:52 clicks does not matter: the rule broke in the gap between a read and a write.
-
00:22:00 R-01 is an invariant: a rule that must hold in every state. When 2 operations run at the
-
00:22:05 same time, their steps interleave, and a race in that gap can break the invariant.
-
00:22:11 A common first fix is to wrap the code in a transaction.
-
00:22:15 The preset In a transaction does exactly that, at read committed, the default level of PostgreSQL.
-
00:22:21 Does that stop the overlap? Option A, yes: a transaction prevents double booking. Option B,
-
00:22:27 no: both still read available first. Option C, only if 1 request is slower.
-
00:22:33 Time one: Ari's transaction begins and reads available. Time 2:
-
00:22:38 Bo's transaction begins and reads available too, because Ari has not committed anything yet.
-
00:22:44 And nothing was locked. There is no row for the free half hour yet,
-
00:22:48 so there is nothing to lock. Each transaction only looks at the bookings already there.
-
00:22:54 Time 3: Ari's transaction writes and commits B-001. Time 4: the second transaction, from Bo,
-
00:23:01 writes and commits B-002. That makes 2 confirmations again, so the answer is B.
-
00:23:07 A transaction label is not a rule. The strictest isolation level would catch this pattern:
-
00:23:12 1 transaction fails, and the code must run it again. That strategy is a choice you make,
-
00:23:18 not a default you get for free. Another tempting fix is a uniqueness rule in storage. The preset
-
00:23:25 Unique room plus start refuses a second booking with the same room and the same start time.
-
00:23:31 Does that stop this overlap? Option A, yes: the second booking is refused. Option B, yes,
-
00:23:37 as long as both start on the hour. Option C, no: 10 and 10:30 are different keys.
-
00:23:44 The reads go exactly as before, available for Ari and then available for Bo. The uniqueness
-
00:23:50 rule only acts when a booking is written. Ari's write uses the key C101 at 10, which is accepted.
-
00:23:57 Bo's write uses C101 at 10:30, a different key, so it is accepted too. The times still overlap,
-
00:24:05 so the answer is C. The key protects same room, same start, which is a smaller rule than R-01.
-
00:24:12 Here is what does work. In 1 atomic decision, the check and the write happen as 1 step per room,
-
00:24:18 so nothing can happen between them. What happens to the same 2 requests now? Option A, one confirms
-
00:24:25 and the other gets a conflict. Option B, both confirm. Option C, neither booking goes through.
-
00:24:32 Ari's request goes first: it checks and writes in 1 step, and B-001 is confirmed. Line 2 of the code
-
00:24:39 makes each room's calendar take one decision at a time. Then Bo's request gets its turn. It checks,
-
00:24:47 finds B-001 in the way, and writes nothing. It returns a booking conflict instead. Bo sees
-
00:24:54 Rejected: C101 is taken from 10:00 to 11:00, and Bo can choose another time. R-01 remains true,
-
00:25:00 so the answer is A. There are several ways to get 1 decision like this. An exclusion constraint on
-
00:25:06 room and time range, as in PostgreSQL, makes the database itself refuse overlapping rows.
-
00:25:13 Transactions at the strictest isolation level work too, if the code runs the failed one again.
-
00:25:19 Or a lock on the room's calendar, rather than on a row that is still missing. Here is the principle:
-
00:25:26 an invariant shared by concurrent operations needs enforcement that survives their interleavings.
-
00:25:32 In short, a shared rule needs 1 guard that races cannot slip past. Now back to the lost answer
-
00:25:39 from the opening. What should Ari's browser do after a timeout? Scene 5 answers that question.
-
00:25:47 Scene 5: a timeout does not tell you whether the write happened. On the left are 3 parts:
-
00:25:53 Ari's browser, Booking and the booking database. Ari's request carries only the booking itself:
-
00:26:01 C101, 10:00 to 11:00. Nothing in it says which attempt this is. Booking stores
-
00:26:08 B-001 as confirmed, exactly as in the opening. The booking database now holds Ari's booking.
-
00:26:16 And again the answer is lost on the way back. Ari's screen says unknown outcome. Should the
-
00:26:22 browser simply send the booking again? Option A, yes: an error means nothing was saved. Option B,
-
00:26:29 not blindly: the write may have happened. Option C, no: tell Ari it failed. Pause and choose.
-
00:26:37 Let's see what a plain retry does. The browser sends the same booking again,
-
00:26:41 with no key. To Booking, this looks like a brand new request. So Booking checks R-01 and finds
-
00:26:48 that 10:00 to 11:00 overlaps B-001. The answer is Rejected, with a booking conflict as the reason.
-
00:26:56 Ari is told the room is taken, by Ari's own booking. From Ari's side, 2 attempts have
-
00:27:01 now failed, even though the room was booked the first time. So Ari does what any person would do
-
00:27:08 and books another room: C202, 10:00 to 11:00, confirmed. Now Ari holds 2 bookings for 1 meeting.
-
00:27:16 And C101 is held for nobody who needs it. Booking could not tell a retry from a new request,
-
00:27:22 and the right answer was B: not blindly. The fix is to give the operation an identity. In Key K1,
-
00:27:28 same request, the browser sends an operation key, K1, with the first attempt and repeats it
-
00:27:34 on every retry. The key belongs to Ari and to this one booking. What should a retry with K1
-
00:27:40 return? Option A, create a second booking. Option B, a conflict with B-001. Option C,
-
00:27:48 the original result: B-001, confirmed. Pause and think about what Ari actually wants here.
-
00:27:56 Booking stores B-001, and in the same commit it records the key. K1 belongs to Ari, for C101 at
-
00:28:03 10, with the result: B-001 is confirmed for Ari. Storing the key in the same commit matters. There
-
00:28:10 is no moment when the booking exists but the key does not, so a retry can never slip through a gap.
-
00:28:17 The answer is lost again, and Ari sees unknown outcome. This time the browser keeps K1,
-
00:28:23 ready for the retry. The retry carries K1 and the same request. Booking looks up K1,
-
00:28:29 finds the original result and returns it: B-001, confirmed. No second booking is made.
-
00:28:36 On the right is the code that answers a request with a key. Lines 3 to 6 find the key of this
-
00:28:42 requester, compare the request and return the stored result. The right answer was C.
-
00:28:48 1 more point about the web itself. HTTP defines GET, PUT and DELETE as idempotent methods,
-
00:28:54 and POST as not. A key like K1 is an application rule that makes this POST safe to repeat.
-
00:29:00 Idempotent means that repeating an operation has the same effect as doing it once. Exactly once
-
00:29:06 does not appear by itself: you design it, with keys like this one. But what if a retry reuses
-
00:29:12 the key for a different request? In Same key, new request, the retry still says K1, but asks
-
00:29:18 for 10:30 to 11:30. K1 already holds a result for 10:00 to 11:00. So what should happen? Option A,
-
00:29:25 an explicit conflict. Option B, move B-001 to 10:30. Option C, a new booking for 10:30.
-
00:29:34 Booking looks up K1, sees that it was used for 10:00 to 11:00, and refuses: conflict,
-
00:29:40 key reused with a different payload. Nothing is stored, and nothing else changes at all.
-
00:29:47 Silently treating the changed request as the old one would hide a real mistake. So the right answer
-
00:29:53 is A, an explicit conflict, which code lines 3, 4 and 7 produce. The table shows the same handler
-
00:30:00 on 4 requests, with results checked by running it. Ari with K1 and the same request gets the
-
00:30:07 original result back. Ari with K1 and a different request gets the conflict. But Bo, using the same
-
00:30:14 text K1, starts a new operation, because a key belongs to a requester and 1 intended action.
-
00:30:20 And with nothing stored yet, K1 simply starts a new operation. After that, R-01 decides about the
-
00:30:26 booking itself, as usual. Here is the principle: retries need defined semantics for identity,
-
00:30:34 repeated effects, and uncertain outcomes. In short, give each operation an identity,
-
00:30:39 so a retry cannot double it. Before the next scene, 1 page sorts out the
-
00:30:45 answers a requester can get, because an error message is not always a no.
-
00:30:51 Ari asked for C101 from 10:00 to 11:00. Here are 4 answers Ari could get, and each one says
-
00:30:57 something different about the write. 3 come from Booking, and 1 only from Ari's clock.
-
00:31:03 For each one, ask 2 questions before you open it: was the booking stored,
-
00:31:08 and what should happen next? The first answer is Rejected, booking conflict.
-
00:31:14 This is a response from Booking, and it is a decision. No booking was stored:
-
00:31:19 Booking checked R-01 and the answer is no. The same request would get the same answer.
-
00:31:26 Second: service unavailable. It is also a response from Booking, and our contract sends it only
-
00:31:31 before any decision. So nothing was stored, and a later retry with the same key is safe.
-
00:31:38 Notice where that certainty came from: the contract. Without that promise,
-
00:31:42 service unavailable would leave you guessing. Next, an unexpected server error.
-
00:31:49 This is a response, but not a decision. The failure may have happened after the write,
-
00:31:53 so nobody knows whether B-001 is in the database. For now, the outcome is unknown.
-
00:32:01 And the last one: no answer before the timeout. This one comes only from Ari's clock. The request
-
00:32:06 may be lost, still running, or stored with its answer lost, just like in the opening.
-
00:32:13 So 2 of the 4 leave the write unknown. For those, the safe next step is to ask, or to retry with the
-
00:32:19 same key, never to assume that nothing happened. Now let's give the 3 observations their names.
-
00:32:27 A timeout is when the waiting side stops waiting. It is an observation at 1 boundary, nothing more.
-
00:32:33 A failure is a response that reports a problem, and it says only what its contract promises.
-
00:32:40 An unknown outcome means the requester cannot tell whether the write happened. So an error message
-
00:32:46 is not always a no, and an operation key turns an unknown outcome into a safe question. Next,
-
00:32:52 the email that follows every booking. Scene 6: a confirmed booking and a pending email can both
-
00:32:59 be true. B-001 and its confirmation email, N-001, are 2 separate facts on 2 timelines.
-
00:33:08 Right now B-001 is confirmed, and N-001 has not been delivered. Did the booking fail? Option A,
-
00:33:15 yes: no email means no booking. Option B, no: the booking and the email are separate facts.
-
00:33:21 Option C, only if the email bounces. Think about what Ari can rely on at this moment.
-
00:33:29 The booking timeline says confirmed, and the notification timeline says pending. Ari is told:
-
00:33:35 your booking is confirmed, and the email is on its way. Support sees N-001 waiting for delivery. Both
-
00:33:43 views are honest, and neither hides the other. That is rule R-04 at work. Now attempt 1 fails,
-
00:33:51 because the mail provider is unavailable. The booking line does not move at all, and Ari is
-
00:33:56 told the booking is confirmed and the email is late. Support sees the failure: N-001 failed once,
-
00:34:04 and a retry comes later. Pending work that failed stays visible, so someone can act on it.
-
00:34:10 The second attempt is delivered. Now both records are complete, and Ari's inbox finally shows the
-
00:34:16 confirmation email. The table lists what each combination means. Confirmed with pending: the
-
00:34:25 booking is confirmed and the email is on its way. Confirmed with failed delivery: confirmed, and the
-
00:34:31 email is late. Booking confirmed, email delivered: everything is done. And a rejected request creates
-
00:34:39 no notification, because no booking was made at all. So the answer was B. Confirmation depends on
-
00:34:46 the booking decision; the email may finish later, and it stays visible until it does.
-
00:34:52 This is sometimes called eventual consistency: the email catches up with the booking a little later.
-
00:34:58 That is fine for an email, but never for the no overlap decision itself.
-
00:35:03 Delayed work brings a new question: what if the same email is attempted twice? In
-
00:35:08 Duplicate attempt, N-001 is sent a second time, and the booking does not change.
-
00:35:15 2 handlers stand side by side. What should the second attempt do? Option A, send again,
-
00:35:21 because duplicates are harmless. Option B, cancel the booking. Option C, nothing new,
-
00:35:26 because N-001 is already delivered. Decide before the second attempt comes in.
-
00:35:34 The first attempt goes through the same way in both handlers: each delivers N-001,
-
00:35:39 and Ari gets exactly 1 email so far. Then attempt 2 arrives. The first handler checks first, finds
-
00:35:46 N-001 already delivered, and does nothing. The second handler always sends, so it sends again.
-
00:35:54 The result: 1 email on the left, but on the right a second email to Ari and 2 sends in
-
00:35:58 the log. So the answer was C: nothing new to do. B-001 stays confirmed in both handlers. Only the
-
00:36:06 handler decides whether repeat work is harmless, so write handlers that check first and act after.
-
00:36:13 1 more danger is a crash. In Crashes and the outbox, a process crashes at 3
-
00:36:19 different moments. On the left, the email is written separately from the booking.
-
00:36:24 Booking writes B-001 and commits. Then it writes the pending email in a second write. What survives
-
00:36:31 if the process crashes in between? Option A, B-001 only. Option B, both of them survive. Option C,
-
00:36:38 neither survives. Decide using what you already know about what a commit makes permanent.
-
00:36:46 The crash lands between the 2 writes. B-001 is committed, and the notification was never written.
-
00:36:53 The email is never attempted, and nothing shows that it is missing.
-
00:36:57 That is the worst kind of failure, a silent one, and the answer was A.
-
00:37:02 Now the design on the right, called a transactional outbox.
-
00:37:07 The booking B-001 and the pending notification N-001 are committed together, in 1 transaction.
-
00:37:15 A worker delivers the notification later. Crash after the commit, before delivery: both B-001 and
-
00:37:22 the pending N-001 survive. After the restart, the worker finds N-001 and delivers it. A crash after
-
00:37:30 sending, but before N-001 is marked delivered? The worker comes back up and sends it again:
-
00:37:37 delivery attempt number 2. So the outbox keeps the work discoverable, and the email goes out
-
00:37:43 at least once, sometimes twice. The handler still has to tolerate a repeat, as you saw a moment ago.
-
00:37:50 In practice, work waiting in a queue commonly runs on RabbitMQ or Kafka. The queue moves the
-
00:37:56 work, but it does not decide what a repeat should do. That stays your design decision.
-
00:38:02 Here is the principle: asynchronous work changes the timing and failure contract;
-
00:38:07 it does not remove responsibility for completion. In short, later work is still your work:
-
00:38:13 track it until done. So far, everything happened inside 1 contract between the browser and Booking.
-
00:38:21 Let's look at that contract, and at what happens when it changes.
-
00:38:26 Scene 7: an added field and a changed meaning are not equivalent. On the left is the booking
-
00:38:32 contract between Booking and everything that calls it. Every booking request is a POST to
-
00:38:39 /bookings. Let's make the contract concrete, one part at a time, starting with what a caller sends.
-
00:38:46 The request has 4 fields: room_id, C101; start and end, 10:00 and 11:00; and the operation_key,
-
00:38:51 K1. That key is the retry identity from scene 5. Identity is not a field. The signed in requester
-
00:38:59 comes from Identity, never from a field the browser fills in. Otherwise anyone could type
-
00:39:05 someone else's name. The response has 2 fields: booking_id, B-001, and outcome, Confirmed. The
-
00:39:12 panel at the top right shows the response exactly as Booking sends it. Then come 4 error meanings,
-
00:39:20 each with a defined when. Invalid request, when a field is missing or the times are malformed.
-
00:39:27 Not permitted, when the requester may not do this. Booking conflict, when R-01 or R-02 says no. And
-
00:39:34 service unavailable, which is sent only before any decision. The answers page relied on that promise.
-
00:39:41 Finally, the retry rule: repeat the same operation key with the same request to get
-
00:39:46 the original result. The same key with a different request counts as a conflict, never as a retry.
-
00:39:53 In practice, HTTP contracts like this one are often described in OpenAPI. An OpenAPI description
-
00:39:59 captures the operation, its fields, their types and the error responses. But it does not establish
-
00:40:06 who owns the booking, that bookings never overlap, or that a retry is safe. A schema describes shape,
-
00:40:12 and behavior needs checks of its own. 3 consumers read these answers, each in
-
00:40:18 its own way. The booking web app reads booking ID and outcome, and ignores fields it does not know.
-
00:40:25 The room door display reads only outcome, and shows a room as booked when outcome is
-
00:40:30 Confirmed. The nightly export reads every field, and rejects any field or value it does not know.
-
00:40:38 Today all 3 of them work. Now the first change. In Add a field, the response gains 1 more field,
-
00:40:43 called room_name. Which consumers keep working? Option A, all 3: adding is always safe. Option B,
-
00:40:51 the web app and the door display, while the strict export rejects it. Option C, none of them.
-
00:40:59 The producer adds room_name, with the value Room C101. Nothing else changes: the old fields keep
-
00:41:05 their names and their meanings. The booking web app was released together with the producer,
-
00:41:11 and shows the room name. The door display never reads room_name, so it works too.
-
00:41:18 But the nightly export rejects the unknown field, and the whole export fails. So the answer is B:
-
00:41:24 adding a field is safe only for consumers that ignore what they do not know.
-
00:41:30 Now a sneakier change. In Same field, new meaning, the bytes stay identical,
-
00:41:35 but outcome Confirmed is now sent as soon as a request arrives, before R-01 is checked.
-
00:41:41 What breaks? Option A, nothing, because the response looks the same. Option B,
-
00:41:46 only the export. Option C, every consumer, and every check still passes.
-
00:41:53 The response looks exactly as before: outcome, Confirmed. But it now arrives before the decision,
-
00:41:59 so Bo's overlapping request also gets Confirmed as its answer. Every consumer still parses it,
-
00:42:06 and every one is wrong. The web app tells Bo that the request went through,
-
00:42:10 the door display shows a booking that R-01 later rejects, and the export lists rejected requests.
-
00:42:18 So the answer is C. A changed meaning passes every shape check,
-
00:42:22 an OpenAPI description included, which makes it far more dangerous than an added field.
-
00:42:28 The next change is a new spelling of the status. In New status values, outcome Confirmed becomes
-
00:42:35 outcome CONFIRMED, in capital letters, in a single release. What does the door display do? Option A,
-
00:42:42 it shows the room as free, silently. Option B, it fails loudly. Option C, it keeps working.
-
00:42:50 In the abrupt change, the web app works because it was released together with the
-
00:42:55 producer. The door display compares outcome with Confirmed, finds no match, and shows C101 as free.
-
00:43:03 That is answer A: silently wrong, the worst kind of wrong. The nightly export at least
-
00:43:08 fails loudly, rejecting the unknown value. Now the same change as a transition, in 4 steps. Step one:
-
00:43:15 the export learns the new field and its value first, before anyone sends them.
-
00:43:21 Step 2: the producer sends a new field, status, beside outcome. Old readers still find outcome,
-
00:43:27 and the new status field says CONFIRMED. Step 3: each consumer moves to status in its own release.
-
00:43:35 Step 4: outcome is removed once no consumer reads it. No consumer broke along the way. Here is the
-
00:43:42 whole picture: each change, each consumer, and the assumption behind each cell. The assumptions sit
-
00:43:48 under the consumer names: ignore unknown fields, or reject them. Read the rows. An added field
-
00:43:55 works for 2 consumers and fails for the export. A new meaning is silently wrong everywhere.
-
00:44:00 The abrupt status change works, fails silently and fails loudly. The transition works everywhere. The
-
00:44:07 principle: compatibility is a relationship between actual producers and consumers, not a label on a
-
00:44:13 release. In short, ask who reads a field before you change it. 1 question remains: which structure
-
00:44:20 should Campus Rooms have, and how do you write that choice down? That is the last scene.
-
00:44:27 Scene 8: which structure protects the promises? On the right is decision record DR-002:
-
00:44:34 1 modular application, an authoritative booking store and recoverable notification work.
-
00:44:40 It protects R-01 and R-04, and safe retries after a lost response. The diagram at the bottom
-
00:44:46 left shows the structure it chose. A diagram shows what was chosen; the record says why.
-
00:44:53 So which evidence supports this architecture? Option A, it is the most modern style. Option B,
-
00:44:58 it has the fewest boxes. Option C, the requirements it protects,
-
00:45:03 written as testable scenarios. Take a moment to choose before we open the record.
-
00:45:11 First, the context. 1 campus and 1 small team. Bookings must never overlap, even when
-
00:45:16 requests race. A failed email must never undo a booking, and a lost response must not create
-
00:45:22 a second booking. Then the decision. 1 modular application decides every booking in 1 database,
-
00:45:29 with an atomic interval rule. Each booking commits a pending notification beside it,
-
00:45:34 and requests carry operation keys. Now the most useful part, the quality scenarios. Each promise
-
00:45:41 becomes a situation you can test. QS-1: 2 people book overlapping times at once, and exactly 1 is
-
00:45:47 confirmed. QS-2: the mail provider is down for an hour, and bookings keep confirming while emails
-
00:45:55 wait. QS-3: a lost response and a retry return the original result. Each scenario names what
-
00:46:02 protects it: 1 atomic decision, notifications committed with the booking, and operation keys.
-
00:46:08 That is why the answer is C. The trade-offs come next. 1 deployable is simple to release and watch,
-
00:46:14 but it scales as 1 unit. The database is 1 shared dependency: while it is down, no booking is
-
00:46:20 decided. And Notification can move into its own worker later without changing the booking logic,
-
00:46:27 as in scene one. Ownership is clear: 1 team owns the application and the booking data. Next, what
-
00:46:34 happens when parts fail, decided in advance. Mail provider down: confirm, keep N-001 pending, and
-
00:46:41 retry. Database down: answer service unavailable and decide nothing. And a lost response:
-
00:46:47 the browser retries with the same key. These are the answers you built up in scenes 2, 5 and 6.
-
00:46:54 Last, revisit when: the changes that would reopen this decision. Notification volume growing on its
-
00:47:00 own, several independently operated campuses, or another team releasing on its own schedule.
-
00:47:07 The record also says what it is not: a teaching baseline for this case, not a prescription for
-
00:47:13 every system. Now let's see one of its triggers in action. In Several campuses, Campus Rooms now
-
00:47:20 serves several independently operated campuses, each with its own rooms, staff and operations.
-
00:47:26 What should happen to DR-002? Option A, keep it, since it has worked so far. Option B, reopen it,
-
00:47:33 because one of its revisit triggers fired. Option C, replace it with services everywhere.
-
00:47:40 The trigger, several independently operated campuses, fires, and the status turns to
-
00:47:45 Revisit due. The record told us in advance when to come back to it. The answer is B.
-
00:47:51 Reopening it means reconsidering 4 questions. Who owns each campus's booking data? And where is the
-
00:47:57 authoritative no overlap decision made for each room? What does a booking mean while 2 campuses
-
00:48:04 cannot reach each other? And which contracts does each campus offer, and who may change them?
-
00:48:11 Consistency across distant sites is not solved in this lecture. The record names the questions
-
00:48:17 and keeps the decision open, and that honesty is part of a good record. The principle: architecture
-
00:48:23 decisions should explain which requirements they protect and which assumptions would change
-
00:48:29 the choice. In short, write down what a choice protects and what would change it. That completes
-
00:48:36 the 8 scenes. The next page collects their principles, with 6 questions to check yourself.
-
00:48:44 Here are the 8 principles of this lecture, one per scene. One: architecture views should
-
00:48:49 state their level, because a box on its own says nothing about where it runs. 2:
-
00:48:55 interaction structure decides which failures reach which promises. 3: choose deployment boundaries
-
00:49:01 for needs you can demonstrate. 4: a shared rule needs enforcement that survives interleavings. 5:
-
00:49:09 retries need an identity, defined repeat effects, and a plan for uncertain outcomes. 6: asynchronous
-
00:49:17 work stays your responsibility until it completes. 7: compatibility depends on real consumers. 8:
-
00:49:24 a decision record says what it protects and what would change it. Now 6 checks. Decide
-
00:49:30 your answer before each one opens. Check one: why can 2 availability checks both return true?
-
00:49:37 Because they can observe the same earlier state before either write has been enforced. That was
-
00:49:43 the race you saw in scene 4, between Ari and Bo. Check 2: why not block confirmation on
-
00:49:50 every notification attempt? Because it couples the booking promise to an outside dependency
-
00:49:55 without need, under R-04. Separate work still needs reliable tracking, as the pending email
-
00:50:02 showed. Check 3: what should happen when an operation key is reused with a different payload?
-
00:50:11 A defined conflict or rejection, never silently treating the altered request as the original
-
00:50:17 operation. Check 4: is a C4 container always a Docker container? It is not. In that model,
-
00:50:25 a container is an application or a data store boundary, not a specific packaging
-
00:50:29 format. Check 5: what survives a crash after an atomic booking and pending notification commit?
-
00:50:38 The booking and the pending work both stay recorded. Delivery still needs recovery,
-
00:50:43 and a later retry can repeat a delivery attempt.
-
00:50:47 And the last check leaves room booking behind. A batch importer crashes after storing an entry,
-
00:50:53 but before marking its input complete. What makes a restart safe?
-
00:50:59 Give the intended operation a stable identity, and tie its effect to durable completion evidence,
-
00:51:05 or make a replay produce the same outcome again. A crash does not show that no write happened,
-
00:51:12 and reusing an identity for changed input needs an explicit policy. It is the lesson of scene 5,
-
00:51:18 in a new setting. The last page lists what carries forward to next week, the terms of this lecture,
-
00:51:25 and where to read more. Week 7 begins with this question: how can several people change 1 system
-
00:51:32 without losing intent or trust? 3 things carry forward: the booking contract with its retry rule,
-
00:51:39 decision record DR-002 with its revisit triggers, and 1 atomic decision per room for R-01.
-
00:51:47 In practice, as of 2026: HTTP contracts are often described in OpenAPI, and PostgreSQL
-
00:51:54 can enforce no overlap for time ranges with an exclusion constraint. Work in a queue commonly
-
00:52:01 runs on RabbitMQ or Kafka, and services ship as Docker images, a packaging format,
-
00:52:06 not the containers of the C4 model. In the middle are the terms of this week, from architecture
-
00:52:12 view and system context to idempotent, operation key and transactional outbox.
-
00:52:19 And on the right are the sources: the C4 model by Simon Brown, the HTTP semantics standard,
-
00:52:25 the PostgreSQL documentation on transaction isolation, and the OpenAPI specification.
-
00:52:31 So today you followed 1 lost answer through a whole system: what a box means,
-
00:52:35 what a request waits for, how a race breaks a rule, and how a key makes a retry safe.
-
00:52:41 And you saw how pending work, contracts and decision records keep these promises over
-
00:52:46 time. Thank you for watching, and I will see you in week 7.