Repository navigation
Turn Stakeholder Requests into Verifiable Requirements Full Course Lecture 2
Full tutorial link > https://www.youtube.com/watch?v=wJibevFLxqg
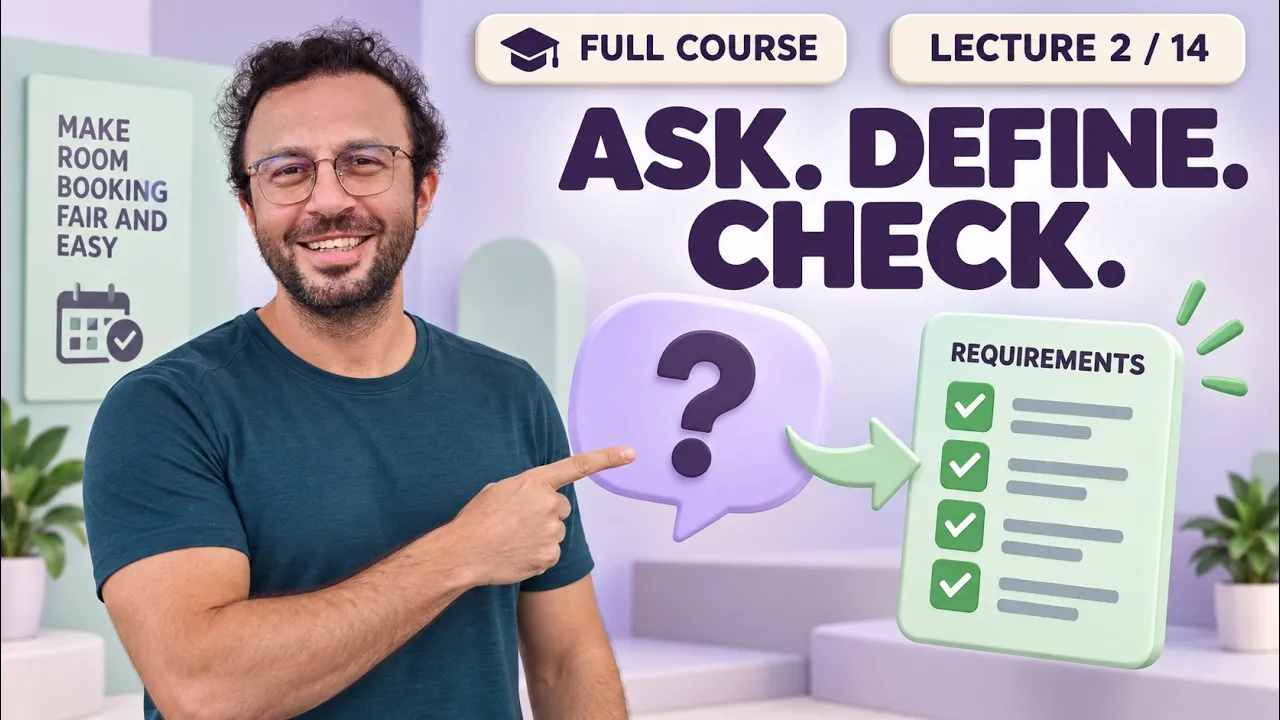



Learn how to turn a vague software request into requirements you can check. In Lecture 2 of the 14-part Software Engineering course, we follow the fictional Campus Rooms service from “make room booking fair and easy” to explicit rules, boundary examples, quality conditions and traceable decisions. The central question: how would we know that a requirement has been satisfied?
Links:
SECourses Patreon: [ https://www.patreon.com/SECourses ]
Course repository and interactive lessons: [ https://github.com/FurkanGozukara/Software-Engineering-Full-Lecture-2026-2027-Fall ]
Lecture 1 PDF: [ https://github.com/FurkanGozukara/Software-Engineering-Full-Lecture-2026-2027-Fall/blob/main/site/pdf/week-02.pdf ]
SECourses Discord: [ https://discord.com/servers/software-engineering-courses-secourses-772774097734074388 ]
You will learn how to ask stakeholders for concrete examples, separate facts from assumptions and open questions, define accepted and rejected behavior, and test the edges of a 30–120 minute booking rule. We compare vague and precise requests to an assistant, examine why an average response time hides slow users, and connect requirements to design decisions, examples and checks.
Main topics include requirements engineering, elicitation and scope, behavior and quality requirements, business rules, acceptance examples, boundary testing, response-time percentiles, keyboard accessibility, verification versus validation, traceability, prioritization and change management.
Use the chapters to jump to any demonstration or revisit the requirement register and closing checks.
Chapters:
00:00:00 The question of this week: when is a requirement satisfied?
00:02:58 A request in words, four kinds of statement, this week's outcomes
00:05:17 An ambiguous request: the developer reads fair alone
00:10:04 Ask the stakeholders first: three examples of a fair outcome
00:12:19 Elicitation and scope: the question behind a second email
00:16:40 A visitor appears: deferred with a date or omitted
00:18:02 Observable behavior: where accepted turns into rejected
00:22:10 A temporary variant: only the examples at the edge change
00:23:27 Two requests to an assistant: one example judges the drafts
00:25:51 Quality with conditions: one user, one number, no evidence
00:29:33 Fifty users: the average hides the slow tail
00:30:27 The keyboard path: a quality accepted by outcome
00:31:52 Verification against the statement, validation against the need
00:35:34 Correcting the words moves the mismatch into view
00:36:36 The traceability matrix: decision, examples and checks per row
00:40:37 Delegated cancellation: what a change to R-03 would touch
00:41:47 Priority and risk: reasons on the table, not scores
00:45:15 A closure tomorrow adds urgency and changes nothing else
00:46:16 Requirements under change: stale and current evidence
00:49:51 A wording-only correction leaves every link current
00:51:00 The requirement register: kinds, statuses and open items
00:54:19 Eight principles and six checks, including a desktop editor
00:57:39 What carries forward to week three, terms and sources
This lecture is for anyone who needs to turn a short request into a clear decision about what to build. Campus Rooms and its names, numbers and incidents are teaching examples. Lecture 1 introduces the service and its overlapping-booking problem; Lecture 3 continues with models for booking, cancellation and failure states.
Background music in the silences: Infinity, Serene View, Romantic 05, Relaxation 04, Digital Clouds, Your Breath, Stylz, Down the River, Vastness, Opalescent, Curiosity, Pilates and Yoga (Mixkit, Stock Music Free License).
For questions, updates and the rest of the course, see the links above, the pinned comment, Patreon and Discord. Share your questions in the comments. Thank you for watching.
-
00:00:00 Greetings everyone. Today I am going to show you how 1 short sentence becomes requirements you can
-
00:00:07 check. This is week 2 of the Software Engineering course, and it starts exactly where week 1 ended:
-
00:00:14 with a request from the room staff. Here is the request card. Make room booking fair and easy.
-
00:00:21 6 words, no examples, no numbers, no names. And on those 6 words a whole service is supposed to
-
00:00:27 be built. Read it twice before we go on. Let's do what most of us do first. I click Read it
-
00:00:35 as a developer, and a first reading appears. Fair becomes whoever asks first gets the room,
-
00:00:41 and easy becomes fewer clicks on the booking screen. Look at the last line of that card:
-
00:00:47 nothing here is wrong yet, and nothing here is decided either. That is the whole tension
-
00:00:53 of this week. A confident reading feels like a decision, and it is not one. In the middle you see
-
00:01:00 the question of this week: how would we know that a requirement has been satisfied? Keep it in mind
-
00:01:06 for the whole lecture, because every scene answers it in a different way. 3 answers. Option A,
-
00:01:13 when the person who asked says it is done. Option B, when a concrete example behaves the way the
-
00:01:20 requirement says. Option C, when the code runs without errors. Pick one, and keep it in mind
-
00:01:27 for a minute. Keep your answer in mind, because scene 3 tests it with 4 numbers. Now I click What
-
00:01:34 does this course build, and the card on the right fills in. Let me read it with you. This lecture
-
00:01:41 builds a small connected set of requirements for Campus Rooms. R-01, no overlapping confirmations.
-
00:01:48 R-02, a duration from 30 to 120 minutes. R-03, who may cancel. R-04, the notification is a separate
-
00:01:57 fact. R-05, keyboard completion. And Q-01, the search response time. 6 identifiers, and each
-
00:02:05 of them comes back in a later week under the same name. Each of them gets an example you can check,
-
00:02:13 and each links to a design decision and an independent check. Below that, where this applies:
-
00:02:19 every request you receive in words has this shape, a wish, some missing decisions, and an assumption
-
00:02:26 or 2. And the thread of the course: a precise requirement is also what makes an automated
-
00:02:32 assistant's draft judgeable. In scene 3 the same request goes to an assistant twice, once vague
-
00:02:40 and once as R-02, and 1 example decides between the drafts. Check out the tutorial description to
-
00:02:47 see the chapters, so you can jump to any scene. To move between pages I use the arrow buttons at the
-
00:02:53 top right. I click the next page button now. This page starts from a request you received in words:
-
00:03:01 think of the last time someone asked you for something in 1 sentence, faster, simpler,
-
00:03:08 fairer. Hold that request in your head for a moment, because 3 questions about it are
-
00:03:14 coming next. Now, 3 questions about that request. What did you build first, and how did you decide
-
00:03:21 that? Which words did you fill in for them without asking, a limit, a default, a who? And how did you
-
00:03:28 know whether they got what they needed? The small note reminds you what week 1 left on the table:
-
00:03:37 the context map, the no overlap concern, and rule R-01. The open assumptions about closures,
-
00:03:44 delayed messages and simultaneous requests are there too, and we will use every one of them
-
00:03:50 today. The second card names 4 kinds of statement that will come apart this week. What the service
-
00:03:58 must do is a behavior. How well it must do it is a quality target. A rule the organization sets is
-
00:04:06 a business rule. And a way of building it is an implementation decision. 2 of these sound alike
-
00:04:13 in a meeting, and the difference decides who may change them. Only the first 3 are requirements.
-
00:04:19 Keep that sentence close, because the register at the end of the lecture sorts every statement into
-
00:04:25 1 of these 4 boxes, and the fourth box is not a requirement at all. On the right, what you will be
-
00:04:31 able to do by the end. First, identify ambiguity, missing stakeholders and hidden assumptions in a
-
00:04:38 request. Second, turn a request into observable behavior with boundary and failure cases. Third,
-
00:04:45 distinguish a requirement from a solution decision and a supporting assumption. Fourth,
-
00:04:50 connect a requirement to a design decision and an independent verification check. And fifth,
-
00:04:56 explain how a changed requirement affects its linked evidence. 1 more thing before the first
-
00:05:04 scene: the requirements written this week are not finished once. They return in week 3 as models,
-
00:05:10 in week 8 as checks, and in week 12 when they change, so let's open the first scene. This is the
-
00:05:18 first anchor scene, and its title is a claim: 1 sentence, 3 systems. 3 people will read the same 6
-
00:05:25 words, and each of them will describe a different booking service. The request card sits at the top
-
00:05:32 left. Under the sentence you see 3 requests that will test every reading of it. Ari asked at 09:00
-
00:05:40 for room C101 from 10:00 to 11:00, and Ari already holds 4 bookings this week. Bo asked at 09:05
-
00:05:48 for the same room and the same hour. The room staff asked at 09:10. 3 people, 1 room, 1 hour:
-
00:05:55 whichever reading of fair we choose, 2 of them lose. Before anything is built, decide before the
-
00:06:01 reveal. What does fair mean in this sentence? Option A, first come, first served. Option B,
-
00:06:09 a per user weekly limit. Option C, staff requests come first. Pick one before I continue. Think like
-
00:06:18 the developer. Option A is what code gives you for free: the first request wins. Option B needs
-
00:06:25 a number and a period. Option C needs a list of who counts as staff. Every option hides a decision
-
00:06:33 nobody has made. A word about the controls, since every scene uses them: Step moves the
-
00:06:40 scene 1 state forward, and Back returns 1 state. Replay restarts the selected condition, and Reset
-
00:06:48 returns to the baseline; the condition card names the presets, and the baseline is selected
-
00:06:54 now. In this baseline the developer reads the sentence alone and builds it from that reading,
-
00:07:02 so I press Step. The developer reads fair as first come, first served, and rewrites the sentence with
-
00:07:10 more confidence: rooms are allocated strictly in the order requests arrive. Notice the chip:
-
00:07:18 more confident wording. The rewrite sounds like a decision. It is not one; it silently picked 1
-
00:07:23 of 3 readings and hid the other 2. Nobody outside the developer's head was asked. Step again, and
-
00:07:31 the screen is built from the rewrite. Ari asked first, so Ari is confirmed. Bo sees not available,
-
00:07:37 and so do the room staff. The screen works exactly as written, and the last line says the important
-
00:07:44 part: nobody else was asked. Step. The department coordinator sees the result and objects: nobody
-
00:07:52 should hold more than a fair share of the week. Their reading of fair is a per user weekly limit.
-
00:07:59 Ari is at the limit of 4, so under their rule Bo gets the room. Step. The room staff see it too:
-
00:08:08 our requests have to come first, we run the rooms. Their reading is staff priority. Under their rule
-
00:08:14 the staff request wins and both students are turned away. Same sentence, third winner. Look
-
00:08:21 at the 3 cards side by side. Ari wins on the left, Bo wins in the middle, the room staff win on the
-
00:08:28 right. 3 rules, 3 different winners, and all 3 can be defended from the same 6 words. I press Step,
-
00:08:37 and the strip at the bottom lists the questions that were never asked. Who decides? What is
-
00:08:43 scarce? What outcome matters? The fights over fair are fights over these 3 questions, and no wording
-
00:08:51 of the sentence answers them. Think of a request you know: make the report faster. Faster for the
-
00:08:57 person who reads it every morning, or for the server that builds it at night? That is the same
-
00:09:03 shape: 1 word, 2 winners, and the decision hidden until somebody asks. The last step reveals the
-
00:09:11 principle. The rewrite decided nothing; it only sounded decided. Ambiguity is resolved through
-
00:09:17 examples and stakeholder decisions, not through more confident wording. And easy is a second,
-
00:09:23 separate ambiguity: easy for whom? A keyboard user, a first time visitor, or the room staff? It
-
00:09:29 goes to scene 4 and rule R-05 as an open quality question. What I take from this as a student:
-
00:09:37 when a sentence sounds decided, I look for the example that would prove it. If I cannot write
-
00:09:43 one, the sentence has not decided anything yet, and that is the moment to ask, not to code. Read
-
00:09:49 the principle once more: ambiguity is resolved through examples and stakeholder decisions,
-
00:09:55 not through more confident wording. In short, confident wording settles nothing; examples
-
00:10:01 and decisions do. Now let's change 1 condition and keep everything else exactly the same, so I click
-
00:10:09 Ask first. Same sentence, same 3 requests, and no code yet, because each stakeholder will be asked
-
00:10:17 for an example of a fair outcome before anything is built. Step. The student answers: whoever asks
-
00:10:24 first should get the room. Rule: first come, first served. Example: Ari is confirmed because
-
00:10:32 Ari asked first. The same card as before, but now it is 1 voice among 3, not the only one.
-
00:10:40 Step. The department coordinator: nobody should hold more than a fair share of the week. Rule:
-
00:10:45 a per user weekly limit. Example: Bo is confirmed, because Ari is at the weekly limit. Step, and the
-
00:10:53 room staff: our requests have to come first, so the rule is that staff requests take priority.
-
00:11:00 Example: the staff request is confirmed, because a staff request beats every student request. 3
-
00:11:07 examples, and each one is concrete. Step, and the strip appears again: 3 winners from 1 sentence,
-
00:11:15 on the table before any code. The conflict is not hidden inside a build. It is a decision,
-
00:11:21 and the decision belongs to these people, not to the developer's rewrite. Step. Now something gets
-
00:11:28 settled, and something is left open on purpose. Settled for this lecture: exclusive booking of
-
00:11:36 available rooms. Open decision: the fairness policy, which the stakeholders decide with
-
00:11:42 their examples. And easy for whom goes to scene 4. Writing down what is open is not a failure.
-
00:11:50 The open decision has an owner, the stakeholders, and it has 3 examples attached. That is far more
-
00:11:57 useful than a confident sentence that pretends the question is closed. The final step gives
-
00:12:03 the principle for this condition: same sentence, same people, a different service. The reading that
-
00:12:10 reaches the screen is the one the stakeholders chose, with their examples written next to it.
-
00:12:16 Let's go to the next page. The user asked for an email. Is that the requirement? Ari asks for
-
00:12:23 another confirmation email, and before building it we find out what happened. On the left is a
-
00:12:30 scope map: the dashed line is this release, campus members book rooms. Inside the line: the booking
-
00:12:37 screen and decision, Ari as a campus member, and the room staff who run the rooms. Outside the
-
00:12:44 line, below, a guest who is not a member and asks to book. The line says who this release serves.
-
00:12:52 Decide before the reveal: Ari asks for another confirmation email, so what do you build? Option
-
00:12:58 A, a second email, as requested. Option B, ask what happened last time. Option C, nothing at all,
-
00:13:06 because 1 email is already enough for anyone. Option A is fast to build and easy to regret:
-
00:13:14 a second email fixes nothing if the first never explained the outcome. Option C assumes the person
-
00:13:23 is wrong. Option B costs 1 question, and only it can find out. I press Step. Instead of a second
-
00:13:32 email, the conversation card gets 1 question: what happened on your last booking? A request names a
-
00:13:39 solution. The question looks for the situation behind the solution. Step, and Ari answers the
-
00:13:46 question: after submitting, the person cannot tell whether the booking was stored. The answer carries
-
00:13:53 the tag simulated observation, an authored example of such a conversation, and the register gets its
-
00:14:00 first row: a fact, stated by Ari. Step, and now the 2 callouts: requested, another confirmation
-
00:14:08 email; needed, to know the outcome of the booking. The second row of the register is an assumption:
-
00:14:15 that a second email would tell Ari the outcome. It was inferred, and the register says so. Why
-
00:14:23 does that distinction matter? A fact has a speaker you can go back to. An assumption has an author,
-
00:14:30 and the author is us. If the email had been built, it would have answered the assumption and left the
-
00:14:38 fact untouched. Step brings a small prototype. 3 outcomes the screen tells apart: submitting,
-
00:14:46 confirmed, and unknown outcome. Walking through this prototype with Ari informs the requirement.
-
00:14:52 The authoritative stored result is a separate concern, the one week 1 taught us to check.
-
00:14:59 So the requirement is not send another email, and the sentence that replaces it came from a
-
00:15:05 question. It is closer to: after submitting, the person can see whether the booking was stored,
-
00:15:12 or that the outcome is still unknown. Step, and the question widens to the guest at the
-
00:15:18 boundary. 2 badges appear on the line. Identity: who is this person to the campus, and how does the
-
00:15:25 service know? And cancellation rights: may a guest cancel, and whose booking? Step. 2 more. Keyboard
-
00:15:33 completion is already a stated rule, R-05, so its badge is green. And room closures, who may record
-
00:15:40 one and what happens to affected bookings, stays an open question until week 14. The register also
-
00:15:49 grew by 2 rows. A fact stated by the coordinator: campus members book rooms in this release. And an
-
00:15:58 assumption inferred by the developer: guests never need a room. One was said; the other was filled
-
00:16:05 in. The last step gives the principle: an explicit boundary and an open question register make
-
00:16:12 uncertainty discussable. Facts have a speaker, assumptions an author, questions a place on the
-
00:16:18 line. In short: write down what you know, what you assume, and what is open. The register is what I
-
00:16:25 would copy into my projects: what we know and who said it; what we assume and who assumed it;
-
00:16:31 and what is open. A project without that third column still has the same open questions; it
-
00:16:37 only hides them better. Now the changed condition: I click A visitor appears, and a new stakeholder
-
00:16:44 stands outside the campus and outside the dashed line: an external visitor. The line does not move
-
00:16:52 at all, and what is written about the visitor decides what happens next. Step, and deferred,
-
00:16:59 explicitly: visitors book rooms, deferred to a later release, with a dated decision and an owner.
-
00:17:06 The visitor is told at the screen that booking is for campus members, and where to ask. The register
-
00:17:13 gets a deferred row. Step. Omitted, accidentally: nothing written about visitors. The visitor finds
-
00:17:21 out at the door, and nobody can say whether it was ever decided. The row is faded on purpose: there
-
00:17:28 is nothing to point at. Compare the 2 badges at the top of the map: deferred, told at the screen;
-
00:17:35 omitted, finds out at the door. Same boundary, same visitor, and the only difference is 1 written
-
00:17:41 decision with a date and an owner. The last step states it: a deferred behavior is a decision with
-
00:17:48 a date and an owner; an omitted one is a surprise waiting at the door. Let's move on to the next
-
00:17:55 scene, where short booking becomes a rule you can examine. The second anchor scene turns short
-
00:18:03 booking into a rule you can examine: 4 requests on a ruler, 29, 30, 120, and 121. The sentence so far
-
00:18:14 is keep bookings short, and it draws no line on that ruler. Decide before the reveal: which of the
-
00:18:21 4 should be accepted? Option A, only 30. Option B, 30 and 120. Option C, 30, 120 and 121. Pick one;
-
00:18:34 the examples will check your answer. My own first instinct was Option A, because 30 sounds like a
-
00:18:44 typical short booking. But the word short never said 30. Any number I pick here is my assumption
-
00:18:52 dressed as the requirement, and the reveal will show whose number it is. I press Step,
-
00:18:59 and rule R-02 appears: a booking lasts at least 30 and at most 120 minutes, inclusive. On the ruler
-
00:19:06 the green band is the rule, and both ends belong to it. R-02 carries the example assumption tag,
-
00:19:12 because the number belongs to this teaching case and not to every campus. What travels to your own
-
00:19:20 service is the shape of the rule: a lower edge, an upper edge, and the word inclusive. Step, and the
-
00:19:30 4 examples get a row each. 29 minutes: below 30, rejected. 30 minutes: inside the band, accepted.
-
00:19:39 120: inside, accepted. 121: above, rejected. The pins on the ruler turn green and red to match. 2
-
00:19:48 of these sit 1 minute outside the band, and 2 sit exactly on its ends, on purpose. A rule shows what
-
00:19:55 it means at its edges, and inclusive is a word that is easy to write and easy to get wrong in
-
00:20:03 code. Step. The rule card expands into 4 parts. Who: a signed in requester. Under what condition:
-
00:20:11 the requested duration in whole minutes, with the end later than the start. Expected behavior:
-
00:20:19 accepted when the duration is at least 30 and at most 120. And the rejection behavior: the
-
00:20:27 screen says duration must be 30 to 120 minutes, and nothing is stored. Write the rejection down
-
00:20:34 every time. A rule that only describes the happy path leaves the failure case to whoever codes it
-
00:20:42 first. Step. A proposed screen appears: a slider from 30 to 120 minutes. Notice the purple chip:
-
00:20:50 a solution, not the requirement. The rule would hold just as well with 2 time fields or a typed
-
00:20:59 duration, whichever screen is built. Keeping the rule apart from the widget is what lets you
-
00:21:05 check the widget later, on its own. If the slider allowed 121, the row in the examples table would
-
00:21:13 catch it, because the row belongs to the rule. Step, and 1 more request: start 11:00, end 10:00,
-
00:21:22 which is rejected as a malformed interval, not as a duration decision. 1 boundary rule
-
00:21:29 does not describe every validity condition, so the register needs the shape rule too. The last
-
00:21:35 step of the baseline gives the principle: a useful requirement makes meaningful differences between
-
00:21:42 acceptable and unacceptable outcomes visible. In short, a good rule shows exactly where accepted
-
00:21:49 turns into rejected. What this gives me: whenever a rule has a number, I write down the value below,
-
00:21:57 the value itself, and the value above. Then I say what happens to each. 3 examples per edge,
-
00:22:05 and the argument about inclusive is over before it starts. Now the temporary variant: I click Variant
-
00:22:12 30 to 90, and only the upper limit changes, from 120 to 90. The card says so: temporary variant,
-
00:22:21 comparison only. The band on the ruler ends earlier, so which examples change? Step,
-
00:22:29 and 3 new rows appear at the new edge of the band: 89 accepted, 90 accepted, 91 rejected. And 1 old
-
00:22:40 row flips: 120 minutes is now rejected. On the ruler the pin at 120 has turned red. Step, and the
-
00:22:50 rows at the lower end are unchanged: 29 still rejected, 30 still accepted, because the lower
-
00:22:58 limit was not touched. And the green badge says it: the canonical rule is restored, 120 minutes,
-
00:23:06 so nothing outside this comparison changed. The last step: change 1 number in the rule,
-
00:23:12 and exactly the examples at that edge change. That is how you see what a change means before anything
-
00:23:20 is built, and it is why the examples are worth writing down next to the rule. Now the thread
-
00:23:27 of the course. I click Assistant. 2 requests go to an automated assistant. Request A says keep
-
00:23:35 bookings short. Request B carries R-02: 30 through 120 minutes inclusive. The candidates below were
-
00:23:44 authored for this comparison. Step. Candidate A invents a 60 minute limit: the code returns true
-
00:23:51 when the duration is at most 60. Nobody asked for 60. The request had no number, so the candidate
-
00:23:59 supplied one, and there is nothing to judge it against. Step, and candidate B implements the
-
00:24:05 rule: the code returns true when 30 is at most the duration and the duration at most 120. The precise
-
00:24:13 request made this candidate easy to compare with the rule, line by line and number by number.
-
00:24:21 Step. A precise request still does not settle it. Here is another candidate for the same request B,
-
00:24:29 taken from week 13. Its explanation says inclusive 30 to 120, and its code says 30 at most duration,
-
00:24:40 duration less than 120. Read that last line again: less than 120. The explanation says inclusive;
-
00:24:49 the code is exclusive. A fluent sentence next to a wrong comparison is exactly the kind of draft that
-
00:24:58 passes a quick look. Step, and the independent example decides. 120 minutes must be accepted.
-
00:25:06 Candidate B accepts it; the fluent candidate rejects it. That single row is the difference
-
00:25:12 between the 2 drafts. 30 passes on both, and 121 is rejected by both, so neither of those rows can
-
00:25:22 tell the candidates apart. The row that separates them is the row at the edge, exactly where the
-
00:25:30 fluent code went wrong. The last step gives the lesson of the thread. A precise requirement makes
-
00:25:37 a draft checkable; the check still has to be made. The rule made an independent judgment possible,
-
00:25:44 and the 120 minute example made it. Let's go to the next page. Fast needs a workload and
-
00:25:52 a measurement boundary. 1 search answered in 200 milliseconds. Does that number prove the service
-
00:25:59 is fast? Think about what the number leaves out before you answer. Option A, yes, a fifth of a
-
00:26:07 second is fast. Option B, only that 1 search was. Option C, only under stated conditions. Decide
-
00:26:14 before the reveal. Option A is the answer a demo gives: 1 number, 1 smile. Option B is honest but
-
00:26:25 useless on its own. Option C is the shape of every quality requirement in this course: a number means
-
00:26:32 something only under stated conditions. I press Step, and the sample behind the number appears:
-
00:26:40 20 searches by 1 person, every one answered in 200 milliseconds. The histogram is a single bar
-
00:26:46 20 responses tall, the mean is 200 milliseconds, and the table under it lists every value. Read
-
00:26:54 the small print: these are illustrative samples from the course's latency fixture, a concept
-
00:27:01 illustration, not a load test. And notice what the sample never mentions: other people, other data,
-
00:27:08 a busy hour. 1 user, 1 afternoon, 1 number. Step, and the requirement, Q-01, appears with 3 chips:
-
00:27:17 threshold, workload, boundary, 1 for each part. Under the teaching fixture, the 95th percentile of
-
00:27:25 search response time is at most 500 milliseconds under 50 concurrent users, measured at the search
-
00:27:32 API. Q-01 carries the example assumption tag as well: it is an authored target for this course,
-
00:27:38 not a universal service standard. Your service will have its own number. What travels between
-
00:27:44 services is the shape: a percentile, a threshold, a workload, a boundary. Step, and now compare what
-
00:27:53 was measured with what was claimed: measured, 1 user; claimed, 50 concurrent users. The red
-
00:27:59 chip says it plainly: not evidence for Q-01 yet. The sample answers a different question,
-
00:28:07 and nobody should quote it for this one. Step. The boundary. The measured span is the search API and
-
00:28:14 its storage, highlighted in yellow. The browser and the network are outside it, faded. A viewer's
-
00:28:22 whole experience is longer than the number, and the requirement says which span it means. Why
-
00:28:28 does the boundary matter? 2 teams can both say 500 milliseconds and disagree by a second. 1 measured
-
00:28:34 at the API, the other in the browser. Naming the span is what makes their 2 numbers comparable.
-
00:28:41 Step. The names other engineers use, from the ISO 25010 standard, 2023 edition. Response time
-
00:28:50 is performance efficiency, and keyboard accessible completion is interaction capability. Same ideas,
-
00:28:57 shared words. The last step of the baseline: threshold, percentile, workload, boundary; remove
-
00:29:04 any one of them and fast is a feeling again. The principle: a quality requirement needs observable
-
00:29:10 acceptance, a boundary, and stated conditions, all 3 of them. As a student I would test myself
-
00:29:18 with 1 sentence: the search must be fast. Which of the 4 is missing? All 4. That sentence is a wish,
-
00:29:26 and Q-01 is what the wish looks like after someone asked the 4 questions. Now change only
-
00:29:33 the workload: I click 50 users, and the sample becomes 50 concurrent users with 20 responses. 18
-
00:29:41 at 100 milliseconds and 2 at 1100: a tall bar on the left and a small one far right. Step, and the
-
00:29:49 mean is still 200 milliseconds. But the nearest rank 95th percentile, the 19th sorted value of 20,
-
00:29:57 is 1100 milliseconds. That is above 500, so under the stated workload, Q-01 is not met at all. The
-
00:30:06 last step: the average hid the 2 slow responses, and the percentile with its conditions did not.
-
00:30:14 Stating the workload is what made the difference visible. If you only remember 1 thing from this
-
00:30:21 scene, remember that averages hide tails. I click Keyboard path, because not every quality is a
-
00:30:30 number. Rule R-05 asks whether the core task can be completed by keyboard, with perceivable status.
-
00:30:38 On the left is the booking screen, used by Ari with the keyboard alone, and nothing else. Step:
-
00:30:46 Tab, and the focus ring lands on the room list, so the list is reachable by keyboard.
-
00:30:52 Step: Tab again, and it lands on the time fields, reachable too. The keys pressed are listed under
-
00:30:58 the screen as we go. Step: Tab, and the focus ring lands on the Reserve button, because it
-
00:31:04 is a real button. Step: Enter, and the screen shows Confirmed. The status message is announced,
-
00:31:11 so the outcome is perceived without looking at a color. The last step compares the 2 requirements.
-
00:31:18 Q-01 accepts by a number: a percentile under a workload at a boundary. R-05 accepts by an
-
00:31:27 outcome: reachable and understandable, yes or no. Both are observable, and that is what makes
-
00:31:34 both of them requirements. So fast means nothing without a workload, a boundary and a threshold,
-
00:31:41 and accessible means something precise when you can walk the path and name the outcome. Let's move
-
00:31:47 on to a precise requirement that still describes the wrong thing. A precise requirement can still
-
00:31:54 describe the wrong thing: here a system enforces a 30 minute maximum, because someone wrote 30
-
00:32:01 where 120 was meant. 3 parts sit across the top of the page: the need, the written statement,
-
00:32:08 and the observed behavior. The need is still hidden on purpose; the statement says booking
-
00:32:16 duration is at most 30 minutes, and the behavior says every request over 30 is rejected. Decide:
-
00:32:24 would checking the system against its written statement catch the transcription mistake? Think
-
00:32:31 before the reveal. Read the question carefully: it asks about checking the system against its written
-
00:32:39 statement, and nothing else. The statement says 30 and the system enforces 30, so ask yourself what
-
00:32:47 a check would compare, and whether 120 appears anywhere a check can see. I press Step and run the
-
00:32:55 checks. 30 minutes: the statement says accepted, the system accepts, match. 31: rejected, rejected,
-
00:33:03 match. 120: rejected, rejected, match. Every verification check passes. The system is exactly
-
00:33:10 what the statement says. Step, and the need appears. Ari asked for a 2 hour study session in
-
00:33:17 C101 from 10:00 to 12:00, so 120 minutes must be accepted. The intended statement was at most 120,
-
00:33:26 and someone wrote 30. That is the whole error: 1 number, copied wrong, and every check so far
-
00:33:33 compared the system with the wrong number. Look at the new row: 120, the need says accepted,
-
00:33:42 the system rejects, mismatch. And the red cross between the need and the statement. The mismatch
-
00:33:49 sits between the need and the words, exactly where no check looked. Step. Feature delivered, outcome
-
00:33:56 missed. Every reservation is short, and the 2 hour session is impossible. A feature can be delivered
-
00:34:03 exactly and still miss the outcome the person needed. Shortening every reservation satisfies
-
00:34:09 the written limit and makes a useful session impossible. Step, and the remedy: before accepting
-
00:34:16 a specification, compare the proposed behavior with 1 concrete stakeholder example. Here that
-
00:34:24 example is 120 minutes, and it would have failed on the first read. 1 example, 5 minutes, and the
-
00:34:31 whole mistake is gone. Step. 1 line to keep the scene honest: the fairness policy stays an open
-
00:34:38 decision, and this scene selects no policy. 1 transcription error is enough to carry the lesson,
-
00:34:45 so nothing else changes here. The last step names 2 questions, not 1. Verification: does the system
-
00:34:53 match its written description? Validation: does the description match the need? Real practice
-
00:35:00 mixes them, and both are needed; the first one alone passed every check here. The principle:
-
00:35:06 question both whether the system matches its description and whether the description matches
-
00:35:12 the need. In short, check the system against the words, and the words against the need. The habit
-
00:35:19 I take: before I accept any requirement, I ask the person for 1 example and run it through the
-
00:35:26 words by hand. It takes a minute, and it is the only check that sees the gap between the need and
-
00:35:33 the sentence. Now the changed condition: I click Correct the words, and the statement becomes the
-
00:35:40 intended rule: booking duration is 30 through 120 minutes inclusive, R-02. The implementation
-
00:35:47 is untouched, and it still rejects every single request over 30 minutes, exactly as before. Step,
-
00:35:56 and the same checks run again. 31 minutes: the corrected statement says accepted,
-
00:36:02 the system rejects, mismatch. 120: accepted, rejected, mismatch. Now verification fails,
-
00:36:10 visibly, and the fix has a place to go. The last step: correcting the words moved the
-
00:36:17 mismatch to where checks can see it, and that is the whole point. Validation fixed the description;
-
00:36:25 verification will now drive the implementation. Next, a requirement should lead somewhere,
-
00:36:31 so let's open the traceability matrix. The third anchor scene: a requirement should lead somewhere.
-
00:36:39 We start from R-01 and an empty matrix. 1 row, 3 empty cells: design decision, examples, checks.
-
00:36:48 A matrix is a table whose blanks are visible, and that is the whole point of it. Decide before
-
00:36:54 the reveal: what connects R-01, the rule of no overlapping confirmations, to an implementation?
-
00:37:01 Option A, the code that checks overlaps. Option B, a decision, examples and a check. Option C,
-
00:37:10 a test that passes. Options A and C are real, and both are outputs: the code and the test
-
00:37:19 exist because somebody decided where the rule lives and which cases define it. Left unwritten,
-
00:37:26 those decisions leave the code as the only record, and code can never say why. I press Step,
-
00:37:34 and the design decision appears in the first cell: an authoritative conflict decision at the
-
00:37:41 booking boundary. The decision is where the rule is enforced, and there is exactly 1 such place,
-
00:37:48 which is what week 1's 2 confirmations taught us. Step. The examples: C101 from 10:00 to 11:00
-
00:37:57 against 10:30 to 11:30 conflicts. 11:00 to 12:00 is adjacent and allowed. And C202 at the same time
-
00:38:06 is allowed. 3 boundary cases, the adjacent one included. Step. The checks: an interval predicate
-
00:38:13 check, and a concurrent request check at the storage boundary. The second one is the check
-
00:38:19 that the single example of week 1 could not stand in for: 2 people in the same instant. Step adds
-
00:38:28 a second row, R-03, cancellation authorization. The decision: ownership is read from the stored
-
00:38:34 booking, not from the request. The request can claim anything; the stored booking knows who
-
00:38:39 made it. The examples: U-01 cancels their own future booking, allowed. U-02 cancels B-001,
-
00:38:48 denied. U-01 cancels at 10:00, denied, because the booking has started. 1 check: the authorization
-
00:38:56 matrix check. Step adds a third row, R-02 from scene 3: the whole minute duration validated once,
-
00:39:04 at the request boundary. Then the 4 boundary examples, and 1 duration boundary check. 3 rows,
-
00:39:11 12 cells, and every cell answers a question. The cells are clickable: I click R-03, and its whole
-
00:39:19 row lights up, all its cells at once. The chain card below spells it out: R-03, the decision,
-
00:39:26 3 examples, 1 check. I click it again to release it. Step. Why a matrix and not a pipeline diagram?
-
00:39:33 Coverage is a question about rows and blanks, and a blank cell is visible here. A pipeline shows
-
00:39:41 movement; a matrix shows what is missing. And its limit, the faded row at the bottom: R-?, no row.
-
00:39:50 A requirement nobody wrote has no row. A matrix shows the links it has, not the ones it lacks,
-
00:39:57 so it never proves completeness on its own. The last step gives the principle: each cell answers
-
00:40:05 1 question. Where is this enforced, which cases define it, what would show it broke. Traceability
-
00:40:11 makes relationships inspectable, and a link is useful only when its meaning and evidence
-
00:40:18 are current. If I were starting a project, the matrix would be a table in the repository, 1
-
00:40:25 row per identifier, filled as decisions are made. Not for an auditor: for the day someone asks why
-
00:40:32 the code checks the stored booking and not the request. Now the matrix does what it is best at,
-
00:40:40 so I click Variant, delegated cancel, at the top. A proposed change to R-03: a delegated staff role
-
00:40:49 may cancel under a recorded reason. Nothing is decided yet; the matrix shows what it would
-
00:40:55 touch. Step. Genuinely dependent on R-03: the R-03 decision, the cancellation decision table,
-
00:41:02 and the authorization matrix check. Each of those cells gets a yellow chip, needs review,
-
00:41:09 with a symbol and a word, not only a color. Step, and now the unaffected cells: the duration
-
00:41:16 checks and the interval checks, marked green and unchanged. They do not depend on who may cancel,
-
00:41:24 so they stay exactly as they are; that is the answer to check 4 on the principles page.
-
00:41:30 The last step: the variant is marked as requiring a stakeholder decision. The matrix shows what a
-
00:41:36 decision would cost, 3 cells to review and 2 to leave alone, and the decision belongs to the
-
00:41:42 stakeholders. Next page. The loudest request is not automatically the next one. 3 requests wait:
-
00:41:52 correct duplicate confirmations, add decorative room photos, and make cancellation work by
-
00:41:58 keyboard. Decide before the reveal: which should come next? My instinct says P1,
-
00:42:08 because a duplicate confirmation is a bug and bugs come first. But instinct is not a reason anyone
-
00:42:14 else can check. The table that appears next is how a team turns instinct into an argument. I press
-
00:42:22 Step, and the columns light up: user benefit, dependency, uncertainty, consequence of waiting,
-
00:42:30 effort. 5 columns of information, and none of them is a score. Each is a fact or a judgment you can
-
00:42:38 read and argue with. Step. P1, correct duplicate confirmations. Benefit: 1 confirmed booking per
-
00:42:45 room and hour, R-01, so nobody meets a stranger at the door. Dependency: the shared booking decision
-
00:42:52 from week 1. Uncertainty: low, the cause is known. Consequence of waiting: 2 people at 1 door for
-
00:43:02 every overlap that slips through. Effort: medium. Every cell is a sentence someone can dispute,
-
00:43:10 and that is the point of writing them. Step. P2, decorative room photos. Benefit: a nicer screen,
-
00:43:18 and no task completes sooner. Dependency: room records must supply the photos. Uncertainty:
-
00:43:24 medium, because who owns the photos is not settled. Consequence of waiting: none for any
-
00:43:30 booking outcome. Effort: small to medium. Step. P3, cancellation by keyboard, rule R-05. Benefit:
-
00:43:38 keyboard users can cancel at all. Dependency: the cancellation screen, R-03. Uncertainty: low,
-
00:43:46 the route is known from the keyboard walk through. Consequence of waiting: a room stays booked by
-
00:43:52 someone who cannot cancel it, and nobody else can book it. Effort: small. Small effort and a real
-
00:43:58 exclusion removed is a combination worth noticing. Step, and the order appears: P1, then P3, then P2.
-
00:44:07 P1 removes a broken promise and keeps R-01. P3 is small and removes an exclusion. P2 changes no
-
00:44:15 outcome and waits for the photo owner. No number produced this order; the reasons did, and they
-
00:44:22 are on the table for anyone to argue with. Notice that the loudest request, the photos, came last,
-
00:44:30 and not because photos are bad in themselves. The consequence of waiting for them is none,
-
00:44:36 while waiting on P1 costs 2 people at a door every time an overlap slips through. The last step gives
-
00:44:44 the principle: the table did not rank features; it laid out consequences and dependencies so that a
-
00:44:51 choice could be explained. Priority is a reasoned choice under constraints, not a permanent property
-
00:44:57 of a feature. As a student I notice what is absent from this table: no priority number, no score,
-
00:45:04 no vote. When someone at work asks why the photos wait, I can point at a cell instead of a feeling,
-
00:45:12 and they can argue with the cell. Now 1 condition changes: I click Closure tomorrow,
-
00:45:18 and in this fictional scenario a room closure is scheduled for tomorrow. Recording closures itself
-
00:45:27 stays an open need until week 14. A new column appears on the right: urgency; the 5 other columns
-
00:45:34 keep every word. Step, and the urgency column fills: P1 unchanged, P2 unchanged, and P3 rises,
-
00:45:43 because people must cancel and rebook before tomorrow, keyboard users included. The benefit,
-
00:45:49 dependency, uncertainty and effort cells did not move by a single word, which is the point. The
-
00:45:58 last step: the new order is P3, then P1, then P2. Only urgency changed. When the closure passes, the
-
00:46:06 urgency column empties and the old order returns, because nothing else about the requests changed.
-
00:46:13 Next page. When the rule changes, what happens to its evidence? R-02 version 1 is on the left:
-
00:46:22 booking duration is 30 through 120 minutes inclusive, decided on the 8th of September by
-
00:46:30 the room policy owner. The dates and the owner are fictional, but the shape is what you will meet at
-
00:46:36 work. A statement, a decision date, and a person who can answer for it. On the right, 6 pieces
-
00:46:43 of linked evidence, all current. 4 examples: 29 rejected, 30 accepted, 120 accepted, 121 rejected,
-
00:46:53 each one a row. And 2 checks: the duration boundary check, and the interval overlap check
-
00:46:59 from R-01. Every row says current on the right. Decide before the reveal. The rule changes after
-
00:47:07 the checks were written. What happens to them? Option A, delete them and start over. Option B,
-
00:47:14 nothing, they passed. Option C, revise the ones whose meaning changed. Option A throws away
-
00:47:22 evidence that may still be true. Option B keeps checks that may now prove the wrong thing, and a
-
00:47:29 wrong check passes quietly. Option C costs a read of every link, and only there does the evidence
-
00:47:36 keep its meaning. I press Step, and version 2 of the rule appears: booking duration is 30 through
-
00:47:44 90 minutes inclusive. The rationale sits next to it: more people need rooms in the afternoon peak,
-
00:47:51 so shorter sessions let more fit. Decided on the fourteenth of October. 2 things to notice:
-
00:47:58 the card is labeled scenario, because the course's canonical R-02 stays 30 through 120;
-
00:48:06 this is a change management exercise. And version 1 is still on screen, faded, marked history;
-
00:48:14 it did not disappear, and it should not. Step. The linked examples: 29 current, 30 current,
-
00:48:22 121 current, and 1 row turns red. 120 accepted is stale: under the new rule 120 minutes must
-
00:48:32 be rejected. Only the example at the old edge is affected. Step. The linked checks. C1 is stale:
-
00:48:40 the upper bound in the duration check must change. C2 is current: interval overlap never depended on
-
00:48:47 the maximum duration. 2 stale items among 6, and the other 4 keep proving what they proved before.
-
00:48:55 Step, and what travels together: the new wording, in place; its rationale, written next to it;
-
00:49:02 a dated decision with an owner. Then E3 revised; C1 rewritten; and the old wording kept as history.
-
00:49:12 Nothing on this screen pretends to be current. The last step gives the principle: a change is
-
00:49:20 not simply a new sentence on its own. It is the sentence, the reason for it, and the evidence
-
00:49:26 that must move with it. Manage the meaning of a change, its rationale, and its evidence together.
-
00:49:33 What I take to work: a change is a small package, not a sentence in a chat. New wording, the reason,
-
00:49:42 a date and an owner, and the examples and checks I reread. If I cannot list the evidence,
-
00:49:48 I cannot know what it touches. Now a different kind of request. I click Wording only. A booking
-
00:49:55 lasts at least 30 and at most 120 minutes, both inclusive. Same behavior, clearer sentence. The
-
00:50:03 rationale: the words through 120 inclusive were misread twice in review. Step. Check the meaning
-
00:50:11 before reacting: every linked example gives the same outcome under the new sentence, so all 6
-
00:50:18 items stay current. Look at the right column: current, current, current, all the way down.
-
00:50:24 Examples unchanged, checks unchanged, history note kept. The last step: a semantic change and
-
00:50:31 an editorial change look alike in a diff and mean different things. Judge the meaning, then decide
-
00:50:39 what to revise. Changing the rule, its reason and its evidence in 1 move is the habit; reacting
-
00:50:45 mechanically is not. That was the last of the 8 scenes. What is left is the register that collects
-
00:50:52 everything this lecture wrote, the principles, and the handoff to week 3. I click the next page. The
-
00:51:00 requirement register of this lecture. 6 statements with identifiers that reappear in later weeks,
-
00:51:06 4 open items kept visible, and 3 sentences that are not requirements at all. The kind
-
00:51:12 column is hidden for now. Read the rows. R-01: no overlapping confirmed bookings for the same room,
-
00:51:19 with its interval example. R-02: 30 through 120 minutes, with the 6 duration examples. R-03:
-
00:51:28 an authenticated requester cancels only their own future booking. R-04: a notification failure does
-
00:51:36 not undo a confirmed booking, and the pending message stays visible. R-05: the core task can
-
00:51:44 be completed with the keyboard, with perceivable status. And Q-01: the search response time, with
-
00:51:51 threshold, workload and boundary named. Look at the status column. R-01, R-02 and R-03 are stated,
-
00:51:59 example backed and traced, and R-03 adds that delegated cancellation is an open variant.
-
00:52:06 R-04 and R-05 are stated and example backed, and R-05's acceptance is categorical. Q-01 is stated,
-
00:52:15 with its conditions named, and not yet checked under those conditions. Every status is honest
-
00:52:22 about what exists, and an honest status is what lets week 3 start from the right place. Below
-
00:52:29 them the 4 open items: the fairness policy, a decision the stakeholders owe. Easy for whom,
-
00:52:36 an open quality question. Visitors, deferred with a date and an owner. And room closures, open until
-
00:52:44 week 14. They stay visible so nobody forgets them. Now I click Reveal the kinds. Behavior,
-
00:52:51 behavior, business rule, behavior, quality for accessibility, quality target. And the card on the
-
00:52:57 right explains the 4 kinds: what the service does, how well, who may do what, and how to build it.
-
00:53:05 Why does R-03 count as a business rule? Because it is a policy the organization sets about who may do
-
00:53:12 what, not a behavior of the software alone. If the organization decides differently, the
-
00:53:19 software follows. That is exactly the variant from the matrix. I click What is not a requirement,
-
00:53:26 and 3 sentences appear. Use Framework X to make booking fast: a solution choice mixed with a vague
-
00:53:33 quality objective. Use a relational database: an implementation decision. And a slider for
-
00:53:41 the duration: a screen design. That first sentence is check 1 on the next page. It mixes a solution
-
00:53:49 choice with an underspecified quality objective. The way through: name the needed outcome and its
-
00:53:57 conditions separately, then record the framework as a decision next to the requirement it serves.
-
00:54:04 1 more note: identifiers stay stable. R-01 in week 3 is the R-01 of this table, and R-02 in week 8
-
00:54:12 is checked by the examples you saw today. Let's go to the principles page. 8 principles, 1 per scene,
-
00:54:20 and 6 checks. Principle 1: ambiguity is resolved through examples and stakeholder decisions,
-
00:54:26 not through more confident wording. In short, confident wording settles nothing; examples
-
00:54:32 and decisions do. Principle 2: an explicit boundary and an open question register make
-
00:54:38 uncertainty discussable. Principle 3: a useful requirement makes meaningful differences between
-
00:54:44 acceptable and unacceptable outcomes visible. A good rule shows where accepted turns into
-
00:54:51 rejected. Principle 4: a quality requirement needs observable acceptance, a boundary, and stated
-
00:54:58 conditions. Principle 5: question both whether the system matches its description and whether
-
00:55:04 the description matches the need. Principle 6: traceability makes relationships inspectable,
-
00:55:10 and a link is useful only when its meaning and evidence are current. Principle 7: priority
-
00:55:16 is a reasoned choice under constraints, not a permanent property of a feature. Principle 8:
-
00:55:22 manage the meaning of a change, its rationale, and its evidence together. Now the 6 checks;
-
00:55:29 decide your answer before I open each one. Question 1: is use Framework X to make booking
-
00:55:37 fast a clear behavior requirement? I click it. It mixes a solution choice with an underspecified
-
00:55:43 quality objective; define the needed outcome and conditions separately. Question 2: should a
-
00:55:50 120 minute booking satisfy R-02? I click, and the answer is yes. The upper limit is inclusive, and
-
00:55:57 the other validity and availability checks still apply. That is the row at the edge from scene
-
00:56:04 3. Question 3: what is missing from search must finish in 500 milliseconds? Click. At least the
-
00:56:12 measurement boundary, the workload, the proportion or percentile, and the conditions. Scene 4 in 1
-
00:56:19 sentence. Question 4: what does selecting R-03 in the matrix tell us? Click. Which decisions and
-
00:56:26 checks are linked to cancellation authorization; those links need review when the rule changes.
-
00:56:34 Question 5: does supplying R-02 to an assistant guarantee that its candidate is correct? Click.
-
00:56:41 No. The explicit rule makes an independent judgment possible; the inclusive boundary
-
00:56:47 still needs to be checked. Question 6 leaves room booking behind. A desktop editor request says save
-
00:56:55 my work safely. What must be clarified before choosing autosave? Think about it for a second,
-
00:57:02 then I open the answer. Click. Clarify what counts as saved, the acceptable loss after
-
00:57:10 an interruption, the recovery feedback, and the overwrite behavior. Choose an observable recovery
-
00:57:16 example with the user. Autosave is a possible design, not the requirement itself. Notice how
-
00:57:23 the editor question has the same shape as fair and easy: 1 wish, several missing decisions,
-
00:57:29 and a solution hiding inside the request. The principles carry across; only the domain changes.
-
00:57:35 Now the last page. What carries forward, and where to read more. Week 3 starts from this question:
-
00:57:44 does a written rule alone make booking, cancellation and failure states understandable?
-
00:57:50 Read it twice, because it is exactly the question that the models of week 3 will answer. 3 things
-
00:57:57 are carried forward. The requirement register: R-01 to R-05 and Q-01, each with an acceptance
-
00:58:04 example and a stable identifier. The traceability matrix: R-01, R-02 and R-03 linked to a decision,
-
00:58:12 examples and checks. And the open items, kept visible: the fairness policy, easy for whom,
-
00:58:20 visitors deferred, and room closures until week 14. An open item written down is progress;
-
00:58:26 an open item forgotten is next month's incident. In practice, in 2026, requirements live as issues
-
00:58:33 or user stories in GitHub Issues, Jira or Azure Boards. Acceptance examples are
-
00:58:39 often written as Given When Then scenarios, and tools such as Cucumber or pytest-bdd
-
00:58:47 run them as checks. The middle card lists 13 terms, starting with requirement: a statement of
-
00:58:54 what the service must do or keep true, checkable by an example. Then behavior, quality requirement,
-
00:59:01 business rule, and implementation decision, which are the 4 kinds from the register page. Then
-
00:59:09 elicitation, scope, assumption and acceptance example, the words of scenes 2 and 3, in that
-
00:59:16 order. Traceability, verification and validation, the words of scenes 5 and 6. And priority,
-
00:59:24 the reasoned order of scene 7. On the right are the 4 sources. The Software Engineering Body of
-
00:59:30 Knowledge and the Computer Science Curricula 2023; the Web Content Accessibility Guidelines
-
00:59:36 version 2.2; and the ISO 25010 quality model. So that is lecture 2. Ask what a word means before
-
00:59:44 you build it, and write the examples next to the rule. Give every quality a workload,
-
00:59:51 a boundary and a threshold, or an outcome you can name. Check the system against the words
-
00:59:56 and the words against the need, and keep the links current. Order the work with reasons, and move a
-
01:00:03 change with its rationale and its evidence. Thank you for watching, and I will see you in week 3.