Repository navigation
Serving
🏠 Home · 🧭 Choose a method · 🚀 Quickstart · 🧰 Help
On this page
- Overview
- 🧭 Choose the service boundary
- 🚀 Use it: a loopback smoke service
- Workflow at a glance
- Installation and version boundaries
- 🔬 Go deeper: HTTP contract and engine adapters
- Built-in OpenAI-like HTTP server
- External-runtime checkpoint compatibility
- vLLM integration
- SGLang integration
- Tokenizer, OpenAI, and environment compatibility notes
- Implementation map
- Pitfalls and operational checklist
- Source files
- See also
Choose how your application reaches a quantized model: a small local HTTP endpoint or an in-process external engine. For: developers moving from a working generation call to a service.
GPT-QModel has three distinct serving/inference integration paths:
| Path | What GPT-QModel provides | What it does not provide |
|---|---|---|
model.serve() |
A small FastAPI/Uvicorn HTTP shim around an already-loaded model's generate(), with optional bearer-token authentication and a chat.completion response shape. |
Streaming/SSE, an engine scheduler or request batching, TLS configuration, and the rest of the OpenAI API surface (/v1/models, text completions, embeddings, Responses). |
BACKEND.VLLM |
Checkpoint loading into a vLLM LLM, HF-style sampling conversion, prompt/token handling, and a token-tensor result adapter. |
Starting vLLM's HTTP server or full compatibility with every HF generation kwarg. |
BACKEND.SGLANG |
Checkpoint loading into SGLang Engine or legacy Runtime, runtime-option normalization, prompt/token handling, and text extraction. |
Starting SGLang's HTTP server or making legacy Runtime support every Engine feature. |
The external backends are in-process runtime integrations. Their engines' own HTTP servers are separate entry points. A checkpoint that loads with a native GPT-QModel kernel is not automatically supported by either external engine.
This page follows source revision 13ee428f2. Loading and Inference covers the common load API; Inference Backends covers backend selection.
| Need | Choose this when | Consider another path when |
|---|---|---|
| Small local HTTP integration |
model.serve() has the endpoint/auth shape you need |
You need streaming, batching, request scheduling, TLS configuration, or a complete OpenAI API |
| vLLM inside Python | Your format/runtime satisfies the vLLM adapter gates | You want HTTP serving; use that engine's own server separately |
| SGLang inside Python | Your format/runtime satisfies the SGLang adapter gates | You expect HF-compatible token-tensor output; this adapter returns text |
Before serving: successfully load and generate from the same saved checkpoint/backend; install the selected optional extra in its own compatible environment; and decide where authentication/network exposure belongs. Native GPT-QModel support does not qualify an external engine. NVIDIA CUDA and AMD ROCm must each satisfy the engine's device/kernel requirements; the presence of Triton is not enough.
Start with the minimal example below. It binds 127.0.0.1:8000 and uses the small built-in shim, not an engine scheduler. Keep loopback binding for a first test. For non-loopback exposure, configure api_key= and a trusted service boundary; bearer authentication alone is not TLS or rate limiting. Supply keys securely in application configuration, never committed examples.
from gptqmodel import GPTQModel

model = GPTQModel.load(
    "ModelCloud/Llama-3.2-1B-Instruct-gptqmodel-4bit-vortex-v2.5",
    device="cuda:0",
)
model.serve(host="127.0.0.1", port=8000, async_mode=True)
model.serve_wait_until_ready(timeout=30)

# Keep the owning process alive while serving.
# Call model.serve_shutdown() when the service should exit.
curl http://127.0.0.1:8000/v1/chat/completions \
-H 'Content-Type: application/json' \
-d '{
"model": "local-model",
"messages": [{"role": "user", "content": "What is quantization?"}],
"max_tokens": 64,
"temperature": 0.0,
"n": 1
}'The request's model field is optional and does not select a model. The server owns one loaded model, and the response uses model.config.name_or_path captured at server construction.
From another terminal while the service is running:
curl --fail http://127.0.0.1:8000/health
curl --fail http://127.0.0.1:8000/v1/chat/completions \
  -H 'Content-Type: application/json' \
  -d '{"messages":[{"role":"user","content":"Name the capital of France."}],"max_tokens":16}'
These calls assume no API key in the loopback demo. If configured, add your bearer token without putting it in shared shell history or logs. Health is intentionally unauthenticated. A healthy response is readiness evidence, not throughput/quality qualification. A chat.completion response shape does not imply support for other OpenAI endpoints or streaming.
For a background application, use async_mode=True, wait with serve_wait_until_ready(...), and pair its lifetime with serve_shutdown(). Synchronous serving blocks. See the endpoint/auth tables below before changing binding, request sizes, or shutdown behavior.
Next: checkpoint compatibility, quality validation, or the built-in limitations.
Public source for this guide: gptqmodel/utils/openai_server.py · gptqmodel/utils/vllm.py · gptqmodel/utils/sglang.py · docs/openai-server-exposure.md. Examples and declarations target revision 13ee428f2; older pinned citations below retain their original evidence scope.
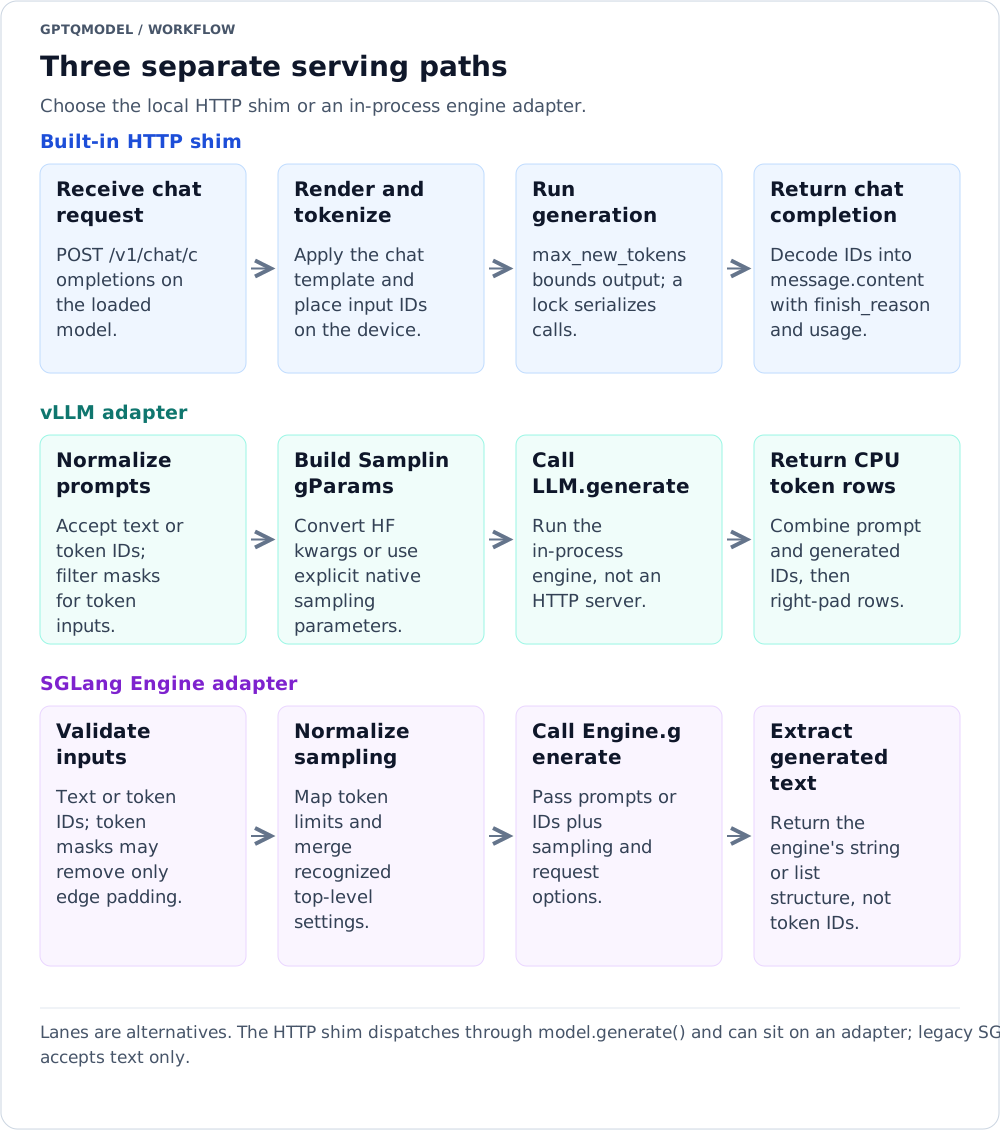
Reading the diagram: Lanes are alternatives. The HTTP shim dispatches through model.generate() and can sit on an adapter; legacy SGLang Runtime accepts text only.
Text version of the workflow
-
Built-in HTTP shim: Receive chat request → Render and tokenize → Generate under a single-entry lock → Return
chat.completionchoices. - vLLM adapter: Normalize prompts → Build SamplingParams → Call LLM.generate → Return CPU token rows.
- SGLang Engine adapter: Validate inputs → Normalize sampling → Call Engine.generate → Extract generated text.
The optional dependencies are declared in pyproject.toml. Engine extras have their own Torch/Transformers constraints; the project explicitly recommends a dedicated environment for them.
| Component | Declared extra/dependencies at this revision | Missing-package behavior |
|---|---|---|
| Built-in HTTP server |
openai: uvicorn>=0.54.0, fastapi>=0.161.1, pydantic>=2.14.1
|
Import raises with pip install gptqmodel[openai] --no-build-isolation. |
| vLLM |
vllm>=0.31.0 for Python <3.11; vllm>=0.32.0 for Python >=3.11,<3.15
|
Adapter raises ValueError with installation/import diagnostics. Its missing-install hint is pip install -U vllm. |
| SGLang |
sglang[srt]>=0.5.21 for Python <3.11; sglang[srt]>=0.5.22 for Python >=3.11
|
Adapter raises ValueError with diagnostics. Its missing-install hint is pip install -U 'sglang[srt]'. |
| GPT-QModel Python | >=3.10 |
Each engine can further restrict supported interpreters/platforms. |
| Tokenizer normalization | Core tokenicer>=0.0.14
|
Checkpoint tokenizer construction routes through Tokenicer. |
# Choose the extra for the intended environment.
pip install 'gptqmodel[openai]' --no-build-isolation
# In dedicated engine environments, as appropriate:
pip install 'gptqmodel[vllm]' --no-build-isolation
pip install 'gptqmodel[sglang]' --no-build-isolation
Neither adapter imposes a single global CUDA/ROCm version or hardware architecture floor. The installed engine build, its quantization implementation, and the checkpoint/model architecture determine support. Match the engine's PyTorch/CUDA or ROCm build; importing an installed but incompatible engine is not equivalent to the package being absent. MLX is a different backend, not a replacement implementation of vLLM/SGLang: see MLX Apple Silicon.
These paths have different input/output types and independent format/dependency gates. Read the relevant adapter section before reusing HF generation kwargs or putting the endpoint behind a public service.
BaseQModel exposes:
def serve(self,
           host: str = "127.0.0.1",
           port: int = 80,
           async_mode: bool = False,
           api_key: Optional[Union[str, List[str]]] = None):

def serve_shutdown(self):

def serve_wait_until_ready(self, timeout: int = 30, check_interval: float = 0.1):
OpenAiServer takes the key at construction and has a different asynchronous default:
def __init__(self, model, api_key: str = None, allowed_hosts: list = None):

def start(self, host: str = "127.0.0.1", port: int = 80, async_mode: bool = True):

def shutdown(self):

def wait_until_ready(self, timeout: int = 30, check_interval: float = 0.1):| Option |
model.serve() default |
Meaning |
|---|---|---|
host |
"127.0.0.1" |
Loopback bind. Non-loopback listeners require a configured API key. |
port |
80 |
Listening port; choose a non-privileged port such as 8000 when appropriate. |
async_mode |
False |
False runs Uvicorn synchronously and blocks; true starts a non-daemon thread. |
api_key |
None |
Bearer key or list of keys for the inference routes. None falls back to GPTQMODEL_OPENAI_API_KEY; an explicit empty list disables authentication even when the variable is set. Blank entries are dropped. |
Readiness timeout
|
30 seconds |
Deadline waiting for uvicorn_server.started. |
Readiness check_interval
|
0.1 seconds |
Poll interval for that flag. |
These are Python method arguments. openai_server.py does not define a standalone CLI flag parser, worker-count option, or TLS configuration API. Uvicorn is constructed with log_level="info".
When at least one key is configured, a pure-ASGI AuthenticationMiddleware requires Authorization: Bearer <key> on every path under /v1, /v2, and /inference; failures return 401 with WWW-Authenticate: Bearer. /, /health, and CORS OPTIONS preflight stay open. Keys are SHA-256 digested before a constant-work secrets.compare_digest loop, so neither key length nor which entry matched is exposed. OpenAiServer.start() refuses a non-loopback bind without a key, raising ValueError before Uvicorn starts.
Loopback listeners accept only Host names localhost, 127.0.0.1, and ::1 by default, protecting against DNS rebinding. An explicitly authenticated non-loopback bind accepts any host by default. Direct OpenAiServer(..., allowed_hosts=[...]) construction can narrow that policy; model.serve() does not expose that constructor argument. Bodies larger than 1 MiB, including chunked bodies without a declared length, receive HTTP 413.
GET /shutdown is privileged: with keys configured it accepts only a valid bearer token; without keys it accepts loopback callers only, because any browser page open on the host could otherwise issue a cross-site GET. Other callers get HTTP 403.
| Method/path | Behavior |
|---|---|
POST /v1/chat/completions |
Render messages with the tokenizer's chat template, generate under a single-entry lock, decode continuation tokens, and return chat.completion choices with finish_reason and usage. Bearer-guarded when keys are configured. |
GET / |
Returns {"message": "GPT-QModel OpenAI Compatible Server is running."}. It is not a generation/warmup check. |
GET /health |
Unauthenticated liveness probe returning {"status": "ok"}; deliberately outside the guarded prefixes. |
GET /shutdown |
Calls shutdown() and returns {"message": "Server is shutting down..."} after the authentication policy above. |
The module does not register /v1/models, /v1/completions, embeddings, Responses API, or streaming/SSE routes. FastAPI's framework-provided documentation routes are not additional inference APIs.
The nested Pydantic model in setup_routes() is:
class OpenAiRequest(BaseModel):
    model_config = {"extra": "forbid"}

    model: str = ""
    messages: list = Field(default_factory=list, max_length=256)
    max_tokens: int | None = Field(default=None, ge=1, le=4096)
    max_completion_tokens: int | None = Field(default=None, ge=1, le=4096)
    temperature: float = Field(default=0.0, ge=0.0)
    top_p: float = 1.0
    n: int = Field(default=1, ge=1, le=16)
    stop: list | str | None = None
    stream: bool = False
seed: int | None = None| Field | Default | Use |
|---|---|---|
model |
"" |
Schema field only; not used for routing. |
messages |
[] |
At most 256 entries; passed directly to apply_chat_template. An empty list returns HTTP 400. No strongly typed OpenAI message/content schema is defined here. |
max_tokens |
None |
Range 1–4096 when supplied. The effective generation budget is 256 when neither token-budget field is set. |
max_completion_tokens |
None |
Range 1–4096; takes precedence over max_tokens and becomes max_new_tokens. |
temperature |
0.0 |
Nonzero selects do_sample=True and forwards temperature/top_p; zero selects greedy generation. |
top_p |
1.0 |
Passed to generation only when do_sample is true. |
n |
1 |
Range 1–16; passed as num_return_sequences. n != 1 with temperature=0 is rejected with HTTP 400 because Transformers refuses multiple greedy sequences. |
stop |
None |
String or list of strings; empty entries are dropped. Native generation gets stop_strings plus the tokenizer; runtime adapters get the OpenAI-style stop argument. Matched text is trimmed from the response. |
stream |
False |
False is accepted; True returns HTTP 400 because streaming is not implemented. |
seed |
None |
Forwarded to external runtime adapters. Native Transformers generation captures, seeds and restores CPU/already-initialized accelerator RNG state inside the generation lock, including restoration on failure. |
The message-count, token-budget, nonnegative-temperature and choice-count bounds are Pydantic field validators; invalid requests and unknown fields receive HTTP 422 before generation rather than silently dropping unsupported SDK options. Backend validation failures inside the route are caught and returned as HTTP 500 with detail=str(exception).
class OpenAiResponseMessage(BaseModel):
    role: str = "assistant"
    content: str

class OpenAiResponseChoice(BaseModel):
    message: OpenAiResponseMessage
    index: int = 0
    finish_reason: str | None = None

class OpenAiUsage(BaseModel):
    prompt_tokens: int = 0
    completion_tokens: int | None = None
    total_tokens: int | None = None

class OpenAiResponse(BaseModel):
    id: str = ""
    object: str = "chat.completion"
    created: int
    model: str
    choices: list[OpenAiResponseChoice]
    usage: OpenAiUsage | None = None
The implementation supplies a UUID string ID and Unix timestamp. finish_reason is "stop" when the sequence ended on EOS or a matched stop string, "length" when it exhausted the token budget, and null when a runtime adapter did not report a reason. prompt_tokens is the rendered prompt length; completion_tokens and total_tokens are null rather than a fabricated zero when the backend returns only text. It still does not implement tool calls, logprobs, or streaming chunks; clients needing those need an external engine's server.
The route calls:
model_inputs = self.tokenizer.apply_chat_template(
    request.messages,
    add_generation_prompt=True,
    return_tensors='pt',
)
It supports a tensor or a mapping-like tokenizer result exposing .to(...) and input_ids, moves the result to self.model.device, and determines the prompt length from token IDs. The endpoint is a synchronous def, so it runs in the threadpool instead of stalling the event loop, and a threading.Lock admits one generation at a time. It then invokes the wrapper with:
| Generation argument | Value |
|---|---|
max_new_tokens |
max_completion_tokens, else max_tokens, else 256 |
eos_token_id |
Deduplicated EOS IDs from generation config, model config and tokenizer; one integer or a list, omitted when empty |
do_sample |
request.temperature != 0.0 |
temperature, top_p
|
Request values, only when do_sample is true |
num_return_sequences |
request.n, only when n != 1
|
stop_strings plus tokenizer
|
Request stop list, native path only (Transformers 5.x requires the tokenizer alongside stop_strings) |
stop |
Request stop list, only when model._runtime_generate is set (vLLM/SGLang adapters) |
A tensor result is sliced as outputs[:, prompt_length:] and decoded with batch_decode(..., skip_special_tokens=True); each row's token count and finish_reason come from _sequence_end, which counts through the first EOS (inclusive) or strips trailing padding and reports "length". A non-tensor result is normalized by _coerce_generation_results, which accepts GenerationResult values, strings, {"text": ...} mappings, sequences of those, or an object exposing .texts — adapter-reported completion_tokens/finish_reason are kept. _strip_stop then trims each text at its earliest stop-string match and marks that choice finish_reason="stop".
Important consequences:
- The shim dispatches through
model.generate(), so it also servesGPTQModel.load(..., backend=BACKEND.VLLM or SGLang)wrappers: adapters getmax_new_tokensand the OpenAI-stylestopargument, and their text/GenerationResultreturns are coerced. Feature depth still trails the engines' own servers — no streaming, engine-specific sampling parity, or/v1/models. -
temperature=0withn != 1is rejected with HTTP 400 before generation instead of surfacing a Transformers error. - A valid model-specific chat template is required. Arbitrary multimodal message parts or tool schemas are not normalized by this route.
wait_until_ready() polls the Uvicorn started flag, sleeping for the configured interval, and raises TimeoutError after the deadline. Call it after starting the server. This indicates that Uvicorn started, not that a GPU warmup or test completion succeeded.
shutdown() sets uvicorn_server.should_exit = True; it does not synchronously join the thread or prove that the socket has closed. Asynchronous startup creates a non-daemon thread, so an owning process can remain alive until shutdown completes. The wrapper's readiness/shutdown methods do nothing when no server is assigned.
The synchronous endpoint runs in the threadpool and the lock admits one generation at a time; concurrent requests queue rather than batch. This code provides no batching scheduler, rate limiting, TLS, or CORS policy beyond the bearer gate described above. Bind to a trusted/local interface or place it behind a properly configured service boundary — when no API key is configured, generation is unauthenticated and /shutdown accepts any loopback caller.
ModelLoader.from_quantized() resolves the checkpoint locally, loads quantization metadata and tokenizer, then validates the resolved FORMAT before engine initialization:
| Requested backend | Accepted FORMAT members |
Literal format strings |
|---|---|---|
BACKEND.VLLM |
GPTQ, GEMM
|
gptq, gemm
|
BACKEND.SGLANG |
GPTQ, GPTQ_V2, GEMM, MARLIN
|
gptq, gptq_v2, gemm, marlin
|
These are GPT-QModel integration gates, not the external engines' full upstream format matrices. For example, FORMAT.GPTQ_P, GGUF, EXL3, VPTQ, BitBLAS-native layouts, and other formats are not implicitly accepted by this gate. Passing a different backend does not repack an unsupported artifact before the gate.
After that check, the engine must still support the architecture, metadata, bit width, group size, symmetry, activation ordering, device, and any dynamic overrides. Fused projections can require compatible settings across all members of a fused unit; independent per-module overrides are not automatically executable by an engine that fuses them. See Packing Formats and Compatibility and QuantizeConfig Reference.
The adapter entry point is:
def load_model_by_vllm(
    model,
    **kwargs,
):
It calls LLM(model=model, **kwargs). The main quantized loader supplies the resolved local checkpoint path, model trust, and runtime kwargs. It then obtains config/device across the engine layouts supported by get_vllm_model_config() and get_vllm_device(), stores them on the runtime, and wraps it with _runtime_generate = vllm_generate.
from gptqmodel import BACKEND, GPTQModel

model = GPTQModel.load(
    "/path/to/gptq-checkpoint",
    backend=BACKEND.VLLM,
    tensor_parallel_size=1,
    gpu_memory_utilization=0.8,
)
output_ids = model.generate(
    "The capital city of France is",
    max_new_tokens=32,
    do_sample=False,
)
print(model.tokenizer.decode(output_ids[0], skip_special_tokens=True))
The numeric values here are explicit example choices, not GPT-QModel defaults. The wrapper does not start an HTTP server. When deploying through vLLM's own server, give that engine a compatible saved checkpoint and use its installed version's server configuration; the Python conversion helper is not an OpenAI request parser.
ModelLoader.from_quantized() consumes dtype, device, device_map, and several Hub/configuration options before constructing vLLM. In particular, its resolved dtype and native placement map are not passed to LLM in this branch. Passing dtype=torch.bfloat16 to GPTQModel.load(..., backend=BACKEND.VLLM) therefore does not pin vLLM's own dtype. Engine initialization settings that remain in the forwarded kwargs, such as tensor_parallel_size, do reach LLM. If direct control over a consumed option is required, use vLLM's own API/server (or the lower-level load_model_by_vllm helper) and verify the engine's effective configuration. SGLang differs: its loader explicitly restores the resolved dtype and translates device information.
vllm.py records VLLM_VERSION, VLLM_AVAILABLE, and VLLM_IMPORT_ERROR. It detects the distribution through importlib.metadata.version() and separately imports LLM and SamplingParams. TokensPrompt is imported first from vllm, then vllm.inputs, with a legacy token-ID call fallback if neither export exists.
_require_vllm() distinguishes unavailable/import-failing engines in its diagnostics. A package installed with incompatible Python dependencies or PyTorch/CUDA binaries must be fixed as an environment problem; re-installing only GPT-QModel does not necessarily repair it.
def convert_hf_params_to_vllm(hf_params: Dict[str, Any]):| HF/wrapper field | vLLM SamplingParams field |
Notes |
|---|---|---|
num_return_sequences |
n |
More than one with do_sample=False is rejected. |
max_new_tokens, max_tokens
|
max_tokens |
Avoid specifying both; the conversion map processes max_tokens later. |
min_new_tokens, min_tokens
|
min_tokens |
Same alias precedence caveat. |
repetition_penalty |
Same | Passed when not None. |
temperature, top_k, top_p, min_p
|
Same |
do_sample=False overrides temperature to zero. |
frequency_penalty, presence_penalty
|
Same | Engine validates accepted values. |
ignore_eos, stop, stop_token_ids, seed
|
Same | Supported conversion fields. |
stop_strings |
stop |
Merged with explicit stop entries by the vLLM adapter. |
eos_token_id |
Added to stop_token_ids
|
Integer or integer sequence/tensor; merged and deduplicated. Booleans are not valid token IDs. |
do_sample |
Temperature policy | False selects greedy temperature 0.0. |
max_length, min_length
|
Unsupported by HF conversion | Non-None values raise; use new-token lengths instead. |
num_beams other than None/1
|
Unsupported | Raises; direct engine beam-search APIs are outside this adapter. |
If an installed SamplingParams constructor rejects converted fields, the helper reports the version and requested field names. It is not a full Transformers generation-config translator.
vllm_generate() accepts an explicit sampling_params:
| Value | Handling |
|---|---|
Omitted/None
|
Collect supported HF kwargs and default do_sample=False before conversion. |
SamplingParams object |
Used directly. |
| Mapping | Construct SamplingParams(**mapping) directly; use native vLLM field names, not HF aliases. |
| Other type | Raises TypeError. |
With explicit sampling_params, HF sampling kwargs are not merged into that object by _build_sampling_params(). Set the intended policy in one place. Unknown generation kwargs are not generally validated as HF arguments: only known sampling fields and the explicit runtime forwarding list are consumed, so a misspelled field can be ignored.
The HF checks in the table, including max_length/beam-search rejection and the greedy multi-sequence guard, run only when sampling_params is omitted/None. Supplying an explicit object or mapping bypasses those HF checks; separate top-level HF sampling fields are ignored rather than applied. Native SamplingParams validation still belongs to the installed vLLM version.
The engine adapter has signature vllm_generate(model, **kwargs) and runs under torch.inference_mode().
| Input/control | Behavior |
|---|---|
prompts="text" / list or tuple of strings |
Text is given to the engine's tokenizer. |
input_ids or numeric prompts
|
Nonempty 1-D integer sequence or batch of integer sequences; tensors are detached and moved to CPU lists. |
Both prompts and input_ids
|
Error. |
input_ids containing strings |
Error. |
attention_mask with token prompts |
Must match rows and token lengths and contain booleans or 0/1 integers. Only left/right padding may be removed; interior holes and all-masked rows raise. |
attention_mask with raw text prompts |
Rejected; tokenize first and pass input_ids when masking is required. |
use_tqdm, lora_request, priority, tokenization_kwargs, mm_processor_kwargs
|
Forwarded to LLM.generate(). Actual support depends on the installed engine. |
BaseQModel.generate(inputs=...) translates strings to prompts, tensors to input_ids, and merges mappings before calling this adapter. Higher-rank tensor masks are normalized by the wrapper first. The wrapper also supplies its attached tokenizer's pad ID when no non-None pad_token_id was given; the adapter's fallback below applies only when that value is still None.
Results are flattened in request/output order. With input_ids, each row restores the caller's original token row, including prompt padding, then appends completion IDs. Thus output[:, input_ids.shape[1]:] begins at the completion for rectangular tensor inputs even though padding was removed before engine execution. Text prompts use result.prompt_token_ids as their prefix. Rows are right-padded to equal length using the explicit pad_token_id, then the engine tokenizer's pad ID, then EOS ID, then 0. The returned tensor is CPU torch.long; no results gives shape (0, 0).
This contract supports decoding IDs, but does not return vLLM's complete RequestOutput metadata or promise native HF return-dict semantics.
def load_model_by_sglang(
    model,
    trust_remote_code,
    config=None,
    **kwargs,
):
The main loader supplies its already-loaded HF config, avoiding an unnecessary second remote/config lookup. A direct caller omitting config gets AutoConfig.from_pretrained(model, trust_remote_code=...).
| API availability | Initialization/behavior |
|---|---|
sglang.Engine export exists |
Calls Engine(model_path=model, **normalized_kwargs) and marks _gptqmodel_uses_sglang_engine=True. |
No Engine export |
Calls legacy Runtime(...), marks false, and registers it through set_default_backend() when available. |
| Engine constructor fails | Raises a contextual RuntimeError; does not silently retry legacy Runtime. |
The helper returns (runtime, hf_config). The wrapper attaches sglang_generate, not native Transformers generate().
from gptqmodel import BACKEND, GPTQModel

model = GPTQModel.load(
    "/path/to/gptq-checkpoint",
    backend=BACKEND.SGLANG,
    device="cuda:0",
    dtype="bfloat16",
    tensor_parallel_size=1,
    gpu_memory_utilization=0.8,
)
text = model.generate(
    "The capital city of France is",
    max_new_tokens=32,
    do_sample=False,
)
print(text) # SGLang adapter returns text, not a token tensor._build_sglang_runtime_kwargs() combines loader device information and the resolved dtype, removes config, and ensures dtype is passed once. _normalize_sglang_engine_kwargs() then applies:
| Accepted alias | SGLang field | Rule |
|---|---|---|
tensor_parallel_size |
tp_size |
Supplying both raises. |
gpu_memory_utilization |
mem_fraction_static |
Supplying both raises. |
max_model_len |
context_length |
Supplying both raises. |
seed |
random_seed |
Supplying both raises. |
enforce_eager |
disable_cuda_graph |
Boolean conversion; supplying both raises. |
Torch dtype
|
String without torch.
|
Engine expects dtype names. |
Indexed device, such as cuda:1
|
Device family plus base_gpu_id=1
|
Uses setdefault for the ordinal; an explicit base ID is retained. |
device="rocm" |
device="cuda" |
PyTorch/SGLang ROCm device spelling. |
base_gpu_id, context_length, random_seed, tp_size
|
Same | Coerced to integers when not None. |
mem_fraction_static |
Same | Coerced to float when not None. |
trust_remote_code |
Same | Set from loader trust unless already present. |
These normalization rules do not invent runtime defaults for every SGLang setting. Unspecified settings remain the installed engine's defaults. The loader's device selection is not a replacement for configuring tensor parallelism or available GPUs correctly.
_build_sglang_sampling_params(value, kwargs) accepts a mapping or None, copies the mapping, normalizes aliases, then overlays recognized top-level values.
| Input | SGLang Engine sampling field / handling |
|---|---|
max_tokens / max_new_tokens
|
max_new_tokens |
min_tokens / min_new_tokens
|
min_new_tokens |
num_return_sequences |
n |
temperature, top_k, top_p, min_p
|
Same |
repetition_penalty, frequency_penalty, presence_penalty
|
Same |
ignore_eos, stop, regex, json_schema, sampling_seed
|
Same |
stop_token_ids |
Integer(s), normalized/deduplicated; mapping and top-level IDs are merged. |
Top-level eos_token_id
|
Added to stop token IDs. |
Top-level do_sample=False
|
Forces temperature=0.0, even over a supplied temperature. |
max_length, min_length
|
Rejected in the mapping or top-level kwargs. |
| Both max-token aliases, or both min-token aliases at the same normalization stage | Rejected. |
Use sampling_seed for per-generation sampling; the load-time seed alias maps to runtime random_seed. With no explicit sampling_params mapping, SGLang defaults to greedy (temperature=0.0) unless do_sample=True. A caller-supplied mapping keeps its own policy unless top-level do_sample=False explicitly forces greedy. Beam-search HF options are not translated into an equivalent engine operation. A requested device="rocm" maps to the engine's cuda spelling only under a HIP Torch build; NVIDIA-only builds reject it rather than silently selecting NVIDIA hardware.
@torch.inference_mode()
def sglang_generate(
    model,
    **kwargs,
):
Text and token inputs are mutually exclusive. Nonempty text lists and integer token lists/tensors are normalized; invalid token types, mismatched masks, and all-masked prompts fail. Single versus batch shape is preserved by the SGLang input normalizer.
SGLang accepts attention_mask only with token inputs, not raw text. Mask entries must be booleans or integer 0/1, and they may remove left/right padding only: a zero between kept tokens raises. This is stricter than the vLLM helper, which filters token positions by their truth value and can remove interior positions. A flat token sequence is a single prompt; a nested one-row token batch remains a batch. Engine output extraction preserves the result's string/list structure rather than forcing every response into a single string.
For the Engine API, the adapter calls:
model.generate(
    prompt=text_prompts,
    input_ids=token_prompts,
    sampling_params=sampling_params,
    **request_kwargs,
)
Non-sampling kwargs are forwarded as request kwargs, except pad_token_id, which is discarded. Engine compatibility is determined by its installed API. _extract_sglang_text() extracts string text fields from mapping results and recursively extracts lists; unexpected types or non-string text fields fail. This adapter is a synchronous text-result adapter, not a streaming iterator decoder and not a token-tensor API.
The legacy Runtime frontend:
- Accepts text prompts only;
input_idsraises. - Rejects additional request kwargs rather than silently ignoring them.
- Converts new-token aliases back to legacy
max_tokens/min_tokens. - Checks the
sgl.gensignature, with a finite supported-field fallback for decorated/opaque signatures. Unsupported sampling fields raise, including Engine-only fields not accepted by that frontend. - Calls the decorated
_legacy_generate.run(prompt=...), then reads the returned state's"result"string. A text batch is evaluated one prompt/state at a time.
Legacy default-backend registration is process-global behavior; do not assume that initializing many independent legacy Runtime wrappers provides isolated frontend routing.
| Topic | Guidance |
|---|---|
| Wrapper tokenizer versus engine tokenizer | GPT-QModel constructs its tokenizer through Tokenicer, but a runtime may tokenize raw text internally. Compare exact IDs/template output if the two paths differ. Pretokenized input avoids retokenizing that prompt, but requires an Engine/API that accepts it. |
| Chat formatting | Wrapper string generation sends plain prompts. Apply a chat template explicitly or use the engine server's appropriate chat endpoint/template configuration. Do not apply a template twice. |
| Model trust | Model/tokenizer custom-code trust and adapter remote-download permissions are separate. See Loading and Inference. |
| Adapters | GPT-QModel's native LoRA attachment is not automatically translated into an engine request. vLLM exposes lora_request forwarding; configure the engine's adapter support itself. |
| OpenAI HTTP | The built-in shim emits the chat.completion schema with usage/finish_reason, but still lacks streaming, /v1/models, embeddings, and the wider API surface. vLLM/SGLang Python adapters are not HTTP servers. |
| Environment knobs |
vllm.py and sglang.py do not read their own os.getenv/os.environ switches. They use Python kwargs and inspect engine APIs/versions. Engine-owned environment variables are governed by that engine's installed version, not by utils/env.py. |
| Common loader environment |
GPTQMODEL_USE_MODELSCOPE affects Hub selection, GPTQMODEL_PRINT_MODULE_TREE affects loader diagnostics, and other native-kernel controls are covered in Loading and Inference. They are not HTTP startup flags. |
-
GPTQModel.load()/from_quantized()chooses the model definition and normalizes backend/trust/adapter inputs. -
ModelLoader.from_quantized()resolves the checkpoint, reads its saved quantization configuration and tokenizer, and calls_validate_external_backend_format(). - The selected runtime constructor receives its engine initialization kwargs. SGLang has an explicit alias/device/dtype normalization layer; vLLM receives the kwargs forwarded to
LLM. - The wrapper stores
_runtime_generate, andBaseQModel._generate_with_runtime()converts publicinputsinto adapter kwargs. - vLLM returns padded token IDs; SGLang returns extracted text. The built-in HTTP server calls the same
model.generate()dispatch and normalizes both result shapes: token tensors are sliced/decoded, and text orGenerationResultvalues are coerced by_coerce_generation_results.
- Confirm the saved format, not just the method/backend label, before selecting an engine.
- Use a dedicated engine environment and record engine/Torch/CUDA or ROCm versions for reproducibility.
- Separate load-time engine options from per-generation sampling/request options.
- Use
max_new_tokenswith external adapters. The built-in shim now sends the samemax_new_tokens/stopfields, but engine-specific features still require the engines' own servers. - Handle return types explicitly: native/vLLM token tensors versus SGLang text.
- Keep prompt/tokenizer/chat-template behavior identical when comparing native and engine results.
- Do not interpret Uvicorn readiness as a model-quality or GPU warmup test.
- Non-loopback serving requires
api_key/GPTQMODEL_OPENAI_API_KEY. Loopback serving without a key still allows local inference and local shutdown; keep untrusted local clients out and preserve Host validation. - Do not assume a legacy Runtime fallback will rescue a failing Engine constructor or support Engine-only sampling/streaming features.
| Path | Responsibilities |
|---|---|
gptqmodel/utils/openai_server.py |
HTTP routes, bearer-auth middleware, Pydantic schemas, Uvicorn start/readiness/shutdown. |
gptqmodel/utils/generation_result.py |
GenerationResult: a str subclass carrying adapter-reported completion_tokens/finish_reason so the server can report real usage. |
gptqmodel/utils/vllm.py |
Optional import/version diagnostics, vLLM construction, config/device compatibility, sampling conversion, input/mask normalization, padded token results. |
gptqmodel/utils/sglang.py |
Optional import diagnostics, Engine/Runtime selection, runtime aliases, sampling conversion, legacy frontend restrictions, text extraction. |
gptqmodel/models/base.py |
serve*, generate, _generate_with_runtime, tokenizer wrapper. |
gptqmodel/models/loader.py |
External format gates, checkpoint/tokenizer resolution, engine kwargs and wrapper creation. |
gptqmodel/models/auto.py |
Public loader dispatch. |
gptqmodel/utils/backend.py |
External backend enum values and normalization. |
gptqmodel/utils/hf.py, gptqmodel/utils/modelscope.py
|
Tokenicer construction, trust, optional Hub behavior. |
gptqmodel/quantization/config.py |
Saved method/format metadata. |
pyproject.toml, requirements.txt
|
Optional engine/server dependency and Python requirements. |