Repository navigation
Getting Started
This guide takes you from a working Forge Neo to your first H3 video. It describes version 0.6.0.
| Forge Neo | The neo branch at revision d70373e (3 October 2026) or later, which ships comfy-kitchen 0.2.37. Tested with Python 3.13 and Torch 2.13 with CUDA 13.0. |
| FFmpeg | Needed to write the MP4. On the PATH, or set its path in Settings → MiniMax H3. |
| Disk | About 50 GiB for the four model files (about 31 GiB with the smaller set), plus 1.8 GiB per turbo LoRA. |
| System RAM | Forge keeps the checkpoint, text encoder and both VAEs in RAM. On a 48 GB card the INT8 set peaked at about 46 GiB; on a 24 GB card the smaller set used about 35 GB and the INT8 checkpoint with the INT4 text encoder about 67 GB. |
| GPU | Tested on an NVIDIA A40 (48 GB) and an RTX 4090 (24 GB). On the 4090, Forge's own offloading ran 10-second clips with every tested file; the smaller set is the fastest there. A 16 GB card with 32 GB of RAM works with the smaller set and Forge's --cuda-malloc flag (16 GB Cards); cards under 16 GB have not been tested. |
Note
The extension adds no Python packages to Forge Neo. If you used version 0.1.2, the DiffSynth packages and the models/H3/processor folder it installed are no longer used; they do not affect anything and can stay.
- In Forge Neo, open Extensions → Install from URL.
- Paste
https://github.com/eduardoabreu81/minimax-h3-forge-neoand click Install. - Restart the WebUI.
- Check the console:
-
[MiniMax H3] native backend enabled- ready. -
[MiniMax H3] This Forge Neo is too old for the extension- nothing was changed and the extension stays off. Update Forge Neo (git pullon theneobranch) and restart; the lines below the message say what is missing.
-
H3 is split into four files. All four are needed, from the Comfy-Org/MiniMax-H3 repository:
| Part | File | Size | Forge folder |
|---|---|---|---|
| H3 checkpoint | minimax_h3_fl2va_pruned_int8_convrot | 19.5 GiB | models/Stable-diffusion |
| Text encoder | qwen3vl_32b_minimax_h3_int8_convrot | 25.3 GiB | models/text_encoder |
| Video VAE | minimax_h3_video_vae_fp16 | 4.9 GiB | models/VAE |
| Audio VAE | minimax_h3_audio_vae_fp32 | 0.6 GiB | models/VAE |
| Turbo LoRA (optional) | minimax_h3_fl2v_turbo_8step_v1.0_comfyui_bf16 | 1.8 GiB | models/Lora |
Other checkpoints, VAEs and LoRAs that work (FastH3, Ref2VA, a smaller INT8 video VAE, community fine-tunes) are listed in Models. Use the files above for your first test: a file called H3 somewhere else may be a different format.
Refresh the model lists in Forge (or restart) after the download.
Two Forge Neo launch flags help H3. Add them to COMMANDLINE_ARGS in webui-user.bat (Windows) or webui-user.sh (Linux) and restart:
set COMMANDLINE_ARGS=--cuda-malloc --use-ck-attention| Flag | What it does | Measured with H3 |
|---|---|---|
--cuda-malloc |
Switches PyTorch's GPU memory allocator to the CUDA driver's asynchronous one (cudaMallocAsync). The default allocator keeps freed blocks for reuse; when the 15 GB text encoder leaves the card and the checkpoint arrives, the free memory can be split into pieces too small for the checkpoint. Forge suggests the flag in the console on RTX cards. | On a 16 GB card the first step ran out of memory with 2.8 GB free without it, and ran with it, the whole W4A8 checkpoint on the card (16 GB Cards). With Never OOM it also made steps 11% faster. |
--use-ck-attention |
Computes attention with Comfy Kitchen's INT8 kernels instead of PyTorch's. Attention is the heaviest part of each step for video. The kernels rotate channels before quantizing, which keeps H3's picture. | 3-10% faster on the W4A8 and INT8 checkpoints, the same picture; 17% with Sparse Attention from 0.50 (Speed Options). Needs comfy-kitchen 0.2.37, which the extension requires. |
Neither changes the result; they change how memory and attention are handled. Without them H3 works as well, a little slower, and on 16 GB cards only with Never OOM Integrated.
- In the UI preset selector at the top, pick h3. It sets Res Multistep, Simple, 20 steps, CFG 1 and Shift 12.
- In the checkpoint selector, pick minimax_h3_fl2va_pruned_int8_convrot.
- Under VAE / Text Encoder, select all three: the text encoder, the video VAE and the audio VAE.
When an H3 checkpoint is selected:
- a MiniMax H3 panel appears below the generation settings; its Components section lists the files it recognized;
- Batch Size becomes Frames, the length of the video, with the duration shown next to it;
- Batch Count is fixed at 1.
Select another model and everything goes back to normal.
Start small to check the setup. In txt2img:
| Setting | Value |
|---|---|
| Prompt | A small bird sings on a branch in a quiet garden, natural daylight, clear bird song, no subtitles. |
| Width × Height | 640 × 384 |
| Frames | 22 (under one second) |
| Sampler / Schedule / Steps | Euler / Simple / 20 |
| Seed | 123 |
In the MiniMax H3 panel keep Output on Video and Include generated audio on, then click Generate.
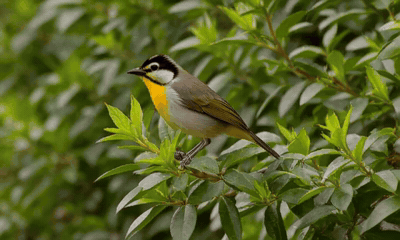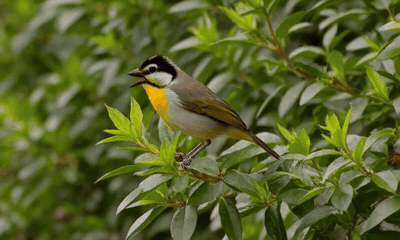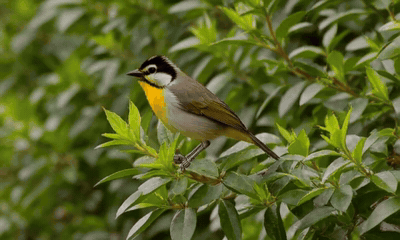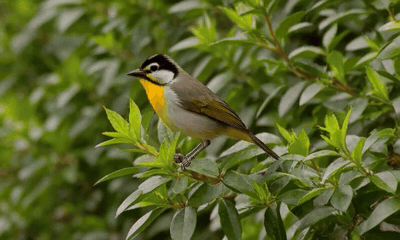
On the A40 this took 53.5 seconds including loading the model. The first load reads about 50 GiB from disk, so it can take much longer on a slow drive; later generations reuse the loaded model.
The MP4 plays in Forge's usual result area. It is saved in the txt2img (or img2img) output folder as h3-<seed>-<id>.mp4, with a .json file next to it that records the prompt and every setting. The settings are also in the MP4 itself, in its comment field.
Once the bird works, try a 3-second clip at the model's size:
- Width × Height: 1152 × 768 (landscape) or 768 × 1152 (portrait)
- Frames: 73
- Sampler / Steps: Res Multistep / 20 (the h3 preset)
- A prompt that says what happens, how the camera moves and what we hear. The Examples page has many to start from.
That takes about 5-6 minutes on the A40, or under 3 minutes with the turbo LoRA.
- Writing Prompts - the prompt layouts H3 was trained with, and tips for sound, speech and music
- Settings and Controls - every control and what it does for a video
- First and Last Frame and Reference Pictures - start from your own pictures
- Overview - every tested file and setting, rated
- Troubleshooting - if something does not work