Repository navigation
Motion Control
New in 0.7.0. With alibaba-pai's Fun ControlNet-Union, H3 follows the motion and shapes of any video: a person's pose, the depth of a scene, its edges. With a mask it redraws only part of a video and keeps the rest. It works with any H3 checkpoint, FL2VA or Ref2VA, and with the turbo and Acc LoRAs.
- Download the Fun ControlNet-Union 2.0, for example Kijai's INT8 file minimax_h3_fun_controlnet_union_2.0_pruned_int8_convrot (4.5 GB; the bf16 file is 8.4 GB). Version 2.0 is the one to use; the first union model is older.
- Put it in
models/ControlNet. - In the MiniMax H3 panel, open Control, press 🔄 and pick it under Fun ControlNet.
- Upload a Control video and choose a Preprocessor.
- Keep CFG at 1: the ControlNet is made for one pass per step.
| Control | What it does |
|---|---|
| Fun ControlNet | The control model file |
| Control video | Any video; it is cropped to the clip's size and cut to its length |
| Preprocessor | Turns each frame into a pose, depth or edge map with Forge's own preprocessors. The map is saved next to the result (...-control.mp4) so you can check it |
| Strength | How closely the clip follows the map (1 by default) |
| Start / End | The part of the generation that follows the map: 0 to 1 is all of it; an earlier End leaves the last steps free |
| Inpainting mask | A picture or a video, white where the clip is redrawn |
| Source video to redraw | The video the mask applies to; without one, the control video itself |
| Preprocessor | Follows | Good for |
|---|---|---|
| Pose (DWPose) | Body, hands and face of people | Dance and action with a new person or place |
| Depth (Depth Anything V2) | Shapes and distances | Keeping the layout of a scene and the volume of people |
| Depth (MiDaS) | The same, older model | |
| Canny edges | Every outline | Keeping a scene almost exactly while changing colors, light, clothes or season |
| HED edges, Scribble (HED) | Soft outlines | A looser version of canny |
| Line segments (MLSD) | Straight lines | Rooms and buildings |
| Gray | Brightness | Recoloring a video |
| None | Nothing: the video is already a control map | Maps made elsewhere |
The first time a preprocessor runs, Forge downloads its model. DWPose on a long clip takes a minute or two on the processor before the generation starts.
Second control adds another map through the same ControlNet, from the same control video unless you give it one. The two add up, so keep their strengths around 1 in total, for example pose 0.7 + depth 0.3. Pose alone can lose an arm or a leg that is hidden behind the body when a person turns sideways; a little depth keeps the body's volume.
Give an Inpainting mask (white = redraw, black = keep) and describe the whole new scene in the prompt. A still picture masks the same area in every frame; a video mask can follow something that moves. Without a Source video, the control video is the one redrawn. With Soundtrack: Control video, the result keeps the source's original sound.
All on an NVIDIA A40 (48 GB), 124 frames (5.17 s), CFG 1, the MP4 exactly as Forge saved it. Click a preview for the MP4 with sound.
A Pexels clip of a woman walking down a ramp as the control video, Canny edges, and a prompt with another woman in a crimson coat on a rainy autumn evening. The ramp, the handrail, the camera and every step stay the same.
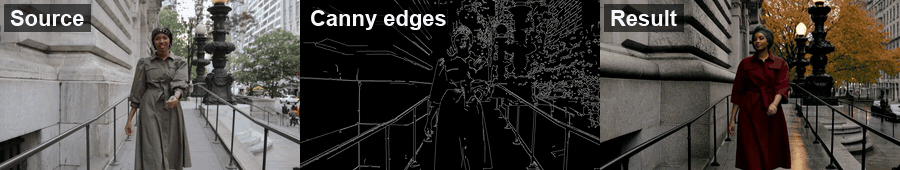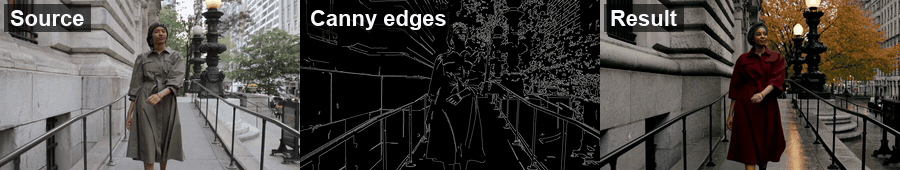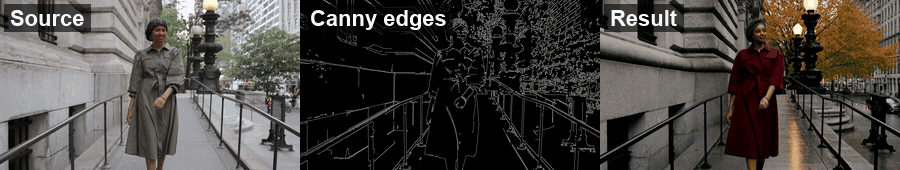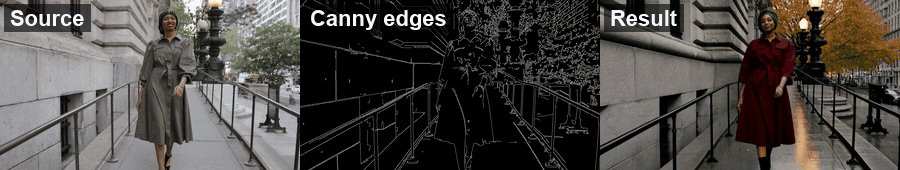
| Model | Size | Sampler | Steps | Seed | Time |
|---|---|---|---|---|---|
| FL2VA INT8, Sparse Attention 0.50 | 1344×768 | Res Multistep | 40 | 1105 | 1115.3 s |
Prompt
integrated_multimodal_description: [Shot 1] Live-action, cinematic, a full-body shot of a young woman in her late twenties with deep brown skin and an emerald-green silk headwrap, wearing a long crimson wool coat cinched at the waist with a belt and black ankle boots, walking toward the camera down a wide stone ramp beside a grand old granite building on an autumn evening, a black metal handrail along the ramp, ornate iron lamp posts glowing warm amber, the pavement wet and reflecting the lamplight after the rain, orange and golden leaves on the trees. She walks at an easy, relaxed pace, glances at the building beside her, then looks ahead with a calm smile, her coat swinging with each step. The camera moves backward smoothly at chest height, keeping her centered in the frame. No subtitles, no text overlays.

overall_soundscape: Her boots clicking on the wet stone, light city traffic in the distance and a soft breeze through the leaves.

non_diegetic_music: A mellow, slow jazz piano.
The same walk with a still mask over its right third and no control map: only that third is redrawn as a row of cherry trees in bloom; the woman, the ramp and the building are kept, and so is the clip's original sound.
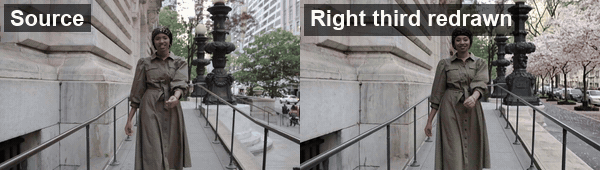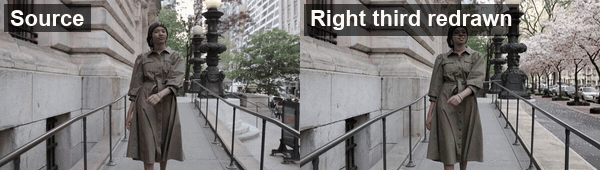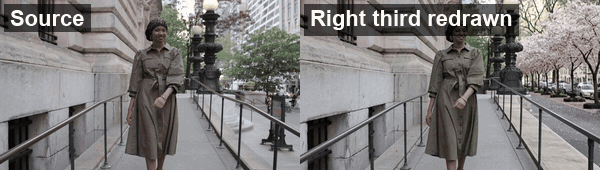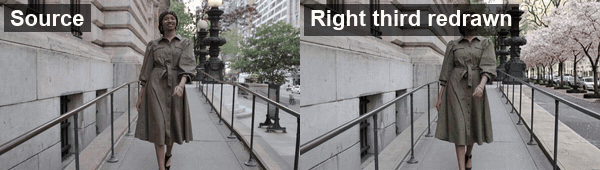
| Model | Size | Sampler | Steps | Seed | Time |
|---|---|---|---|---|---|
| FL2VA INT8 + FL2VA Acc 8-Step | 1344×768 | Euler | 8 | 1105 | 415.5 s |
Prompt
integrated_multimodal_description: [Shot 1] Live-action, cinematic, a full-body shot of a young woman with deep brown skin and a patterned dark headwrap, wearing a long olive-green belted shirt dress, walking toward the camera down a wide stone ramp beside a grand old granite building on a spring afternoon, a black metal handrail along the ramp, ornate iron lamp posts, and on the right side of the ramp a row of cherry trees in full pink bloom lining the street, pink petals drifting through the air and scattered on the pavement. She walks at an easy, relaxed pace and smiles, her dress swinging with each step. The camera moves backward smoothly at chest height, keeping her centered in the frame. No subtitles, no text overlays.

overall_soundscape: Her shoes on the stone, light city traffic in the distance and a soft breeze through the blossoms.

non_diegetic_music: None.
<lora:MiniMax-H3-FL2VA-Acc-8Step_pruned_comfy:1>
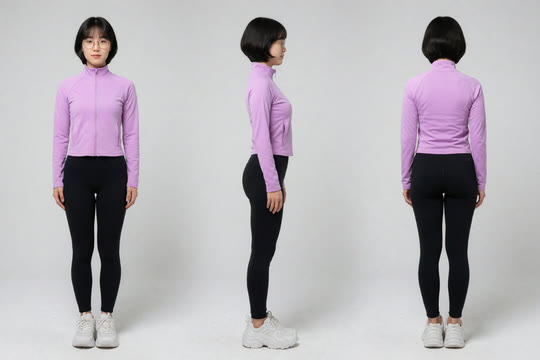
A K-pop dance cover as the control video with Pose (DWPose) and Soundtrack: Control video, on a Ref2VA checkpoint with the Acc LoRA. The new character was given once as one picture with three views (front, side and back) and once as three separate pictures. Both follow the dance; with the views, the face turns better than with a single front picture.
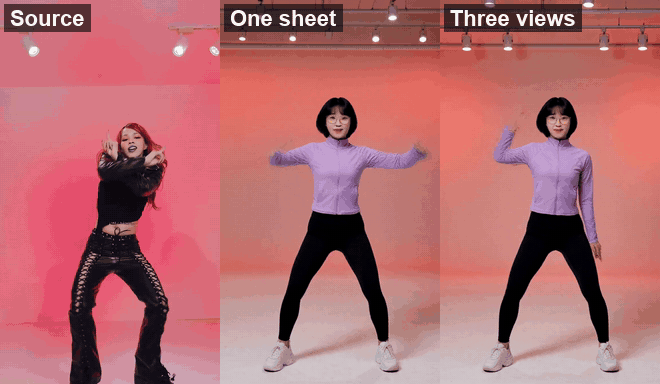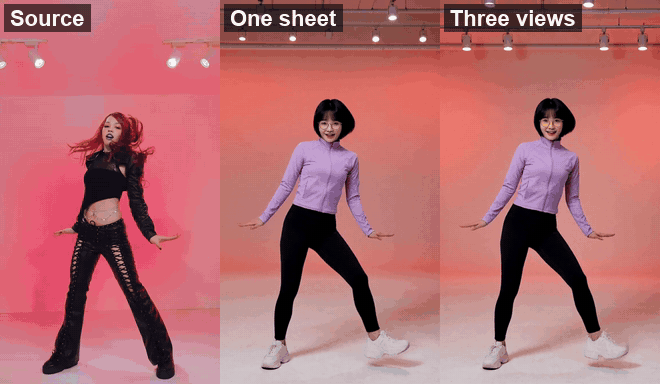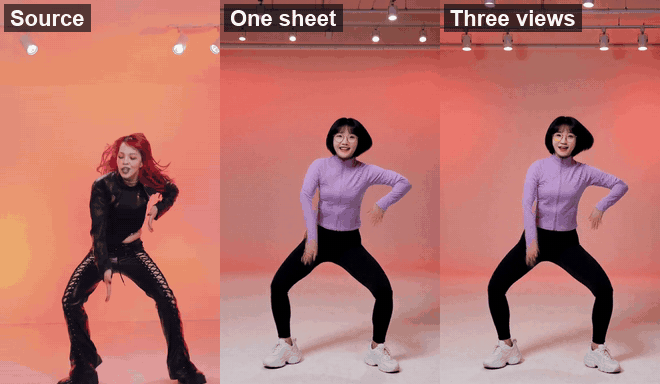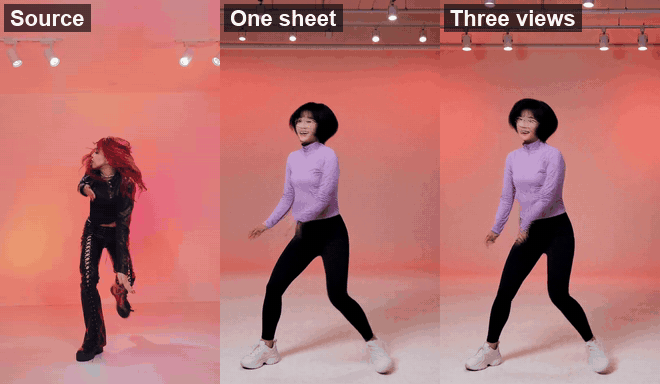
| Reference | Character sheet (Krea 2) |
|---|---|
One picture with three views (MP4), or the three views as <Picture 1> to <Picture 3> (MP4) |
 |
| Model | Size | Sampler | Steps | Seed | Time |
|---|---|---|---|---|---|
| Ref2VA INT8 + Ref2VA Acc 8-Step | 768×1344 | Euler | 8 | 1102 | 513.3 s (sheet), 519.0 s (views) |
Prompt (one sheet)
subject_definitions:
<Subject 1> is the young woman shown in <Picture 1>, a character sheet of her from the front, in side profile and from the back, preserving her black inverted bob with bangs, round gold-rimmed glasses, fit athletic build, lavender track jacket, black leggings and white sneakers. The sheet only shows her appearance; it does not appear in the video.

summary:
[reference generation] The target video is a 5-second vertical full-body clip in which <Subject 1> dances a sharp K-pop routine in a bright dance studio, her face lively and expressive from start to finish.

retention_analysis:
<Subject 1> (appears in [Shot 1]): fully_preserved - her face, round glasses, black inverted bob with bangs, lavender track jacket, black leggings and white sneakers remain clearly recognizable from every angle.

detailed_description:
The target video is a 5-second single continuous vertical shot in cinematic photorealistic live action, bright and energetic.
[Shot 1] A full-body shot frames <Subject 1> in a dance studio with a smooth seamless backdrop glowing coral pink, a pale pink floor and a row of small white spotlights on a ceiling track, her whole body visible from head to sneakers. She hits every move on the beat: wide stance, arm swings, shoulder pops, quick turns to the side and sharp footwork, her bob swinging with each move. Her face reacts to the music the whole time: a confident smirk, a quick open grin, eyebrows lifting on the accents, looking into the camera whenever she faces it. The camera stays fixed on a tripod at chest height.

overall_soundscape: Sneakers squeaking and tapping on the studio floor and the swish of her track jacket with every move.

non_diegetic_music: A high-energy K-pop dance track with a punchy bass and crisp snares, from the first second to the last.
<lora:MiniMax-H3-Ref2VA-Acc-8Step_pruned_comfy:1>
What did not work, and why, is in Bloopers: this prompt describes generic dance moves, and in some frames the text won over the pose map.
- Describe the person and the place, not the moves. The control video already gives the motion; a choreography in the prompt competes with it, and the text can win.
- Canny keeps the most, pose the least. Choose by how much of the original you want to keep.
- Pose maps cannot show which way a person faces. If the prompt says "in side profile" while the person faces the camera at an angle, the clip follows the prompt.
- A hidden arm or leg disappears from a pose map when the person turns; add depth as the second control.
- An earlier End (0.6) gives the last steps back to the prompt: looser motion, more freedom in the details.
- The Acc 8-Step LoRAs work with control: 8 steps with Euler.
- The control video is read at the clip's size; very long clips with control use more memory and time.