EchoSub 1.1.0

EchoSub shows live, translated captions for anything your PC plays — videos, streams, calls, games. It listens to your speakers, recognizes speech in almost 100 languages, translates it on your own GPU, and shows it in a customizable always-on-top caption box, with a line and a color for every speaker.
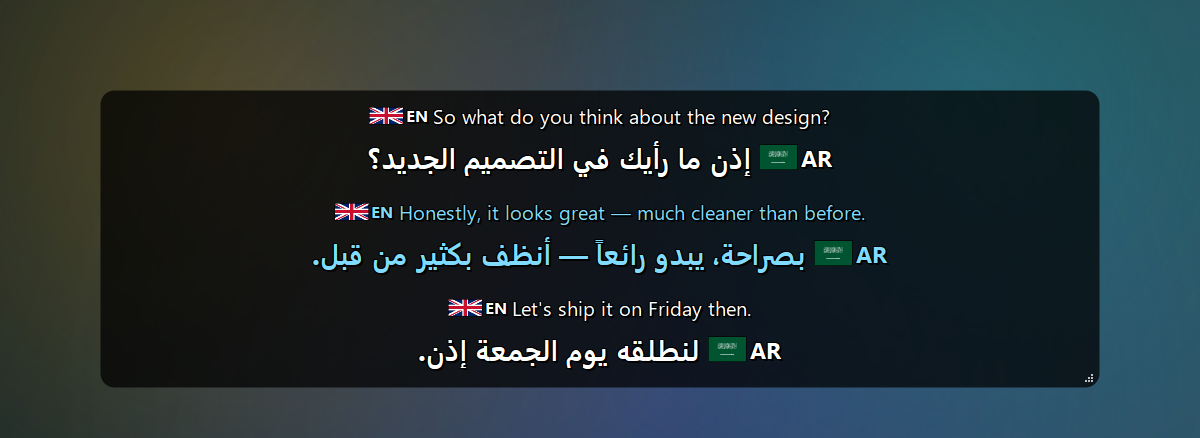
What's new in 1.1.0
Your microphone, captioned too
Settings → Language & Engine → Microphone (off by default). What you say is recognized and translated like everything else, in its own colour and with your own label ("You"), on its own line. Both sources share the one speech model, so nothing extra runs while nobody is talking, and a microphone that cannot be opened never stops the captions.
Voice commands
Off by default (tray menu, or Settings → Advanced). Say the wake word — "echo sub", or your own — and then one of a fixed list: open or close eighteen everyday apps (Calculator, Notepad, Paint, File Explorer, Windows Settings, Task Manager, Snipping Tool, on-screen keyboard, Magnifier, Character Map, Chrome, Edge, Firefox, VLC, VS Code, Discord, Steam, Spotify), or pause, resume, hide, show and clear captions. Understood in about twenty languages and in everyday wording. Nothing that is said ever reaches a shell or names a program: a spoken sentence can only pick one of the actions written into EchoSub. Closing an app is the same as clicking its X, so unsaved work is still protected.
Keeping up on a busy PC
Measured on a GTX 1060 6 GB while a game was using the card, on 39 seconds of speech:
- Light mode (tray menu) — the Small speech model and no live text: Whisper's work dropped from 15.2 s to 3.7 s, and every caption arrived about 1.0–1.3 s sooner.
- Live text is no longer translated on the recognition thread (it blocked it for 3.4 s), speech detection costs about a third of what it did, and captions can no longer fall behind without end.
- Catch-up audio buffer: when recognition is behind, the audio still waiting is kept in a temporary folder and used in order instead of being lost. Session-only, deleted as it is read; you choose the size and which drive it lives on (Settings → Advanced).
Fewer made-up captions
Whisper's own signals are weighed together, known filler phrases ("Thanks for watching") and looping repetitions are dropped, and text too dense for the audio it came from is rejected. Live text is judged more strictly than a finished caption and can never reach the history or a transcript file.
Also
- A sound card that is unplugged and plugged back in now reconnects. A failed attempt used to leave a PortAudio instance behind, so the device that came back kept failing with "Invalid device info". If the device you picked is missing, EchoSub uses the default one and says so, then moves back on its own.
- Update checks for the installed app, once a day, through the official releases — it only ever opens the download page, and can be switched off.
- The Settings window fits every screen, its fields line up, and no tab scrolls sideways.
Download
EchoSub-Setup-1.1.0.exe (973 MB) — Windows 10/11, 64-bit
SHA-256: 6E44BAF54F988AF338C74AF4AF09EE5762C65FC2FFA94B8A2F49994ADF76FFAE
- Close EchoSub if it is running, then run the installer (no admin rights needed; you can also install for all users). Installing over an earlier version keeps your settings and models.
- Start EchoSub. The first start downloads the AI models (~2.3 GB) in a progress window — you can cancel and it resumes later.
- Play anything with speech. Right-click the caption box or the tray icon for the menu.
Windows SmartScreen: the installer isn't code-signed yet, so Windows may show "Windows protected your PC". Click More info → Run anyway. You can verify the file with the SHA-256 above:
Get-FileHash EchoSub-Setup-1.1.0.exe.
System requirements
| Minimum | Recommended | |
|---|---|---|
| Operating system | Windows 10, 64-bit | Windows 11, 64-bit |
| Processor | 64-bit, 4 cores | 6+ cores (e.g. Intel Core i5-9400F / AMD Ryzen 5 3600) |
| Memory (RAM) | 8 GB | 16 GB |
| Graphics | None required — CPU with the Small or Base speech model (captions lag several seconds) | NVIDIA GeForce GTX 1060 6 GB or better |
| Graphics memory | 4 GB (default models on an NVIDIA GPU) | 6 GB or more |
| NVIDIA driver | 527.41 or newer | Latest |
| Free disk space | 6 GB | 10 GB on an SSD |
| Internet | Once, to download the models (~2.3 GB) | Also for the optional Google Translate engine |
Highlights
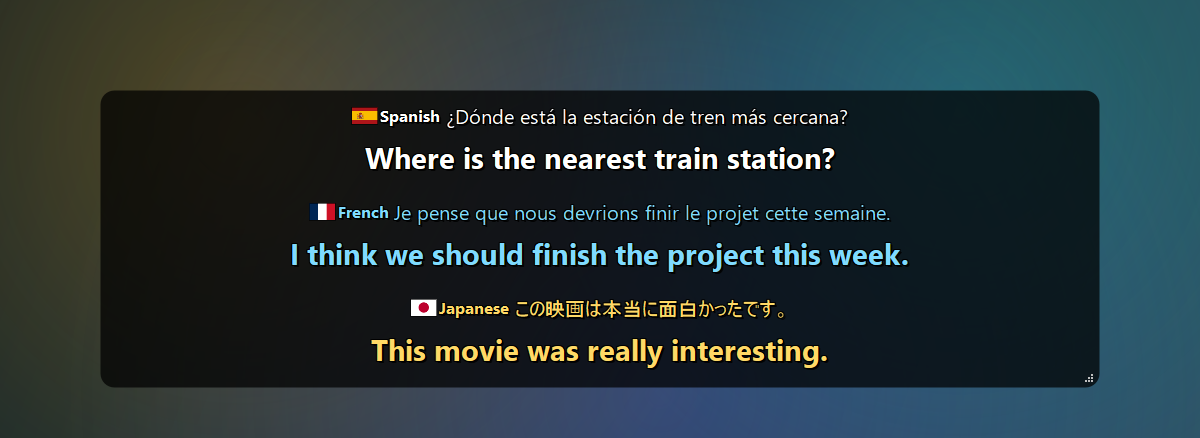
- Any app, any language — WASAPI loopback capture, Whisper large-v3-turbo recognition with automatic language detection (~100 languages).
- On-device translation — NLLB-200 (600M / 1.3B), or Google Translate. The original text appears instantly and the translation follows a moment later.
- Speakers — each voice gets its own line and color.
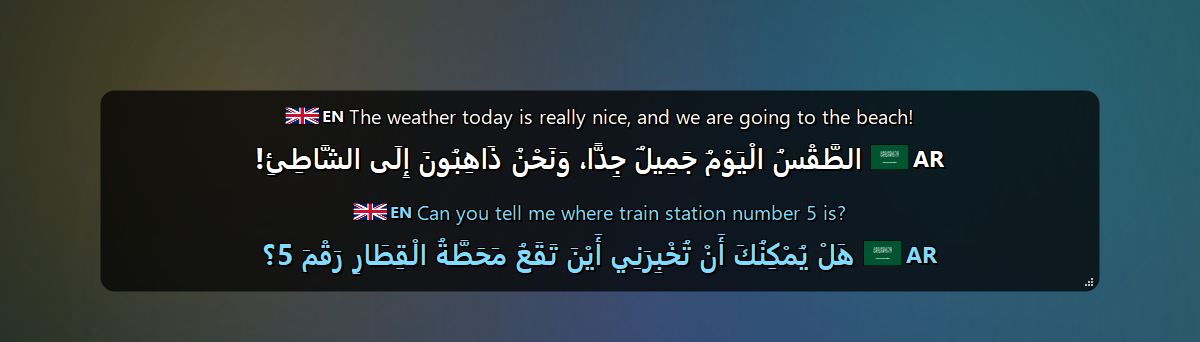
- Arabic — Moroccan Arabic (Darija) support and optional diacritics (تشكيل).
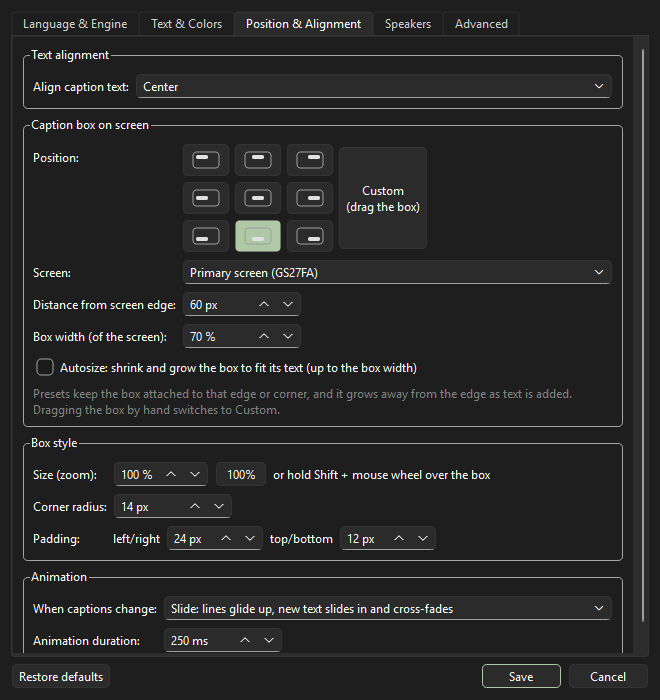
- Caption box your way — fonts, colors and spacing, language labels with flags, 9 screen positions or drag anywhere, autosize, corner radius, padding, smooth slide / fade animations.
- Handy — global hotkeys (
Ctrl+Alt+H/P/L), caption history and transcripts, click-through lock, auto-hide when nobody talks, cancelable model downloads, self-recovery when an audio device disappears.
| Any language in, your language out | Arabic diacritics (تشكيل) |
|---|---|
 |
 |
| Settings | About |
|---|---|
 |
 |
More screenshots in the README · full changelog · user guide.
License
Copyright © 2026 Mohammad Al-Safadi — GPL-3.0.
The default offline translation model (NLLB-200) is licensed for non-commercial use only; see third-party notices.