Repository navigation
MegaCapybara 1.35

What's new
-
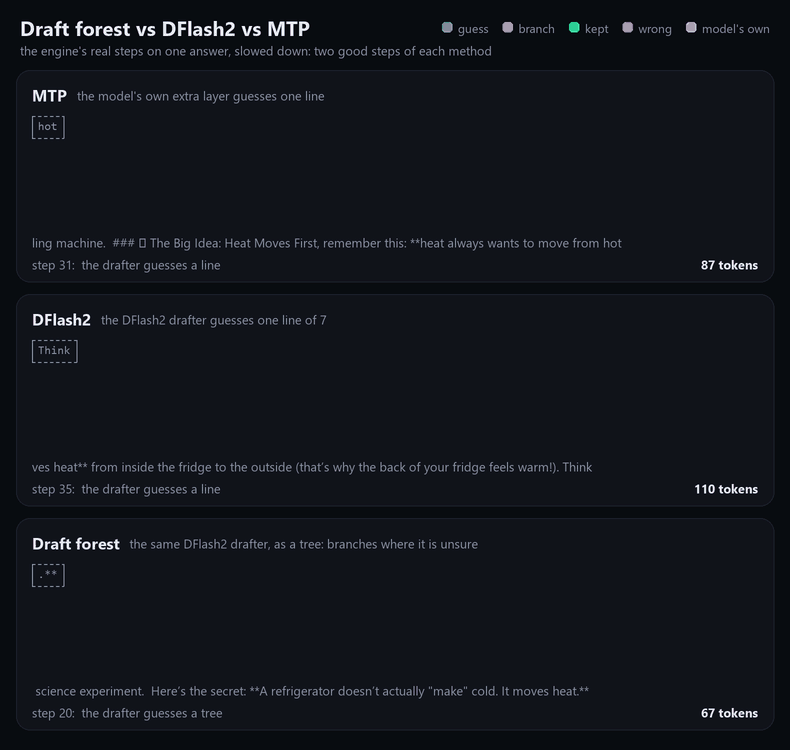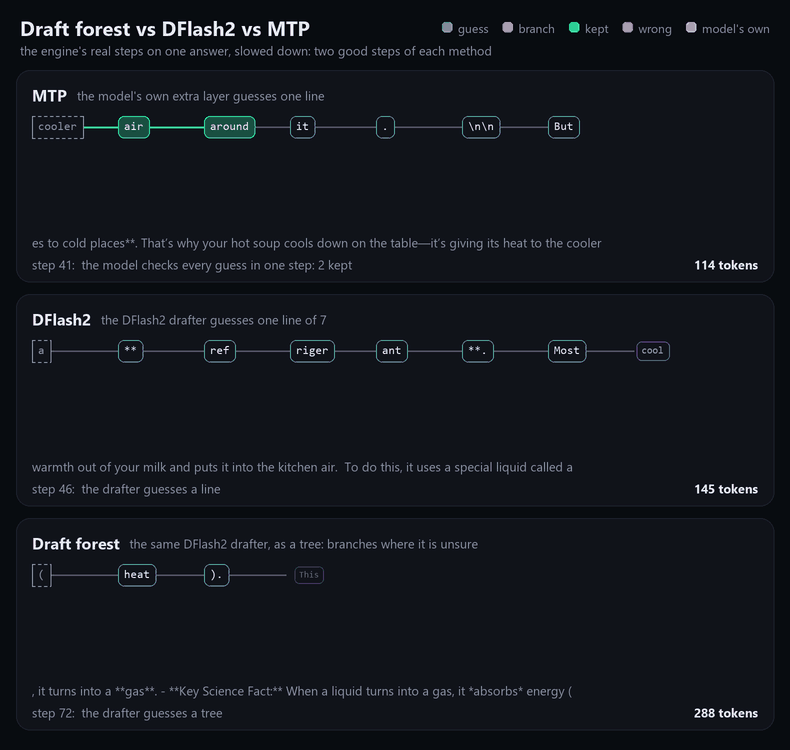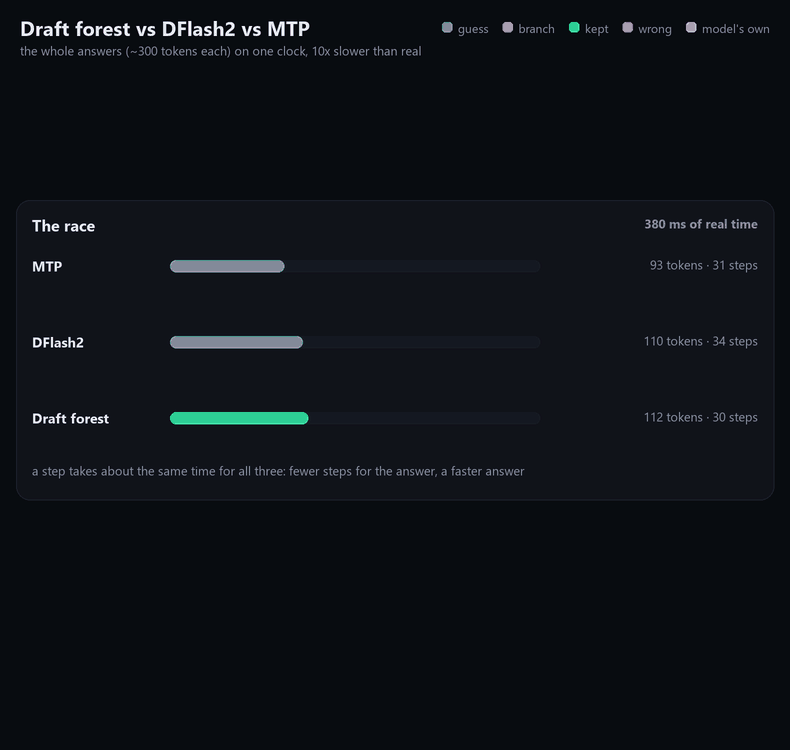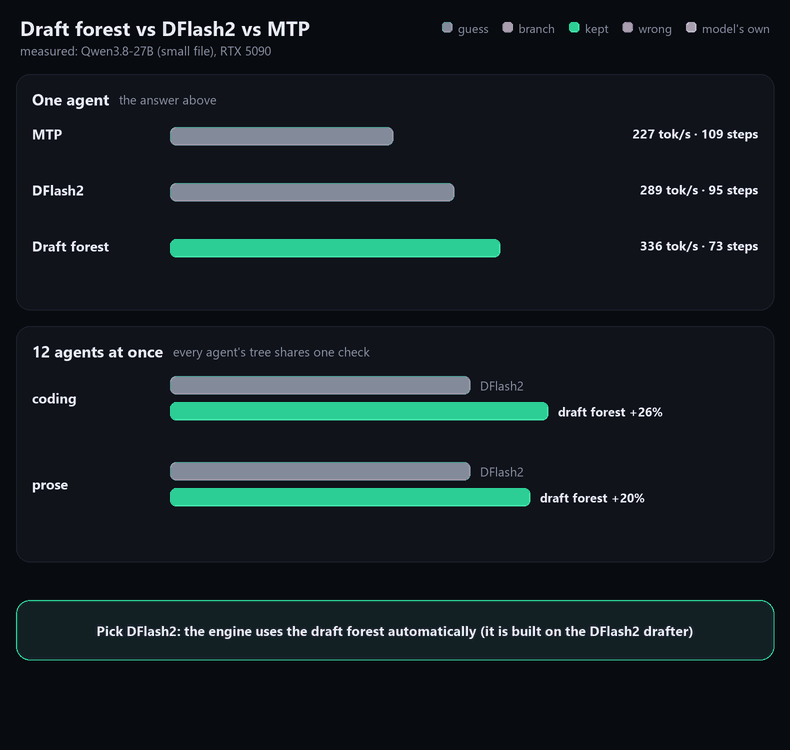
Draft forest: faster with many agents. DFlash2 and MTP guess the next tokens as one line, and the first wrong guess ends the round. The draft forest takes the same DFlash2 drafter's guesses as a tree instead: where the drafter is unsure it also tries its second and third choices, so a miss on one branch is often caught by another and more tokens are kept per step. With several agents, all their trees share one check, and the rows go where guesses are likeliest to be kept. Many agents at once gain the most (the table below). Answers are the model's own, as before.
You don't need to turn it on: when you pick DFlash2 (the launcher's default), the engine uses the draft forest automatically instead of the slower one-line DFlash2, because the draft forest is built on the DFlash2 drafter.
-
More tokens per second in total when many agents work at once. Each shared step that checks several agents' guesses got cheaper (a new kernel for the model's linear-attention layers, faster weight reads), and a ~25 ms stall that every new request caused is gone. Coding speed per model file, measured with 1.17's engine (2026-10-01) and with this one:
Size 1 agent, 1.17 1 agent, 1.35 8 agents, 1.17 8 agents, 1.35 12 agents, 1.35 Tiny 540 537 1,890 2,333 (+23%) 2,782 Small 495 499 1,755 2,379 (+36%) 2,584 Medium 440 436 1,638 2,203 (+35%) 2,529 Large 377 372 1,427 1,953 (+37%) 2,269 XXL 313 307 1,255 1,645 (+31%) 1,921 Tokens per second, coding answers up to 2,000 tokens, Qwen3.8-27B on one RTX 5090. One agent alone writes as fast as before; the gain is with many at once.
-
Shared openings use their memory once. Agents that start with the same system prompt and tools now share one copy of it in the context pool instead of holding a copy each: 12 agents with the same 20K-token opening held 246K tokens of context in 30K tokens of the pool (88% less). Shared openings also move to the RAM cache as one copy, and come back shared.
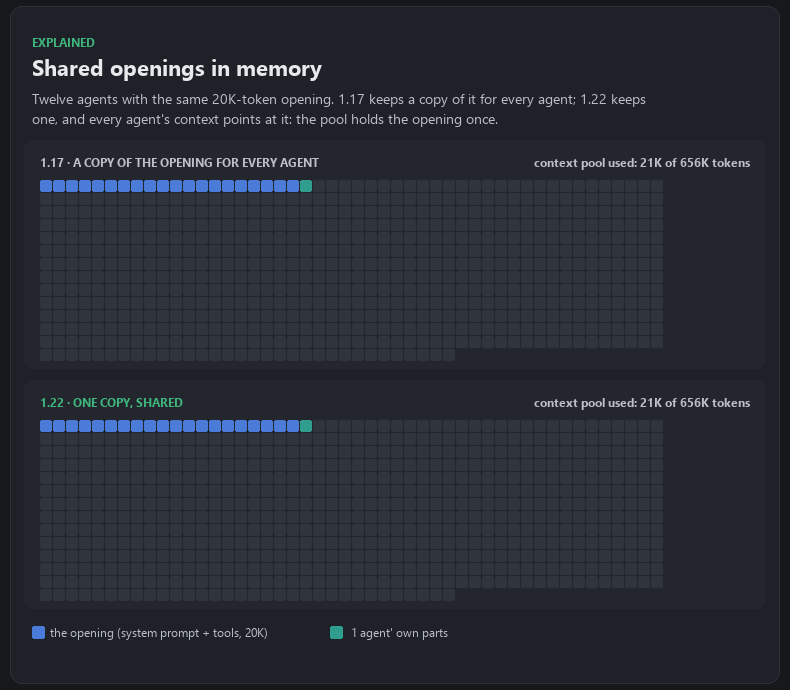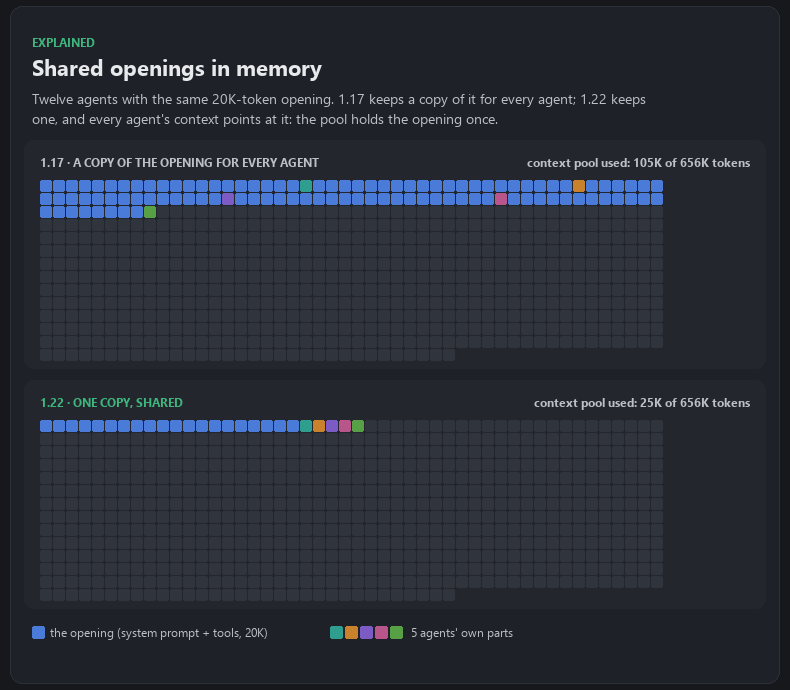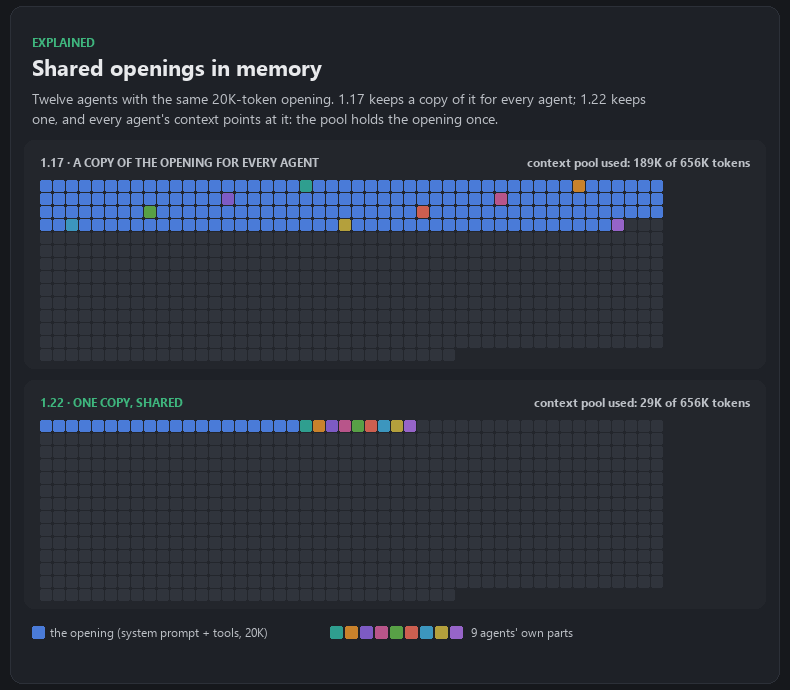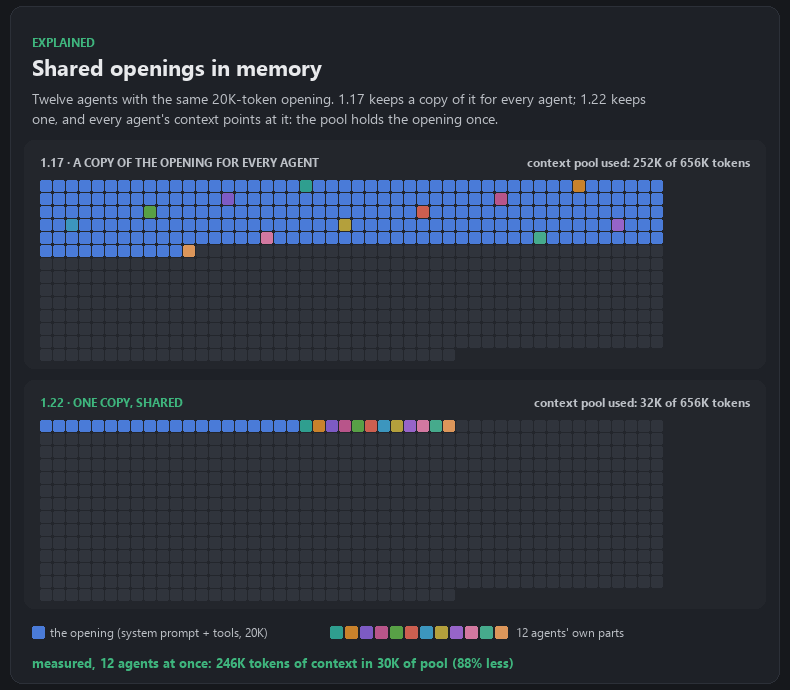
-
Honest projections in the launcher. Every model file was re-measured with this version (DFlash2 meaning the draft forest, many agents measured on a server already running) and its scores updated on Hugging Face under the same names, and the launcher's MTP and many-agents figures were re-measured too. Files you downloaded earlier keep their old scores: download them again to see the new figures. (This replaces v1.34, released earlier today, whose many-agent figures were measured on a freshly started server and read 10-20% low.)
-
Crash and hang reports. If the server crashes, its log shows where (functions and lines) and a crash dump is saved in
logs\; if it stops making progress for 30 seconds, the log gets every thread's stack.megacapybara.pdbships beside the server for this.
Fixed
- A crash when a shared opening was kept while the RAM cache was nearly full. With many agents and a large opening (64K tokens), the server could crash with nothing in its log.
- The monitor froze and the server looked hung under heavy load. With 12 agents running and many more requests queued, every connection thread was taken and the launcher's statistics got no answer. The server now always has a thread for them.
- Agents re-reading their whole conversation after part of its cache went to RAM: their next turn read 50K–120K tokens again instead of continuing (introduced in the withdrawn 1.22).
- A conversation whose cache was in RAM was sometimes read again from scratch when VRAM was briefly short; it now waits a moment for room instead.
- All running conversations could end at once when the RAM cache was full and a request continued a conversation that had been moved to RAM.
- The monitor listed idle conversations as held in VRAM when most of their cache was in RAM.
The "Source code" files GitHub attaches to this release hold only the README and the docs; the engine's source code will be released soon.