ICML 2026 RoboMME
RoboMME: Benchmarking and Understanding Memory for Robotic Generalist Policies — A taxonomy-driven benchmark and 14 memory-augmented π0.5 variants
Venue: ICML 2026 (Oral) Category: Benchmark Affiliations: University of Michigan, Stanford University, Figure AI Traction (2026-06): 6 citations (arXiv)
📖 In-depth review with the memory-implementation breakdown, full results tables, and the FrameSamp+Modulator code analysis: Review-RoboMME

Open-world manipulation frequently requires reasoning over history and recalling information from past interactions — returning books to their original shelf positions, wiping a table a specified number of times, or folding laundry after watching a human demonstration. In these cases, acting from immediate perception alone is insufficient: the policy must retain and reuse information across time, i.e., use memory. Recent vision-language-action (VLA) models have begun to incorporate memory mechanisms, but their evaluations remain confined to narrow, non-standardized settings, which limits systematic understanding, fair comparison, and progress measurement.
RoboMME contributes two things: a standardized benchmark and a controlled study of memory designs.
Benchmark. RoboMME comprises 16 manipulation tasks constructed under a cognitively-motivated taxonomy that evaluates four memory types — temporal, spatial, object, and procedural — organized into task suites such as Counting, Permanence, Reference, and Imitation (e.g., PickXTimes, StopCube, VideoUnmask, MoveCube, InsertPeg, PatternLock). Tasks are long-horizon and history-dependent, with some requiring hundreds of steps.
MME-VLA suite. On top of the π0.5 backbone, the authors build a family of 14 memory-augmented VLA variants to systematically compare memory representations against integration mechanisms under controlled settings.
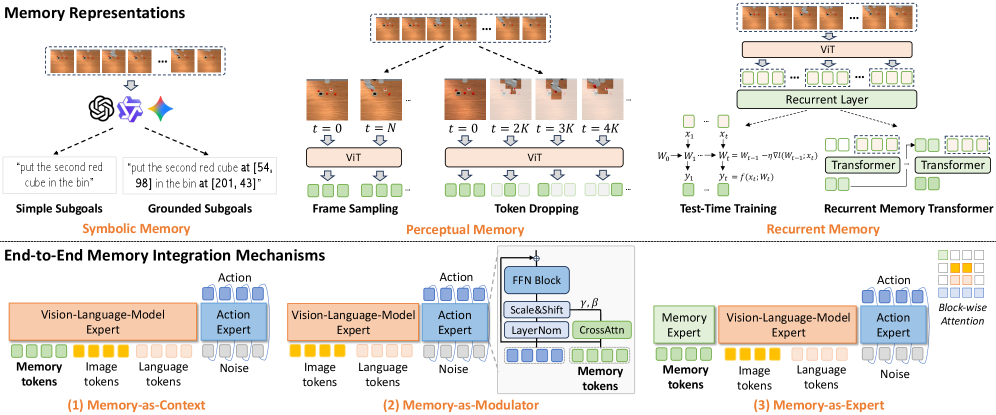
- Representations: (1) Symbolic memory — interpretable language subgoals predicted by an auxiliary VLM (SimpleSG vs. grounded GroundSG with image coordinates); (2) Perceptual memory — visual tokens from past frames via Token Dropping (TokenDrop) or Frame Sampling (FrameSamp); (3) Recurrent memory — Recurrent Memory Transformer (RMT) or Test-Time Training (TTT).
- Integration mechanisms: memory-as-Context, memory-as-Modulator, and memory-as-Expert.
Evaluation fixes a memory budget of 512 tokens for fair comparison, and subgoals can be sourced from Gemini-2.5-Pro, a fine-tuned Qwen3-VL-4B, or simulator ground truth (Oracle).
Across the 16-task average, the strongest configuration is GroundSG + Oracle at 84.08%, far above SimpleSG variants and approaching the human ceiling (96% on counting; 90.5% human average). Key findings:
- The effectiveness of memory representations is highly task-dependent — each design has distinct strengths and weaknesses.
- Symbolic memory excels at counting and visual grounding; grounded subgoals (image coordinates) substantially aid spatial reasoning.
- Perceptual memory is crucial for time-sensitive behaviors and motion imitation; FrameSamp outperforms TokenDrop (aggressive pruning removes global spatial context, hurting tasks like StopCube), and memory-as-modulator is the most effective integration strategy for perceptual memory.
- Recurrent variants (TTT/RMT) trail on most suites (≈22% average).
RoboMME provides the first large-scale, taxonomy-grounded benchmark for memory in robotic generalist policies, plus a controlled 14-variant study that disentangles what to remember (representation) from how to use it (integration). Its central message — that no single memory design dominates and that the right choice is task-dependent — gives the field a concrete tool and a clear research agenda for memory-augmented VLAs.
- arXiv: 2603.04639
- ICML 2026: https://icml.cc/virtual/2026/poster/65933
← Back to ICML-2026