Home
OpenAI-compatible AI gateway with intelligent routing, automatic failover, and multi-provider support.
Single Rust binary. No runtime dependencies. Just download and run.
OBEY API Gateway sits between your application and your AI providers. Point your existing OpenAI SDK at it instead of api.openai.com, and you get automatic failover, circuit breakers, and multi-provider routing — without changing your application code.
AI providers go down. Rate limits hit. Models get deprecated. OBEY handles all of that transparently.
| Feature | Description |
|---|---|
| Drop-in OpenAI Replacement | Full /v1/* API compatibility (chat, completions, embeddings, images, audio) |
| Assistants & Responses API | Stateful /v1/responses and /v1/assistants surfaces backed by local SQLite |
| Multi-Provider Routing | OpenAI, Ollama, AWS Bedrock, Groq, Together AI, NVIDIA NIM, vLLM, LM Studio |
| Automatic Failover | Circuit breakers + retry with exponential backoff across providers |
| Smart Rate-Limit Handling | Honors Retry-After, X-RateLimit-Reset, Anthropic headers, weekly quotas |
| Streaming Reliability | True SSE pass-through, early events, keep-alive, mid-stream failover |
| Response Caching | Two-tier: in-memory exact-match + optional Qdrant semantic cache |
| Token Compression | Multi-engine payload compression with custom pipelines and cache-aware downgrades |
| Tool Definition Compression | Multi-stage pipeline to reduce tool/function definition token overhead with feedback loop |
| Structured Output Validation | JSON Schema validation of model responses with automatic corrective retries |
| Persistent Memory | Cross-session memory extraction, decay, and injection with namespace isolation |
| Virtual Key Management | Per-caller keys with budgets, rate limits, model access, expiry |
| Guardrail Pipelines | PII redaction, content moderation, prompt injection detection |
| Agent Loop Detection | Detects and breaks repetitive agent loops with graduated enforcement |
| Smart Model Routing | Complexity-aware routing with tier selection, cascade, A/B testing, and online optimization |
| Cache-Aware Routing | Sticky provider selection, cache-control breakpoint injection, cached-token-aware cost sorting |
| Reasoning Compatibility | Safe cross-model failover for reasoning models: detect, strip/preserve, normalize, cost-attribute |
| OpenAI OAuth Login | Browser-based sign-in with ChatGPT Plus/Pro subscription |
| Codex Backend | Routes OAuth requests through ChatGPT Codex, translating APIs on the fly |
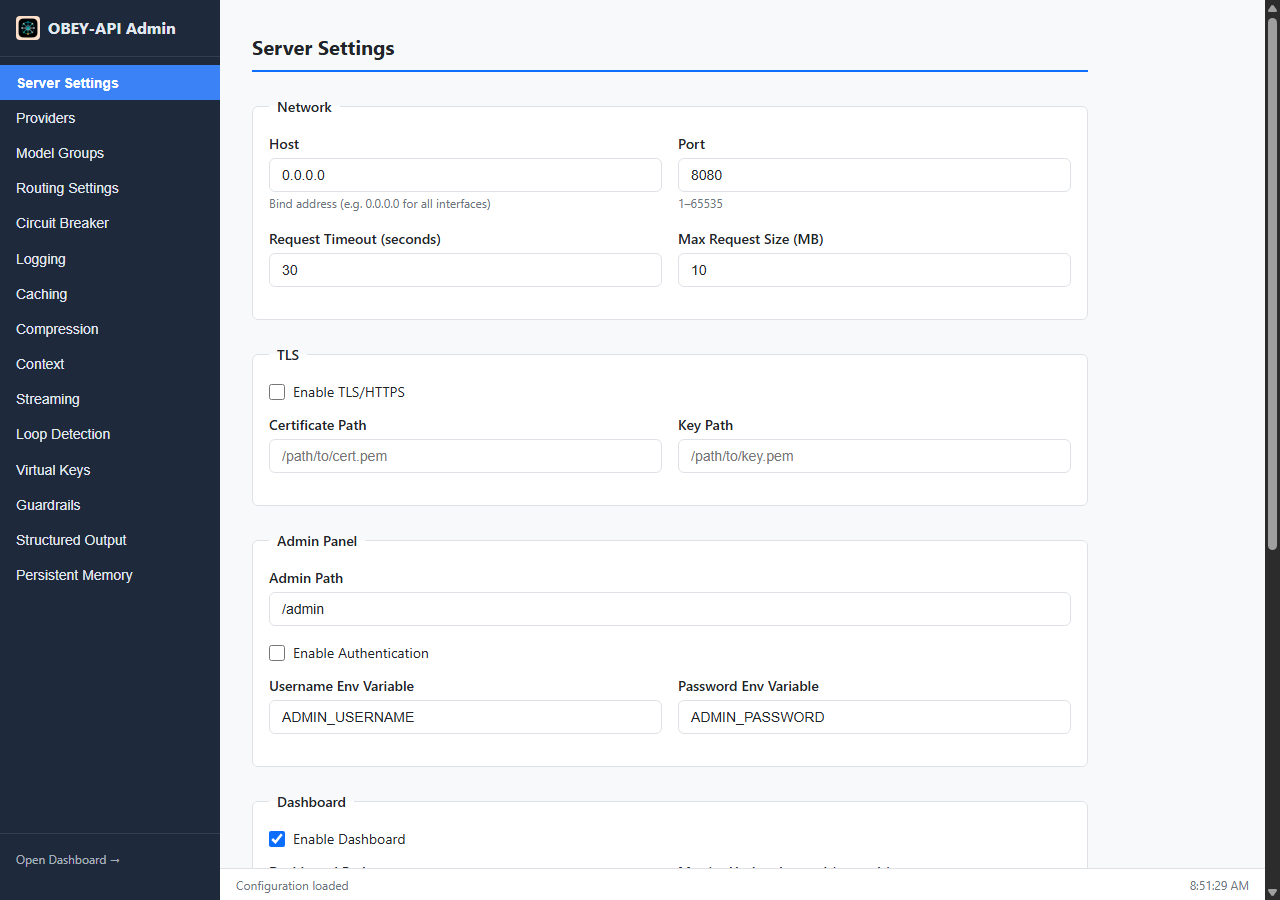
| Admin Panel & Dashboard | Embedded web UIs for config, metrics, and logs |
| Encrypted Key Storage | Provider keys encrypted at rest with machine-local master key |
| TLS Support | Optional HTTPS with certificate configuration |
| Windows System Tray | Desktop app with splash screen and tray menu |
| Hot Config Reload | Change settings via admin UI without restarting |
| Prometheus Metrics |
/metrics endpoint for monitoring infrastructure |
# Point any OpenAI-compatible SDK at the gateway
export OPENAI_API_BASE=http://localhost:8080/v1
from openai import OpenAI
client = OpenAI(base_url="http://localhost:8080/v1", api_key="unused")
response = client.chat.completions.create(
model="gpt-4-group", # Use your model group name
messages=[{"role": "user", "content": "Hello!"}]
)See Installation for all setup options.
┌─────────────────┐     ┌──────────────────────────────────────────────────┐
│  Your App /     │     │              OBEY API Gateway                     │
│  OpenAI SDK     │────▶│                                                  │
│                 │     │  ┌──────────┐  ┌──────────┐  ┌───────────────┐  │
└─────────────────┘     │  │ Guardrail│─▶│  Router  │─▶│   Providers   │  │
                        │  │ Pipeline │  │(failover)│  │               │  │
                        │  └──────────┘  └──────────┘  │ ┌───────────┐ │  │
                        │                              │ │  OpenAI   │ │  │
                        │  ┌──────────┐  ┌──────────┐  │ ├───────────┤ │  │
                        │  │  Cache   │  │  Circuit │  │ │  Ollama   │ │  │
                        │  │(2-tier)  │  │ Breakers │  │ ├───────────┤ │  │
                        │  └──────────┘  └──────────┘  │ │  Bedrock  │ │  │
                        │                              │ ├───────────┤ │  │
                        │  ┌──────────┐  ┌──────────┐  │ │  Groq     │ │  │
                        │  │ Virtual  │  │   Rate   │  │ ├───────────┤ │  │
                        │  │  Keys    │  │ Limiters │  │ │ Together  │ │  │
                        │  └──────────┘  └──────────┘  │ └───────────┘ │  │
                        │                              └───────────────┘  │
                        └──────────────────────────────────────────────────┘

- Installation — Download, Docker, Railway, build from source
- Configuration — Full config reference, environment variables
- Providers — Supported providers and their setup
- Routing & Failover — Intelligent routing, circuit breakers, priorities
- Smart Model Routing — Complexity-aware tier selection and cascade
- Cache-Aware Routing — Sticky selection and prompt-cache breakpoints
- Reasoning Compatibility — Safe cross-model reasoning failover
- Assistants & Responses API — Stateful OpenAI-compatible surfaces
- Streaming — Streaming reliability features
- Caching — Exact-match and semantic cache
- Token Compression — Multi-engine payload compression
- Tool Definition Compression — Reduce tool/function definition tokens
- Structured Output — JSON Schema validation with corrective retries
- Persistent Memory — Cross-session memory extraction and injection
- Virtual Keys — Multi-tenant key management
- Guardrail Pipelines — Policy enforcement and PII protection
- OAuth & Codex — OpenAI OAuth and Codex backend
- Admin Panel & Dashboard — Web UIs, API, metrics
- Security — Encryption, TLS, secrets management