Repository navigation
Exit Criteria Evaluation
Screen: gui/templates/strategy/exitCriteriaEvaluation.html
BFF: api/exitcriteriaevaluation/index.php
ASIDE: Test Strategy → Exit Criteria Evaluation (new entry, $TLS_href_test_strategy_exit_evaluation, present in all 19 server locales).
The Exit Criteria Definitions screen (#1936) captures the criteria of a test project — test level, entry/exit text and one measurable metric with a target value. It is CRUD only: it never says whether those criteria are actually met by the execution of a test plan. This screen is the evaluation half of feature issue #1088 (Implement definition of EXIT CRITERIA) and answers exactly that question, read-only.
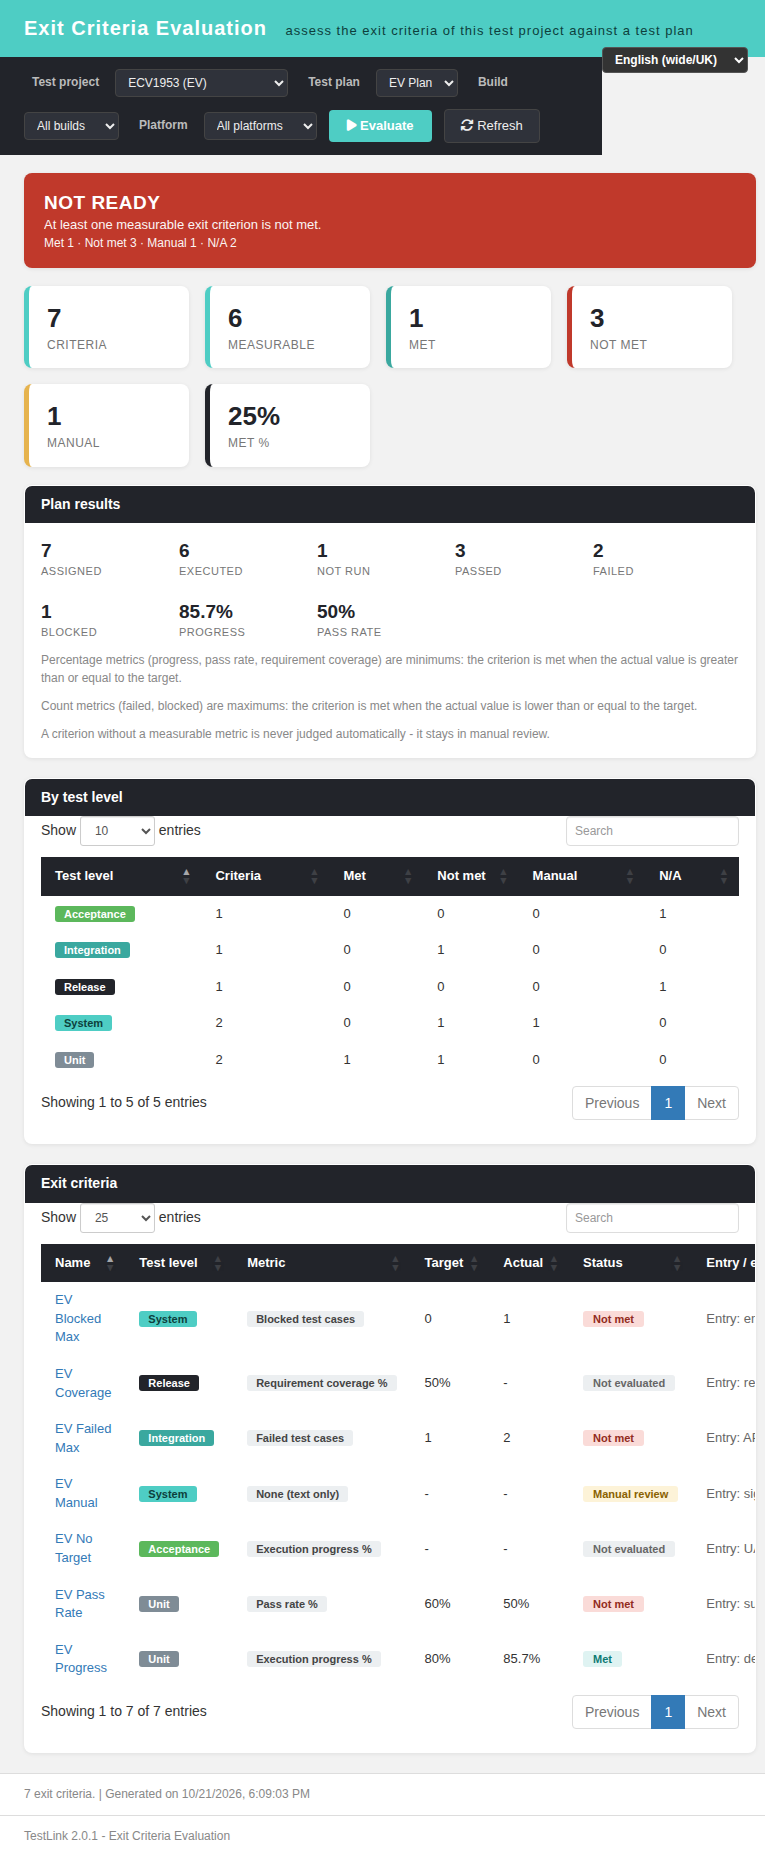
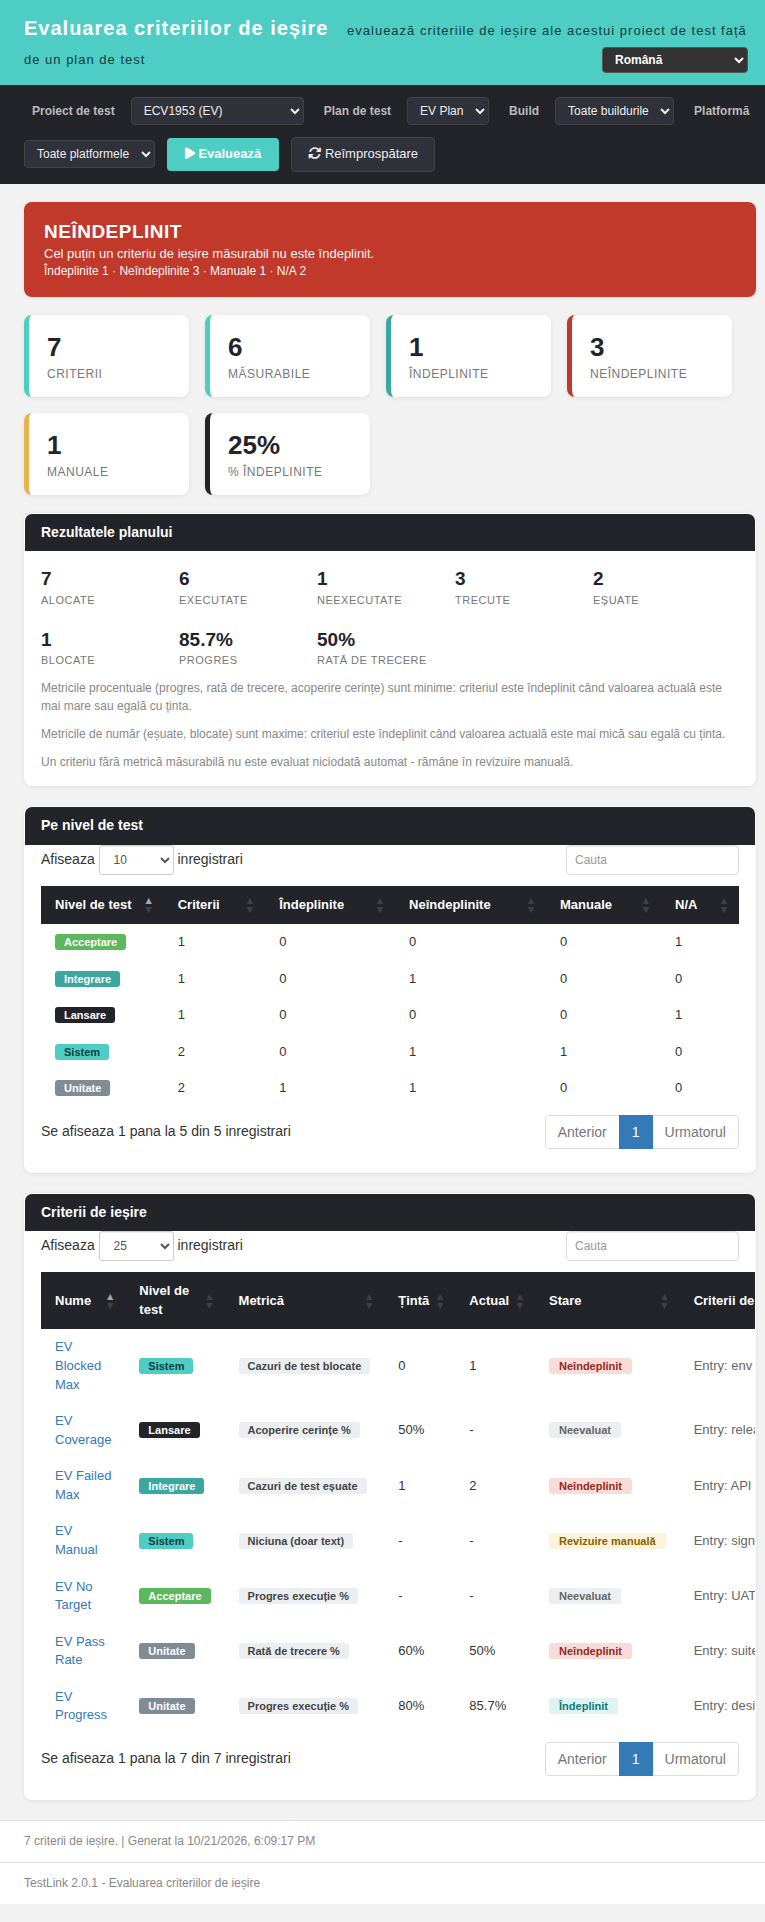
- Teal Dashio header with subtitle + client-side
TLi18nlocale switcher (10 locales). - Toolbar: project selector, test plan selector, build selector, platform selector, Evaluate and Refresh buttons.
-
Verdict banner:
ready/not_ready/manual/no_datawith a body sentence and the countsMet · Not met · Manual · N/A. - Six KPI tiles: Criteria, Measurable, Met, Not met, Manual, Met %.
- Plan-results strip: Assigned, Executed, Not run, Passed, Failed, Blocked, Progress %, Pass rate %.
- By test level table: one row per test level that actually carries criteria (the canonical levels — unit, integration, system, acceptance, release — plus any other level found in the data, which gets its own row instead of being dropped) with their criteria / met / not met / manual / N/A counts.
- Criteria DataTable: Name (clickable → details modal), Level, Metric, Target, Actual, Status, Actions. Sortable and searchable.
-
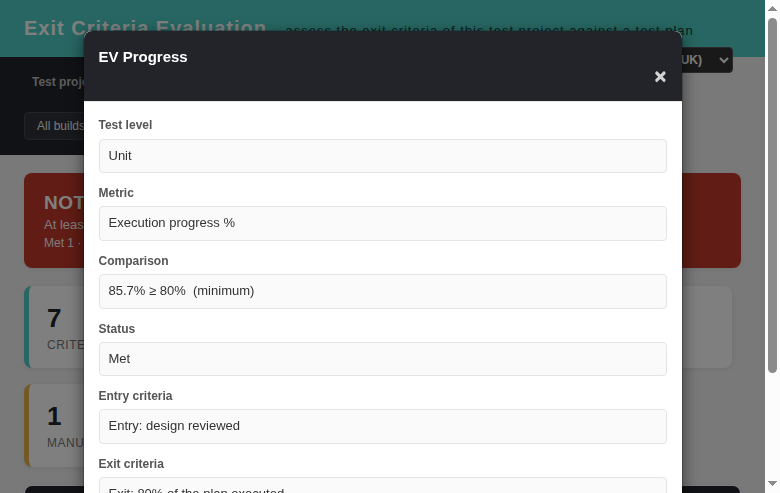
Details modal: test level, metric, the comparison line
(
85.7% ≥ 80% (minimum)), the status, the entry criteria and the exit criteria. - Three convention hints that state the judging rules in words.
- Footer:
N exit criteria.+ the generated timestamp. - State cards for 401 / 403 / 404 / 400 / 405.
-
Unit of work — a
testplan_tcversionsassignment row (a test case version assigned to the plan). -
Result of a test case version — its latest execution
(
MAX(executions.id)) for that (tcversion, platform) inside the selected plan and build. -
Percentage metrics (
progress,pass_rate,req_coverage) are minimums — the criterion is met whenactual ≥ target. -
Count metrics (
failed,blocked) are maximums — met whenactual ≤ target. -
metric = noneis never judged automatically → Manual review. - A criterion without a target value is Not evaluated — and it carries no actual value either (an unjudged criterion must never look like a measured one).
-
Verdict —
no_datawhen the plan has no assigned test case;manualwhen nothing could be judged (no criterion is measurable, or every measurable criterion ended up "Not evaluated") — a human has to decide, so the verdict is never "ready";not_readywhen at least one judged criterion is not met;readyotherwise. -
Met % is computed over the criteria that could really be judged
(
met + not_met), so a criterion that needs a human decision cannot dilute it. - Scope — the whole plan, optionally restricted to one build and/or one platform.
Session auth + same-origin CSRF guard (bffSameOriginGuard) + inactivity timeout
(bffEnforceSession). Read only — there is no write verb at all. Rights are
checked on the addressed test project before it is resolved (the #1697
lesson: no existence oracle).
| Route | Meaning |
|---|---|
GET|HEAD ?action=projects |
{projects:[{id,name,prefix}]} — the projects the caller may read |
GET|HEAD ?action=init&tproject_id=N |
{context:{project, plans, builds, platforms}, metrics, levels} |
GET|HEAD ?action=evaluate&tplan_id=M[&tproject_id=P][&build_id=B][&platform_id=PL] |
{context, verdict, metrics, levels, criteria[]} |
- read =
mgt_view_tcormgt_modify_tcon the project.
Machine codes: not_authenticated (401), no_right (403), unknown_action (400),
invalid_request (400), invalid_parameter (400 — an array parameter), tplan_not_found
(404), tproject_not_found (404), project_mismatch (404 — the plan belongs to
another project), method_not_allowed (405, Allow: GET, HEAD).
No plan-existence oracle. When the request does not assert a project, the plan is
looked up first and a plan the caller may not see answers with the same opaque
404 tplan_not_found as a plan that does not exist. Only an asserted project the
caller may not see answers 403 no_right — the answer therefore never reveals whether
a plan id exists.
91 ecv.* keys plus footers.exitCriteriaEvaluation in all 10 client bundles
(gui/templates/i18n/*.json), plus $TLS_href_test_strategy_exit_evaluation in
all 19 server locales. ai/verify_i18n_coverage.sh passes (9324 keys, 9/9 bundles).
The DataTables pagination, the "entries per page" menu and the search inputs are
localized too (dtLanguage() / patchSearch() on the client), and the shared locale
switcher got an accessible name through the new common.language key.
Suite Suite — Issue #1953 in tmp/TLU_Test_Cases.md (15/15 PASS) plus
Suite — Issue #1953 (review fixes) (12/12 PASS) plus
Suite — Issue #1953 (correction) (7/7 PASS). Verified in the
browser as admin: render, verdict, build and platform filters, the criteria search,
the details modal, the empty-project state, the 403 (right-less user) and 404
(unknown project / cross-project plan) states; console clean; Event Viewer shows
only AUDIT rows, 0 new Error/Warning. BFF error paths exercised over curl
(400/401/403/404/405). English and Romanian render fully translated, with no raw
ecv.* key on the page. php -l clean on the BFF. Lighthouse: Accessibility 96,
Best Practices 100 (the remaining colour-contrast findings are the shared Dashio
house palette, identical to the sibling screens).
Two measurements recorded in the earlier suites of this screen did not survive a
re-run of the fixture and were corrected in the appended suite
Issue #1953 (correction) (7/7 PASS). The screen itself was not changed.
| Wrong record | Correct value |
|---|---|
Issue #1953 (review fixes) case 1953-R.11: selecting EV Build 2 gives 3 Met / 1 Not met / 75% Met %
|
EV Build 1 (id 5) gives 3 Met / 1 Not met / 75% Met %; EV Build 2 (id 6) gives 2 Met / 2 Not met / 50% Met % — the case had the two build ids swapped |
Issue #1953 (review fixes) case 1953-R.2: the NA-only plan reads 0 Met / 0 Not met / 2 Manual
|
the two criteria are Not evaluated (na), so the tiles read 0 Met / 0 Not met / 0 Manual / 0% Met % and the counts strip "Met 0 · Not met 0 · Manual 0 · N/A 2" — the verdict is still manual (evaluated = 0) |
The authoritative numbers of the fixture (ECV1953 = 55, EV Plan = 58,
EV Build 1 = 5, EV Build 2 = 6, EV Platform 1 = 3, ECV1953 NA ONLY = 57,
EN Plan = 60) are:
| Scope | Tiles | Verdict |
|---|---|---|
| all builds | 7 Criteria / 6 Measurable / 1 Met / 3 Not met / 1 Manual / 25% Met % | not_ready |
EV Build 1 |
3 Met / 1 Not met / 1 Manual / 75% Met % | not_ready |
EV Build 2 |
2 Met / 2 Not met / 1 Manual / 50% Met % | not_ready |
EV Platform 1 |
4 Met / 0 Not met / 1 Manual / 100% Met % | ready |
ECV1953 NA ONLY |
2 Criteria / 2 Measurable / 0 Met / 0 Not met / 0 Manual / 0% Met % | manual |
-
The build selector, the platform selector and the Evaluate button were dead.
The global function was named
evaluate(), and an inlineonchange/onclickhandler resolves a name throughdocumentbeforewindow— sodocument.evaluate(the XPath API) shadowed it and the console logged 3 ×Uncaught TypeError: Failed to execute 'evaluate' on 'Document': 2 arguments required, but only 0 present. (0 args). The function was renamed torunEvaluation(); the BFFaction=evaluatecontract is unchanged. -
An unknown deep link silently fell back to the first accessible project.
?tproject_id=99999(or a?tplan_id=of another project) now shows the Not found state card instead of quietly displaying a different project.
-
A criterion without a target value was judged as met. The evaluation loop read
the computed actual value before checking that the criterion has a target, so a
progresscriterion withtarget_value = NULLended up with the status "Met" and a number in the Actual column. It is now Not evaluated with an empty actual value. -
The verdict said "ready" when nothing could be judged. The BFF now also reports
evaluated = met + not_metand answersmanualwhenevaluated = 0or when no criterion is measurable — a human has to decide, so the verdict is never "ready". -
The "Met %" tile was diluted by criteria that were never judged — the
denominator is now
evaluated. -
An unknown metric id crashed the evaluation with an
Undefined array keywarning (Event Viewer) and was silently judged as met — the metric is now sanitized tonone(Manual review). - A plan the caller may not see leaked its existence — see "No plan-existence oracle" above.
- A criterion on an unknown test level was dropped from the "By test level" table, so the level totals did not add up — it now gets its own row.
-
Accessibility: the four toolbar selects, the six modal fields, the per-row action
button, the two DataTables search inputs, the
mainlandmark and the shared locale switcher were missing their accessible wiring — all fixed (Lighthouse Accessibility 90 → 96, Agentic Browsing 13 → 63). - Dead code: the client-side criteria filter (and its "no match" row) was removed — the tiles are now rendered from the summary computed by the BFF, which is the single source of truth.